
Key takeaways
• ML anomaly detection is a buy-or-build call, not a research project. Platforms like Avigilon, Verkada and BriefCam cover 80% of generic anomalies; custom builds pay off above ~200 cameras or when the anomaly class is domain-specific.
• Architecture beats algorithm. A $249 Jetson Orin Nano Super (67 TOPS, NVIDIA, December 2024) runs detection at the edge with sub-100 ms alerts; pushing raw streams to the cloud adds 200–2,000 ms and an uplink bill.
• False positives, not accuracy, kill deployments. Untuned systems fire 30–70% false alerts; adaptive thresholds plus temporal filtering cut that by 67% without losing true positives.
• GDPR & the EU AI Act narrow your options. Real-time remote biometric ID for law enforcement in public spaces and untargeted face scraping have been banned since 2 February 2025; other biometric uses become high-risk on 2 December 2027 under the 2026 Digital Omnibus. Object and behavior anomaly detection (loitering, intrusion, crowd density) stays in the low-risk band.
• New in 2026: agentic alarm triage. Vision-language models now check a flagged clip against access-control and POS events before a human sees it (NVIDIA VSS Blueprint 3, GA June 2026). Use them as a second-stage filter on top of a fast detector, not as the detector.
Updated October 2026: EU AI Act dates after the Digital Omnibus (Regulation 2026/1744), 2026 edge hardware (Orin Nano Super, Hailo-8, Jetson Thor), new UCF-Crime state of the art, and a section on agentic alarm correlation.
Machine learning video anomaly detection is software that learns what normal activity looks like on each camera and raises an alert when a scene departs from it: an intruder after hours, a fall, a fight, a bag left behind. For a security team it is a triage layer. It decides which few clips out of thousands of camera-hours a human operator should look at, and it is judged on false alarms per camera per day, not on benchmark accuracy.
Why Fora Soft wrote this playbook
Fora Soft has built video and multimedia products since 2005: 250+ projects and 50 in-house engineers, with custom video surveillance development, AI-assisted video analytics and real-time streaming at the core of the portfolio. Our engineers wire up detection pipelines on top of WebRTC, RTMP/HLS, RTSP and NVIDIA DeepStream, run them on Jetson edge boards and AWS/Hetzner clusters, and stay on the hook for them after launch.
The clearest case study is VALT, the video recording and observation platform we have built and run as the sole development team for 10+ years. It is used by 770+ U.S. organizations, including police interview rooms, medical simulation labs and child advocacy centers, where a missed recording or a broken audit trail is not an option. That operational reality, not a Kaggle leaderboard, shapes the recommendations in this guide.
The rest of this playbook answers the questions buyers actually ask us on intro calls: which model families work, what good architecture looks like, what the real costs are, where GDPR and the EU AI Act stop you, and when it’s cheaper to buy an off-the-shelf VMS instead of building one. Use it to scope your own project—or send us the spec and we’ll scope it with you.
Scoping an ML-based video surveillance product?
Bring us your camera count, anomaly classes and compliance zone. We’ll tell you in one call whether to build, buy or go hybrid—and what it realistically costs.
What counts as a video anomaly in a security context
Before picking a model or a vendor, nail the anomaly taxonomy. Most “AI surveillance” failures happen because the buyer never separated “anomalous pixels” from “anomalous events” from “policy violations”. These are three different problems, with three different cost curves.
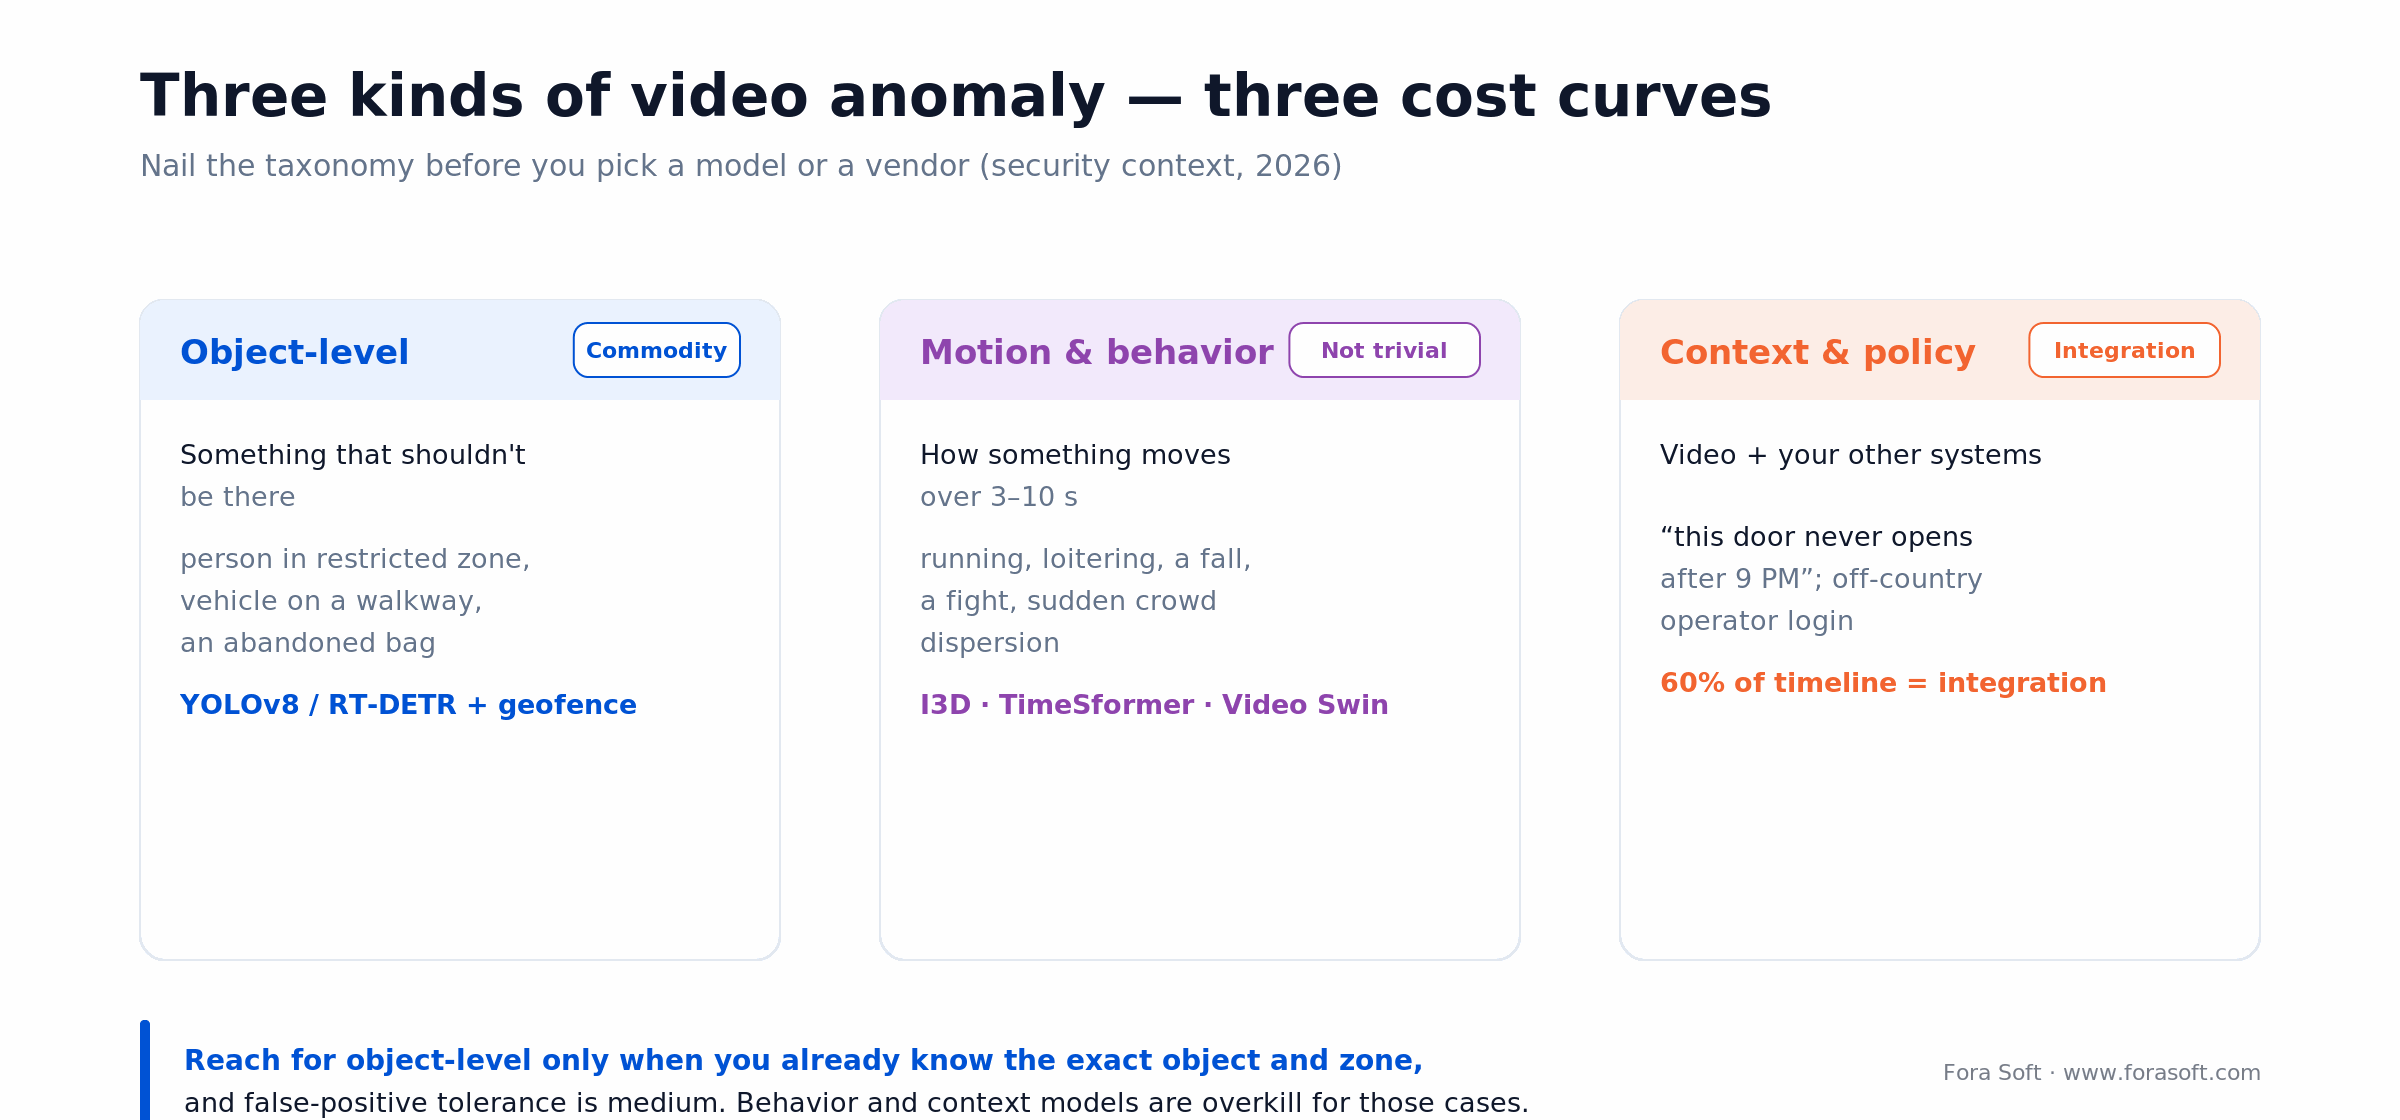
Figure 1. The three anomaly classes a security buyer must separate before scoping a model or a vendor.
1. Object-level anomalies. Something that shouldn’t be there: a person in a restricted zone, a vehicle on a pedestrian path, an abandoned bag. Solvable with mature object-detection models (YOLOv8, RT-DETR) plus geofence rules. Commodity work.
2. Motion & behavior anomalies. Running in a no-running zone, loitering, a fall, a fight, a sudden crowd dispersion. These need spatio-temporal models (I3D, TimeSformer, Video Swin) and 3–10 seconds of context. Solvable but not trivial.
3. Contextual & policy anomalies. “This door should never open after 9 PM.” “This operator never logs in from outside the country.” These combine video events with access-control, schedule and identity data. The ML part is the easy bit; the integration with your existing systems is where 60% of the timeline goes.
Reach for object-level only when: you already know the exact object and zone you care about (intruder in perimeter, vehicle in fire lane), and false-positive tolerance is medium. Behavior and context models are overkill for these use cases.
Market snapshot: why every VMS vendor now ships an AI SKU
MarketsandMarkets sized the AI-in-video-surveillance market at $3.90 B in 2024 and projects $12.46 B by 2030, a 21.3% CAGR (report released December 2024). Analysts disagree on the exact curve, but they agree on the direction: AI analytics is now a standard line item in VMS deals, not an add-on.
Three forces are driving that curve. First, edge silicon got cheap: the Jetson Orin Nano Super developer kit costs $249 and delivers 67 TOPS (NVIDIA, December 2024), and a Hailo-8 M.2 module adds 26 TOPS for about $169 (Electromaker list price, September 2026). Second, pre-trained backbones and vision-language models collapsed the data-collection cost for buyers who don’t have a million labeled frames lying around: NVIDIA DeepStream 9.0 (2026) ships a VLM plugin for Cosmos Reason 2, and the VSS Blueprint 3 went GA in June 2026. Third, vendors market big operator-workload gains; Avigilon (Motorola Solutions), for example, says its self-learning Unusual Motion Detection cuts false alarms by roughly 90%. Treat vendor numbers as upper bounds and measure on your own cameras.
The practical read: if you’re commissioning this product in 2026, the detection layer is a production-hardened stack. The new, less mature part is the agentic triage layer on top of it, covered below.
Model families that actually ship to production
Five detector families cover most real deployments, and a sixth, vision-language models, now sits on top of them as a verification stage. Our video surveillance engineering course breaks each one down, and our comparison of video anomaly detection models has the full benchmark table. Here we focus on which ships fastest for a security team. Pick by how much labeled data you have, how tight your latency budget is, and whether your anomalies are spatial, temporal or both.
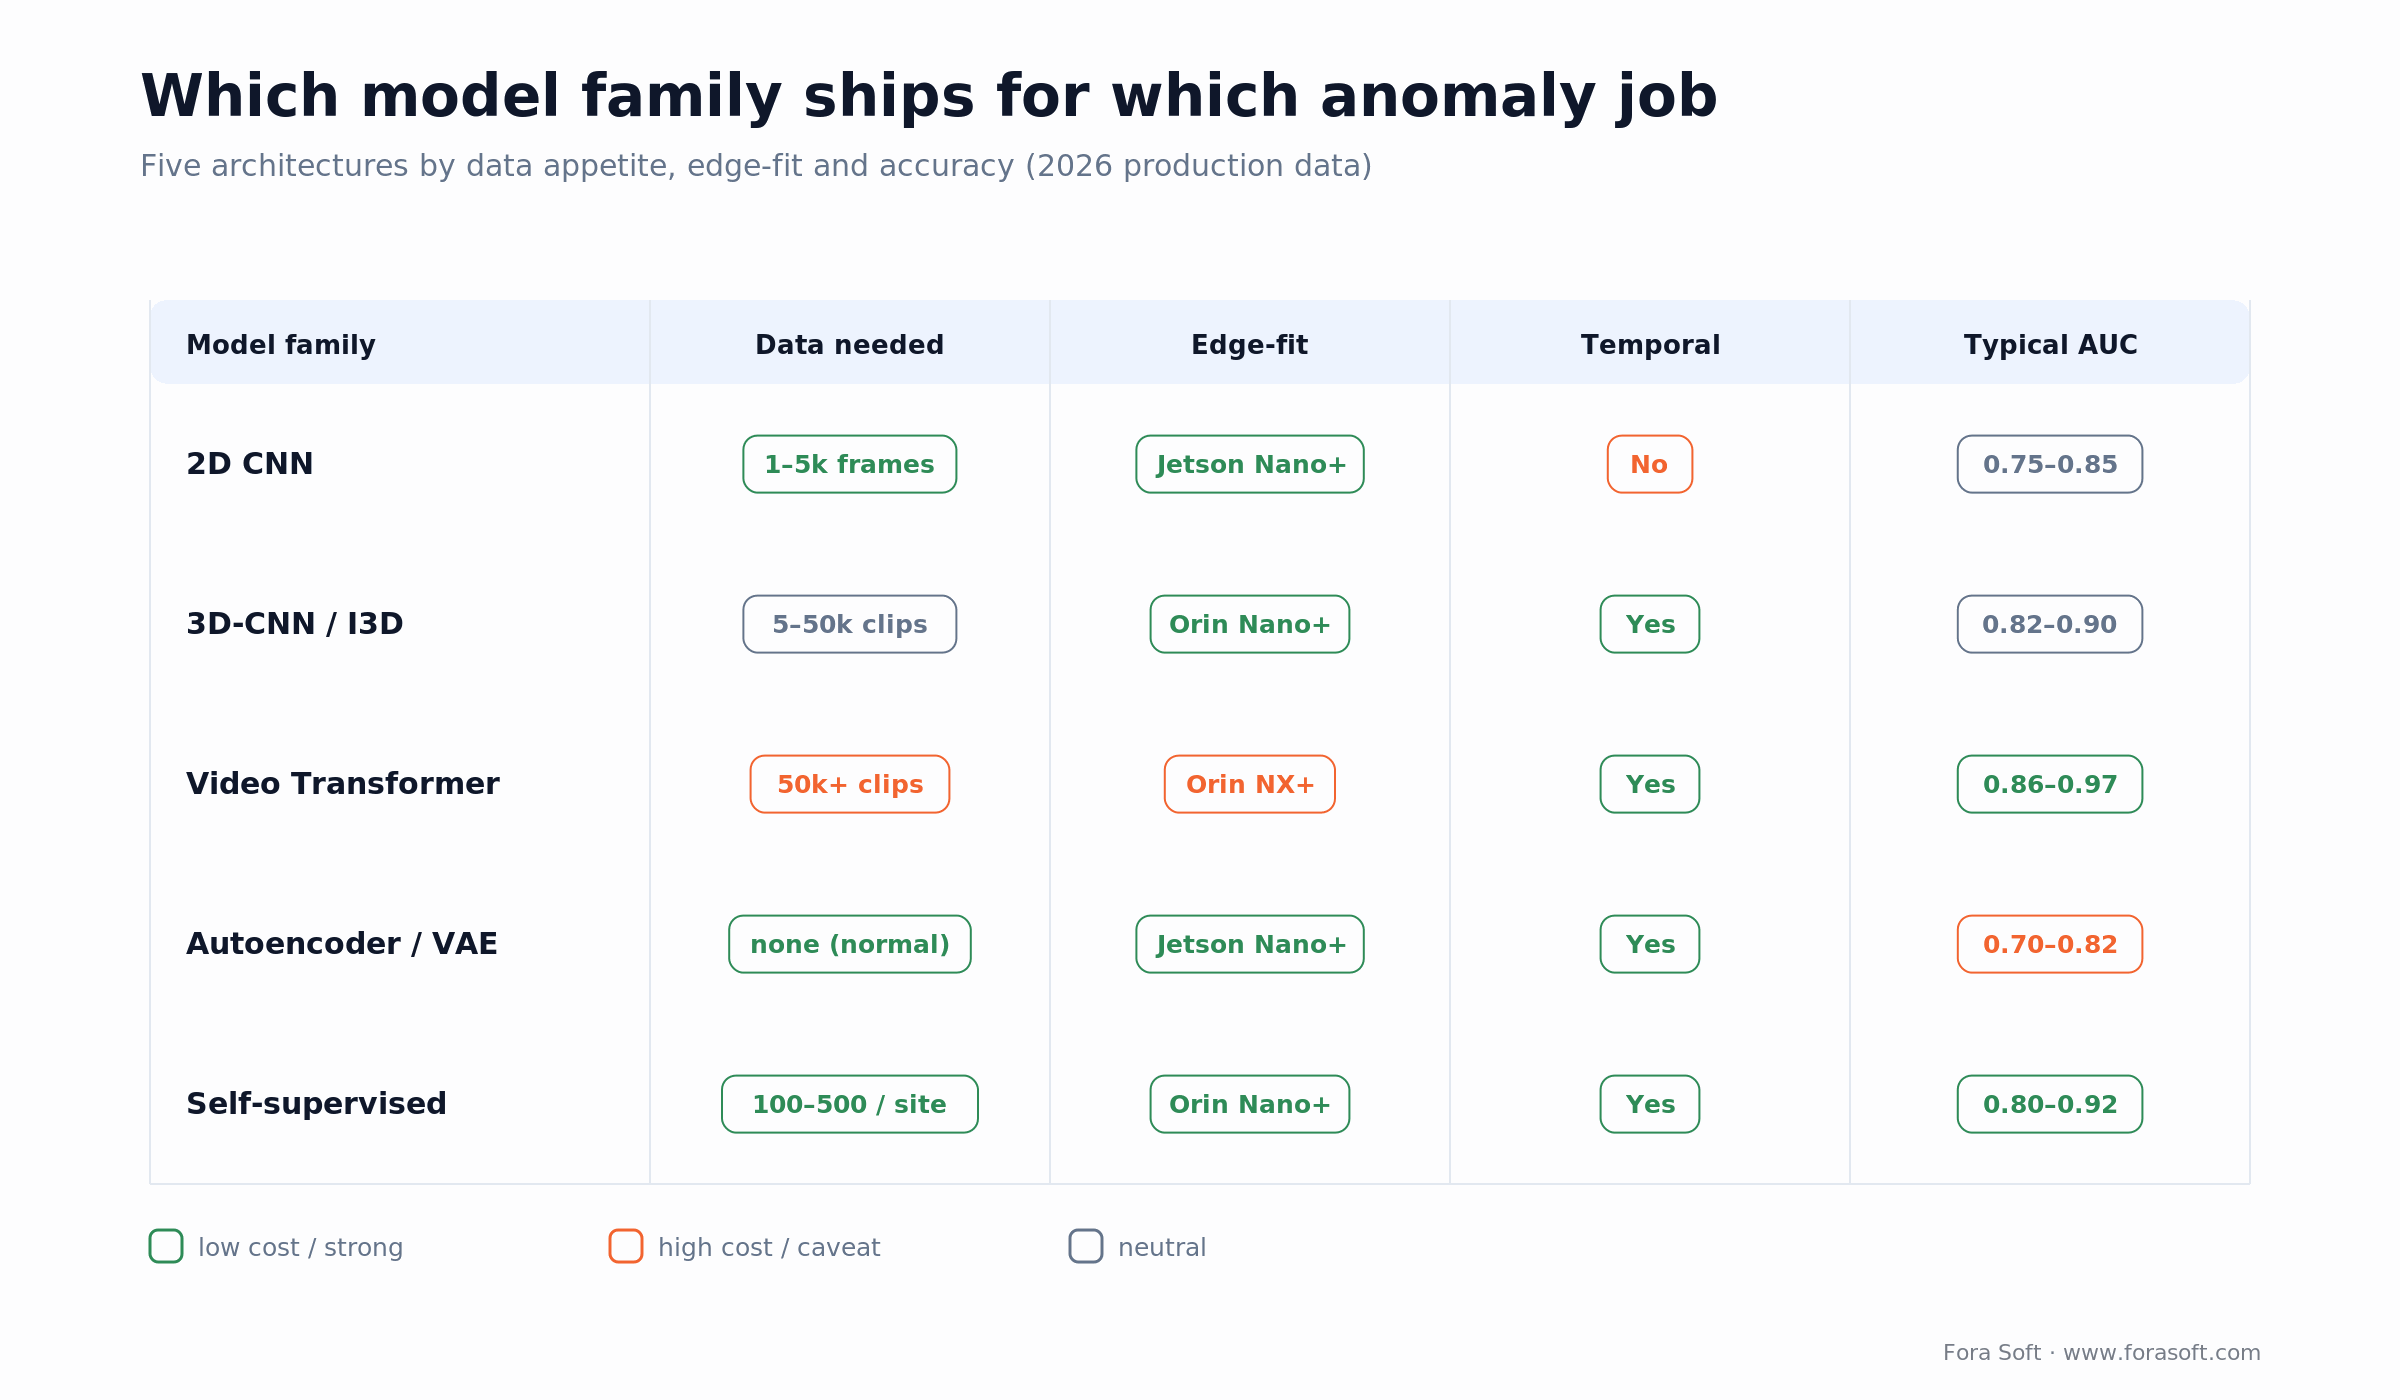
Figure 2. Five model families that ship to production, ranked by data appetite, edge-fit and accuracy.
CNN backbones (ResNet, DenseNet, EfficientNet)
Why pick it. Fastest inference (2–5 TFLOP/frame), tiny memory footprint, every edge runtime supports it. Perfect for per-frame object or scene classification.
Limits. No temporal reasoning. A CNN cannot tell “a person walked into a bank” from “a person ran into a bank”. High false positives on static scenes with lighting flicker.
3D-CNN / I3D
Why pick it. Learns spatial and temporal features jointly, and I3D features are still the default input for many weakly supervised anomaly heads on UCF-Crime. Mature tooling in NVIDIA TAO and DeepStream.
Limits. Memory-heavy: expect 6–8 GB VRAM per stream at 224×224, 32-frame clips. Slower than 2D alternatives on edge devices without TensorRT optimization.
Video Transformers (TimeSformer, Video Swin)
Why pick it. Strongest temporal reasoning of the classic detectors: long-range context for fights, falls and crowd flows without LSTM’s vanishing-gradient pain. Distilled and quantized variants now run in real time on Orin-class hardware.
Limits. Hungry for training data and compute; not the right pick if you have fewer than 10k labeled clips. Deployment requires careful attention to quantization to fit on edge devices.
Autoencoder & VAE reconstruction
Why pick it. Unsupervised. Train on hours of “normal” footage, flag frames the model can’t reconstruct. No labels needed. Ideal when your anomaly class is “anything weird” rather than a specific event.
Limits. Assumes reconstruction error correlates with abnormality—often false. Prone to high false positives on lighting changes, camera shake, new objects that are normal-but-rare.
Self-supervised & contrastive (MoCo, SimCLR, VideoMAE)
Why pick it. Few-shot friendly. Pre-train on large unlabeled video, fine-tune on a few hundred labeled anomaly clips. Cuts labeling budget by 10× in our experience.
Limits. Pre-training is expensive. Only worth it if you can amortize that cost across multiple deployments or sites.
Reach for a Transformer when: you have >50k labeled clips, need long-range temporal context (fights, falls, crowd flows), and can afford Orin NX-class edge hardware. Stick with I3D or CNN + rules if you have less data or tighter BOM budgets, and add a VLM check only where false alarms are expensive.
Vision-language models (VLMs) as a second stage
Why pick it. A VLM such as Cosmos Reason 2 (served through the DeepStream 9.0 nvvllmvlm plugin, 2026) or a cloud model looks at the 5–20 seconds around an alert and answers a plain question: “Is this a person climbing the fence, or a shadow?” No retraining for a new anomaly class; you change the prompt.
Limits. Seconds of latency and a GPU bill per clip, so it can’t watch every frame of every camera. Use it on the few clips a fast detector already flagged, keep a human on the final call, and log every prompt and answer for audit.
Comparison matrix: which model for which job
| Model family | Best for | Labels needed | Edge-friendly | Typical AUC (public benchmarks) |
|---|---|---|---|---|
| 2D CNN | Object & zone rules | 1–5k labeled frames | Yes (Jetson Nano+) | 0.75–0.85 |
| 3D-CNN / I3D | Fights, falls, running | 5–50k clips | Orin Nano+ | 0.82–0.90 |
| Video Transformer | Long-context crowd & scene anomalies | 50k+ clips | Orin NX+ | 0.86–0.97 |
| Autoencoder / VAE | “Anything weird” unsupervised | None (normal footage only) | Yes (Jetson Nano+) | 0.70–0.82 |
| Self-supervised fine-tune | Few-shot, multi-site | 100–500 clips per site | Orin Nano+ | 0.80–0.92 |
| VLM verifier (2nd stage) | Confirming flagged clips, new classes by prompt | None to a few hundred examples | Thor-class or cloud GPU | Not benchmarked as AUC |
Reference architecture: edge, cloud, or hybrid
The architecture decision dominates cost and latency far more than the model choice. Three patterns exist; hybrid wins for almost every serious deployment.
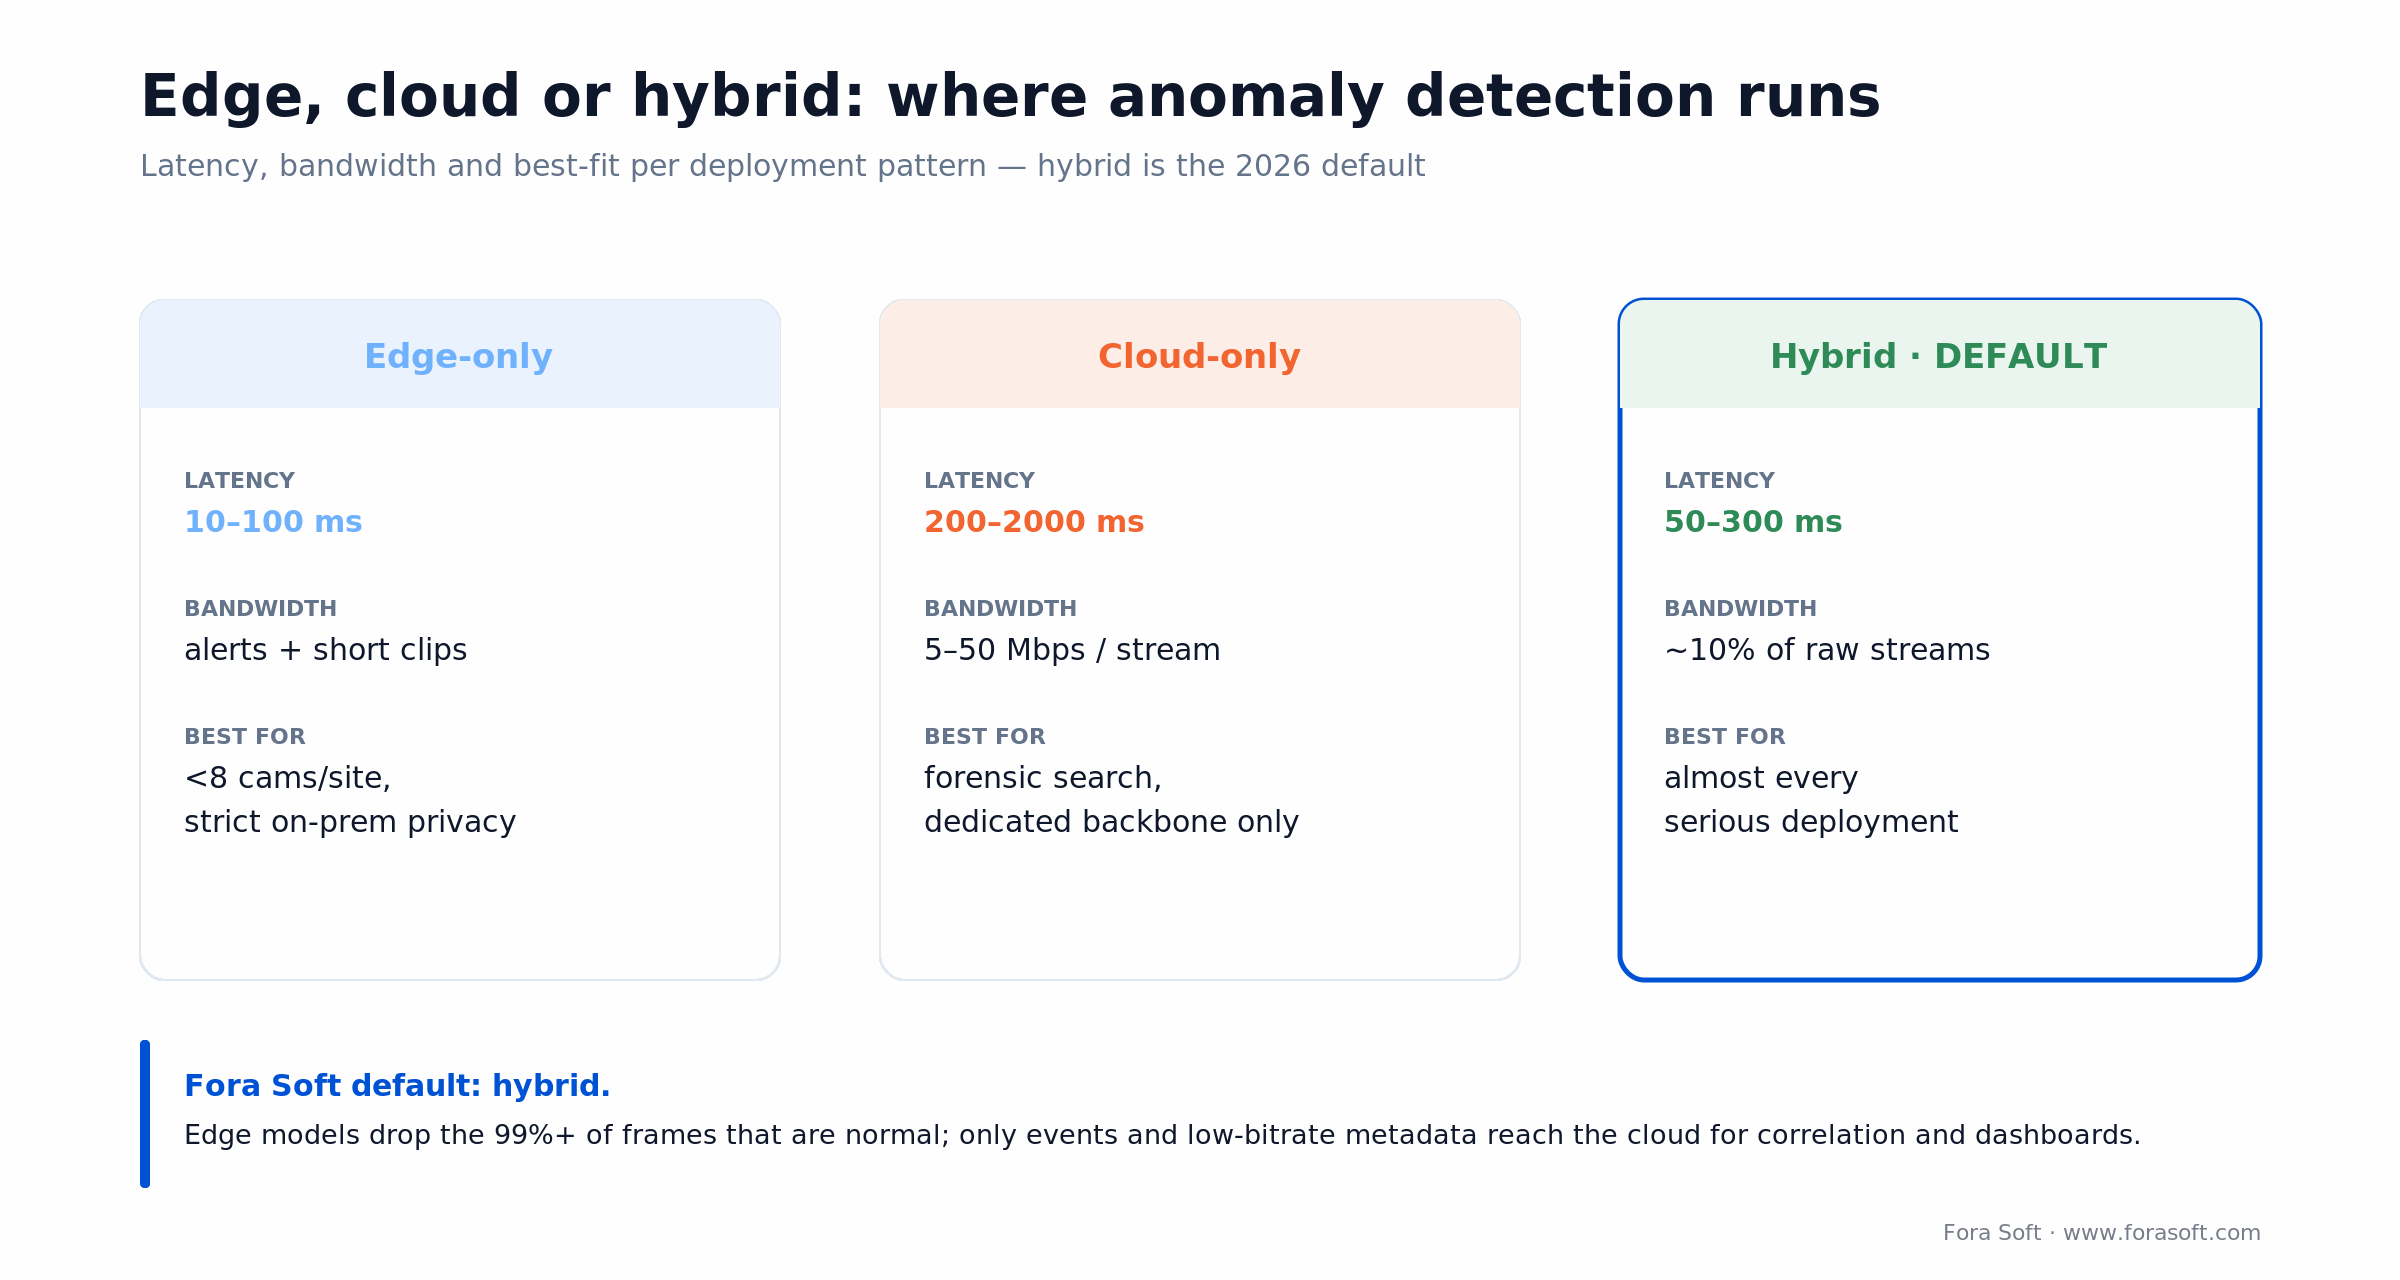
Figure 3. Where detection runs — edge, cloud or hybrid — and why hybrid wins most serious deployments.
Edge-only
Detection runs on the camera or a local Jetson/Hailo module. Latency 10–100 ms. Bandwidth to headquarters is just alerts plus short event clips. Works offline. Best for fewer than 8 cameras per site or strict privacy regimes where raw video must stay on-premise.
Cloud-only
All streams go to AWS/GCP for inference. Latency 200–2,000 ms. Bandwidth: ~5–50 Mbps per stream. A 500-camera site at 4 Mbps average pushes 2 Gbps around the clock, about 21.6 TB a day. Inbound transfer into AWS itself is free (AWS EC2 data transfer pricing, 2026), so the bill comes from a dedicated 2 Gbps+ uplink, GPU instances that decode and analyze 500 streams 24/7, and hot storage. Only justifiable for forensic search, low-rate polling, or when the customer already has a dedicated backbone.
On-prem vs cloud for 500 cameras: which is cheaper?
For continuous real-time analytics on 500 cameras, on-prem or edge inference is cheaper in almost every case we have priced. Edge boxes are a one-time cost (for example 125–250 Orin Nano Super-class appliances at 2–4 streams each), while cloud-only inference pays every month for the uplink and for GPUs that never idle. Cloud wins only when you analyze a small slice of footage on demand: Amazon Rekognition Video charges $0.10 per minute for stored-video label detection (AWS pricing page, October 2026), which is fine for investigations and ruinous at 720,000 camera-minutes a day. Transportation agencies and other buyers that cannot use cloud at all get the same answer: hybrid with an on-prem correlation server instead of a cloud one.
Hybrid (edge detection + cloud correlation)
Edge models filter the 99%+ of frames that are normal; only events and low-bitrate metadata travel to the cloud, where you do multi-camera correlation, long-term pattern mining, and dashboard/UX. Latency 50–300 ms. Bandwidth ~10% of raw streams. This is the default for everything Fora Soft ships today.
Reach for cloud-only when: you need forensic search across historical footage (BriefCam-style) more than real-time alerting, and bandwidth is not a concern. Everyone else should default to hybrid.
Edge hardware: what to put in the BOM
Your edge chip decides how many streams per box you can analyze and what models fit. The 2026 shortlist changed in two ways: the Orin Nano got a “Super” mode that lifted it from 40 to 67 TOPS at the same $249, and the Blackwell-based Jetson Thor family made on-prem VLMs practical.
| Device | AI performance | Power | Price (2026) | Best for |
|---|---|---|---|---|
| Jetson Orin Nano Super | 67 INT8 TOPS (sparse) | 15–25 W (Super modes) | $249 developer kit | 2–4 streams, CNN/I3D, small YOLO |
| Jetson Orin NX 16GB | 157 INT8 TOPS (sparse, Super mode) | 10–40 W | module, distributor quote | 8–16 streams, Transformer heads |
| Hailo-8 (M.2) | 26 INT8 TOPS | up to 8.25 W | ~$169 | Fixed CNN detectors on x86 or Arm gateways |
| Hailo-8L (M.2) | 13 INT8 TOPS | up to 6.6 W | ~$85 | Single-camera or battery-powered nodes |
| Jetson AGX Thor / T4000 | 2,070 / 1,200 FP4 TFLOPS (sparse) | 40–130 / 40–75 W | $3,499 AGX Thor developer kit | On-prem VLM verification for a whole site |
For most of our clients, a Jetson Orin Nano Super plus a local PoE switch covers 2–4 streams per appliance and clears standard anomaly models after TensorRT optimization. Step up to Orin NX when you need Transformer-class models or >8 streams per box, and to a Thor-class box per site when you want VLM verification without sending video to the cloud. Sources: NVIDIA Jetson announcements (December 2024, August 2025, July 2026) and Electromaker Hailo pricing (September 2026). For deployment detail (ONVIF Profile M metadata, thermal design and five-year TCO) see our video surveillance anomaly detection deployment playbook.
What a real-time pipeline looks like under the hood
A production pipeline is seven stages, not one model call. Missing any stage shows up as false alarms, latency spikes, or storage bills.
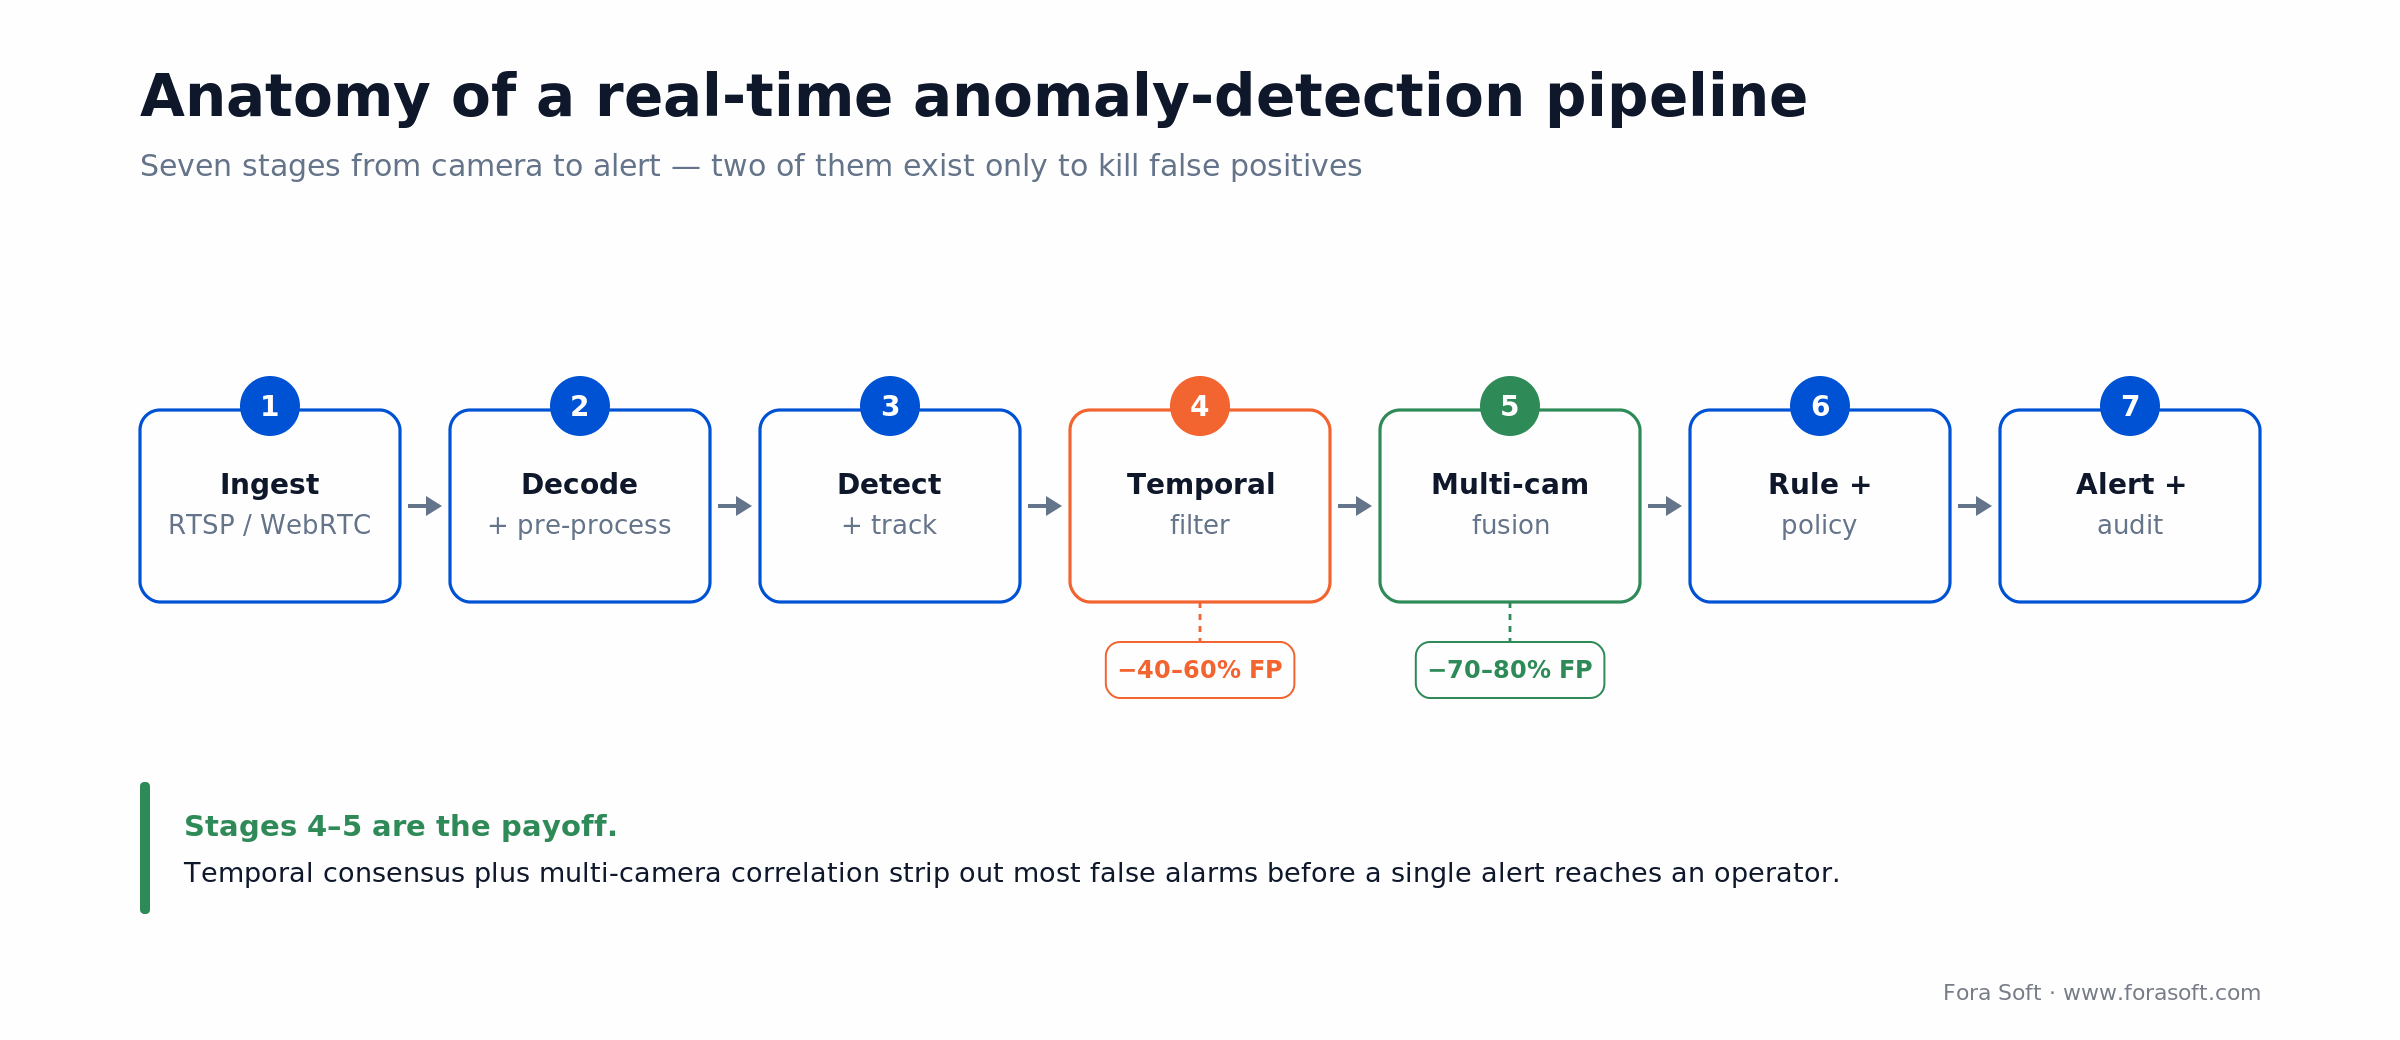
Figure 4. The seven stages of a real-time pipeline; stages 4–5 exist to strip out false positives.
1. Ingest. RTSP pull (ONVIF Profile S cameras) or WebRTC for newer stacks. Use GStreamer or NVIDIA DeepStream nvstreammux for multi-stream batching.
2. Decode & pre-process. H.264/H.265 hardware decode on NVDEC or the camera’s SoC. Histogram equalization and resolution crop for the model input.
3. Detection / tracking. YOLO26 (Ultralytics, January 2026, NMS-free export for edge) or RT-DETR for objects; ByteTrack for multi-object tracking that survives occlusion; I3D or Video Swin for temporal anomalies.
4. Temporal filter. Require an anomaly signal across 3–5 consecutive frames before firing an alert. This alone removes 40–60% of false positives at a 5–10 ms latency cost.
5. Multi-camera fusion. Correlate events across neighboring cameras via NTP-synced timestamps. Shared anomalies (e.g., a runner crossing two feeds in sequence) get scored higher.
6. Rule & policy engine. Geofences, schedules, access-control events. This is where you convert “person in zone” into “person in restricted zone during off-hours”.
7. Alert dispatch & audit trail. WebSocket to the ops console, push to mobile, write to an immutable audit log. The audit log is what sells you into regulated accounts—skip it and you lose every enterprise deal.
Need a second opinion on your pipeline design?
Send us the sketch. One of our video engineers will red-team it for latency, false positives and bandwidth before you commit to hardware.
Benchmarks and datasets: what “state of the art” actually means
When a vendor quotes a headline accuracy number, ask which dataset. The four that matter, ranked by difficulty:
UCF-Crime. 1,900 untrimmed videos, 128 hours, 13 real-world anomaly types (abuse, robbery, shooting, arson and more). The hardest common benchmark. Best published weakly supervised result we found: 90.33% frame-level AUC (π-VAD, CVPR 2025).
XD-Violence. 4,754 videos of violent behavior from films, sports and CCTV, weakly labeled, scored by average precision (AP), not AUC. RefineVAD (AAAI 2026) reports 88.66% AP.
ShanghaiTech Campus. 13 campus scenes, controlled splits. Easier than UCF-Crime; top weakly supervised methods report 97–98% AUC.
CUHK Avenue. One campus walkway, 16 training and 21 test clips (running, throwing objects, wrong direction). Saturated: high-90s AUC is common, so a vendor quoting Avenue alone tells you little.
Real-world warning: in our projects, deployment on a new site typically costs 15–25 points of AUC in the first week because of domain shift. A model that hits 0.90 on ShanghaiTech can land at 0.70–0.75 on day one. Budget a retraining sprint on your own labeled data. The full model-by-dataset table lives in our video anomaly detection models comparison.
The false-positive problem (the only thing operators actually care about)
An untuned model fires a false alarm on 30–70% of events. Past about 30 false alerts per camera per day, human operators start ignoring 40–70% of everything the system raises—including the real events. Every mature deployment spends more engineering on false-positive suppression than on the detector itself.
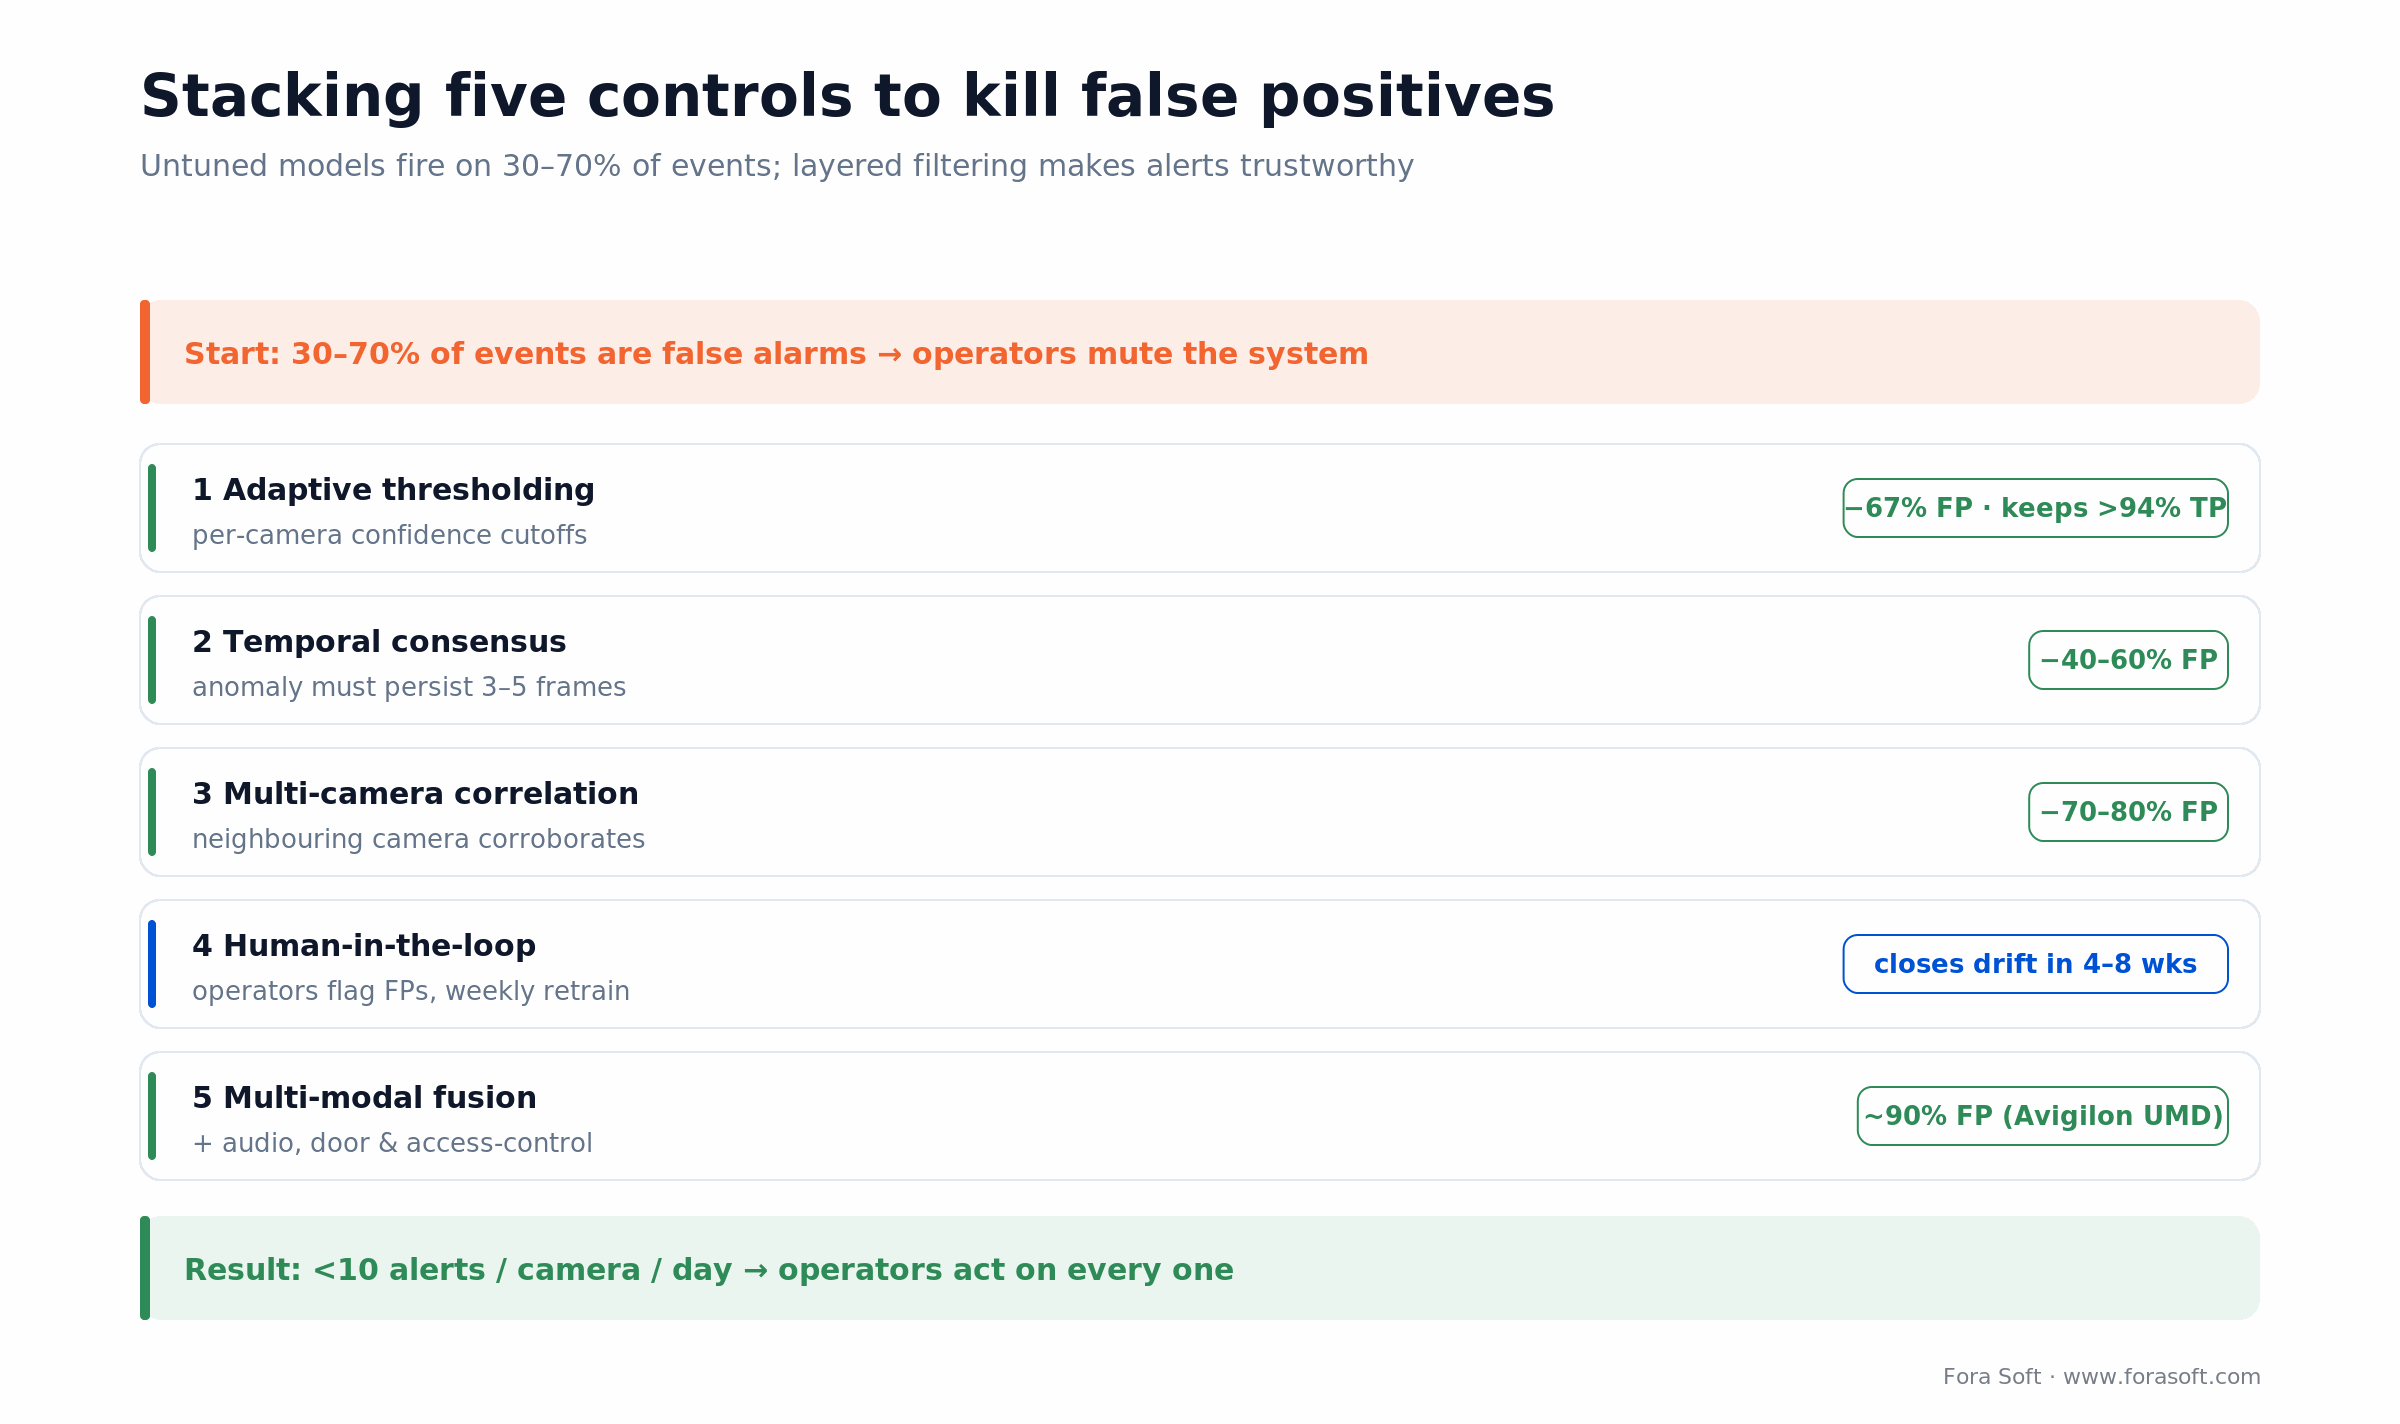
Figure 5. Layering five controls turns a 30–70% false-alarm rate into alerts operators actually trust.
Five layers actually work, in combination:
1. Adaptive thresholding. Tune per-camera confidence cutoffs on-site. Published adaptive methods report 67% false-positive reduction while keeping >94% true-positive rate.
2. Temporal consensus. Require the anomaly to persist across 3–5 consecutive frames. 40–60% false-positive reduction at negligible latency cost.
3. Multi-camera correlation. Alerts corroborated by a neighboring camera score higher. 70–80% false-positive reduction on regional events.
4. Human-in-the-loop feedback. Let operators flag false positives from the UI; retrain weekly on that feedback. Closes the domain-shift gap in 4–8 weeks.
5. Multi-modal fusion. Combine video with audio, door sensors, access-control events, and (for industrial sites) machine telemetry. Avigilon’s self-learning UMD reports roughly 90% false-alarm reduction in the field. For the non-video streams in that mix, our anomaly detection guide for tabular and time-series data covers Isolation Forest, ECOD and forecaster-based detectors.
How agentic AI correlates alarms, access logs and camera events
Agentic AI cuts false alarms by checking each alert against the other systems a guard would check by hand. When a detector fires, an agent pulls the access-control log for that door, the schedule for that zone, the neighboring cameras and, in retail, the POS transaction. It then asks a vision-language model to describe the clip and decides whether to escalate, attach context, or close the alert with a reason. The operator sees fewer alerts, and each one arrives with the evidence already gathered.
Three correlations pay off first in our projects:
- Door-held and tailgating. A badge swipe for one person plus two people through the door in the video is a real alert; a door-held alarm with nobody in frame is not.
- Schedule and role. Motion in a server room at 02:00 by someone whose badge was just used at that door, during a booked maintenance window, gets logged, not escalated.
- Transaction vs video. On Live Eye, a retail surveillance platform we built, the system matches POS transactions to video in real time and alerts owners within 30 seconds when fewer items are scanned than bagged.
The tooling matured in 2026. NVIDIA’s VSS Blueprint 3 (announced at GTC in March, GA in June 2026) packages agentic search over video events, and DeepStream 9.0 can run a VLM inside the pipeline. Guardrails matter more than the model: the agent recommends, a person decides on anything that dispatches a guard or calls the police, every prompt and answer goes into the audit log, and the agent never identifies people by face. If you want this layer built on top of your existing VMS, our AI video agent development team builds the detector, the correlation rules and the VLM verification step as one pipeline.
Buy vs build: third-party platforms you’ll compare against
Any honest custom-build pitch starts by comparing the platform market. If one of these gets you 80% of what you want at 40% of the cost, buy it. Most VMS vendors no longer publish list prices, so the table shows how each one charges; get quotes for your camera count. If your anomaly class is domain-specific, our computer vision development services cover the detector, the tracker and the alert logic that runs 24/7.
| Platform | Sweet spot | Pricing model (2026) | Pick it when |
|---|---|---|---|
| Avigilon (Motorola Solutions) | Self-learning anomaly + unified cameras | Camera hardware + per-channel software licenses, quote-based | Managed service, <100 cameras |
| Genetec Security Center | Enterprise unified video + access control | Per-camera and per-door licenses, quote-based | >500 cameras, security is a business function |
| Verkada | Cloud-native SMB | Camera hardware + per-device annual license, quote-based | No IT staff, fast rollout <200 cameras |
| BriefCam | Forensic search, video synopsis | Per-camera license, quote-based | Investigation > real-time alerting |
| Amazon Rekognition Video | Pay-per-minute analysis | $0.10/min stored-video label detection; $0.00817/min streaming events (AWS, 2026) | Sporadic or event-triggered analysis |
| NVIDIA DeepStream + VSS | Developer SDK and blueprints | Free SDK; enterprise support via NVIDIA AI Enterprise subscription | Custom pipeline, in-house or partner engineering |
Reach for a custom build when: you have >200 cameras, a domain-specific anomaly class no vendor covers (pharmaceutical clean-room breach, cockpit compliance, courtroom behavior), or a data-residency requirement that rules out cloud-only VMS.
Cost model: a realistic 100-camera deployment
Planning is easier with concrete numbers. Here’s how a 100-camera anomaly-detection deployment lands across the three sourcing paths, at typical 2026 market rates. These ranges assume off-the-shelf anomaly classes (intrusion, loitering, fights, falls). Domain-specific anomalies push custom-build cost up.
| Cost bucket | Off-the-shelf VMS | Hybrid (edge + SaaS) | Custom build (Fora Soft) |
|---|---|---|---|
| Initial CapEx | $100k–250k | $80k–180k | $50k–150k |
| Dev timeline | 2–6 weeks setup | 2–4 months | 4–8 months MVP |
| Annual OpEx | $50k–200k | $30k–120k | $20k–80k |
| Ops staffing | 0.25–0.5 FTE | 0.5–1 FTE | 1–2 FTE |
| 5-year TCO | $350k–700k | $250k–600k | $200k–500k |
Our agent-engineering workflow (LLM-assisted coding, reusable internal libraries for ingest/decoding/tracking/UI) shortens the custom-build timeline versus the baseline industry figures above. The “$50–150k initial” range reflects that, not a low-ball—talk to us with a concrete camera count before you anchor to a number.
Mini case: VALT and Live Eye in production
VALT is the video recording and observation platform we have built and maintained as Intelligent Video Solutions’ sole development team for 10+ years. It runs in 770+ U.S. organizations with 50,000+ active users: police interview rooms, medical simulation labs, child advocacy centers. The core job is recording, review and rule-based flagging (motion detection, scheduled recording, PTZ presets, word search inside recordings via Amazon Transcribe), under HIPAA and GDPR.
Live Eye is the other end of the spectrum: AI-powered cloud surveillance for retail, restaurants, hotels and banks, with behavioral anomaly alerts, POS-to-video matching and local storage with encrypted cloud backup. It is the contextual-anomaly pattern from the taxonomy above, running in production.
Two lessons carried over to every surveillance build since: invest in the audit trail and permission model early, because regulated buyers won’t sign without them, and keep the “rules” engine independent of the ML model so non-engineers can add and tune alert policies. Want a similar assessment for your deployment?
A decision framework in five questions
Q1. How many cameras, at how many sites? Below 50 cameras at one site, a commercial VMS like Verkada or Avigilon wins on TCO. Above 200 cameras or across multiple sites with data-residency rules, custom starts to make sense.
Q2. Are your anomalies in the off-the-shelf catalog? Intrusion, loitering, fights, falls, abandoned objects, crowd density—all covered by BriefCam, Avigilon and Verkada. Domain-specific classes (clean-room breach, procedural non-compliance, cockpit behavior, courtroom signals) are not. That’s where custom earns its fee.
Q3. What is your latency budget? Live intervention (robbery, violence) needs <100 ms alerts; forensic review is fine at minutes. Tight latency forces edge or hybrid; forensic can live in the cloud.
Q4. Where does the data legally live? The EU AI Act and GDPR effectively rule out cloud-first face-recognition deployments, and biometric systems become high-risk on 2 December 2027. If your buyer is a public body or an EU enterprise, default to edge + on-prem storage, detect objects and behavior only.
Q5. Who will retrain the model? Domain shift costs 15–25% AUC on day one. If you don’t have a plan for weekly retraining on site data, pick a vendor that owns that burden or sign a maintenance contract with your custom-build partner.
Five pitfalls that sink deployments
1. Benchmarking on the wrong dataset. Shipping a model that hits 0.95 AUC on ShanghaiTech into a warehouse yard will embarrass you. Always fine-tune on 500+ site-specific clips and report real-world AUC, not research numbers.
2. Treating false positives as a post-launch problem. By the time operators tell you alerts are noisy, they’ve already muted notifications. Temporal filtering, adaptive thresholds and multi-camera fusion go into the MVP, not the backlog.
3. Streaming every camera to the cloud for inference. 500 cameras at 4 Mbps is about 21.6 TB a day and a 2 Gbps uplink that never rests, plus GPUs that analyze every frame. Edge inference is not an optimization, it’s a line-item survival move.
4. Ignoring domain shift and seasonal drift. “Loitering” in an outdoor mall has different baselines in July and December. Without scheduled retraining or online learning, alert precision degrades inside three months.
5. Skipping the audit trail. Regulated buyers (healthcare, law enforcement, courts, finance) walk away the moment they see you can’t produce a tamper-evident log of every alert, every override and every model change. Bolt this on in week one of the build, not month six.
KPIs: what to actually measure
Quality KPIs. Precision and recall on site-specific clips (not public benchmarks). Target: precision ≥ 0.9 at recall ≥ 0.85 after three retraining cycles. Track AUC drift weekly.
Business KPIs. Alerts per camera per day (target <10), operator acknowledgement rate (>80%), time-to-first-response on true positives (<60 s), and percentage of real incidents caught by the system vs. discovered later (>85%).
Reliability KPIs. Edge appliance uptime (99.5%+), detection-to-alert latency p95 (<500 ms), and training pipeline health (successful retraining runs/month, >90%).
Privacy, GDPR and the EU AI Act: what you can and can’t ship
Regulation separates “anomaly detection” into three bands, and the dates moved in 2026. The Digital Omnibus on AI (Regulation (EU) 2026/1744, in force 27 July 2026) kept the bans but pushed most high-risk obligations back.
Low-risk (shippable today). Object detection, motion anomaly, behavior anomaly that does not identify or categorize individuals: crowd density, loitering by silhouette, intrusion, fall and fight detection. Requires a GDPR legal basis, signage and a data protection impact assessment.
Prohibited since 2 February 2025. Real-time remote biometric identification in publicly accessible spaces for law enforcement (narrow exceptions), untargeted scraping of CCTV or the internet to build face databases, biometric categorization that infers race, religion or similar traits, and emotion recognition in workplaces and schools, all under Article 5 of the EU AI Act. Fines reach €35M or 7% of worldwide turnover.
High-risk from 2 December 2027. Other remote biometric identification (including after-the-fact face or gait search), permitted biometric categorization and emotion recognition fall under Annex III. They need risk management, logging, human oversight and a conformity assessment; the Omnibus moved the date from 2 August 2026.
Practical guidance: design for the low-risk band by default. If a buyer insists on facial recognition, scope it as a separate high-risk engagement with its own compliance budget. Enforcement under GDPR already bites: France’s CNIL fined Clearview AI €20M in 2022, and the Dutch DPA added €30.5M in September 2024.
Need a GDPR-safe anomaly detection stack?
We’ve shipped video products into regulated environments since 2005. Send us your compliance zone and we’ll shortlist the models and deployment pattern that won’t get you fined.
When machine-learning anomaly detection is the wrong answer
ML is not a universal surveillance upgrade. Three situations where a rule-based system or a plain human operator is a better fit:
Tiny camera counts with dense human coverage. A single parking-lot camera watched by a 24/7 guard doesn’t benefit enough from an ML layer to justify the hardware, licensing and retraining burden.
Zero training data and zero operator bandwidth. ML needs weeks of labeled “normal” footage plus a feedback loop from operators. If both are missing, a well-tuned motion-detection rule beats an under-trained model.
Life-safety with deterministic rules. Fire, smoke and gas detection are better handled by dedicated sensors than by ML on video. Use video as confirmation, not as primary signal.
A minimal DeepStream pipeline (for engineers scoping this)
For the engineers reviewing this playbook, here’s the skeleton of a multi-stream detection pipeline on Jetson. Useful to set hardware expectations during procurement; not production-ready.
# DeepStream reference pipeline, 4 RTSP streams -> YOLOv8 -> tracker -> sink
gst-launch-1.0 \
  nvstreammux name=mux batch-size=4 width=1280 height=720 live-source=1 ! \
  nvinfer config-file-path=/opt/yolov8.txt ! \
  nvtracker ll-lib-file=/opt/libnvds_nvmultiobjecttracker.so ! \
  nvinfer config-file-path=/opt/anomaly_i3d.txt ! \
  nvmultistreamtiler rows=2 columns=2 ! \
  nvvideoconvert ! nvdsosd ! \
  nveglglessink \
  rtspsrc location=rtsp://cam1:554/h264 ! rtph264depay ! h264parse ! nvv4l2decoder ! mux.sink_0 \
  rtspsrc location=rtsp://cam2:554/h264 ! rtph264depay ! h264parse ! nvv4l2decoder ! mux.sink_1 \
  rtspsrc location=rtsp://cam3:554/h264 ! rtph264depay ! h264parse ! nvv4l2decoder ! mux.sink_2 \
  rtspsrc location=rtsp://cam4:554/h264 ! rtph264depay ! h264parse ! nvv4l2decoder ! mux.sink_3
An Orin Nano clears four 1080p streams with a YOLOv8-s detector and an I3D anomaly head after TensorRT optimization. Swap in a Transformer head and you’ll want Orin NX or better.
FAQ
Can agentic AI correlate alarms, access logs and camera events to reduce false positives?
Yes. An agent checks each detector alert against the access-control log, the zone schedule, neighboring cameras and, in retail, POS data, then asks a vision-language model to describe the clip before deciding whether to escalate. Keep a human on any decision that dispatches people and log every agent step for audit.
On-prem vs cloud AI video analytics: which is cheaper for 500 cameras?
For continuous real-time analytics, on-prem or edge inference is cheaper: 500 cameras at 4 Mbps need a permanent 2 Gbps uplink and GPUs analyzing about 21.6 TB of video a day in the cloud. Cloud pricing such as Rekognition’s $0.10 per stored-video minute (2026) only makes sense for on-demand forensic search.
What is real-time machine learning in video security?
It is running trained models on live camera streams so that an alert reaches an operator within a second or less, usually on edge hardware next to the cameras. The model scores each frame or clip as it arrives, rather than analyzing recorded footage later.
How accurate is ML-based video anomaly detection in real deployments?
Public benchmark scores sit between about 0.85 and 0.98 depending on dataset difficulty; the best published UCF-Crime result is 90.33% AUC (π-VAD, CVPR 2025). In the field, expect a 15–25 point drop in the first week because of domain shift. With 2–3 retraining cycles on site data, production precision of 0.90+ at recall 0.85+ is achievable on off-the-shelf anomaly classes.
What’s the realistic timeline for a custom video anomaly detection product?
A focused MVP for 3–5 standard anomaly classes on a single site lands in 4–8 months. Multi-site, multi-tenant platforms with rules engines, audit trails and operator UX take 9–14 months. Our agent-engineering workflow and reusable internal video-pipeline libraries compress those windows relative to industry baselines.
Can I run anomaly detection on existing IP cameras without replacing them?
Yes, in most cases. Any ONVIF Profile S or RTSP-capable camera pushes H.264/H.265 to an edge appliance (Jetson Orin Nano, Hailo-8, Ambarella gateway). That means your existing fleet keeps working; you add compute and software, not cameras.
How do I compare a custom build against Avigilon or Verkada?
Score on five axes: camera count, anomaly specificity, latency requirement, data-residency, and retraining ownership. Commercial VMS wins on the first row whenever your anomaly classes are generic and cameras are fewer than ~150. Custom wins above that, or when you need a domain-specific detector, tight audit trails or strict on-prem deployment.
Is facial recognition legal for my project under the EU AI Act?
Real-time remote biometric identification in public spaces for law enforcement has been prohibited since 2 February 2025, with narrow exceptions. Most other biometric uses are high-risk and, after the 2026 Digital Omnibus, need a conformity assessment, logging and human oversight from 2 December 2027. For most anomaly-detection use cases, avoid facial recognition entirely and rely on object and behavior signals.
How do I reduce false positives without missing real events?
Layer five controls: adaptive per-camera thresholds, temporal consensus across 3–5 frames, multi-camera correlation, a human-in-the-loop feedback UI, and multi-modal fusion (audio, door sensors, access control). Published adaptive-threshold methods report 67% false-positive reduction at >94% true-positive rate.
What edge hardware should I standardize on in 2026?
Jetson Orin Nano Super ($249 developer kit, 67 TOPS) for 2–4 streams with CNN/I3D models; Orin NX 16GB (157 TOPS in Super mode) for Transformer-class models or 8+ streams; Hailo-8 (26 TOPS) or Hailo-8L (13 TOPS) for low-power gateways and cameras; a Jetson Thor-class box per site if you want on-prem VLM verification. Avoid the original Jetson Nano for new projects; it is too slow for modern video models.
Who owns the model once the project ships?
In our custom builds, you do—source, weights, training data pipelines, the lot. That’s a key reason buyers pick custom over platform: no vendor lock-in, full right to retrain in-house or move providers. We offer maintenance contracts if you prefer us to own the retraining and drift-monitoring burden.
What to read next
Surveillance
Custom Video Surveillance Solutions With AI
End-to-end overview of how we scope and ship custom video surveillance products.
Real-time
Real-Time Anomaly Detection in Video Surveillance
Latency budgets, pipeline design and tuning strategies for live alerting.
Automation
Automated Anomaly Detection for Security Cameras
How to automate event triage on existing camera fleets without ripping them out.
Algorithms
Top Algorithms for Surveillance Anomaly Detection
Deeper dive into which algorithms ship well in security products and why.
Ready to scope ML anomaly detection for your fleet?
The shortlist is clear. Decide the anomaly classes, camera count and data-residency zone first. Pick hybrid as the default architecture, Jetson Orin Nano Super or Orin NX as the default edge chip, and I3D or Video Swin as the default model family, with a VLM verification stage only where false alarms are expensive. Invest in the false-positive stack (adaptive thresholds, temporal consensus, multi-camera fusion, operator feedback) from day one, not after launch.
Then run the build-vs-buy math honestly: if you’re under 150 cameras and your anomalies are generic, a commercial VMS probably wins. Above that, or if your anomaly class is domain-specific, custom is cheaper at five-year TCO and gives you model ownership. Fora Soft has been on the custom side of that line since 2005. Bring us your spec and we’ll tell you which side you’re on before you commit a dollar.

The book · Volume 7 of 7
AI for Video: A Complete Guide to Intelligence in Video Products: From Real-Time Pipelines and Agents to Serving, Cost, Compliance, and Verticals
The DeepStream pipeline above gets an alert out in under 100 ms; keeping it there across a 100-camera fleet is a serving and compliance problem. Volume 7 covers serving and infrastructure on Triton and TensorRT, cost per stream-hour, and the EU AI Act and biometric rules that shape what you can ship. It suits teams moving an anomaly model from pilot to production. Written by Nikolay Sapunov, CEO at Fora Soft.
Read it on Amazon →Kindle & paperback · Fora Soft Video Engineering Handbook
Let’s scope your ML video surveillance project
Share your camera count, anomaly classes and compliance zone. You’ll leave the call with a build-vs-buy verdict, a realistic timeline, and a rough budget band.

