

Key takeaways
• SIP translation integration means four services pipelined in real time. Capture, speech-to-text (ASR), machine translation (MT), and text-to-speech (TTS). Each adds latency, so the design of the pipeline determines whether users hear a natural conversation or a disjointed relay.
• End-to-end latency under 2 seconds is the usability threshold. Below 800 ms it feels live; above 3 seconds people start talking over each other. Every extra network hop or batch step costs you conversational quality.
• Architecture matters more than API choice. Streaming ASR with partial hypotheses, MT that tolerates interim text, and low-latency neural TTS together matter more than whether you picked Whisper, Deepgram, AssemblyAI, Azure, or Google.
• SIP is not the problem; the bridge is. A correctly designed media server (FreeSWITCH, Asterisk, Kamailio, LiveKit, Janus) with a sidecar AI pipeline solves the protocol side. The hard problems are speaker diarisation, overlap, barge-in, and how you place translated audio into the call.
• Pick languages by risk, not by reach. Healthcare, legal, financial, and regulated calls need certified human interpreters in the loop. AI translation is excellent for productivity, exploration, and most business meetings, but do not oversell accuracy where an error has legal or clinical consequences.
Updated October 2026: Google’s Gemini 3.5 Live Translate added as a second managed speech-to-speech option, telephony audio rules for the translation APIs, and EU AI Act dates after the Digital Omnibus.
Real-time multilingual conferencing, or SIP translation integration, has moved from novelty to expected feature in 2026. Global teams, customer support, cross-border sales, remote healthcare, international education, and legal proceedings all increasingly expect that a call in English, Spanish, Mandarin, Arabic, or Russian can be bridged in real time without a dedicated interpreter. The engineering that makes this feel magical is not a single vendor’s API; it is a carefully designed pipeline across ASR, MT, TTS, and SIP media handling.
This playbook is written for CTOs, product leads, and founders integrating real-time translation into a SIP- or WebRTC-based conferencing product: contact centres, telehealth, legal tech, virtual classrooms, unified communications, and any platform where calls cross languages. We cover what the pipeline actually looks like, the latency budget, the ASR / MT / TTS vendor stack, SIP architecture patterns (including PSTN bridging), when to add a human interpreter, accuracy and bias considerations, cost math, decision framework, KPIs, and the pitfalls that make demos look great and production feel broken.
Short answer. SIP translation is real-time speech translation added to a SIP or PSTN call: the media server forks each caller’s audio to a translation pipeline and plays the translated speech back into the call, usually 1–2 seconds behind the speaker. Three kinds of solution do this with live telephony in 2026: a managed speech-to-speech model (OpenAI gpt-realtime-translate or Google Gemini 3.5 Live Translate) behind your own media bridge; a chained streaming ASR → MT → TTS pipeline on FreeSWITCH, Asterisk or LiveKit; and a human over-the-phone interpreter conferenced into the call as an extra leg. In carrier engineering “SIP translation” can also mean rewriting numbers or headers on a session border controller; this playbook is about language.
Why Fora Soft wrote this playbook
Fora Soft is a software development company that has built real-time video and voice products since 2005 — 250+ projects with 50+ in-house specialists and has specialised in the AI-audio layer that SIP translation depends on. We run dedicated practices for speech-to-text, text-to-speech, AI language interpretation, real-time speech translation, and multimodal agentic AI. That is the literal stack a SIP translation product needs.
Across our portfolio, ProVideoMeeting ships enterprise video conferencing with digital signatures and SIP/PSTN dial-in for compliance-heavy tenants. BrainCert runs WebRTC virtual classrooms for 100,000+ customers and 500M+ classroom minutes across many languages. Speakk and The Language Chef are language-learning products where ASR and TTS quality is the product. CirrusMED demonstrates HIPAA-grade WebRTC for regulated consults, the same compliance posture that governs medical SIP translation.
Two of those builds map almost one-to-one onto SIP translation. TransLinguist is a video interpretation platform we developed for remote simultaneous interpretation and AI speech-to-speech translation. TransLinguist won an appointment to the NHS (NOE CPC) language services framework. Nucleus is an on-prem communications platform we develop that handles 600M+ AI-assisted phone minutes a month under SOC 2 and HIPAA. Between them we have already shipped most of the hard parts this playbook describes.
Our AI integration and video conferencing teams own the two halves of this stack, and we lean on Agent Engineering across delivery, which compresses the build phase of real-time AI integrations compared with traditional outsourcing. If you are scoping a SIP translation feature, that speed usually matters — the vendor options shift week by week.
Planning real-time translation inside your SIP or WebRTC product?
Book a 30-minute scoping call. We will walk through your call flow, latency budget, and vendor options — and tell you what a working MVP actually looks like.
What SIP translation integration actually means
Strip the marketing away and SIP translation integration is a four-stage streaming pipeline attached to a SIP or WebRTC media path, with careful handling of who hears what.
1. Capture. The media server forks each participant’s audio stream to an AI sidecar. Forking is preferable to interception so the original call keeps flowing if the AI pipeline has an issue.
2. Streaming ASR. The sidecar runs automatic speech recognition that produces partial and final hypotheses in near real time — not a batch transcript at end-of-utterance, which is far too slow.
3. Streaming MT. Partial source text is translated incrementally. Modern neural MT can handle interim text with context carry-over, but quality is sensitive to latency versus hypothesis stability.
4. Streaming TTS. The translated text is synthesised, streamed back into the media server as a separate audio track, and routed to the participants who need that language — usually mixed with the original at low gain so users can confirm tone.
Everything else — language auto-detection, speaker diarisation, per-user language preferences, transcript archive, and PSTN bridging — is supporting infrastructure around that four-stage pipeline.
Barge-in deserves its own paragraph, because it is the failure people actually notice. Translated audio lands one to two seconds late, so the far side often starts talking while the synthetic voice is still playing their last sentence. Handle it explicitly: detect speech on the interrupting leg, stop TTS playback mid-utterance rather than letting the buffer drain, drop the unplayed remainder instead of queueing it, and let the new utterance take the floor. A pipeline that finishes every sentence it started sounds calm in a demo and unusable in an argument.
Reach for the full pipeline when: calls regularly cross languages, participants are not all technical, and interpreter scheduling is a bottleneck — typical in contact centres, telehealth, legal, and global enterprise UC.

Figure 1. The four streaming stages of a SIP translation pipeline, with the realistic per-stage latency budget.
The latency budget that decides everything
The entire user experience of SIP translation is determined by end-to-end latency — mouth to ear, across the bridge. Product decisions, vendor choices, and architecture all collapse down to this one budget.
A usable conversation needs translated audio reaching the listener within 1–2 seconds of the source utterance. Above 3 seconds, both parties talk over each other and the feature feels broken. Below 800 ms, it feels like live simultaneous interpretation. Getting from “broken” to “great” means spending a fixed budget across five stages that simply add up.
| Stage | Aggressive budget | Realistic budget | How to keep it there |
|---|---|---|---|
| Capture & fork | 50 ms | 100 ms | Co-locate media server and AI sidecar; Opus 20 ms frames |
| Streaming ASR | 150 ms | 300 ms | Partial hypotheses, endpointing, VAD tuning |
| Streaming MT | 150 ms | 400 ms | Incremental decoder; context cache per session |
| Streaming TTS | 200 ms | 500 ms | Chunked synthesis; short-sentence buffers |
| Return to listener | 50 ms | 150 ms | Same-region media; server-side mixer |
| Total, pipeline stages | ~600 ms | ~1.5 s | Architecture + vendor + region choices |
Latency is additive, and that is the good news: shave 20 percent off every stage and the total drops 20 percent, from 1,450 ms to 1,160 ms. Nothing compounds, and nothing hides.
One budget line sits outside that table and catches teams out: transport. Packetisation at 20 ms frames, trunk transit, and the de-jitter buffer at the receiving end are spent before your pipeline sees a sample and after it returns one. On a clean same-region WebRTC leg that is 30–40 ms. On a PSTN leg with a conservative fixed jitter buffer it is routinely 100 ms or more, which is why the same stack feels slower on a phone than in a browser. Add it to the table’s pipeline total and true mouth-to-ear lands near 1.49 s on a clean WebRTC leg and comfortably past 1.55 s on a PSTN one — which is how a stack that hits the 1.5 s KPI in your browser misses it on a phone. Use an adaptive jitter buffer rather than a fixed one, and measure on the phone leg, not on your laptop.
The single biggest win most teams leave on the table is co-locating the media server and the AI sidecar in the same cloud region — a stream that crosses two continents and back can add 100–400 ms to an already tight budget, and it is the one line you can remove by moving a container.

Figure 2. Latency is additive: the same pipeline at an aggressive ~600 ms and a realistic ~1.5 s, stage by stage.
What good SIP translation looks like in 2026
Good real-time SIP translation in 2026 means the listener hears a faithful translation within about 1.5 seconds, on real phone-band audio, with only a handful of words lost. That target is not aspirational any more — it is roughly what the best streaming stacks already ship.
The market moved fast this year. In June 2026 Google moved Meet speech translation onto Gemini 3.5 Live Translate, going from five English-paired languages to 70+ languages and 2,000+ combinations in one meeting, in private preview for business customers first (Google, 2026). Microsoft’s Interpreter agent for Teams covers nine languages in meetings and 1:1 Teams VoIP calls, but not 1:1 PSTN calls (Microsoft Learn, September 2026); interpretation on Teams Phone devices sits on the Microsoft 365 roadmap (item 553594). Translation stopped being a differentiator and turned into something buyers expect a conferencing product to have. What the big suites still leave open is the phone network, and that is exactly where a SIP translation build earns its keep.
The numbers back that up. Deepgram’s Nova-3 reports a median streaming word-error rate of 6.84% at roughly 300 ms of end-to-end latency (Deepgram, 2025). Newer streaming models push further, on vendor-reported numbers: Google gives 4.0% streaming word-error rate for Gemini 3.5 Transcribe across 85+ languages (Google, September 2026), and Deepgram’s Flux Multilingual handles 10 languages with code-switching inside one conversation and end-of-turn decisions in under 400 ms (Deepgram, April 2026). Neural text-to-speech got fast enough to stop being the bottleneck: ElevenLabs quotes about 75 ms of model inference for its Flash models (ElevenLabs docs, 2026). Read that as model inference time, not time-to-first-audio over the wire — add the network and you are realistically at 150–300 ms. Meta’s open streaming speech-to-speech model showed you can translate before the speaker finishes a sentence, at roughly two seconds of latency, taking speech in about 100 languages but speaking it back in 36 (Meta, 2023).
Why 1.5 seconds and not three? Human conversation runs on a roughly 200 ms turn-taking gap (Stivers et al., 2009), and telephony engineers have targeted one-way delay under 150 ms for transparent interactivity for decades (ITU-T G.114). Live interpreters cope by running an ear-voice span of about two seconds; that is the window a translated call has to live inside before people start colliding.
So “good” in 2026 is measurable: p50 mouth-to-ear under 1.5 s, ASR word-error under 10% on your own call recordings, and a voice natural enough that users forget it is synthetic. Anything slower or noisier still reads as a demo, not a product.
Reach for AI real-time translation when: calls routinely cross languages, latency can be held under two seconds, and a mistranslation is inconvenient rather than dangerous — most business meetings, support, and cross-border sales.
The four pipeline components in detail
Streaming ASR — the foundation
ASR quality dominates downstream translation quality; a bad transcript produces a confident-sounding wrong translation. Streaming ASR for SIP translation needs: partial hypotheses emitted every 100–300 ms, voice activity detection that adapts to phone-band audio, reliable endpointing, and language identification when the source language is not known up front.
Current strong candidates: Deepgram Nova, AssemblyAI Universal-Streaming, Google Cloud Speech-to-Text Chirp, Azure Speech, OpenAI Whisper (via server hosting like Replicate or self-hosted), NVIDIA Parakeet and Canary, Speechmatics, and Rev AI. Whisper is excellent offline but not out-of-the-box streaming without architectural work. Deepgram and AssemblyAI ship mature streaming APIs; Google and Azure are solid but typically higher latency.
Streaming MT — the conversation engine
Machine translation for live calls is different from document MT. It must tolerate interim input, preserve speaker context across utterances, handle code-switching (Spanglish, mixed Mandarin-English), and get named entities right. Systems worth testing: Google Translate (the Cloud Translation Advanced API, driven with interim text), DeepL Translator API, Microsoft Azure Translator, Amazon Translate, LLM-based pipelines using frontier LLMs, or open-source (M2M-100 under MIT, MADLAD-400 under Apache-2.0) with a streaming wrapper. Check the licence before you build on it: NLLB-200 and Meta’s open speech-translation models ship under CC-BY-NC-4.0, and Coqui’s XTTS v2 under a non-commercial licence from a company that dissolved in 2024 — none of the three can legally run in a commercial product.
LLMs are increasingly competitive for conversational MT because they handle context and politeness markers better. The trade-off is latency — a raw LLM call per utterance is usually too slow; the pattern is a short-context streaming LLM call with a cached session state.
Streaming TTS — the voice your users hear
TTS shapes the perceived quality of the whole feature. Modern neural TTS is striking — ElevenLabs, Cartesia, OpenAI TTS, Google Cloud TTS, Azure Neural Voices, Amazon Polly Neural. Check the vendor is still trading before you design around it — PlayHT, a staple of every 2024 shortlist, was acqui-hired by Meta in 2025 and wound down. For SIP translation the key properties are: sub-300 ms first-audio latency, good quality at 8–16 kHz phone-band output, and the ability to chunk text and speak partial sentences without distortion.
ElevenLabs and Cartesia currently lead for conversational quality; Azure and Google remain the safest enterprise choices; Polly Neural is the best value for large fleets on AWS.
Media bridge — where ASR meets SIP
The media bridge forks audio from the SIP call to the AI pipeline and re-injects translated audio. Production choices in 2026: FreeSWITCH with mod_audio_fork, Asterisk with ARI and External Media, Kamailio as SIP proxy in front of a media server, Janus Gateway for WebRTC bridging, and LiveKit Agents for modern AI-first builds. Our LiveKit AI agent practice and custom WebRTC architecture teams use this layer daily.
Chained pipeline or one model?
Chain the three stages yourself when you need control of the middle; buy a managed speech-to-speech model when you need translated calls working this quarter. That second option stopped being a research demo in 2026. OpenAI’s gpt-realtime-translate takes speech in 70+ input languages and returns translated speech in 13 output languages, at $0.034 per minute of audio (OpenAI, 2026). Read that as per session, not per call: a two-way bilingual call runs two sessions. The model now runs over WebRTC for browser legs as well as WebSocket for server-side media, and OpenAI’s sizing rule for group rooms is one session per active speaker track per distinct target language (OpenAI, 2026).
Since June 2026 there is a second managed option. Google’s Gemini 3.5 Live Translate, in public preview, translates continuously across 70+ languages (78 in the supported list), takes 16 kHz PCM16 in and returns 24 kHz PCM16 out, and keeps the speaker’s intonation and pacing (Gemini API docs, 2026). It lists at $0.0053 a minute for audio in and $0.0315 a minute for audio out, about $0.037 a minute effective (Gemini API pricing, October 2026). Like OpenAI’s model, it takes no glossary or instructions in translation mode, and Google watermarks its output audio with SynthID.
What it does differently: it streams translated audio and transcript deltas while the source audio is still arriving, detects the source language on its own, and adapts the output voice to whoever is speaking instead of reading everything back in one preset voice. There is no text stage in the middle, which is both the reason it is fast and the reason it is hard to steer.
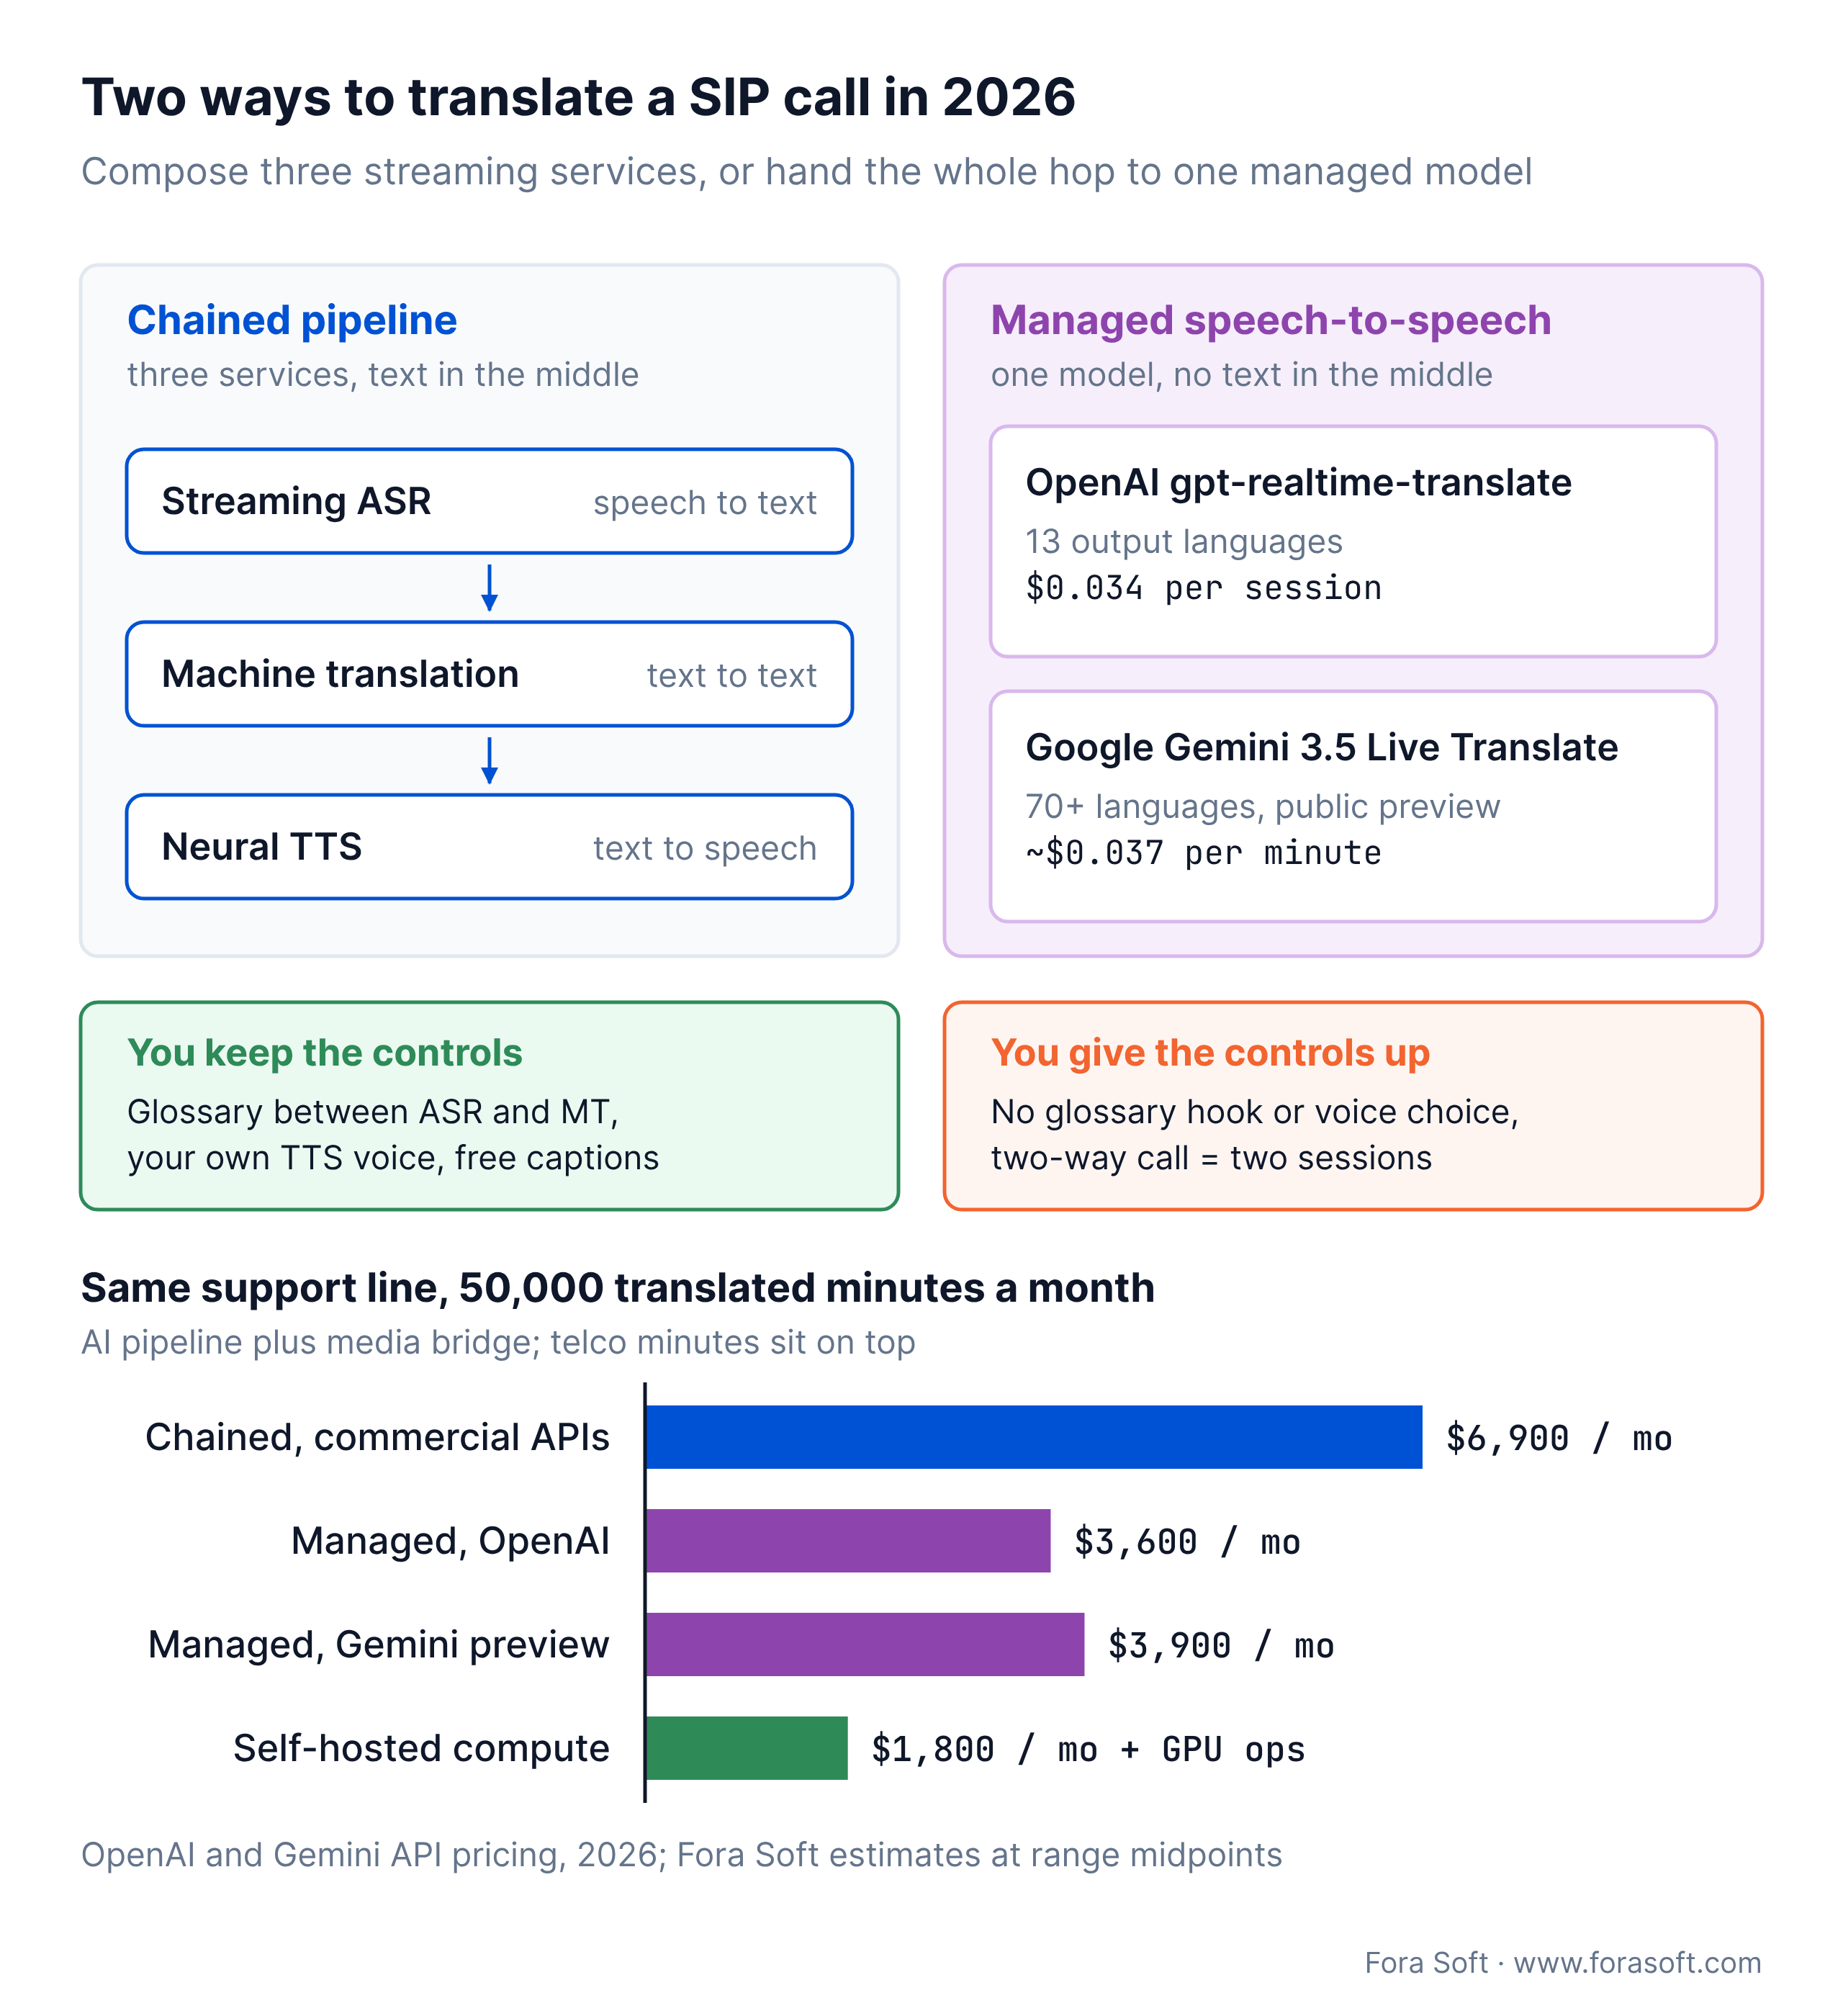
Figure 3. Compose three streaming services or hand the hop to one model — the trade is control for speed and cost.
| What you care about | Chained ASR → MT → TTS | Managed speech-to-speech |
|---|---|---|
| Time to a first working call | Weeks. Three integrations, three sets of credentials. | Days. One session, one endpoint. |
| Terminology control | Yes. Drug names and part numbers get pinned between ASR and MT. | None. With no text in the middle there is nowhere to inject a glossary. |
| Source-language captions | Free — you already produced the text. | A second pass. gpt-realtime-whisper adds $0.017 per minute. |
| Output languages | Whatever your MT and TTS cover, usually 30+. | 13 on OpenAI; 70+ on Gemini (preview). |
| Output voice | You choose it, and it stays the same all call. | Adapts to whoever is speaking; you do not pick it. |
| AI cost per minute | $0.043–$0.185 across the three stages, per stream. | $0.034 (OpenAI) or about $0.037 (Gemini) per session. A two-way call needs two. |
| Debug surface | Three vendors, three queues, three retry policies. | One vendor, one log. |
| Where it breaks | Stalls hide in the handoffs between stages. | No middle to instrument or override. |
The four limits worth checking before you design around the managed model: the output-language list (13 on OpenAI), the missing glossary hook, captions that need a parallel transcription pass, and the fact that it translates rather than reasons. It will not call a tool, hold a persona, or remember anything useful across turns; OpenAI points you at the general realtime model when you want an assistant instead of an interpreter.
Our take: start a new SIP translation build on the managed model and keep the chained pipeline as the escape hatch. For a first release it is not close. You find out in a fortnight whether translated calls change anything for your users, and you have spent a few hundred dollars on a pilot instead of a quarter of engineering. The cost case is thinner than the speed case: once you are at scale, a tuned chained stack or self-hosting beats it. The moment a customer asks you to pin their terminology, or legal asks for a specific voice, or your traffic needs an output language outside the 13, you already know what the chained pipeline has to look like — the rest of this playbook is that build.
One caveat we have to keep saying out loud: we have run the chained pipeline in production for years, and the managed translation models are months old. Their quality on telephony-band audio, in your language pairs, on your accents, is something you measure with your own call recordings before you bet a roadmap on it. We wrote up how that measurement works for video in our guide to real-time translation APIs for live video.
Reach for the managed model when: your output languages are on the managed model’s list (13 for OpenAI, 70+ for Gemini’s preview), nobody is asking you to pin terminology, and the question you actually need answered is whether translated calls are worth building at all.
Reference architecture for SIP translation
The shape below is the one we deploy on most SIP-plus-WebRTC translation projects. It is opinionated but not exotic; any competent team can implement it.

Figure 4. Reference architecture — SIP/PSTN and WebRTC legs meet at the media server; the AI sidecar sits in the same region.
Three design choices in this architecture punch above their weight. First, the AI sidecar is always co-located with the media server to cut 100–400 ms of network latency. Second, speaker diarisation runs on the sidecar, not downstream; mixing translated audio needs to know which speaker the text came from. Third, each participant carries a language preference on join — the media server routes the correct translated mix to each leg, so a 4-way call with three languages produces four tailored audio mixes instead of one confused broadcast.
SIP and PSTN integration specifics
The SIP side of the stack (SIP, RFC 3261) has specific gotchas that do not appear in pure WebRTC demos. Three recurring ones.
Narrow-band codecs and phone-call audio
PSTN and many SIP trunks use G.711 at 8 kHz. ASR quality drops meaningfully on narrow-band audio compared to Opus at 48 kHz fullband. Select an ASR vendor that supports telephony audio explicitly (Deepgram, AssemblyAI, Azure, Google all do) or train acoustic models with telephony samples. Use G.722 or Opus (RFC 6716) where your SIP trunk allows; the transcription gain is real.
DTMF, IVR prompts, and on-hold music
DTMF tones, hold music, and pre-call prompts should not go through translation — they add noise and can trigger false utterances. Detect these on the signalling plane (SIP INFO) or on the media plane (the telephone-event RTP payload defined by RFC 4733, which obsoleted RFC 2833), and suppress translation during non-speech states, and resume when the conversation restarts.
Bridging WebRTC clients and SIP phones
WebRTC participants expect sub-200 ms mouth-to-ear; SIP phones tolerate 300 ms+; PSTN legs often add another 150 ms. Translation adds 1–2 seconds, and that breaks acoustic echo cancellation in two specific ways if you are not careful. The delay exceeds the canceller’s filter tail, so the reference signal no longer lines up with what comes back from the room. And translated audio mixed into the outbound path gets captured by the far-end microphone, fed back into ASR, and translated a second time. The fix for both is to keep translated audio off the original path: a separate WebRTC audio track, or a second SIP channel into a side conference, so the canceller never sees it as room echo and the sidecar never re-ingests it.
Can a SIP trunk talk to the model directly?
Partly, and the detail matters. OpenAI’s Realtime API does terminate SIP: you point the trunk at sip:PROJECT_ID@sip.api.openai.com;transport=tls, a realtime.call.incoming webhook fires, and you accept the call. EU-resident traffic uses sip-eu.api.openai.com (OpenAI, 2026). No REGISTER, no media server.
What you get on the far end of that trunk is a voice agent, not an interpreter. The SIP path creates a standard realtime session on one of the gpt-realtime models. The translation model runs somewhere else: a dedicated translation endpoint that you reach over a WebSocket, feeding it 24 kHz PCM16. It is not selectable on the SIP route.
So the media bridge does not go away. For translated SIP calls your worker still forks the RTP, decodes it, resamples to 24 kHz, and relays PCM16 up the WebSocket, then injects the returned audio back into the call. That is the same fork-and-reinject architecture described above, with one managed model in the box instead of three chained services. The direct SIP endpoint is worth knowing about for a different product — an AI agent answering the phone — not for this one.
The translation APIs add three phone-specific rules (OpenAI telephony guide, May 2026). Convert 8 kHz G.711 μ-law to 24 kHz PCM16 on the way in and back again on the way out; Gemini wants 16 kHz in, in 100 ms chunks. Stream continuously, silence included, because translation is not turn-based and a gated stream stalls it. And pass the original audio through when both callers share a language, because the model goes quiet on same-language speech instead of echoing it. Gemini’s Live Translate has no SIP route of its own either; Google points developers at Agora, LiveKit and Pipecat for the media layer.
Both routes are new enough to show it. OpenAI’s own developer forum carries open threads on greeting delay, legs that drop with an immediate BYE, and RTP gated to particular carriers. Keep your own media path as the fallback before you put either in front of customers, not after.
Adding a human interpreter leg over SIP
For calls that need a certified human (next sections), the SIP side is the easy part. Over-the-phone interpreting providers are reached through a dial-in number, and some offer direct SIP connectivity under contract, so the media server adds the interpreter as a third conference leg, or hands the call over with SIP REFER (RFC 3515), and the AI pipeline drops to captions for that call. Capture the language and the reason for escalation in the IVR or the agent desktop, so the right language queue is dialled and the synthetic voice never talks over the interpreter.
Need senior engineers who have wired ASR and TTS into SIP before?
We have shipped this pattern across contact centre, telehealth, legal, and education products. 30 minutes and you leave with an architecture and a vendor shortlist.
The vendor stack, compared
The matrix below is the cut we use with clients. Prices are indicative; 2026 deals move weekly in this space.
| Stage | Best quality | Best value | Open-source / self-host | Watch out for |
|---|---|---|---|---|
| Streaming ASR | Deepgram, AssemblyAI, Speechmatics | Azure, Google, Amazon Transcribe | Whisper (MIT), NVIDIA Parakeet / Canary v2 (CC-BY-4.0) | Telephony audio quality varies a lot |
| MT | DeepL, Frontier LLMs (GPT, Claude, Gemini) | Google Translate, Azure, Amazon | M2M-100 (MIT), MADLAD-400 (Apache-2.0). NLLB-200 is CC-BY-NC — not for commercial use. | LLM latency at scale |
| TTS | ElevenLabs, Cartesia, OpenAI | Amazon Polly Neural, Azure Neural | Piper (MIT), Kokoro (Apache-2.0). XTTS v2 is non-commercial. | First-audio latency at cold start |
| Managed speech-to-speech | OpenAI gpt-realtime-translate; Google Gemini 3.5 Live Translate (preview) | $0.034/min (OpenAI); about $0.037/min (Gemini) | Meta’s open streaming S2S — research licence only | No glossary hook; OpenAI outputs 13 languages; Gemini is still preview |
| Media server | LiveKit Cloud, Vonage Video, Daily | FreeSWITCH, Asterisk, Janus | FreeSWITCH, Asterisk, Janus, mediasoup | SIP interop + NAT traversal tuning |
| SIP proxy | Kamailio, OpenSIPS | Kamailio, Drachtio | Kamailio, OpenSIPS | Routing complexity scales with trunks |
Reach for a self-hosted stack when: you clear about 100,000 translated minutes a month, you have the engineering to run Whisper, an open MT model, and a local TTS, and data-residency rules put some managed vendors out of bounds.
Mini case — how we wire this in production
A concrete pattern from our portfolio. On ProVideoMeeting we ship enterprise video conferencing with SIP/PSTN dial-in and digital signatures for compliance-heavy tenants — exactly the plumbing a translation overlay plugs into. On BrainCert we run WebRTC classrooms across dozens of countries, which means multi-language participants are a daily reality and language handling is core UX. On Speakk and The Language Chef we have shipped language-learning products where ASR accuracy, TTS quality, and conversational flow were the product.
Across these builds the repeated pattern is the one we already described: a Kamailio / FreeSWITCH or LiveKit media tier, AI sidecars in the same region, streaming ASR into streaming MT into streaming TTS, and per-participant language routing at the mix stage. Where tenants have regulatory constraints (healthcare, finance, education) we pair the AI pipeline with human-in-the-loop review for high-stakes moments and a certified interpreter fallback path.
On CirrusMED we apply the same WebRTC primitives under HIPAA, which is a template we reuse for medical SIP translation deployments.
When to keep a human interpreter in the loop
AI translation is excellent for most business communication and genuinely productivity-changing for cross-border teams. It is not a full replacement for a qualified human interpreter in regulated, high-stakes settings. Three cases where human-in-the-loop matters.
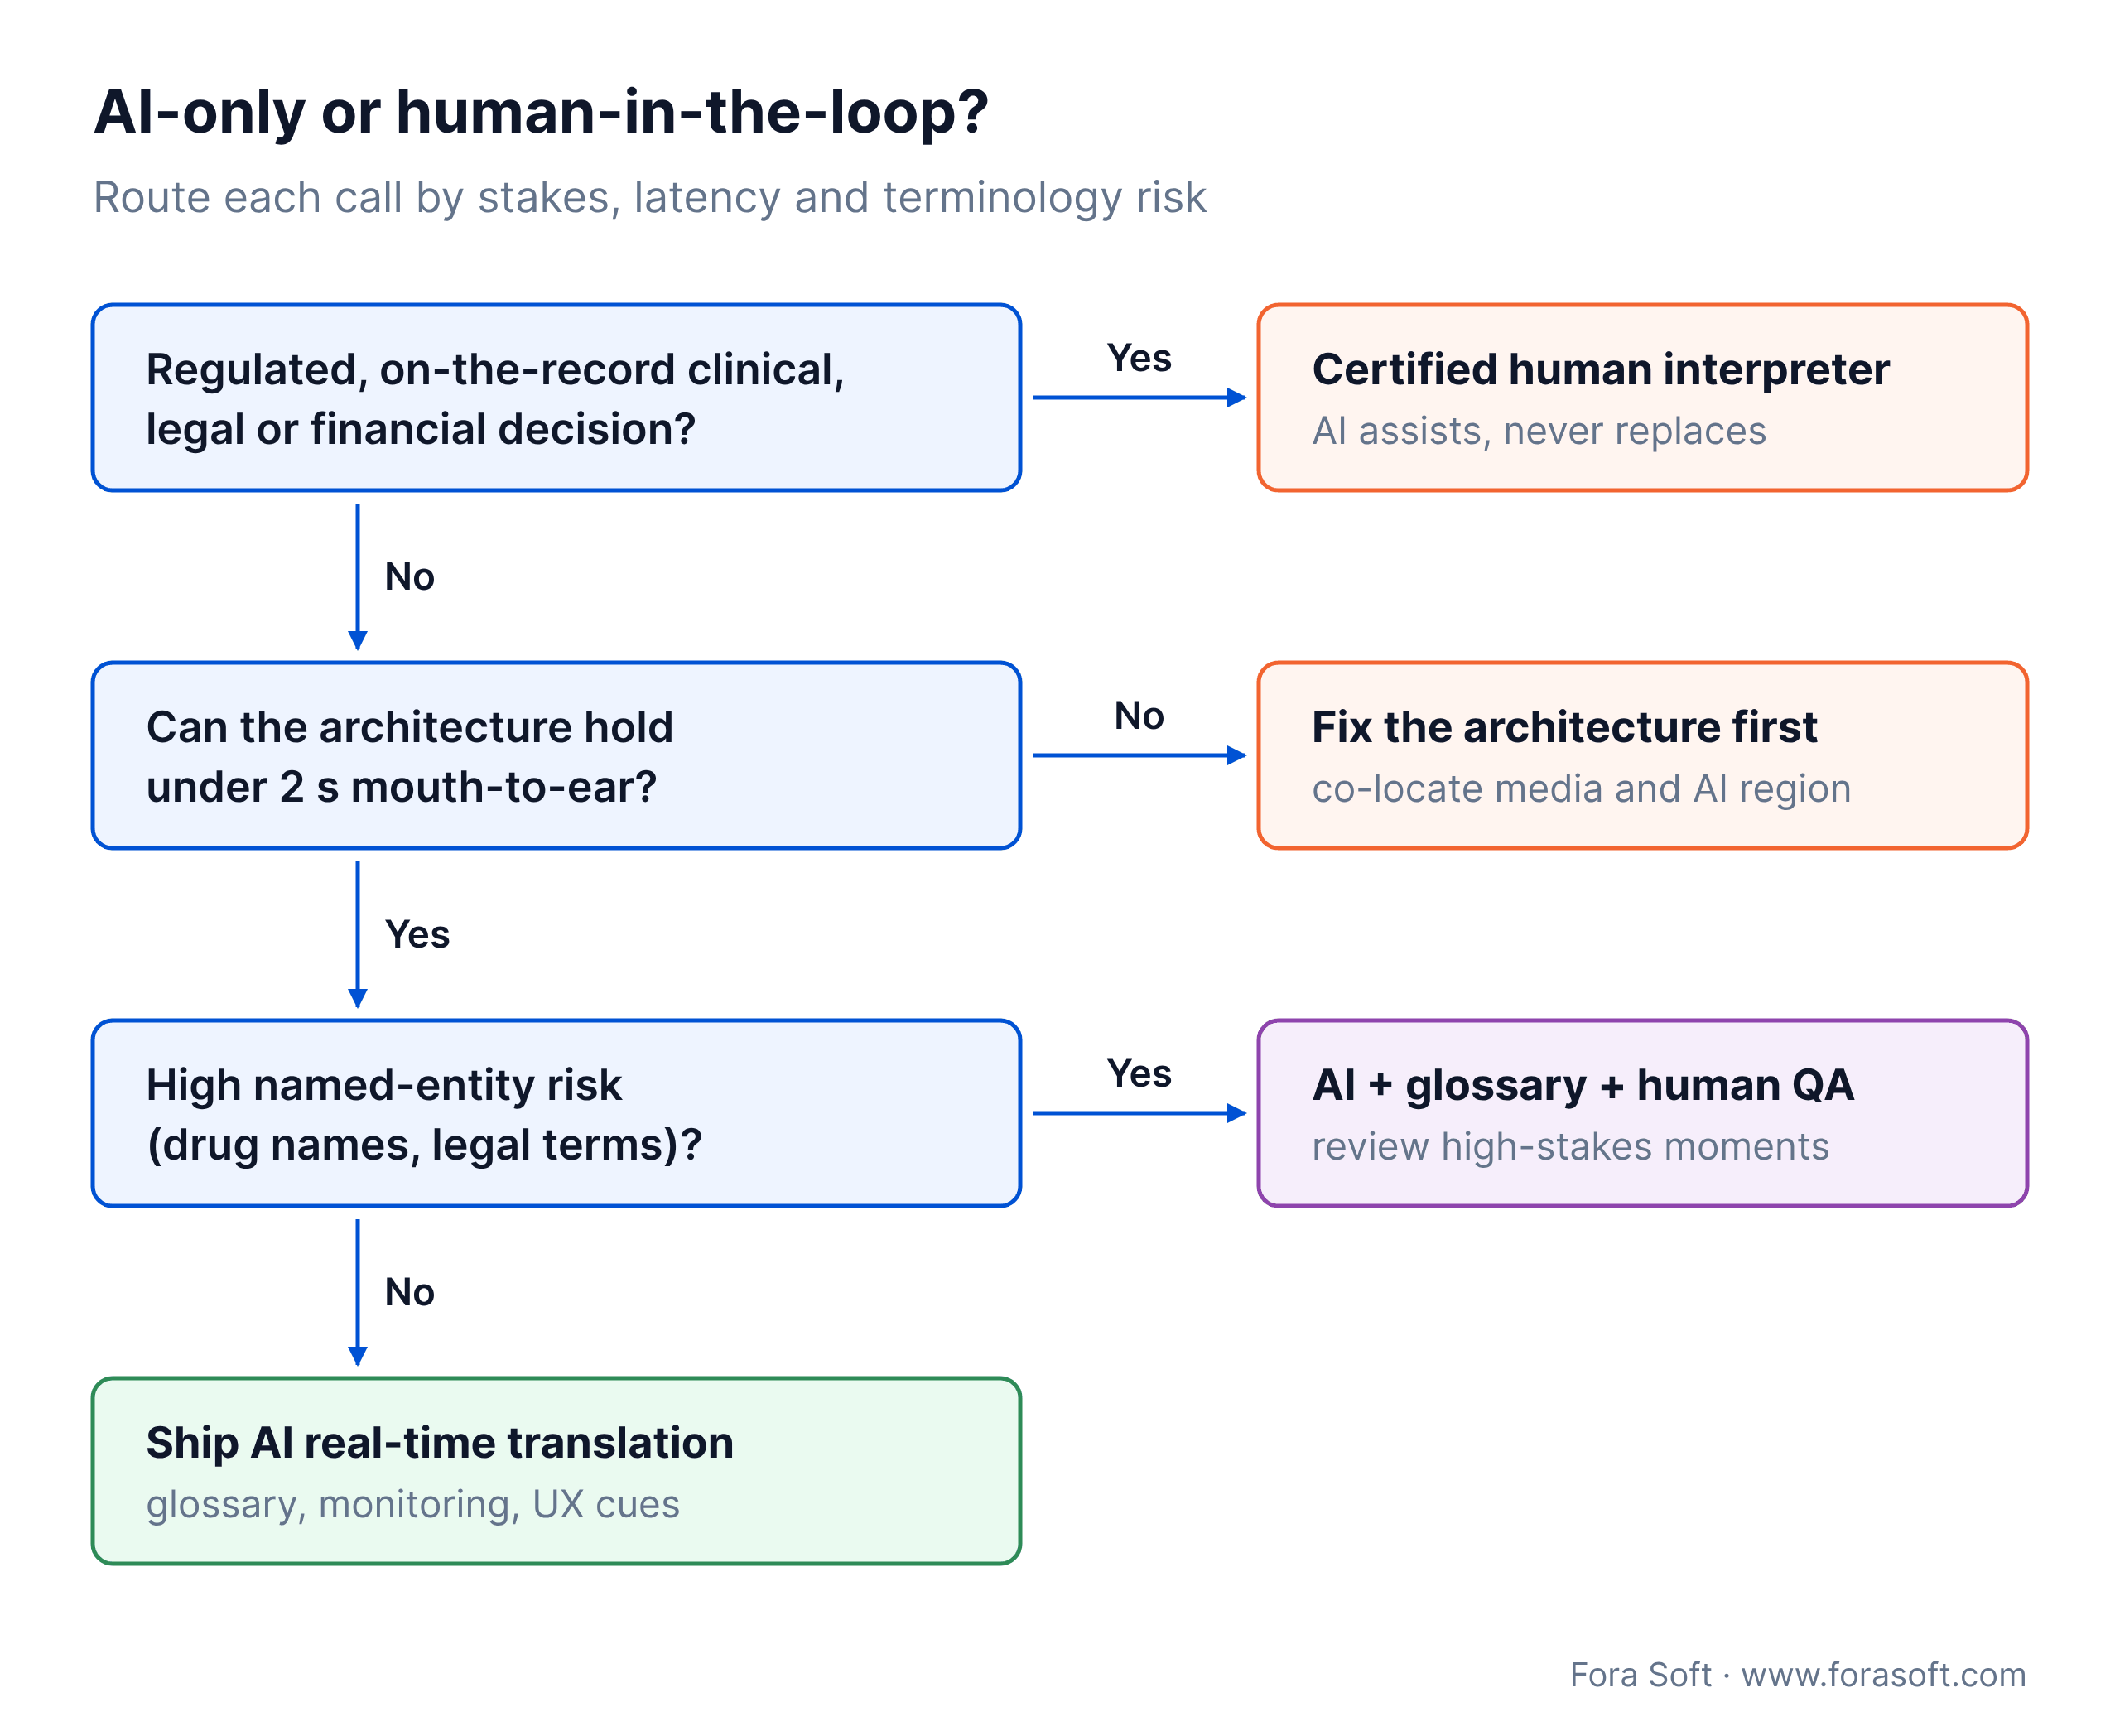
Figure 5. Route each call by stakes, latency, and terminology risk before choosing AI-only or human-in-the-loop.
1. Healthcare consults and clinical decisions. A mistranslated medication dose or symptom description can harm patients. US hospitals are subject to Title VI obligations for language access and often require certified medical interpreters (CCHI or NBCMI credentials). AI can assist; it should not replace.
2. Legal proceedings and depositions. Court rules in most US jurisdictions, in the EU, and elsewhere require certified court interpreters. AI translation might be useful for pre-hearing preparation or non-of-record conversations but not for on-the-record speech.
3. Financial sales and regulated advice. FINRA, MiFID II, and local regulators require accurate records of client communication. AI translation in the call loop creates new audit and liability surfaces that need explicit design and legal sign-off.
Keep a human interpreter when: the words carry clinical, legal, or financial consequence, or a regulator requires a certified interpreter on the record — AI assists there, it does not replace.
Quality, accuracy, and bias considerations
Three practical realities any production SIP translation system has to face.
1. Language coverage is uneven. English-Spanish, English-French, English-German, Mandarin-English work excellently. Low-resource languages — Khmer, Amharic, many African and Pacific languages — still have meaningful quality gaps in both ASR and MT. Know which language pairs your product promises and test aggressively against real-world audio.
2. Proper nouns, brands, and jargon. Product names, medical terms, legal terms, and code-switched slang all trip up general-purpose models. Maintain a custom glossary, use pronunciation lexicons for TTS, and consider fine-tuning where jargon dominates.
3. Bias and tone. Translation systems can mis-gender, over-formalise, or drop politeness markers in ways that feel abrupt. Log a sample of translations for manual review, especially in customer-facing use cases, and iterate. Present a confidence indicator to end users where it matters (for example, an on-screen prompt: “translation confidence 85 percent”).
Compliance, privacy, and data residency
A SIP translation system touches voice, text, and often personal data. Plan for the envelope up front.
1. GDPR and data residency. Audio and transcripts of EU participants are personal data; processing them in a US-only region raises Schrems II concerns. Use EU-region ASR/MT/TTS endpoints where available and document the transfer.
2. HIPAA for healthcare. Every sub-processor in the AI pipeline needs a Business Associate Agreement. Not every vendor signs one at every tier: ElevenLabs and Cartesia now offer HIPAA BAAs on enterprise plans with zero-retention modes, but that coverage is gated to those tiers, so confirm BAA scope and data-retention terms per sub-processor before routing PHI through them. Our secure video communication for facilities playbook goes deeper on the control set.
3. Recording and retention. Many jurisdictions require both-party consent to record calls. Translated audio is still a recording. Document retention policies per content type and align with local law.
4. EU AI Act. The Digital Omnibus entered into force on 27 July 2026 and reset the dates that matter here (Lewis Silkin, July 2026). The Article 50 duty to tell people they are dealing with an AI system applies from 2 August 2026, so a synthetic interpreter voice should announce itself at the start of the call. Marking of synthetic audio has a grace period to 2 December 2026 for systems placed on the market before 2 August 2026. Stand-alone high-risk obligations under Annex III moved to 2 December 2027. Real-time translation itself is typically not high-risk, but speaker identification and emotion recognition features can be, so get a legal review when you combine them.
Cost model — what a minute of translated conferencing actually costs
The cost of the AI pipeline is per-minute, and the biggest variable is which vendor you pick for each stage. The rows below price one translated audio stream for a minute, at 2026 production prices — that is how every vendor in the chain bills.
| Line item | Per minute, commercial | Per minute, self-hosted | Notes |
|---|---|---|---|
| Streaming ASR | $0.008–$0.025 | $0.003–$0.008 | Deepgram and Google in the low range |
| Machine translation | $0.005–$0.040 | $0.002–$0.010 | LLM-based pipelines sit at the top |
| Neural TTS | $0.030–$0.120 | $0.008–$0.025 | ElevenLabs premium at the top |
| Media server + egress | $0.004–$0.010 | $0.001–$0.003 | LiveKit Cloud vs self-hosted |
| Managed speech-to-speech (replaces the three rows above) |
$0.034 per session; a two-way call needs two |
n/a | Billed per translation session, one per direction |
| Subtotal per minute | $0.05–$0.20 | $0.014–$0.046 | Roughly 3–5× cheaper self-hosted |

Figure 6. What a translated minute costs in 2026 — neural TTS dominates the commercial bill; self-hosting pays back at scale.
For a small deployment, commercial APIs are almost always the right choice; the engineering cost to run Whisper, Piper, and a commercially licensed MT model well outweighs the cost delta. Once you cross roughly 100,000 translated minutes per month, a self-hosted or hybrid pipeline starts to pay back. Agent Engineering is where we compress the build timeline of a self-hosted stack, and we are happy to share before/after numbers on a call.
Now convert per stream into per call, because this is where budgets go wrong. A two-party bilingual call transcribes both legs, so it bills a second ASR stream — another $0.008–$0.025 a minute — while MT and TTS scale with output volume and stay roughly flat. Put numbers on it. Take the midpoints: $0.121 a stream commercial, $0.030 a stream self-hosted, plus one extra ASR stream on each side for the second leg. A support line doing 50,000 translated call-minutes a month runs about 50,000 × $0.138 = $6,900 on commercial APIs, versus 50,000 × $0.036 = $1,800 in raw compute self-hosted. The catch: the self-hosted saving only shows up once you can keep two or three GPUs busy and on-call — below that, the managed bill is cheaper than the ops headcount it would replace.
Run the same 50,000 minutes through the managed model and read the meter carefully, because it counts sessions, not calls. OpenAI’s guidance is one translation session per direction: caller A into B’s language, caller B into A’s. A two-party bilingual call therefore burns two sessions at $0.034, so $0.068 a call-minute. 50,000 × $0.068 = $3,400, plus roughly $0.004 a minute for the media bridge and egress, so about $3,600 a month. That is a little over half the commercial chained stack, not a third — and still twice self-hosting. Add source-language captions and a transcription pass at $0.017 a minute per stream, on both legs, takes it to roughly $5,300, about three-quarters of the chained bill. Add a third language and you add sessions again: one per target language, per speaker. Gemini 3.5 Live Translate lands in the same place: 50,000 × 2 × $0.0368 = $3,680, about $3,900 a month with the bridge, on preview pricing that can still change.
Reach for commercial APIs when: you are below about 100,000 minutes a month, you want one vendor accountable for quality, and you would rather spend engineering time on product than on GPU operations.
A decision framework in six questions
Q1. Which language pairs do I actually need? If the top four pairs cover 90 percent of traffic, ship those first and hard-wire a fallback for the long tail.
Q2. What is my latency budget? Under 2 seconds mouth-to-ear is the usability floor. If your current architecture cannot hit 2 seconds, no vendor choice fixes that — architecture does.
Q3. What is the stakes profile of the calls? Business meetings vs medical consults vs depositions vs customer support. Higher stakes require human-in-the-loop, stricter logging, and vendor BAAs.
Q4. Do I care about voice quality, or is readability enough? Subtitles plus TTS is one product; subtitles alone is another. The TTS tier dramatically affects cost and user perception — pick deliberately.
Q5. Which region(s) must the data stay in? GDPR, HIPAA, in-country data residency each constrain vendor choice. Design the vendor shortlist against the compliance envelope, not the other way round.
Q6. Do I need control of the middle? If the answer is no — no glossary, no fixed voice, output languages on the managed list — ship on a managed speech-to-speech model and revisit in a quarter. If the answer is yes, build the chained pipeline now rather than migrating off a managed model under deadline.
Five pitfalls that quietly kill translated calls
1. Shipping end-of-utterance ASR. Batch ASR that emits one block of text after the speaker stops is incompatible with live conversation. Streaming ASR with partial hypotheses is mandatory; anything else feels broken.
2. Cross-continent pipelines. A US-West participant, a London media server, and a Frankfurt ASR endpoint adds 100–400 ms of pure transit to the 1,450 ms pipeline, which is the difference between hitting your p50 and breaching your p95. Co-locate aggressively.
3. No glossary management. A legal-tech product that mistranslates “parol evidence” or a healthcare product that mangles drug names loses trust in a single demo. Ship a glossary subsystem from day one.
4. Overlapping speakers and missing diarisation. When two people speak at once, a naïve pipeline emits jumbled translation. Speaker diarisation and utterance segmentation per speaker matter, especially for 3+ participant calls.
5. Treating translation as a switch rather than a UX. Users need on-screen cues — who is speaking, what language, confidence level, option to toggle original voice. Without that UX, translation feels magical in the demo and confusing in practice.
KPIs — what to measure
Quality KPIs. ASR word-error rate on your actual telephony audio (target under 10% for top pairs; under 15% for tier-two). BLEU / COMET scores on a curated test set per language pair; update every quarter. Mean opinion score (MOS) on TTS samples above 4.0.
Latency KPIs. p50 mouth-to-ear under 1.5 seconds; p95 under 2.5 seconds; p99 under 4 seconds. Track per vendor, per region, per language pair.
Business KPIs. Conversion uplift from offering translated service vs non-translated baseline; cost per translated minute; customer satisfaction on translated versus untranslated calls; interpreter labour reduction where applicable.
When NOT to build this yet
Not every product needs SIP translation built in. If your cross-language traffic is below a few percent, an “invite the interpreter as a participant” workflow may be enough. If your regulatory envelope requires certified human interpreters end-to-end, an AI pipeline becomes decoration, not a replacement. If your team cannot afford to maintain a multi-vendor pipeline (quality tuning, glossary, compliance reviews), you will ship a demo and regret the ongoing burn.
Build it when cross-language interactions are a recurring product moment, translation shortens call setup, or translation is itself the product (a translation-as-a-service offering, a UC vendor, a contact-centre platform). In those cases the playbook above scopes the build.
Building a translated conferencing product?
Fora Soft pairs senior WebRTC, SIP, and AI-audio engineers with your team or builds the product end-to-end. Agent-Engineering-accelerated delivery compresses the build timeline meaningfully.
FAQ
What is the minimum latency a human actually notices in a translated call?
ITU-T G.114 puts 0–150 ms of one-way delay in the transparent band and calls anything past 400 ms unacceptable for ordinary telephony. Translated calls live outside that: people accept 500–800 ms once they know a machine is interpreting; 1–2 seconds is usable but feels like a conference-call delay; above 3 seconds, both sides start talking over each other and the feature stops feeling conversational. Aim for a p50 of 1.5 seconds and a p95 of 2.5 seconds in production.
Is Whisper a good fit for streaming ASR?
Whisper is an excellent batch ASR and a strong baseline for many languages. It is not natively a streaming ASR; turning it into one requires careful chunking, endpointing, and latency tuning. For production SIP translation, a purpose-built streaming ASR (Deepgram, AssemblyAI, Azure, Google) usually delivers better latency with less engineering. Whisper is the right choice if you are self-hosting for cost or compliance and can invest the engineering.
Is LLM-based translation a practical production choice?
Increasingly yes, for quality, especially with conversational context. LLMs (the current GPT, Claude and Gemini tiers, or open-weight fine-tunes) handle politeness, humour, code-switching, and context carry-over better than older NMT systems. The trade-off is latency and cost per minute. The pattern that works is a short-context streaming call with a cached conversation state — not a fresh LLM call per utterance.
How do I bridge a PSTN phone caller into translated conferencing?
Use a SIP trunk into a Kamailio proxy, terminate on a FreeSWITCH or Asterisk media server, fork the caller’s audio to the AI sidecar, and inject translated audio on a separate channel. Watch the narrow-band codec (G.711) and select ASR models trained on telephony audio. See the SIP integration for video conference platforms playbook for the broader plumbing.
Do I need speaker diarisation?
For 1:1 calls, no — each leg is its own speaker. For 3+ participant calls, yes — diarisation tells you which speaker each utterance belongs to, which matters for routing translated audio, per-speaker language detection, and readable transcripts. Most streaming ASR vendors offer built-in diarisation; otherwise a separate diarisation model (pyannote, NeMo) runs alongside.
Is AI translation enough for healthcare or legal calls?
No, not alone. US regulations (Title VI for healthcare, court rules for legal proceedings) typically require certified human interpreters for decisions and on-the-record speech. AI translation is a legitimate productivity aid for non-decisional conversation, intake, patient education, and pre-hearing preparation — but any high-stakes interaction should route through a qualified interpreter with AI assisting, not replacing.
How do I handle domain-specific terminology?
Three levers. First, a custom glossary that the MT and TTS layers consult for preferred translations and pronunciations. Second, a custom vocabulary / language model adaptation on the ASR side for jargon and brand names. Third, fine-tuning on in-domain data when volume justifies it. Glossary work is high ROI and usually the first thing we ship after the baseline pipeline.
Roughly how long does an MVP take?
A single language pair demo in WebRTC, with a managed ASR/MT/TTS stack, takes a seasoned team 2–4 weeks. A production-ready multi-language deployment with SIP/PSTN bridging, speaker routing, compliance review, and monitoring typically lands in 8–16 weeks. Agent-Engineering-accelerated delivery usually compresses that window meaningfully; we are happy to share specific benchmarks under NDA.
Managed speech-to-speech model, or build ASR, MT and TTS yourself?
Use the managed model when you need translated calls in production quickly, your output languages are on its list (13 on OpenAI, 70+ on Gemini’s preview), and nobody is asking you to pin terminology. Build the chained pipeline when you need glossary control, a specific synthetic voice, source-language captions, or output languages the managed model does not cover. At 50,000 call-minutes a month a two-way call runs two translation sessions, so the managed path costs about $3,600 against roughly $6,900 for a commercial chained stack, on 2026 list prices.
Can I point a SIP trunk directly at an AI model?
You can point a trunk at OpenAI’s SIP endpoint and have a webhook accept the call, but that route creates a standard realtime session on a gpt-realtime model — a voice agent, not a translator. The translation model lives on a separate WebSocket endpoint that takes 24 kHz PCM16, so translated SIP calls still need your own media worker to fork, resample and relay the audio.
What is SIP translation?
SIP translation is real-time speech translation inside a SIP or PSTN call: the caller’s audio is forked to speech recognition, machine translation and speech synthesis (or one speech-to-speech model), and the translated voice is played back into the call about 1–2 seconds behind the speaker. In carrier engineering the same words can mean number or header rewriting on a session border controller, which is a different job.
What types of solutions support speech-to-speech translation with live telephony?
Three types in 2026: a managed speech-to-speech model such as OpenAI gpt-realtime-translate ($0.034 a minute) or Google Gemini 3.5 Live Translate (preview, about $0.037 a minute) behind your own media bridge; a chained streaming ASR, MT and TTS pipeline on FreeSWITCH, Asterisk or LiveKit; and a human over-the-phone interpreter added as a conference leg. Neither managed model takes a SIP trunk for translation directly, so all three need a media server that forks and re-injects the audio.
Gemini 3.5 Live Translate or gpt-realtime-translate for phone calls?
Pick OpenAI’s model when your output languages are among its 13 and you want a non-preview API with documented telephony guidance; pick Gemini 3.5 Live Translate when you need more of its 70+ languages and can live with preview status. Both cost roughly $0.034–$0.037 per session-minute, neither accepts a glossary in translation mode, and both need 8 kHz phone audio resampled before it goes in. Test both on your own call recordings before you commit.
Can an over-the-phone interpreting service plug into my IVR?
Yes. Route the IVR’s language choice to a dial-out or SIP transfer to the interpreting provider’s language queue, add the interpreter as a third leg so the agent stays on the call, and switch the AI voice off for that call. Log the language and escalation reason so you can see which calls AI handles and which still need a human.
What to read next
SIP
SIP Integration for Video Conference Platforms
The SIP plumbing playbook that sits underneath translation integration.
Services
Real-Time Speech Translation for Live Video
Our service page for production-grade real-time translation builds.
Security
Secure Video Communication for Facilities
The compliance envelope for regulated video, including BAAs.
AI
Multimodal Agentic AI in Real-Time Systems
Where agentic AI fits in the same pipeline as translation.
Benchmarks
Real-Time Speech Translation Vendor Benchmarks
Latency and accuracy numbers behind the vendor picks in this playbook.
Ready to ship translated conferencing?
SIP translation integration is a four-stage streaming pipeline (capture, ASR, MT, TTS) bolted onto a SIP or WebRTC media bridge with careful per-participant language routing. Everything else is supporting detail: co-located regions to win the latency budget, streaming ASR with partial hypotheses, MT that tolerates interim text, neural TTS with phone-band output, speaker diarisation, glossary management, and compliance gating where the calls demand it.
Apply this playbook and three outcomes follow. End-to-end latency stays inside the conversational window, so the feature actually feels live. Quality holds up on real telephony audio, not just demo recordings. And your product offers a genuinely new experience to international teams and cross-border customers, on top of the SIP infrastructure you already operate.
The book · Volume 7 of 7
AI for Video: A Complete Guide to Intelligence in Video Products: From Real-Time Pipelines and Agents to Serving, Cost, Compliance, and Verticals
A translated SIP call has to fit ASR, translation and TTS inside the pause of a normal conversation. Volume 7 of our handbook covers that real-time budget: where AI slots into a WebRTC pipeline, live captions and translation, serving on vLLM and Triton, and cost per stream-hour. It is the volume our engineers open when a translated call has to stay conversational. Written by Nikolay Sapunov, CEO at Fora Soft.
Read it on Amazon →Kindle & paperback · Fora Soft Video Engineering Handbook
Want this in production, not just in your demo?
Fora Soft builds SIP, WebRTC, and AI-audio pipelines for contact centres, telehealth, legal tech, education, and UC products. 30 minutes and you leave with an architecture and a plan.

