

Key takeaways
• Buy for most, build for a few. Simultaneous interpretation software is a purchase decision under roughly 500–1,000 hours a year and a build decision above it, or when the product needs custom voices, glossaries, or EU data residency.
• The cascade still wins in 2026. ASR → MT → TTS runs 85–90% of production interpretation; direct speech-to-speech (OpenAI GPT-Realtime-Translate, Google Gemini 3.5 Live Translate, Meta Seamless) is catching up where prosody matters, and Zoom, Teams and Google Meet now ship voice translation inside the meeting.
• Latency: sub-1s captions, sub-2s voice. A tuned cascade hits ~0.8–2.0s glass-to-glass, now inside a human interpreter’s 2–4s ear-voice span.
• AI costs 2–16× less on SaaS and 70–200× less in raw API. A full-day, 3-language event runs $5,400–13,200 in human booths, $800–2,500 on AI SaaS, or ~$60–80 in raw API on a DIY cascade.
• Compliance is an architecture decision. GDPR voice data, EU AI Act Article 50 disclosure (applies since 2 August 2026; machine-readable marking for systems already on the market is due by 2 December 2026), HIPAA BAAs, and court exclusions decide your vendor list on day one.
Updated November 2026: Google Meet speech translation in 63 languages, ElevenLabs Realtime Translation, DeepL Aure and the Zoom Interpreter API added; Teams Interpreter now 10 languages, with Town Halls and Webinars on the December 2026 roadmap.
Why Fora Soft wrote this playbook
We’ve built real-time video products since 2005: 250+ projects, most of which touch live communication somewhere (video conferencing, broadcast, tele-education, telemedicine, hybrid events). Over the past three years we’ve added live translation to a growing share of them. Captions in 30 languages for a global webinar series. Voice dubbing for a HIPAA-scoped cross-border telehealth app. Real-time interpretation for a corporate town hall that used to hire six interpreters and now hires none.
This is the working document we use to scope those projects. It covers what “AI simultaneous interpretation” means in 2026, what the pipeline looks like, which vendors and models are worth using, where the milliseconds and the dollars go, and when not to use AI at all. If you’re weighing Zoom AI Companion against a custom build, choosing between Wordly, KUDO, and Interprefy (our comparison of real-time meeting translation platforms covers that buy decision), or trying to understand why your human interpreters cost $13k a day, start here. Two projects ground the advice: TransLinguist and the software we developed for Blaze Streaming Media’s Volo.
For the wider vendor picture, our team also keeps the AI translation companies breakdown and the real-time speech translation architecture guide current. If you want us in the room, that’s our language interpretation engineering team.
A note on cost and speed: Agent Engineering and modern tooling have compressed our timelines by roughly a quarter to a third in 18 months. A 16-week integration is now 10–14. We still do the hard parts (pipeline tuning, glossary work, compliance); we just ship them faster and price them lower than we could two years ago.
What “AI simultaneous interpretation” actually means in 2026
AI simultaneous interpretation is live speech translation done by software instead of a booth interpreter: the system listens to the speaker, recognizes the speech, translates it and delivers captions or synthetic speech in another language about 1–3 seconds behind the speaker. Most 2026 systems chain speech recognition, machine translation and text-to-speech (the cascade); a newer class of speech-to-speech models, such as OpenAI GPT-Realtime-Translate and Google Gemini 3.5 Live Translate, does it in one model.
Remote simultaneous interpretation (RSI) software is the delivery layer around it: the platform that carries speaker audio and per-language channels to remote listeners, whether a human or an AI does the interpreting. For the shorter definition of AI interpretation and the engines you can embed, see what AI interpretation is and which engines to use.
The term gets used loosely, and the buying decisions differ by mode, so precision helps. People usually mean one of five things.
Translated captions (live captions): speaker audio → source transcript → translated text overlay. Under 1 second is achievable. Zoom, Teams, Google Meet, and Webex all ship this. There is no voice replacement, the cost is low, and it dominates enterprise use.
Simultaneous interpretation (voice-to-voice): speaker audio → translated audio in another language, delivered live. This is what a human interpreter in a booth does. A tuned AI cascade now runs it about 1–2 seconds behind the speaker, closer to 3 seconds at P95 on home networks. Wordly, KUDO AI, Interprefy’s AI mode, and purpose-built deployments do this.
Consecutive interpretation: the speaker pauses, the interpreter translates, the speaker resumes. Common for small meetings, depositions, and medical consultations. It’s less latency-critical, so AI handles it comfortably; there’s no race against a live speaker. If you’re searching “consecutive vs simultaneous interpretation,” the split is whether the translation overlaps the speaker (simultaneous) or follows them (consecutive).
Whisper interpretation (chuchotage): a quiet translation to one or two listeners. On mobile this is Google Meet speech translation (63 languages since October 2026) and Apple’s real-time translation in AirPods, where the listener just holds a phone or wears earbuds.
Pre-recorded dubbing and subtitling: not simultaneous, done in post-production. Out of scope here, though it shares most of the stack with live dubbing.
The market: two curves compounding
AI simultaneous interpretation sits where two growing markets meet. Business Research Insights puts the AI simultaneous interpreting segment at roughly $0.5B in 2023 heading to $2.3B by 2032, about 19% CAGR. Slator’s 2026 Market Report tracks the broader AI-addressable language-solutions market at ~$30.9B in 2025. Interpretation is the fast-growing slice inside a much larger video and language stack.
In 2026 the demand driver that matters most is scope, more than unit-price savings. Human interpretation was rationed: you hired interpreters for the annual kickoff, not the weekly town hall. AI makes interpretation cheap enough to switch on for every meeting with international participants. Usage frequency jumps 10–100×, on top of the discount on the old use.
What changed in AI simultaneous interpretation in 2026?
Three things moved between April and October 2026: speech-to-speech translation became a commercial API from both OpenAI and Google, the big meeting suites shipped voice translation inside the call, and the EU AI Act transparency rules started to apply. Since late October the race has shifted to language breadth and voice quality: Google Meet went from one language pair per meeting to any pair across 63 languages, and ElevenLabs and DeepL shipped live voice-translation models of their own. The table lists the releases that change a buy-or-build decision, each checked against the vendor’s own announcement in November 2026.
| Date | Release | Why it matters |
|---|---|---|
| 29 Apr 2026 | Deepgram Flux Multilingual, GA: conversational ASR in 10 languages with mid-call language switching and end-of-turn decisions under 400 ms | One streaming ASR for a multilingual event instead of a model per language |
| 7 May 2026 | OpenAI GPT-Realtime-2, GPT-Realtime-Translate ($0.034/min) and GPT-Realtime-Whisper ($0.017/min) | Live speech-to-speech translation as a metered API: about $2 per hour per voice channel |
| 9 Jun 2026 | Google Gemini 3.5 Live Translate: speech-to-speech in 70+ languages; public preview in the Gemini Live API, private preview in Google Meet | Meet moves from 5 English pairs toward 2,000+ language pairs; a second commercial S2S option |
| 22 Jul 2026 | Zoom Voice Translator: English, Chinese, Spanish, French and Japanese, keeping the speaker’s voice characteristics; Portuguese, German, Italian and Arabic due later in 2026 | Built-in voice interpretation on Pro, Business and Enterprise plans, via ZoomMate or a Live Translation add-on |
| 2 Aug 2026 | EU AI Act Article 50 applies. The Digital Omnibus (Council approval 29 June 2026) delayed the high-risk rules, not Article 50; systems on the market before 2 August get until 2 December 2026 for machine-readable marking | Disclosure and marking of synthetic interpreted audio are now legal duties in the EU |
| Aug–Sep 2026 | Microsoft Teams Interpreter agent GA in Teams Rooms on Android: 20 interpretation hours per room per month with Teams Rooms Pro | Meeting rooms get interpretation without a Copilot seat per attendee |
| 28 Sep 2026 | ElevenLabs Eleven v4 and v4 Turbo: 90+ languages, v4 Turbo median time to first speech ~150 ms | Wider TTS language coverage; Flash v2.5 (32 languages, ~75 ms) stays the fastest |
| 21 Oct 2026 | ElevenLabs Eleven Realtime Translation: live voice translation in 90+ languages with automatic language detection, on Eleven v4 Turbo; alpha for enterprise customers through the API | A TTS vendor now sells the whole voice-to-voice hop, in a library voice or the speaker’s own clone |
| 22 Oct 2026 | Google Meet speech translation expands to 63 languages on Gemini 3.5 Live Translate: any pair in one meeting, automatic language detection; Scheduled Release domains from 2 November 2026 | Built-in voice interpretation for most Workspace business plans; sessions capped at 90 minutes (8 hours on Ultra tiers) |
| 11 Nov 2026 | DeepL Aure: voice model that carries the speaker’s tone, emotion, emphasis and pace into the translated speech; 8 languages at launch, inside DeepL Voice and the DeepL API for Voice | DeepL moves from text MT into voice; a European option for teams that already buy DeepL |
Our recommendation: the cascade still ships most production systems, but for a top-10 language pair a single speech-to-speech API is now a fair first prototype. In the prototype phase (weeks 3–4 of the playbook below), benchmark GPT-Realtime-Translate or Gemini 3.5 Live Translate against a Deepgram + LLM + ElevenLabs cascade on your own recorded sessions, and keep the cascade wherever glossaries, captions for audit, or EU data residency matter.
The interpretation pipeline: six stages, end to end
Almost every deployment, whether Zoom AI Companion or a custom WebRTC build, runs the same six-stage cascade. The real decisions are about what runs where, and how tightly the stages couple.

Figure 1. The cascade, stage by stage, with the 2026 latency budget for each step.
1. Audio capture. Microphone input from the speaker’s client over WebRTC, SIP, or raw RTP. 16 kHz minimum, 48 kHz preferred for TTS output. Noise suppression (RNNoise, Krisp, or platform-native) runs here.
2. Voice activity detection and turn segmentation. VAD separates speech from silence; turn detection predicts when a thought is finished. Deepgram’s Flux folds both into the ASR and emits end-of-turn events at about 260 ms in English (under 400 ms for Flux Multilingual); Silero VAD and WebRTC VAD stay the open-source defaults. A 300–500 ms silence threshold is typical.
3. Streaming ASR. Speech to text, incrementally. Target under 500 ms from audio in to first token. Deepgram Nova-3, Google Chirp 3, AssemblyAI Universal-Streaming, Azure Speech, and self-hosted Whisper v3 are the 2026 options.
4. Machine translation. Source text to target text. In 2026 the top LLMs (GPT-5, Claude, Gemini 2.5 Pro) have overtaken dedicated engines on COMET for most high-resource pairs. Gemini 2.5 Pro won the WMT25 human evaluation on 14 of 16 language pairs. DeepL and Google Translate still win on raw latency (~50 ms) and predictability. Meta NLLB-200 is the open-source fallback past 100 languages.
5. Text-to-speech. Translated text to audio. ElevenLabs Flash v2.5 (~75 ms first byte, 32 languages) leads on low latency; Google Chirp 3 HD, Amazon Polly Neural, and Azure Neural TTS round out the cloud. For output in the speaker’s own voice, use ElevenLabs voice cloning; Meta SeamlessExpressive does the same but is licensed for research only.
6. Delivery. Caption overlay (WebVTT, or EBU-TT-D for broadcast) or audio replacement. WebRTC SFUs (LiveKit, mediasoup, Janus, Amazon Chime SDK) fan out one stream per language; each listener picks their language client-side. This is the layer we most often own end to end on video-conference builds.
Our bias: if you’re building from scratch, run a managed pipeline for 90% of the stack and own only what differentiates you: the glossary, the UX, and the SFU integration. Teams that try to own the whole ASR → MT → TTS chain burn eight months to land something 80% as good as Deepgram + an LLM + ElevenLabs at 10× the engineering cost.
Adding interpretation to a video product?
We’ve wired this pipeline into conferencing, telehealth, and broadcast platforms. Tell us your stack and target languages and we’ll sketch the architecture and a realistic timeline on a 30-minute call.
Cascade vs direct speech-to-speech
The theoretically cleaner approach is end-to-end: audio in, audio out, no text in between. Meta SeamlessM4T v2 (with its streaming variant) does this for ~100 input and ~36 output languages, and Meta released the weights openly, but under a non-commercial CC-BY-NC license, which rules it out of most paid products. OpenAI’s GPT-Realtime models and Google Meet’s speech translation, now moving to Gemini 3.5 Live Translate, are the commercially viable native-S2S options in 2026.
In practice, 85–90% of production deployments still run the cascade. The comparison below shows why.

Figure 2. Seven axes where the two architectures differ, and why the cascade still ships most 2026 systems.
| Dimension | Cascade (ASR → MT → TTS) | Direct S2S |
|---|---|---|
| End-to-end latency | ~800–2000 ms optimized | 300–700 ms potential |
| Modularity / vendor swap | Easy, per stage | Locked to one model |
| Terminology / glossary control | Strong (at the MT step) | Weak |
| Intermediate text for QA, audit, captions | Yes | No (unless you add ASR alongside) |
| Prosody / emotion preservation | Lost in text | Preserved (SeamlessExpressive, Hume) |
| Language-pair flexibility | Any-to-any via MT | Only the model’s pair set |
| Operational maturity (2026) | Production-ready since 2023 | Emerging; greenfield only |
We pick direct S2S where prosody and voice preservation dominate (media dubbing, high-end executive comms, creative work), and only with a commercially licensed model. We pick the cascade for everything else, including nearly every enterprise deployment.
The 2026 model stack: who ships what
The vendor list is long, but the short answer fits in a sentence. Deepgram or AssemblyAI for ASR, an LLM (Claude, GPT-5, Gemini) or DeepL for MT, ElevenLabs or a GPT-Realtime model for TTS, and an OpenAI or Google speech-to-speech model for the cases where direct S2S fits (Meta Seamless is research-licensed). The rest is detail.
Streaming ASR
- Deepgram Nova-3: 45+ languages, diarization, auto language detection, under 300 ms first token, ~$0.0077/min (~$0.46/hr). Its newer Flux model adds model-native end-of-turn detection and went multilingual GA in April 2026. This is our default for mid-to-large events.
- AssemblyAI Universal-Streaming: ~150–300 ms P50, purpose-built for voice agents.
- Google Chirp 3: multilingual streaming ASR, GA across 24+ languages and 100+ in preview, strong on non-English.
- Azure Speech: enterprise-grade, custom models, regional deployment; pairs naturally with Teams.
- Whisper v3 (self-hosted): via faster-whisper or whisper.cpp; free if you own the compute, covers 99 languages; not natively streaming, so it needs chunked decoding.
Machine translation
- Frontier LLMs (Claude, the GPT-5 family, Gemini): now ahead of dedicated MT on COMET for most top-30 pairs, especially with glossary prompting. Latency 200–500 ms. In the 2025 WMT25 human evaluation, Gemini 2.5 Pro ranked first on 14 of 16 pairs.
- DeepL: fastest MT for high-resource pairs (~50 ms), predictable, strong European coverage.
- Google Translate: broadest coverage (240+ languages since the June 2024 expansion), 50–80 ms.
- Meta NLLB-200: 200 languages, open-source, self-hostable; quality falls off outside the top 100.
- Llama, Mistral: open-weight LLMs for self-hosted MT when data cannot leave your infrastructure.
Streaming TTS
- ElevenLabs Flash v2.5: 32 languages, ~75 ms first byte, ~$0.05/1k characters. The lowest-latency multilingual option.
- ElevenLabs Eleven v4 Turbo: released 28 September 2026, 90+ languages, ~150 ms median time to first speech. The pick when you need more output languages than Flash v2.5’s 32.
- OpenAI GPT-Realtime-2 and GPT-Realtime-Translate: native speech-to-speech and live translation (70+ input to 13 output languages at ~$0.034/min), shipped May 2026. Prompt-driven, easy to shape into a custom interpretation agent.
- Google Chirp 3 HD, Amazon Polly Neural, Azure Neural TTS: solid cloud options, good prosody, wide voice catalogs.
- Hume EVI 3: emotional prosody (sighs, emphasis) across 11 languages.
Direct speech-to-speech
- Meta SeamlessM4T v2: ~100 input / ~36 output languages, preserves prosody and speaker voice, open weights. The license is CC-BY-NC (research only), so it can’t go into commercial products as-is.
- OpenAI GPT-Realtime-2 / GPT-Realtime-Translate: commercially licensed native S2S with GPT-5-class reasoning (May 2026); one of two practical choices for a custom real-time interpreter.
- Google Gemini 3.5 Live Translate: announced 9 June 2026, speech-to-speech in 70+ languages; public preview in the Gemini Live API. The second commercially usable native S2S option.
- ElevenLabs Eleven Realtime Translation: live voice translation in 90+ languages on Eleven v4 Turbo, launched 21 October 2026 as an enterprise alpha; keeps a library voice or a cloned voice across languages.
- DeepL Aure: DeepL’s voice model from 11 November 2026 that keeps tone, emotion and pace in translated speech; 8 languages at launch, available through DeepL Voice and the DeepL API for Voice.
- Google Translatotron 3: research preview, limited deployment.
Platforms: what’s actually shipping
Conferencing suites with built-in AI interpretation
Most enterprise buyers don’t need to build. The big four all have real offerings in 2026, but read the voice-translation column carefully, because “translation” usually means captions, not dubbed voice.
| Platform | Caption languages | Voice translation (2026) | Pricing |
|---|---|---|---|
| Zoom AI Companion | 46 via AI Companion | Voice Translator (July 2026): EN, ZH, ES, FR, JA in the speaker’s voice; PT, DE, IT, AR due late 2026 | Pro, Business, Enterprise + ZoomMate or Live Translation add-on (credits) |
| Microsoft Teams | 50+ (Premium) | Interpreter agent, 10 languages (Traditional Chinese added in 2026), own-voice; GA in Teams Rooms Aug–Sep 2026; Town Halls and Webinars on the roadmap for December 2026 | M365 Copilot license; Teams Rooms Pro (20 h per room per month) |
| Google Meet | ~70 live | Speech translation on Gemini 3.5 Live Translate: 63 languages, any pair, automatic language detection (rollout from 22 October 2026); 90-minute cap on standard plans | Bundled in Workspace plans |
| Cisco Webex | 100+ caption | Real-time translated captions; no first-party voice S2S | Paid add-on license |
Two more pieces landed late in 2026. Zoom now sells its interpretation engine outside meetings as the Zoom Interpreter API (preview): speech-to-speech over a WebSocket between 9 languages, with a bilingual transcript, at $2 per hour. Microsoft lists AI interpretation for Teams Town Halls and Webinars on its Microsoft 365 roadmap with a December 2026 target. If you’re already on one of these and the built-in captions cover your languages, you’re done and don’t need to build. A dedicated platform pays off when you need quality, terminology control, voice cloning, large-event reliability, and on-prem or EU-residency compliance.
Dedicated AI interpretation platforms
| Platform | Model | Languages | Best for |
|---|---|---|---|
| Wordly | AI-only | 60+ | Mid-to-large events, AGMs, webinars |
| KUDO | AI + human | 200+ human / 60+ AI | Large conferences, hybrid fallback |
| Interprefy | AI + human (RSI pioneer) | 80+ | Corporate AGMs, investor relations, government |
| Boostlingo | RSI + on-demand | 150+ human | Healthcare, legal, community (VRI/OPI) |
| Verbit | AI + human captioner | 50+ | Broadcast, legal, education |
Latency budget: where the milliseconds go
Human simultaneous interpreters run at a 2–4 second ear-voice span (EVS). That span is the content they need to hear before they can translate meaningfully, and it has little to do with reaction time. Interpreters tolerate about 3 seconds of system latency before quality drops; past 4, delivery breaks. A tuned AI cascade now lands inside that window.

Figure 3. Stage-by-stage P50 latency. ASR and the ASR-to-MT chunk wait dominate the budget.
| Stage | Budget (ms) | Notes |
|---|---|---|
| Audio capture + noise suppression | 20–50 | Platform dependent |
| Network hop to ASR provider | 40–100 | Regional endpoint matters |
| Streaming ASR (P50) | 200–500 | AssemblyAI 150–300 best-in-class |
| ASR-to-MT chunking wait | 200–500 | Wait-k decoding trades accuracy for delay |
| Machine translation | 50–500 | DeepL ~50, LLMs 200–500 |
| Text-to-speech first byte | 75–300 | ElevenLabs Flash 75, Polly ~200 |
| TTS stream + SFU fan-out | 100–300 | Jitter buffer adds 50–150 |
| Client playback buffer | 100–200 | Network-adaptive |
| End-to-end (optimized) | ~800–2000 | Target: under 1s captions, under 2s voice; stages rarely all hit their upper bound (summed worst case ~2.45s) |
Two optimizations matter most. First, co-locate ASR and MT in the same cloud region (Deepgram + an LLM in us-east1); cross-region hops cost 40–150 ms each. Second, start TTS speculatively on the first clause instead of waiting for the full sentence. ElevenLabs Flash takes incremental input, and overlapping TTS with the tail of MT shaves 200–400 ms off perceived delay.
Practical rule: measure end-to-end in production rather than in a benchmark. Your SFU, your users’ home Wi-Fi, your jitter buffer, and client playback all add delay a cloud-to-cloud test never sees. Aim for under 2 s P50 for voice; above 3 s P95, users complain.
AI vs human interpreters: how do they compare?
AI interpreters win on cost, scale and availability. Humans still have the edge on nuance, accountability and legal acceptance. A tuned AI cascade delivers translated voice 0.8–2 seconds behind the speaker at a fraction of the price, while a professional interpreter works at a 2–4 second ear-voice span and remains the only option most courts accept. The numbers below come from the latency and cost sections of this playbook.
| Factor | AI interpretation (2026) | Human interpreters |
|---|---|---|
| Delay behind the speaker | 0.8–2 s (tuned cascade) | 2–4 s ear-voice span |
| Languages per session | 5–70+ per platform, channels run in parallel | One two-person booth team per language |
| Full-day event, 3 languages | $800–2,500 on SaaS; $60–80 in raw API | $5,400–13,200 |
| Endurance | No fatigue, runs around the clock | Rotate every 20–30 minutes |
| Terminology | Depends on the glossary: +5–15 points of accuracy with one | Strong after a preparation briefing |
| Nuance, idiom, humour | Weakest area | Strongest area |
| Legal acceptance | Not accepted in most US and EU courts; EU AI Act Article 50 disclosure | Certified interpreters required for courts, asylum, informed consent |
| Audit trail | Transcript and translation logged by default | Needs separate recording |
Cost model: AI vs human, per hour
This is where the buying case usually closes. Professional simultaneous interpretation needs two interpreters per language. They rotate every 20–30 minutes to keep fatigue errors down (the AIIC “rule of two”). For a full-day event in three languages, that’s six interpreters plus booths and equipment.

Figure 4. The buying case in one chart, plus the DIY per-speaker-hour API math.
| Scenario | Human (2 interpreters/language) | AI SaaS (Wordly / KUDO AI) | DIY cascade (API only) |
|---|---|---|---|
| 1-hour webinar, 1 target language | ~$1,200 (half-day minimum) | ~$150–300 | ~$3 |
| Full-day (8h) all-hands, 3 languages | $5,400–13,200 | $800–2,500 | $60–80 |
| 3-day conference, 6 languages | $35,000–75,000 | $4,000–12,000 | ~$400 |
| 10 h/month, 5 languages (SaaS product) | $15,000+ | $1,500–4,000 | ~$140 |
The DIY numbers assume Deepgram Nova-3 (~$0.46/hr), an LLM for MT (~$0.40/hr at typical speaking rates), and ElevenLabs Flash ($0.05 per 1,000 characters, about $2.25/hr per output language at ~45,000 characters an hour), which comes to about $3.10 per speaker-hour for one language. ASR scales with speaker-hours; MT and TTS scale with speaker-hours × output languages.
What the DIY column hides is the operational cost: engineering, infrastructure, SFU operations, caption UX, glossary management, on-call. In practice, a DIY interpretation layer costs a small team on the order of $180k to build and ~$20k/year to run. That only pays off above roughly 500–1,000 hours a year or when the product needs something SaaS can’t give you: custom voices, proprietary glossaries, EU residency, or broadcast-grade reliability.
Not sure whether to buy or build?
Book a 30-minute call. We’ll walk your usage volume, languages, compliance, and latency needs and tell you honestly whether Zoom plus Wordly beats a custom build for your case.
Budget reality check: SaaS pays back from the first event; a custom build pays back only at volume (in the mini case below, after three to four years at 40+ events a year). What catches teams out is the ops cost of a 24/7 reliable service, not the API bill, so budget SRE and on-call on a DIY build as a fixed $15–25k a year, not as a share of API spend.
Compliance: GDPR, EU AI Act, HIPAA, ADA, broadcast
Interpretation sits on top of voice data, one of the most regulated data categories there is. Most projects hit at least two of these, and each one shapes the architecture instead of being a box to tick.
- GDPR (EU): voice is personal data and voiceprints are Article 9 biometric data. You need a Data Processing Agreement with every ASR/MT/TTS vendor, a lawful basis, explicit consent for voice cloning, a DPIA, EU data residency, and delete tooling.
- EU AI Act Article 50: applies from 2 August 2026. Systems that generate synthetic audio must disclose it: an AI-dubbed voice needs an opening disclosure and machine-readable marking of the output. The Digital Omnibus, approved by the Council on 29 June 2026, delayed the high-risk rules but not Article 50; it only gives providers of systems already on the market before 2 August 2026 until 2 December 2026 to add the technical marking. The Commission’s final Code of Practice on marking and labelling AI-generated content (published 10 June 2026) is the practical reference for how to label it. Fines run up to €15M or 3% of global turnover.
- HIPAA (US healthcare): interpretation transcripts often carry PHI, so any vendor that touches them is a business associate and must sign a BAA, with encryption, retention limits, and audit logging. Most commercial ASR SDKs are not HIPAA-eligible by default.
- ACA Section 1557 (US healthcare): the updated rule requires qualified interpreters and, for the first time in federal policy, that critical machine-translated communications with limited-English-proficiency patients be reviewed by a qualified human. Design a human-review path for high-stakes medical content.
- ADA Title III / Section 508 (US): public meetings and webinars need real-time captions at a 95%+ accuracy target; Section 508 extends this to government systems.
- Court and diplomatic work: AI is not accepted in most US and EU courts. Depositions, immigration hearings, and asylum interviews still require certified humans; AI can help prepare and transcribe, but it can’t replace them.
- BIPA (Illinois): any voiceprint processing on Illinois residents needs written consent and a published retention and destruction schedule. Illinois is an active class-action venue.
A HIPAA, GDPR, or EU AI Act surface to map?
We’ve shipped AI interpretation through each of these regulatory stacks. The architecture is different when compliance is in from day one versus bolted on later. A 30-minute call is usually enough to map your surface and the vendors that fit.
Integration patterns: where AI interpretation plugs in
Most deployments follow one of four patterns. Which one fits depends on how much of the media stack you already own.
Pattern A: SaaS overlay on Zoom / Teams / Meet. Wordly, KUDO, or Interprefy join the meeting as a participant, take the speaker audio, and publish captions or a dubbed channel through the platform’s interpretation slots. There is no integration work: you buy a license and switch it on. This fits 60–70% of enterprise buyers.
Pattern B: conferencing platform on a WebRTC SFU (LiveKit, mediasoup, Janus). You add an interpretation server as an SFU participant. It subscribes to the speaker track, runs the cascade, and publishes one output track per language; the client picks its language via track subscription. It scales cleanly, and it’s how we build most custom video-conference platforms. If your SFU is LiveKit, the interpretation server runs as an agent in the room, and our LiveKit development team builds both the rooms and the agent side.
Pattern C: broadcast / streaming with caption-first delivery. HLS or DASH output with a subtitle track per language (WebVTT or EBU-TT-D). The translation layer produces captions only; voice dubbing happens in post for recorded content. This is the standard setup for live news, sports and public-audience conferences.
Pattern D: mobile whisper apps. Single-user, client-side or API-backed. Apple Translate with AirPods, Google Meet speech translation, and purpose-built apps. The mobile side is covered in our mobile voice playbook; the delivery side in the AI streaming platform guide.
Mini case: an interpretation layer on a hybrid-event platform
An enterprise-events client ran 40+ multi-language webinars a year on a custom LiveKit platform. Before 2026 they booked human interpreters for each event and paid about $60k/year for the service on top of $180k/year for the platform team. AI was clearly cheaper, but they’d tried plain Zoom captions and found the quality too weak for pharma and medical audiences full of terminology.
They were below the usual volume threshold, so the case for building was terminology control and EU data residency rather than hours. We built a cascade layer inside their existing LiveKit cluster:
- ASR: Deepgram Nova-3 with a ~2,500-term medical/pharma keyword boost list.
- MT: an LLM with per-event glossary prompting, DeepL as the latency-critical fallback.
- TTS: ElevenLabs Flash v2.5 across five target languages (Spanish, French, German, Japanese, Portuguese).
- Captions: LiveKit data channels, WebVTT rendered client-side.
- Compliance: EU data residency end to end, GDPR DPAs, and an EU AI Act Article 50 disclosure at event start.
After three months: P50 latency 1.4 s, P95 2.3 s. Caption accuracy against human transcription ran ~96% on the source and ~92% on translation targets. Cost per event dropped from ~$1,500 (human interpreters) to ~$80 (AI). The pharma customer accepted AI-only captions after a 30-day pilot and kept humans on standby only for their highest-stakes regulatory briefings. Year-one savings landed near $55k; integration cost $140k one-time plus ~$18k/year to run. Want a similar assessment for your platform?
The glossary drives quality. A domain-tuned glossary (drug names, SKUs, acronyms, legal terms) moves translation accuracy 5–15 points on average, and more at the tails. Every vendor supports it: Deepgram keyword boost, DeepL glossaries, LLM system-prompt glossaries, Wordly custom term lists. Without one, the pilot will underperform.
Quality metrics: what to measure
Don’t trust vendor marketing numbers. Measure in production; for measured latency and accuracy across engines, see our real-time speech translation vendor benchmarks. The metrics below predict whether users can follow along.
- WER (word error rate): ASR quality. Under 5% is excellent on English; 5–15% is workable on other top-30 languages; over 20% means the wrong model or bad audio. Expect WER to roughly double on noisy or heavily accented input.
- COMET / MQM: MT quality. COMET is the modern neural metric and tracks human judgment better than BLEU; aim for COMET above 0.80 on high-resource pairs, with human sampling for the rest.
- MOS (mean opinion score): TTS naturalness. ElevenLabs Flash and Hume EVI 3 both score above 4.1 in user studies; target above 4.0.
- End-to-end latency: P50 and P95. Captions under 1 s / 1.5 s; voice dubbing under 2 s / 3 s.
- Terminology hit rate: the share of domain terms the translation gets right. Glossary-dependent; aim above 95%.
- User satisfaction: a post-event survey on “I could follow the content in my language.” Target above 4.0 of 5.
Accents, dialects, and low-resource languages
AI interpretation holds up well on high-resource languages and drops sharply on low-resource ones. Plan around the tiers.
Top 30 (English, Mandarin, Spanish, French, Arabic, Hindi, Japanese, Korean, Portuguese, German, Italian, and the like): excellent ASR and MT across all vendors, with WER under 10% and MOS above 4.0. You can ship AI interpretation and be understood.
Ranks 30–100 (Swahili, Tamil, Telugu, Ukrainian, Urdu, Farsi, and ~60 others): workable but error-prone. BLEU 30–40, WER 15–25%. Disclose the limits and keep a human fallback for critical sessions.
Below the top 100: unreliable. No commercial TTS voices, and idiom, toponyms, and cultural context fail often. Use humans.
Accent handling: heavy non-native accents push ASR WER up 15–30% versus a native baseline, and the gap widens under noise. Code-switching (mid-sentence language change) is handled by multilingual models like Deepgram Nova-3 and Chirp 3 but still costs accuracy. Accuracy on regional dialects (Scottish English, Brazilian vs European Portuguese, Arabic variants) tracks training-data coverage.
5 pitfalls that kill AI interpretation projects
1. Benchmarking in the cloud, deploying to home Wi-Fi. Cloud-to-cloud tests show 800 ms; real users on home broadband with jitter see 2.5 s P95. Measure where your users actually are.
2. Ignoring glossaries. Pharma, legal, financial, and technical domains have hundreds of proper nouns and acronyms generic MT butchers. Per-event glossaries do more for perceived quality than anything else, so budget 10–20% of integration time for them.
3. Under-specifying compliance early. GDPR residency, HIPAA BAAs, and Article 50 disclosure are architecture-level. Retrofitting them costs 3–5× more than building them in. Scope compliance in week 1, not week 10.
4. Skipping the human fallback. For board meetings, investor briefings, and regulatory hearings, keep a human interpreter on standby. KUDO and Interprefy offer hybrid tiers for this case. A $2k/day interpreter is cheap insurance against a $2M incident.
5. Choosing direct S2S too early. Meta SeamlessM4T v2 is impressive and non-commercially licensed; native S2S generally has less operational tooling than the mature cascade. Unless voice preservation is a core differentiator, ship the cascade and revisit direct S2S in 12–18 months.
The 30-day pilot that works: pick your three most common language pairs, run AI in parallel with your human interpreters for 30 days, and collect per-session satisfaction scores and transcript comparisons. At day 30 you know whether AI is good enough for your audience, which pairs still need humans, and where your glossary gaps are. Every deployment we’ve shipped started here.
When NOT to use AI interpretation
AI has real limits, and we’d rather name them up front. In the cases below, a human interpreter is still the right answer.
- Court proceedings, depositions, immigration and asylum hearings. AI is not accepted in most US and EU jurisdictions; certified humans are required.
- High-risk medical: informed consent, diagnosis, psychiatric evaluation, medication instruction. Liability and patient safety require certified humans.
- Diplomatic or classified government work. Data residency and security requirements typically exclude commercial cloud vendors.
- Creative content: literature, poetry, film, theater. Metaphor, allusion, and wordplay are where MT is weakest, and will be for years.
- Low-resource languages below the top 100. Quality is unreliable and there are no professional TTS voices.
- High-stakes board, investor, or M&A negotiations. This is a risk-tolerance limit rather than a technology one. When a single mistranslation can move $100M, you pay for humans.
A decision framework — pick your stack in five questions
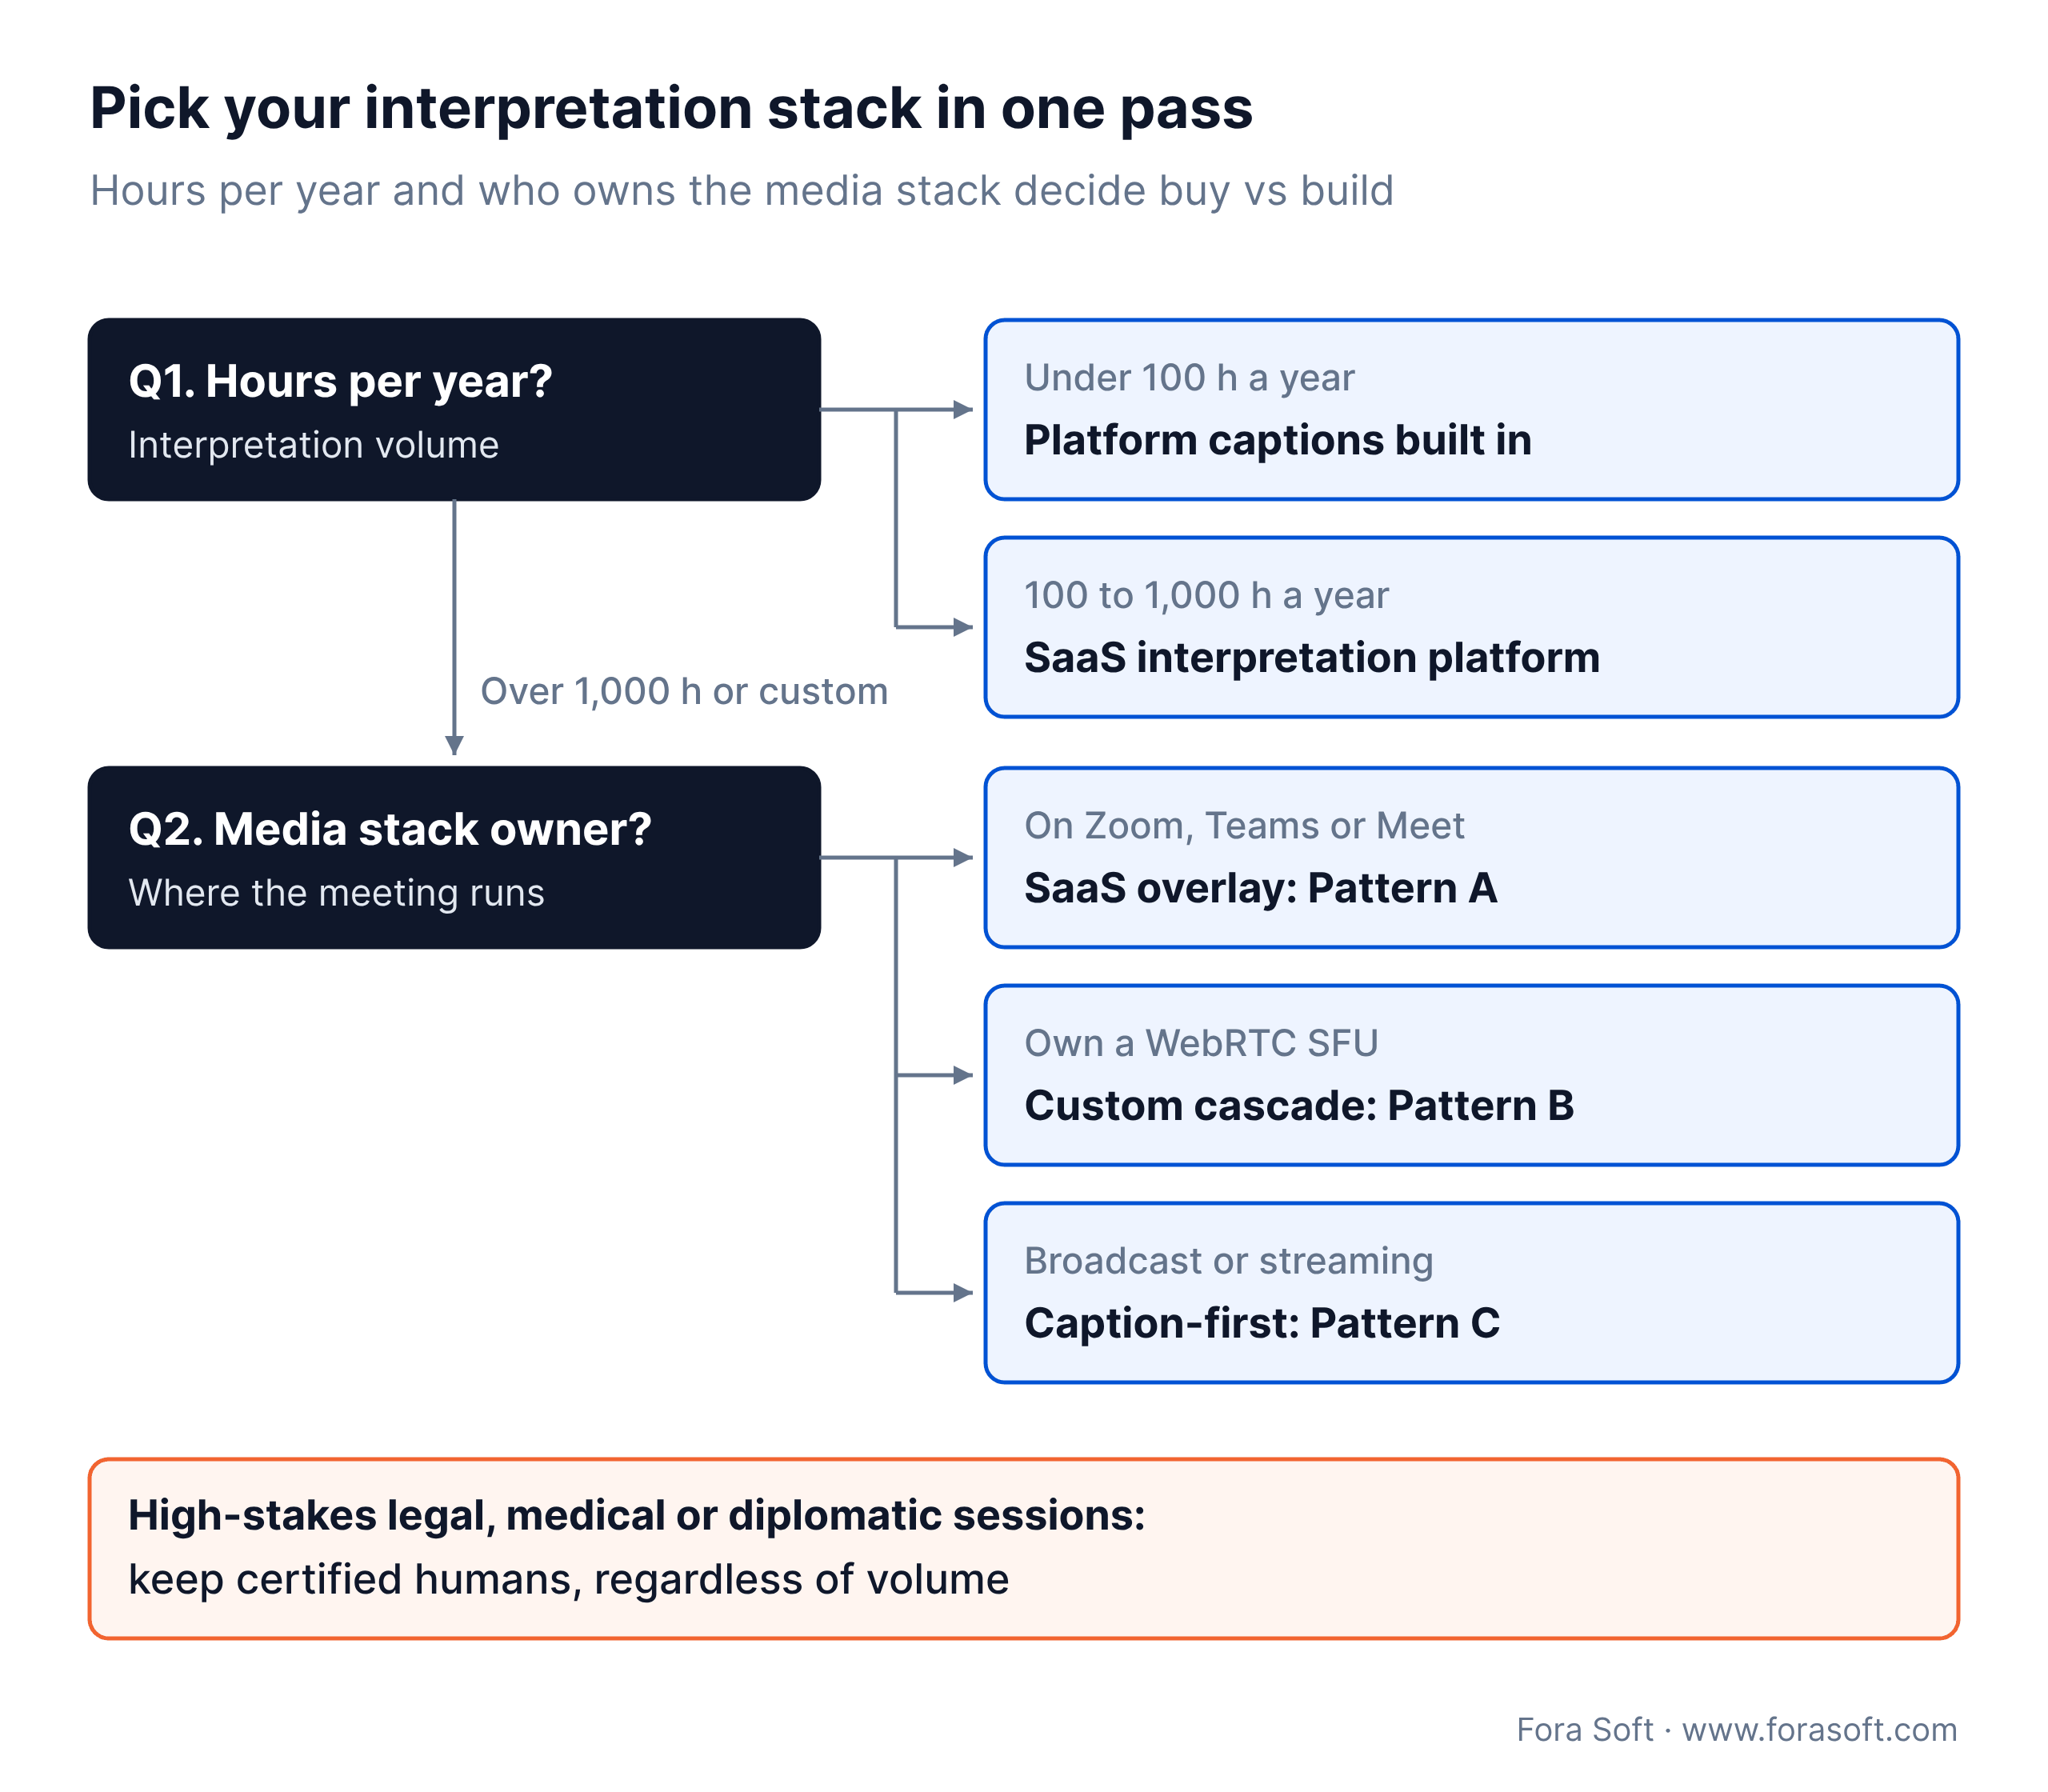
Figure 5. Two questions route most teams from buy to build; high-stakes sessions stay human.
1. How many hours per year? Under 100: stay with humans or a built-in platform (Zoom AI Companion). 100–1,000: SaaS interpretation (Wordly, KUDO AI). Over 1,000 or a differentiated product: custom build on a WebRTC SFU.
2. How many language pairs? One to five top-30 pairs: any vendor works. Ten or more, or low-resource: you need NLLB-200 or enterprise MT with custom terminology.
3. Captions or voice dubbing? Captions-only means a simpler, cheaper pipeline with under 1 s latency. Voice dubbing adds TTS, more latency, and voice-cloning consent.
4. What’s your compliance surface? GDPR and Article 50 only: any major vendor with a DPA. HIPAA: BAA-signed enterprise vendors and a human-review path. Court or regulatory: stay with humans.
5. Who owns the media stack? On Zoom/Teams/Meet: Pattern A (SaaS overlay). Your own WebRTC SFU: Pattern B (integrated cascade). Broadcast or streaming: Pattern C (caption-first). If the answer points to a build, that’s exactly what our interpretation team scopes.
Integration playbook: the 10–14-week path
| Weeks | Phase | Deliverable |
|---|---|---|
| 1–2 | Discovery + architecture | Vendor selection, data-flow diagram, compliance matrix |
| 3–4 | Pipeline prototype | ASR + MT + TTS end to end, latency baseline, 2 language pairs |
| 5–7 | SFU integration + client UX | Per-language audio tracks, caption overlay, language picker |
| 8 | Glossary + terminology | Per-event glossary loader, keyword boost lists, custom prompts |
| 9 | Compliance wiring | GDPR DPA chain, Article 50 disclosures, HIPAA BAAs, retention |
| 10–11 | Load testing | Concurrent sessions, N-language fan-out, failure modes |
| 12–13 | Pilot with real users | Parallel run vs humans (start of the 30-day pilot), quality sampling, NPS |
| 14 | Production rollout | SLA, observability, runbook, on-call, handover |
For a SaaS overlay (Pattern A), compress to 4–6 weeks: skip the SFU integration but keep compliance and the pilot. For a broadcast build (Pattern C), add 4–6 weeks for CVAA compliance and CDN caption delivery. For a timeline against your specific stack and volume, book a 30-minute scoping call and we’ll walk the phases week by week.
Where AI interpretation is heading in 2026–2027
Direct speech-to-speech goes mainstream. As commercially licensed native-S2S models mature (OpenAI’s GPT-Realtime line since May 2026, Google’s Gemini 3.5 Live Translate since June 2026), expect 30–40% of new deployments to use direct S2S by end of 2027, led by media and creative work.
Speaker voice preservation becomes standard. By 2027 most AI interpretation will output in the speaker’s own voice; ElevenLabs voice cloning already enables it (Meta SeamlessExpressive does too, under a research-only license), and Zoom’s Voice Translator has kept the speaker’s voice characteristics since July 2026, with consent workflows as the gating factor.
Sub-second end-to-end latency becomes normal. Co-location, speculative TTS, and wait-k tuning keep tightening the cascade; native S2S drops the floor further. P50 under 1 s for voice dubbing is the 2027 target.
Regulatory consolidation. Article 50 is the template; expect US state-level and Asian equivalents by 2027, and disclosure UX to become a regulated design pattern.
FAQ
What is the best simultaneous interpretation software in 2026?
No single tool wins; the choice depends on volume and control. For turnkey events, Wordly (AI-only) and KUDO (AI plus human fallback) lead; for enterprise all-hands, the built-in Zoom, Teams, and Google Meet features are often enough. For a product that needs custom voices, glossaries, or data residency, a custom cascade on Deepgram + an LLM + ElevenLabs beats every off-the-shelf tool. Match the tool to your hours per year, languages, and compliance surface.
Which companies lead AI simultaneous interpretation in 2026?
Three groups lead. Meeting suites ship it built in: Zoom Voice Translator (5 languages, July 2026), the Microsoft Teams Interpreter agent (10 languages) and Google Meet speech translation (63 languages since October 2026). Event platforms sell it as a service: Wordly (AI-only), KUDO and Interprefy (AI plus human interpreters), Boostlingo and Verbit. Model vendors supply the engines underneath: OpenAI GPT-Realtime-Translate, Google Gemini 3.5 Live Translate, Deepgram, ElevenLabs (Eleven Realtime Translation) and DeepL (Aure). AI’s main effect so far has been to open the far larger market of meetings that never had interpretation, more than to replace booth interpreters.
How do I evaluate AI interpretation platforms for my conference?
Test on your own audio rather than a vendor demo. Take your three most-used language pairs, feed each platform a recorded session with your speakers’ accents and terminology, and score five things: end-to-end delay (under 2 s P50 for voice), terminology hit rate with your glossary loaded (above 95%), listener scores on “I could follow” (above 4 of 5), data handling (DPA, EU residency, retention), and whether a human interpreter can take over a channel mid-session.
What should an “AI is interpreting this meeting” notice say?
Tell people at the start and on screen that an AI system is translating, which languages are machine-interpreted, whether the translated voice is synthetic or cloned, and how to reach a human or report an error. A workable line: “This session uses AI interpretation; translated audio and captions are machine-generated and may contain errors.” In the EU, Article 50 of the AI Act also requires machine-readable marking of the synthetic audio.
What is remote simultaneous interpretation (RSI) software?
RSI software carries a live event’s audio to interpreters working from anywhere and sends each language channel back to the audience on the web, in an app, or inside Zoom or Teams. Interprefy, KUDO and Boostlingo started as RSI platforms for human interpreters; in 2026 Interprefy and KUDO also offer AI channels, so one event can mix human and machine languages. The difference from AI live translation is the interpreter: RSI is the platform that routes audio to whoever interprets, while AI live translation means software produces the translated captions or voice itself.
Can ChatGPT or AI replace human interpreters?
For mid-stakes content in top-30 languages with glossary tuning, AI is now good enough for many sessions that used to get a junior interpreter. OpenAI’s GPT-Realtime-Translate does live speech translation across 70+ input languages. For legal, diplomatic, and high-risk medical work, and for rare languages, no: certified humans are still required, both legally and for quality. Realistically, in 2026 that means AI for scale and humans for high-stakes work.
How accurate is AI simultaneous interpretation?
On top-30 languages with a domain glossary, expect ASR word error rate under 10% and translation accuracy around 90–95% against human reference. Accuracy drops on heavy accents, noisy audio (WER roughly doubles), and low-resource languages. Measure in production against human transcripts. Vendor benchmarks are usually recorded on clean audio, so expect worse numbers in production.
What latency should you target?
Captions: P50 under 1 s, P95 under 1.5 s. Voice dubbing: P50 under 2 s, P95 under 3 s. Humans tolerate up to ~4 s of ear-voice span; above that, fluency breaks and people complain.
How much does a custom build really cost?
Roughly $140–220k one-time integration over 10–14 weeks, $15–25k/year in ops and on-call, plus API costs (~$3.10 per speaker-hour for the first language, ~$2.65 for each extra one). Break-even versus Wordly or KUDO lands around 500–1,000 hours a year; below that, SaaS wins.
How is AI interpretation priced?
AI interpretation is priced per minute or hour of audio at the API level and per event, hour or seat on platforms. OpenAI GPT-Realtime-Translate costs $0.034 per minute (about $2 per hour per voice channel) and the Zoom Interpreter API $2 per hour, both as of November 2026; built-in features in Zoom, Teams and Google Meet come with the plan or an add-on, and event platforms such as Wordly and KUDO quote per event or per hour. Human simultaneous interpreters are billed per interpreter-day, two per language.
Zoom captions or a dedicated platform: which do you need?
If your event mix is under ~100 hours a year in top-30 languages, Zoom AI Companion or Teams Premium is fine. Above that, or with specialized terminology, Wordly, KUDO, or a custom cascade produces noticeably better results and gives you glossary control.
Can AI interpret in my speaker’s own voice?
Yes. ElevenLabs Instant and Professional Voice Clones support it for commercial products (Meta SeamlessExpressive does too, but under a research-only license), and Zoom Voice Translator keeps the speaker’s voice characteristics. You need a consent workflow, a few minutes of source audio, and a one-time enrollment. Voice-cloning laws such as Tennessee’s ELVIS Act and GDPR call for documented consent, and EU AI Act Article 50 for disclosure of the synthetic voice, so plan a signed release.
Do I need to disclose AI interpretation to users?
Under EU AI Act Article 50, applicable since 2 August 2026, yes. Best practice is an opening announcement (“this session uses AI interpretation”), a visible label on captions, and machine-readable marking of synthetic audio. US states are converging on similar rules. Build disclosure into the UX from day one.
What about on-premises or air-gapped deployments?
Possible, with more work. Self-host Whisper v3 for ASR, Llama or NLLB-200 for MT, and Piper or Coqui for TTS. Quality runs 15–30% below the cloud leaders, but it’s necessary for classified government, some healthcare, and strict EU-residency deployments.
What to read next
Architecture
Real-time speech translation
The Fora Soft architecture guide behind this playbook — latency vs accuracy in depth.
Vendors
AI translation companies
The vendor landscape beyond live interpretation, compared head to head.
Voice stack
AI voice recognition for intercoms
The sibling piece on the voice stack, focused on access-control hardware.
Streaming
AI streaming platforms
How live interpretation plugs into WebRTC and broadcast delivery.
Ready to scope your interpretation stack?
AI simultaneous interpretation in 2026 is a buying decision for most organizations and a build decision for a few. The cascade wins on modularity, glossary control, and operational maturity; direct speech-to-speech wins on prosody, and is finally commercially viable through OpenAI and Google. The economics settle it: AI replaces $5,400–13,200/day human budgets with $800–2,500 SaaS or ~$60–80 DIY spend, and a tuned cascade now lands inside a human interpreter’s latency window. Get glossaries and compliance right early, keep humans for legal, diplomatic, and high-risk medical, and you have a system that scales interpretation to every meeting instead of the once-a-year kickoff.
If you want a second opinion on buy vs build, or an engineering team that’s shipped this into conferencing, telehealth, and broadcast, we’re a call away, and we’ll give you a straight answer on which path fits your stack.
The book · Volume 7 of 7
AI for Video: A Complete Guide to Intelligence in Video Products: From Real-Time Pipelines and Agents to Serving, Cost, Compliance, and Verticals
Interpretation lives or dies on the latency budget this playbook breaks down stage by stage. Volume 7 goes deeper into real-time AI pipelines: where translation enters a WebRTC call, live subtitles, moderation on the fly, and the EU AI Act rules that touch speech systems. It helps event and conferencing teams plan a stack that holds up in a live room. Written by Nikolay Sapunov, CEO at Fora Soft.
Read it on Amazon →Kindle & paperback · Fora Soft Video Engineering Handbook
Ready to scope your AI interpretation project?
We’ve shipped AI interpretation into corporate all-hands, hybrid events, telehealth, and broadcast. A free 30-minute scoping call — we’ll tell you honestly whether to buy, build, or hybrid, and what the real timeline looks like.

