

Speech recognition accuracy collapses in noise, and that’s where most voice products fail. A demo that hits 6% Word Error Rate (WER) in a quiet room drifts to 30%+ on a warehouse floor, and the team finds out after launch. Switching APIs alone rarely fixes it, even though the strongest options in November 2026 are clear (Deepgram Nova-3 for live audio; Zoom Scribe API Pro, ElevenLabs Scribe v2 or AssemblyAI Universal-3.5 Pro for recordings). The fix is three layers working together: a neural noise-suppression front-end (Krisp, NVIDIA Maxine, or DeepFilterNet), a noise-hardened acoustic model (Deepgram Nova-3, Whisper Large v3 Turbo, NVIDIA Parakeet, or Conformer-RNNT), and domain fine-tuning plus keyterm biasing on your actual vocabulary. With all three in place, noisy WER in our projects drops from 25–40% to roughly 10–16% on office and call-center audio.
Do only one of the three and you’ll ship something that demos well in the office and falls apart in a drive-thru, a call center, or a hospital corridor. We’ve shipped ASR into all of those and watched it happen. Fora Soft has built 250+ real-time communication products since 2005, and AI-integrated voice and video systems are one of our deepest specialties, from medical platforms where every clinical term has to land to live-streaming apps where captions run over crowd noise and music.
This is the playbook we use: the three strategies that matter, the 2026 model lineup with real numbers, a reference pipeline you can lift into production, and the cost math of cloud APIs versus self-hosting. If you’re choosing between Deepgram, Whisper, Riva, and AssemblyAI for a product where people won’t always be in a quiet room, start here.
Key takeaways
• Three layers, not one. Noise suppression, a noise-hardened model and domain biasing. Skip any of them and you lose several WER points.
• The front-end is the cheapest win. A Krisp-class suppressor alone cuts noisy WER by 20–40% relative, before you touch the model.
• Keyterm biasing beats retraining for vocabulary. Deepgram takes up to 500 tokens of keyterms per request, and AssemblyAI up to 1,000 terms on batch models (October 2026). That gives you accuracy on drug names, part numbers and proper nouns at no extra cost.
• Vendor WER is not your WER. On the Open ASR Leaderboard (13 November 2026), adding noise and room reverberation to the same speech multiplies WER by 1.5–2.8. Real meeting audio (AMI) sits at 6–14%. Measure on your own audio.
• Default 2026 stack. For cloud, Krisp + Nova-3 + keyterm biasing. For self-hosted, DeepFilterNet + Whisper v3 Turbo + a LoRA fine-tune.
Updated November 2026: clean vs noisy WER on the same speech from the 13 November Open ASR Leaderboard, Zoom Scribe API and NVIDIA Nemotron 3.5 Transcribe added, new ElevenLabs prices, Deepgram Nova-3 Pharma and Azure 2,000-phrase lists.
Which Speech Recognition API Is Best for Noisy Audio? The Short Answer
No single API is best in noise; the best result comes from a stack. For live calls and voice agents, put Deepgram Nova-3 (or Deepgram Flux for turn-taking agents) or AssemblyAI Universal-3.6 Pro Realtime behind a neural suppressor such as Krisp. For recorded audio, Zoom’s Scribe API Pro model has the lowest noisy-speech WER on the public Open ASR Leaderboard (13 November 2026), with ElevenLabs Scribe v2 and AssemblyAI Universal-3.5 Pro close behind. For self-hosting, run NVIDIA Nemotron 3.5 Transcribe, Canary-Qwen or Parakeet, or Whisper Large v3 Turbo, with DeepFilterNet in front.
Does voice-to-text work well in noisy environments? Only partly. The Open ASR Leaderboard (13 November 2026) scores the same 1.9 hours of speech twice: once clean, once with added noise and room reverberation (the URGENT24 set). The best hosted APIs go from 4–5 errors per 100 words to 6.6–9.2. Whisper Large v3 and Canary-Qwen go from under 6 to about 13. Noise and echo alone multiply errors by 1.5 to 2.8, and mic distance and overlapping talkers come on top of that.
| Model (November 2026) | WER, clean speech (URGENT24 Clean) | WER, same speech + noise and reverb (URGENT24) | WER, meeting audio (AMI) | List price, batch |
|---|---|---|---|---|
| Zoom Scribe API Pro (scribe_v2.1_pro) | 4.34% | 6.63% | 5.96% | $0.30/hr |
| ElevenLabs Scribe v2 | 4.70% | 9.20% | 8.20% | $0.20/hr |
| AssemblyAI Universal-3.5 Pro | 5.06% | 9.08% | 10.63% | $0.21/hr |
| NVIDIA Nemotron 3.5 Transcribe (open) | 4.36% | 10.94% | 7.78% | self-host |
| NVIDIA Parakeet TDT 0.6B v2 (open) | 5.38% | 11.42% | 9.09% | self-host |
| NVIDIA Canary-Qwen 2.5B (open) | 4.63% | 13.02% | 7.91% | self-host |
| OpenAI Whisper Large v3 (open) | 5.77% | 13.73% | 13.63% | self-host |
Source: Hugging Face Open ASR Leaderboard v1.16.0 (13 November 2026), short-form English, cleaned-reference WER; URGENT24 Clean and URGENT24 score the same speech without and with added noise and room impulse responses. The leaderboard dropped LibriSpeech from its default average on 2 November 2026. Prices from vendor pricing pages, November 2026. Deepgram Nova-3 is not in this table because Deepgram does not submit to the leaderboard.
One pattern in this table matters for self-hosting. The open models lose more accuracy to noise than the hosted leaders do, so a neural suppressor in front of an open model buys back more than it does in front of a hosted API.
How do you improve voice recognition accuracy and speech-to-text accuracy in noisy audio? Work in this order: clean the audio with a neural suppressor, pick a model trained on noisy speech, then add keyterm biasing for your vocabulary. In Krisp’s August 2026 test across 10 speech-to-text engines, its Voice Isolation 2.5 front-end cut average WER from 15.35% to 8.22%, and from 35.92% to 10.90% when another person was talking in the background. The same test shows where it backfires. In hard room acoustics with a single speaker, processed audio scored 11.61% against 8.02% unprocessed, so test the suppressor on and off with your own audio.
Is speech recognition reliable for noisy call-center recordings? For analytics and agent assist, yes, once you add suppression and keyterms. In our 2026 projects we target 12–16% WER on contact-center audio. For unsupervised legal or medical records it is not reliable enough, so keep a human reviewer on those.
Why Noisy Speech Recognition Is Still Hard in 2026
Transformer-based ASR now tops the standard benchmarks. The best 2026 models score 1–2% WER on read audiobook speech (Open ASR Leaderboard, October 2026) and about 5–7% on clean conversational audio in our evaluations. Production audio is rarely that clean. Real users speak:
• Into laptop mics across an open-plan office with HVAC and coworker chatter in the 60–80 dB range.
• Through car speakerphones at 70 km/h, where road rumble sits in the 100–500 Hz band that overlaps male fundamental frequencies.
• Over VoIP from call-center agents sharing a floor with 200 other agents.
• Into warehouse scanners with forklift beeps, PA announcements, and metal-on-metal impacts.
• Into clinical headsets in ICUs where monitors beep every two seconds and ventilators hiss constantly.
• Through Bluetooth earbuds that denoise hard before the signal reaches you, sometimes stripping phonemes along with the noise.
Put a top model into any of those settings and WER triples. Deepgram’s own docs acknowledge that noisy conditions add 5–10 points of overhead even with Nova-3. Whisper, trained on a wide distribution of internet audio, degrades more gracefully but still loses 8–15 points on heavy-noise material. Most ASR projects fail in the gap between “model benchmark” and “product WER”, and our speech recognition software development work is built to close it.
Reach for a three-layer stack when: your users won’t reliably be in a quiet room. Below ~15 dB signal-to-noise ratio, no single model will carry the product alone, however good it is.
Applied together, the three strategies below close most of that gap. They also take engineering work that cloud-API marketing pages rarely mention.
The 2026 WER Benchmarks: What Good Looks Like
Before you set a target, check what the frontier delivers today. These are the reference points we use in 2026, aggregated from public leaderboards (the HuggingFace Open ASR Leaderboard, Artificial Analysis) and our own evaluations on customer audio.
| Scenario | WER target (English) | What gets you there |
|---|---|---|
| Clean studio / headset, native speaker | 5–7% | Any frontier model out of the box |
| Video conferencing, quiet room | 7–10% | Frontier model + basic VAD |
| Open-plan office, background chatter | 10–14% | Add neural noise suppression |
| Call center / contact center | 12–16% | Noise suppression + keyterm biasing |
| In-vehicle, drive-thru, retail | 14–20% | All 3 strategies + domain fine-tune |
| Industrial / warehouse / clinical | 16–24% | All 3 strategies + custom acoustic model |
| Accented / non-native speakers | +3–8 WER points vs native | Multilingual models + balanced training data |
If your current pipeline is more than 5 WER points above the relevant row, you have room to improve. Adding a layer usually helps more than switching models. The chart below shows how the layers compound.
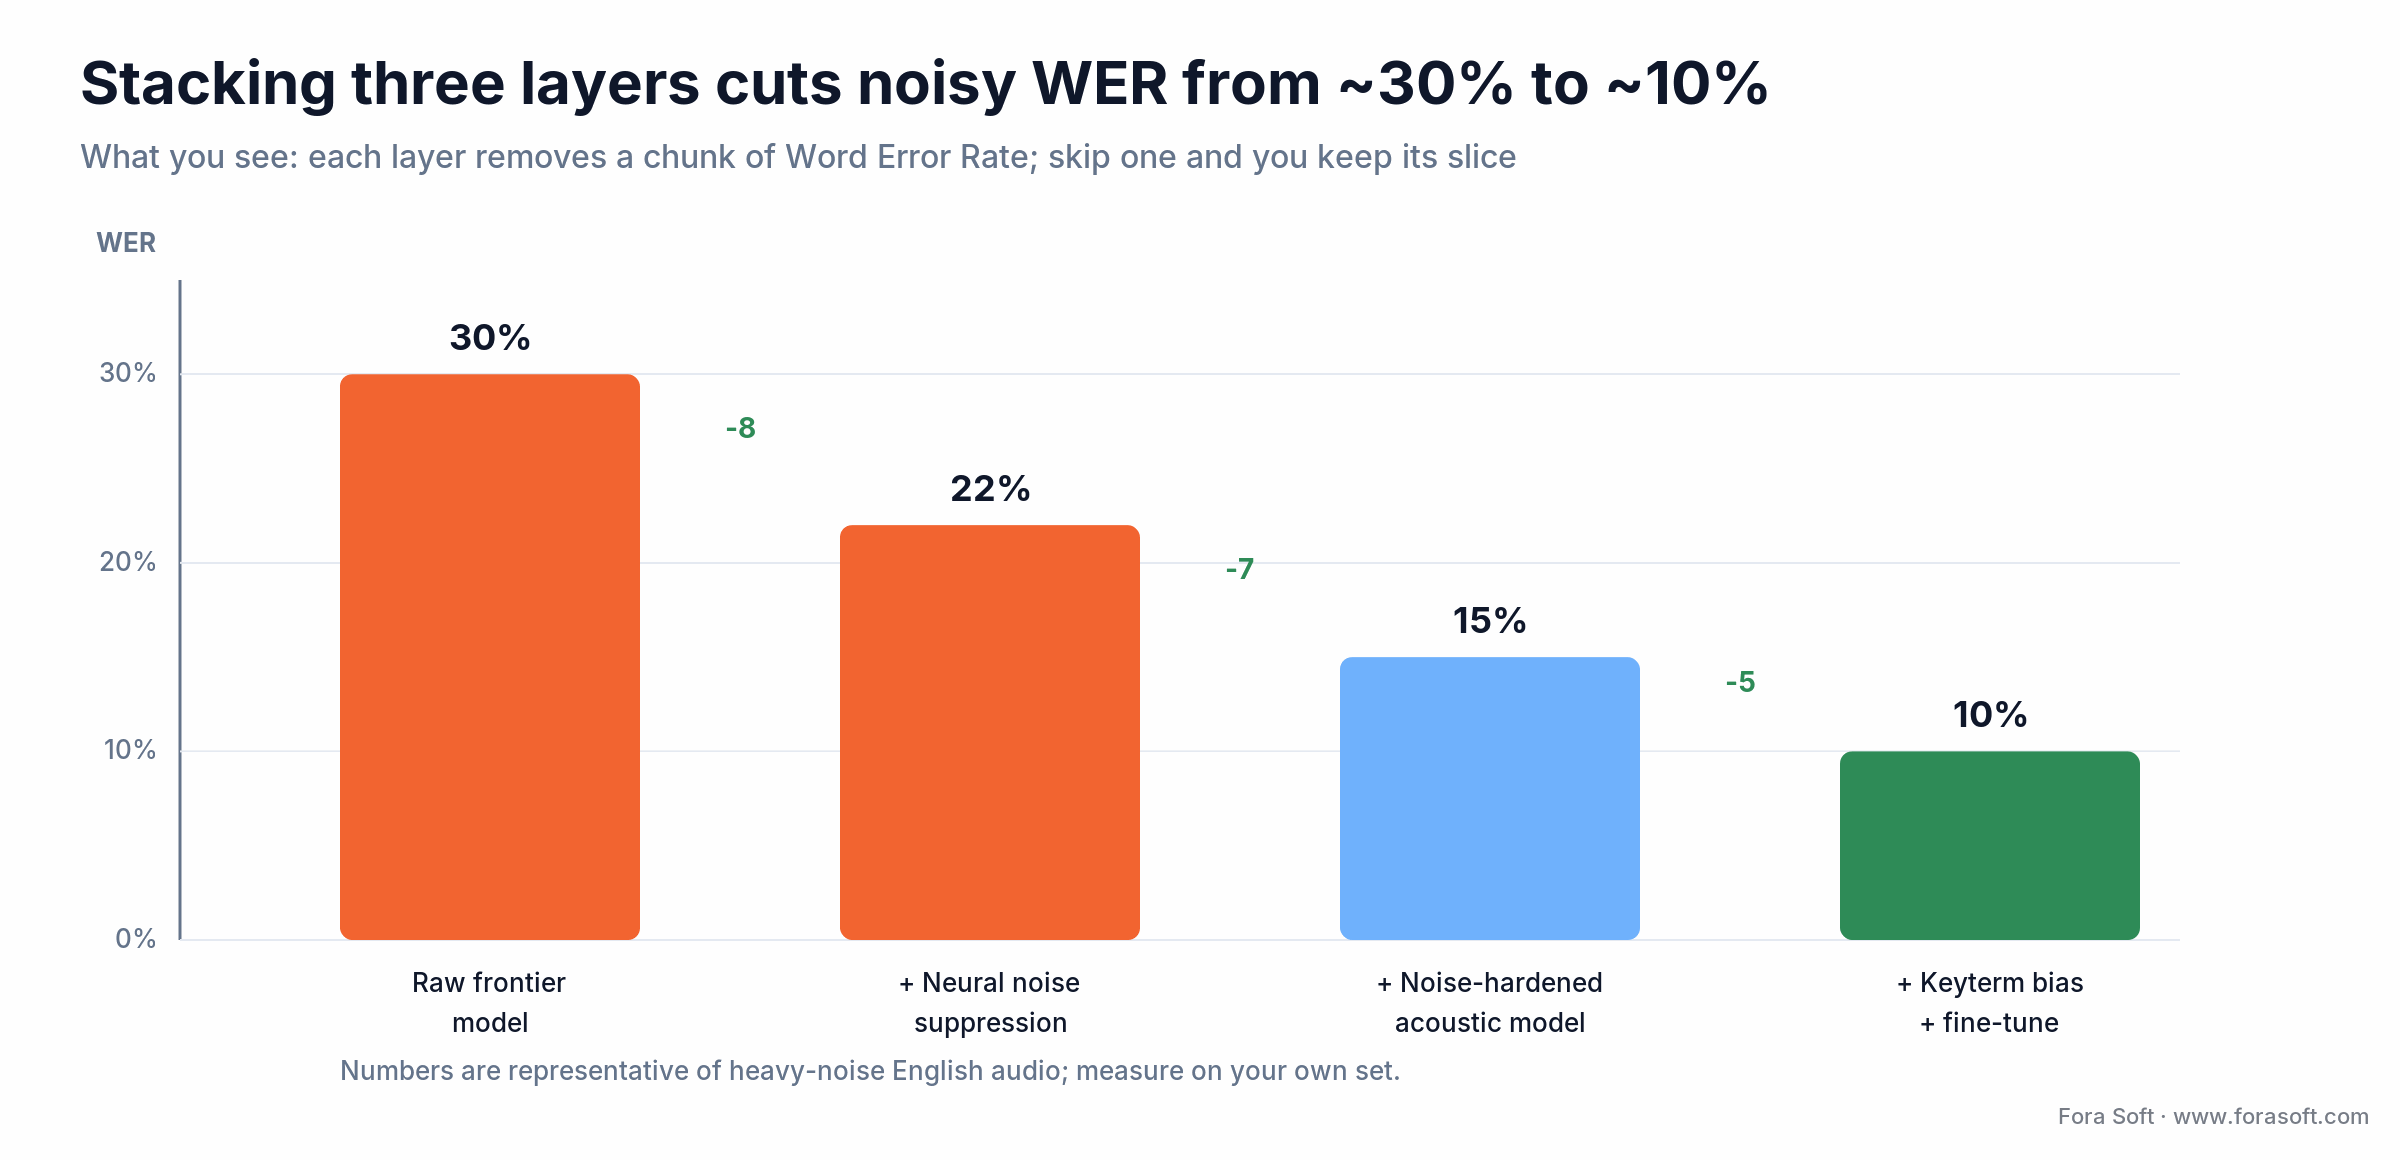
Figure 1. Each layer removes a slice of noisy WER; skip a layer and you keep its slice.
The 3 Strategies That Actually Move the Needle
Every noise-hardened ASR system we’ve shipped or audited comes down to three layers. Teams that skip one try to make up for it with the other two and hit a ceiling.
1. Clean the audio before the model sees it. A neural front-end removes stationary noise (fans, HVAC), non-stationary noise (typing, door slams), and competing speech. In 2026 this is the highest-impact intervention. Modern suppressors run in real time on commodity hardware, and the gain compounds with every layer after it.
2. Use a model trained on noise. Frontier ASR models in 2026 are bigger, and they are also trained on deliberately degraded audio (SpecAugment, room-impulse-response convolution, additive noise at controlled SNR). Pick one whose training distribution matches where you deploy.
3. Teach the model your vocabulary. Even a perfect generic model mis-transcribes your product names, drug names, medical codes, or part numbers. Keyterm biasing at inference, or light fine-tuning on domain data, fixes those error classes cheaply. The next three sections cover each layer in detail.
Transcription WER bleeding above 15% on real audio?
Book 30 minutes with our speech lead. We diagnose the preprocessing, the VAD, and the model choice, most teams are one config change from a 5–8 point WER drop.
Strategy 1: Neural Front-End Noise Suppression
In 2026, sending raw microphone audio from a noisy room straight to an ASR model is rarely the right call. A neural suppressor sits between the mic and the transcriber and cleans the waveform in real time. The main options:
Krisp SDK
This is the most widely deployed neural suppressor in the industry. Zoom licensed Krisp’s technology for its noise cancellation, and the SDK ships inside hundreds of communication products. It runs in under 15 ms on a single CPU core, removes most stationary and non-stationary noise, and keeps speech sounding more natural than classical DSP does. We default to it in production apps when the licensing cost is acceptable. The current Voice Isolation 2.5 model (August 2026) runs on CPU with 15 ms of algorithmic latency and also removes background voices, the noise class that hurts ASR most.
NVIDIA Maxine Audio Effects
GPU-accelerated noise removal with room-echo cancellation and super-resolution. It beats Krisp on hard cases but needs NVIDIA hardware, so it suits server-side pipelines and AI-first endpoints better than commodity mobile devices. As of NVIDIA’s September 2026 Audio Effects SDK docs, Speaker Focus removes background talkers. The SDK’s acoustic echo cancellation effect is deprecated, though, so plan echo cancellation elsewhere (WebRTC AEC3).
RNNoise, DeepFilterNet, Demucs (open source)
RNNoise (Xiph) is the classic lightweight option: free, with a tiny CPU footprint, and good enough for many cases. DeepFilterNet gets quality higher, and Meta’s Demucs handles source separation when music sits under speech. For on-device use on mid-range phones we currently reach for DeepFilterNet v3 at int8.
Platform-native denoisers
Apple’s Voice Isolation, Google Meet’s noise cancellation and modern Bluetooth codecs already denoise upstream. That helps, but they can also strip phonemes your ASR needs. We test with native denoising both on and off, and sometimes ask users to disable it.
Reach for a neural suppressor when: SNR drops below ~15 dB or other people talk in the background. In our projects it typically cuts WER by 20–40% relative under those conditions, which makes it the cheapest intervention before changing models. A/B test it on and off: in clean or reverberant rooms it can hurt.
Strategy 2: Noise-Hardened Acoustic Models
The Conformer architecture (Google, 2020) paired self-attention with convolutional feature extraction and became the de facto backbone of modern ASR. Whisper (OpenAI, 2022) added large-scale weak supervision on 680,000+ hours of varied internet audio, and the result was the first ASR model that degraded gracefully on wild distributions. In 2026 the frontier comes down to a handful of model families, each tuned for a different deployment profile:
• Deepgram Nova-3, proprietary, real-time streaming, ~300 ms latency, about 60 languages; since 23 October 2026 its multilingual mode covers 55 languages in one model (Deepgram changelog). Deepgram reports 6.84% streaming median WER on its own multi-domain set; independent leaderboards put it higher. The strongest fit for real-time voice agents and live captions.
• Whisper Large v3 Turbo, open source, offline/batch. It keeps the v3 encoder but cuts the decoder from 32 layers to 4 (1.54B → 809M parameters), so it runs 2–5× faster and stays within a point of v3 accuracy. Good for recorded-media transcription with zero per-minute cost.
• NVIDIA Parakeet TDT 0.6B v2/v3 & Canary-Qwen 2.5B, the most widely deployed open-weights options; in the 13 November 2026 Open ASR results Canary-Qwen scores 7.91% on AMI meeting audio but 13.02% on the noisy URGENT24 set, while Parakeet prioritizes speed (RTFx above 6,000). Ship via Riva NIM.
• NVIDIA Nemotron 3.5 Transcribe, open weights, released 28 October 2026: a 30B mixture-of-experts model with about 4B active parameters, 40 languages and speaker labels, built for recorded audio rather than live streams (NVIDIA, October 2026). It scores 7.78% on AMI and 10.94% on URGENT24 in the November 2026 leaderboard.
• Zoom Scribe API, hosted, with batch, fast and live modes. Its English Pro model tops the 13 November 2026 Open ASR Leaderboard (4.87% average WER) and has the lowest noisy-speech WER there (6.63% on URGENT24); Pro costs $0.30 per hour batch and $0.40 per hour live (Zoom pricing, November 2026).
• AssemblyAI Universal-3.5 Pro and Universal-3.6 Pro Realtime, strong on call-center audio and speaker diarization. Universal-3.5 Pro (July 2026) is $0.21 per hour for batch in 18 languages; Universal-3.6 Pro Realtime (September 2026) is $0.45 per hour in 32 languages (AssemblyAI pricing, November 2026). Universal-3.6 Pro Realtime also cuts words picked up from nearby talkers from 3.53 to 2.52 per 1,000 words on AssemblyAI’s benchmark, with an optional voice-focus setting (AssemblyAI changelog, 29 September 2026).
• ElevenLabs Scribe v2, batch at $0.20 per hour and Realtime at $0.22 per hour (ElevenLabs pricing, November 2026); 9.20% on the noisy URGENT24 set in the November 2026 Open ASR results.
• OpenAI gpt-transcribe and gpt-live-transcribe, released July 2026; gpt-live-transcribe costs $0.017 per minute (OpenAI pricing, November 2026), and gpt-transcribe scores 12.86% on the noisy URGENT24 set. API-only, with free-form context prompts. It makes sense when the transcript goes straight into an OpenAI LLM anyway.
Reach for a streaming (causal) model when: you render live captions or run a voice agent. Causal models add 1–2 WER points but bring latency under 200 ms, and in conversation that trade pays off.
SpecAugment and noise-mixed training are standard now, so most of these models degrade gracefully, though the amount of noise each saw in training varies. For heavily noisy deployments, prefer models whose vendors publish noisy-condition WER (Deepgram, NVIDIA) over ones that only report LibriSpeech.
Strategy 3: Domain Fine-Tuning and Keyterm Biasing
Even the best generic model turns “metoprolol” into “meta prolo” and “SKU 4-7-A-2-1” into “scue forty seven eight 21.” You don’t need to train from scratch to fix this. Three cheaper moves cover most cases:
Keyterm biasing at inference. Deepgram Nova-3 and Flux take keyterms up to 500 tokens per request (Deepgram recommends 20–50 terms), and since October 2026 the list can be updated mid-stream, including on the EU, Australia and India endpoints. AssemblyAI’s keyterms prompt takes up to 1,000 terms on batch models (a $0.05-per-hour add-on) and 100 on realtime ones. Microsoft’s Azure LLM Speech (09-2026 release, 26 October 2026) accepts phrase lists of up to 2,000 phrases per request. Whisper accepts a glossary prompt; ElevenLabs Scribe v2 bills keyterms at $0.05 per hour batch and $0.08 per hour realtime (pricing pages, November 2026). Biasing buys accuracy on proper nouns, product and drug names, part numbers and jargon without any training, and you can ship it today.
LoRA / light fine-tuning on domain audio. When the whole acoustic distribution is off (heavy accents, specific recording conditions, rare language varieties), a LoRA adapter trained on 20–100 hours of labeled customer audio recovers 3–8 WER points. Whisper, Canary and most HuggingFace pipelines support it.
Custom pronunciation lexicons. For words with non-obvious pronunciation (brand names, code-switched terms), an explicit pronunciation dictionary tells the model how to handle them. Most enterprise ASR platforms expose this.
Do biasing first and fine-tuning second. Biasing costs nothing, can be rolled back and ships in a day. Fine-tuning eats GPU time and adds MLOps overhead, so exhaust biasing before you train.
The Models Compared: Nova-3, Whisper, Riva, AssemblyAI
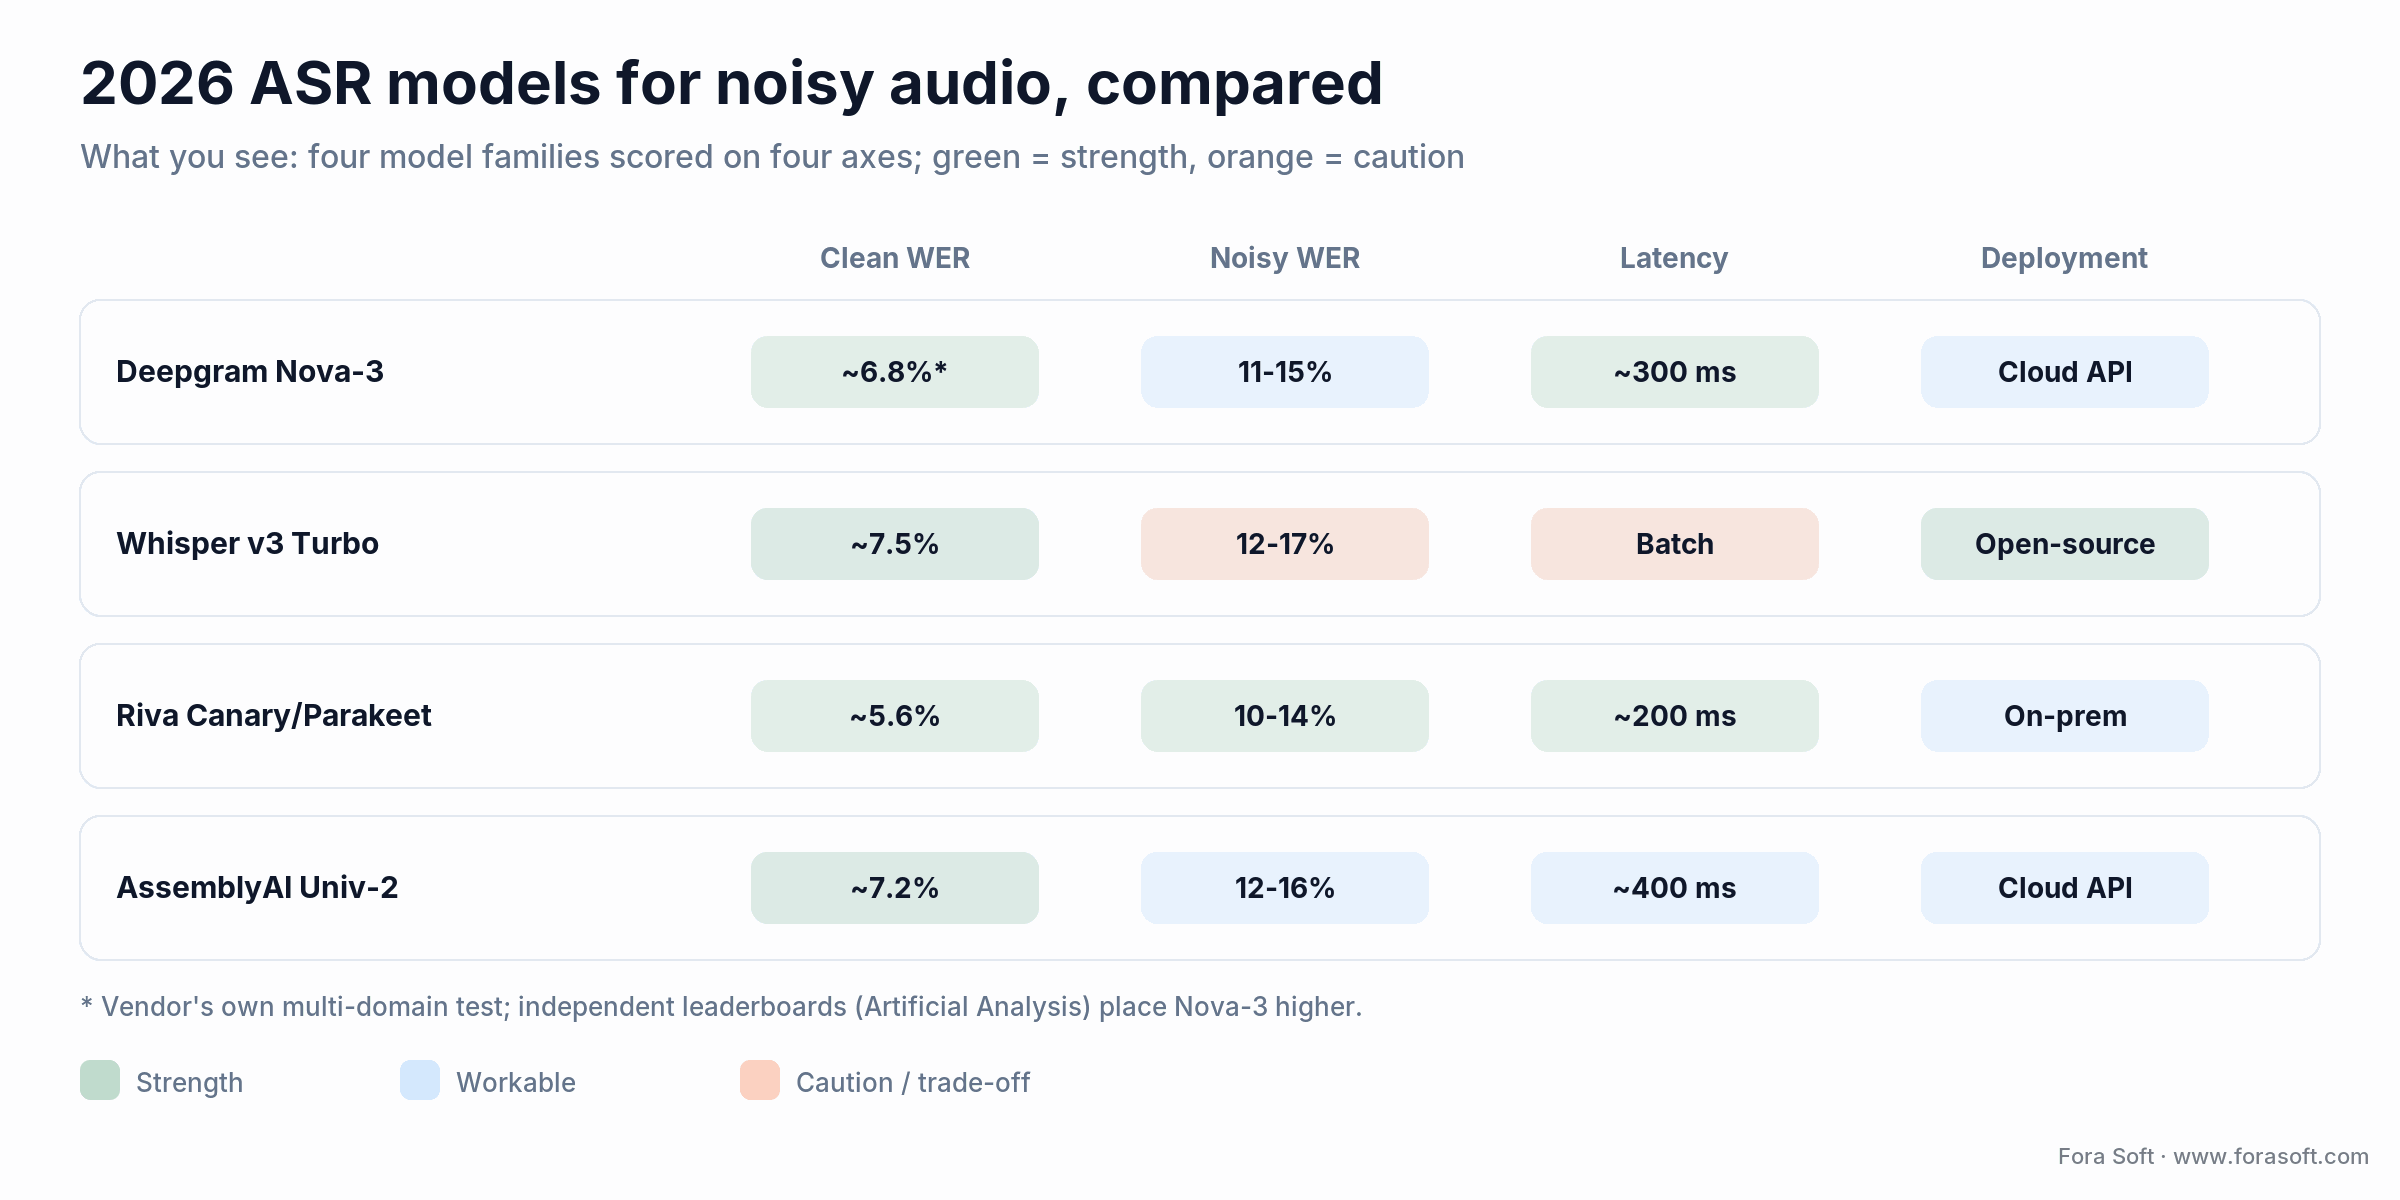
Figure 2. Four model families on four axes. No universal winner: pick per deployment profile.
| Criterion | Deepgram Nova-3 | Whisper Large v3 Turbo | NVIDIA Riva Parakeet/Canary | AssemblyAI Universal-3.5 Pro / 3.6 Realtime |
|---|---|---|---|---|
| Deployment | Cloud API, self-host option | Open source, self-host | NIM microservice, on-prem | Cloud API |
| Real-time streaming | Yes — ~300 ms | Limited (batch-oriented) | Yes — ~200 ms | Yes — ~400 ms |
| Published WER (English, source in cell) | 6.84% streaming, 5.26% batch (vendor set, 2025) | ~7.5% (our evals) | ~5.1% avg (Canary-Qwen, Open ASR, Oct 2026) | ~5.0% avg (Universal-3.5 Pro, Open ASR, Oct 2026) |
| Noisy WER (our 2026 evals, call-center audio) | 11–15% | 12–17% | 10–14% | 12–16% |
| Languages | ~60 | 99 | 25 (Parakeet v3) | 18 batch / 32 realtime |
| Keyterm biasing | Keyterms, 500 tokens | Prompt-based | Custom vocab | Keyterms, 1,000 batch / 100 realtime |
| Diarization | Yes | Via pyannote bolt-on | Yes | Yes, strong |
| Price (per min) | $0.0043 batch, $0.0048–0.0077 streaming (Oct 2026) | Infra only (~$0.001) | GPU-hour pricing | $0.0035 batch, $0.0075 realtime (Oct 2026) |
| Best for | Real-time agents, contact centers | Batch media, privacy-sensitive | Regulated on-prem, leaderboard WER | Podcast/meeting intelligence |
No single model wins everywhere. For real-time noisy use cases we default to Nova-3 + Krisp front-end + keyterm biasing. For on-prem or compliance-bound deployments we go with Whisper v3 Turbo or Riva Canary on customer GPUs. For media transcription at scale, batch Whisper is the cheapest option.
Watch for this failure mode: benchmarking on LibriSpeech instead of your real audio. Benchmark choice moves WER more than model choice: on the 13 November 2026 Open ASR results, Whisper Large v3 scores 1.56% on LibriSpeech clean, 13.63% on AMI meeting audio and 13.73% on noisy URGENT24. The leaderboard itself dropped LibriSpeech from its default average on 2 November 2026. Artificial Analysis also re-based its speech benchmark in February 2026, so older third-party WER figures are not comparable with today’s.
Reference Architecture: A 2026 Noise-Hardened ASR Pipeline
Here is the pipeline we deploy for noisy real-time workloads. Every stage has its own job, latency budget and fallback.
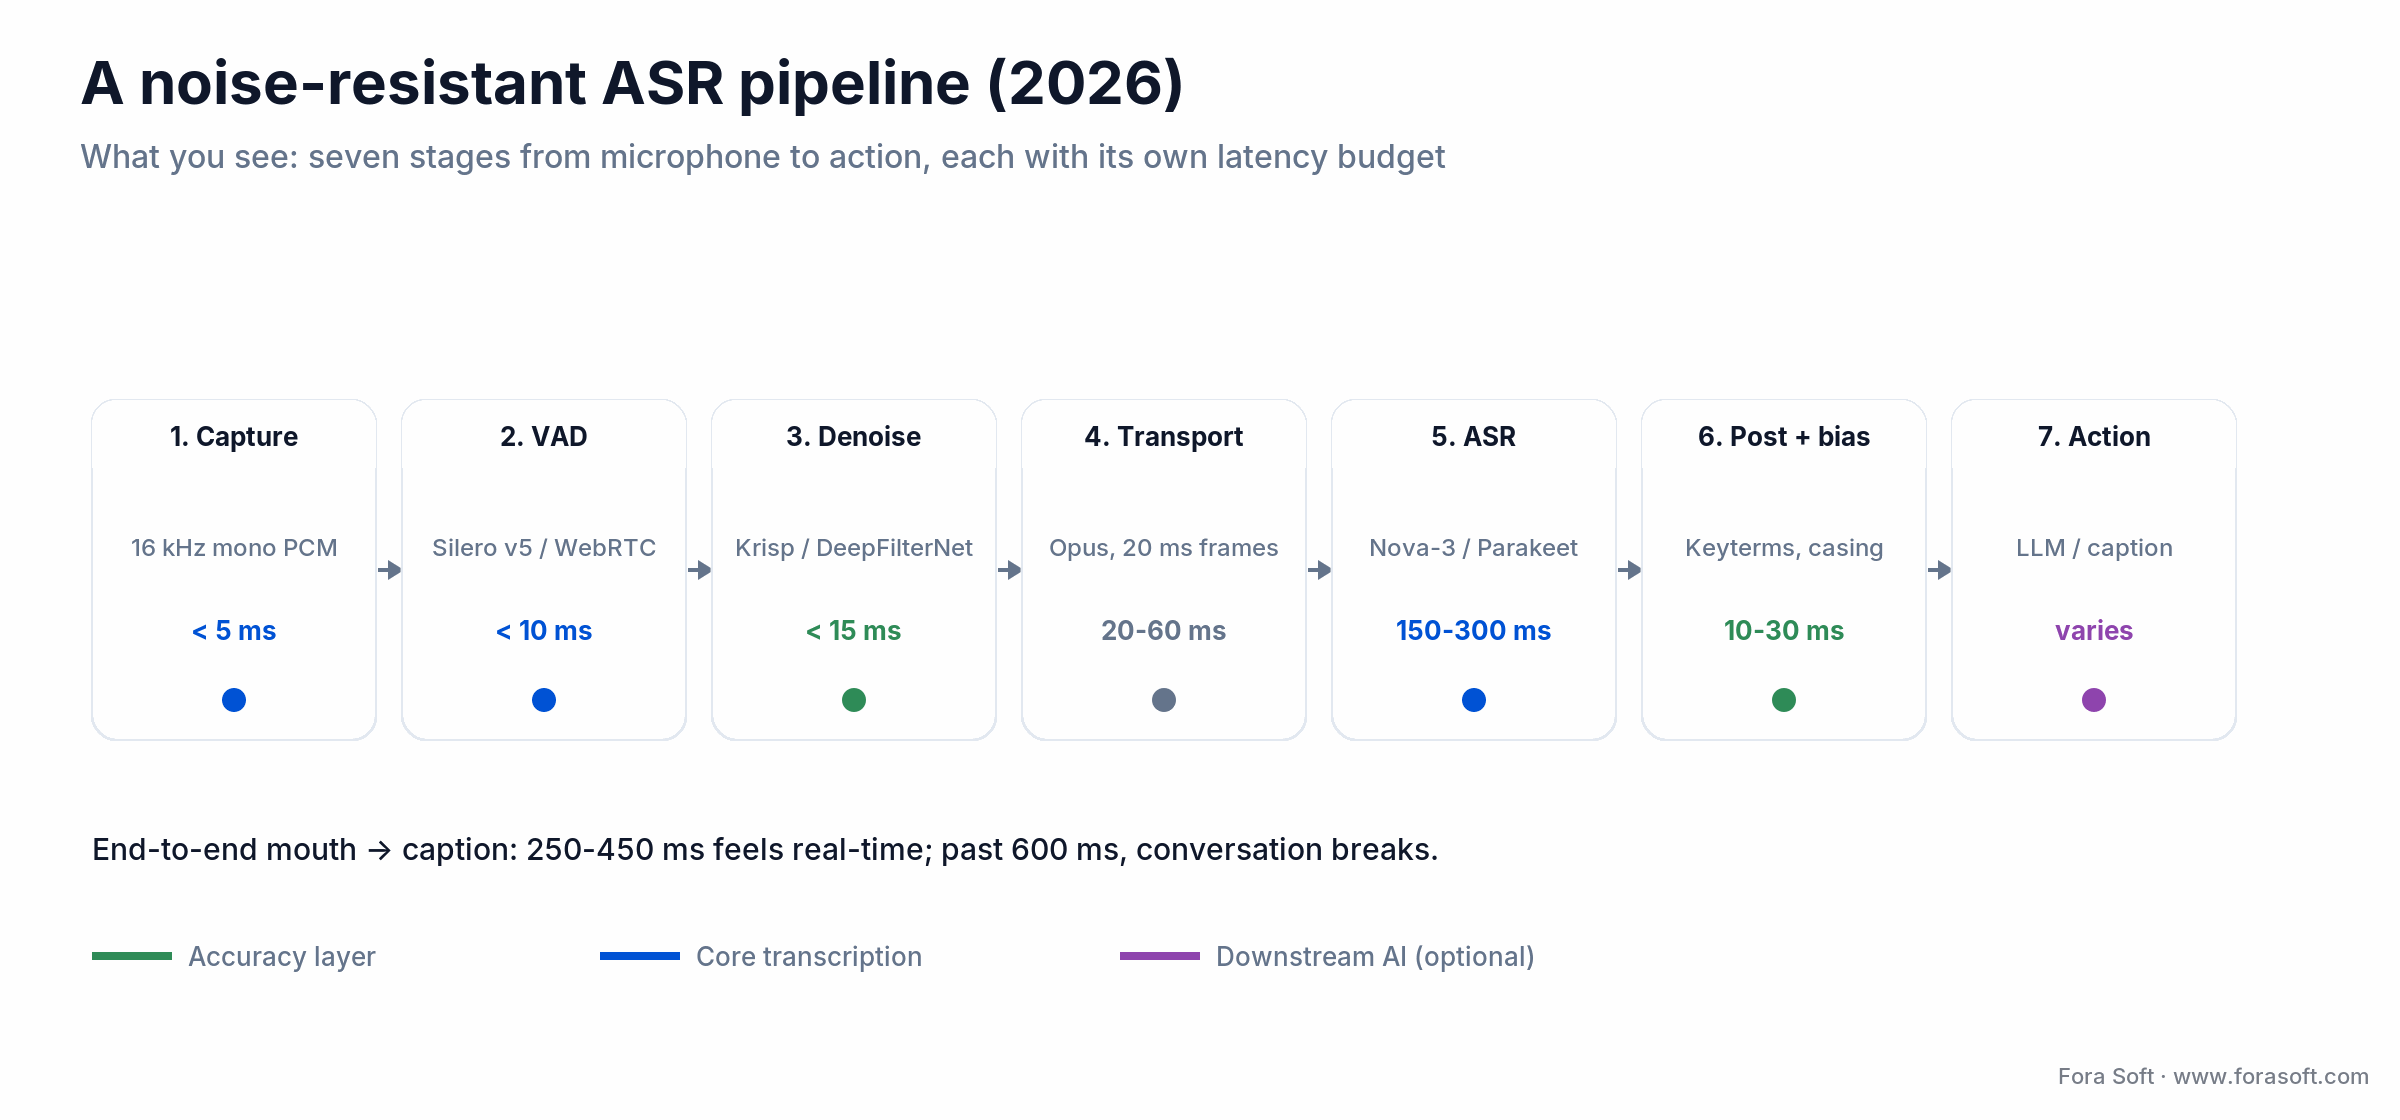
Figure 3. The seven stages from microphone to action, with a latency budget on each.
| Stage | Component | Latency budget |
|---|---|---|
| 1. Capture | 16 kHz mono PCM; AEC on whenever the device plays audio back | < 5 ms |
| 2. Voice Activity Detection | Silero VAD v6 (16% fewer errors on noisy real-life audio than v5), or WebRTC VAD for simple cases | < 10 ms |
| 3. Noise suppression | Krisp SDK, NVIDIA Maxine, or DeepFilterNet v3 | < 15 ms |
| 4. Transport | WebSocket or WebRTC data channel, Opus, 20 ms frames | 20–60 ms |
| 5. ASR | Nova-3 / Riva Parakeet / Whisper Turbo with streaming endpointer | 150–300 ms |
| 6. Post-processing | Substitution for remaining vocabulary misses, punctuation, casing, numeric formatting (keyterms go into stage 5) | 10–30 ms |
| 7. Downstream LLM / action | Optional — intent classification, NER, voice agent, caption render | varies |
From mouth to rendered caption the pipeline takes 250–450 ms end to end, which people still perceive as real-time. Past 600 ms, conversational flow breaks.
For voice agents, the downstream LLM turns consume the most latency. We cover the full agent stack in our LiveKit multimodal agents guide, and the transport and ASR layer described here plugs straight into it. For the audio-engineering fundamentals underneath, our Audio for Video learning track walks through capture, codecs and processing.
The Hardware Layer: Microphones, Beamforming, Device Constraints
Noise suppression can only recover what the mic captured. If you control the hardware, small changes there bring large WER improvements:
Microphone placement. Distance from mouth to mic matters more than mic quality. A $5 boom mic 3 cm from the lips beats a $200 conference mic 2 m away.
Microphone arrays and beamforming. Two or more mics with known geometry let you steer the reception lobe toward the speaker. ReSpeaker, MiniDSP UMA-8 and most conference-room systems do this in hardware. In a fixed-position deployment (kiosk, vehicle, meeting room), beamforming is the cheapest 3–6 WER-point improvement you can get.
Sample rate. Use 16 kHz mono. Higher rates don’t help ASR, since most models downsample internally. Lower ones (8 kHz telephone audio) lose high-frequency content and add 3–5 WER points.
Acoustic echo cancellation. If the system plays audio back to the user (voice agent, video call), you need AEC or you’ll transcribe your own text-to-speech output. WebRTC’s AEC3 is excellent and free.
Reach for beamforming when: you control the hardware and the speaker sits in a known spot. Two mics plus AEC beat a bigger model on a single distant mic almost every time.
What We Learned Shipping ASR in Noisy Real-World Apps
One mini-case first, then the patterns. On a live-captions build for an events product, raw WER on the venue floor sat around 22%, with music under the speaker, a roaming presenter and a crowd. We put a music-aware front-end (Demucs source separation) ahead of the model, biased the model with the event’s speaker names and product terms, and rendered captions on a 300 ms delay. After a two-week iteration WER was down to about 9%, and the “the captions are wrong again” tickets stopped. Want a similar assessment of your audio?
Patterns that keep repeating across the deployments we’ve shipped:
Medical and telehealth platforms. Here clinical vocabulary breaks transcripts more often than noise does. Keyterm-bias the drug list, ICD codes, and procedure names, and bundle a provider-maintained lexicon. For pharma vocabulary, Deepgram’s Nova-3 Pharma (17 September 2026) reports 10.17% batch WER and 91.59% drug-name recognition on its own medical audio benchmark. For learning platforms like BrainCert, the same lexicon pattern applies to course-specific terminology.
Live-streaming captions. Music under speech is the hardest case. Suppressors strip harmonics, and models hallucinate lyrics. What works is a music-aware front-end paired with a model trained on music-contaminated audio. Whisper v3 handles this better than most commercial APIs.
Field-service and construction apps. Wind, machinery and PPE muffling won't go away. Spend on the hardware layer first (bone-conduction mics, directional headsets), then tune the software.
Multilingual meetings. Most ASR models break when a speaker switches language mid-sentence. Pick models with explicit multilingual training, such as Whisper or Canary. We covered the translation side of this in our real-time meeting translation comparison.
Voice agents / IVR replacement. Here low latency matters more than a small WER gain. Users prefer a system that is 200 ms faster with 1% higher WER over the reverse. Choose Nova-3, Flux or Riva streaming, and keep batch Whisper out of real-time paths. When the agent answers phone lines, the same stack sits inside our AI call agent development work, where Krisp-class suppression and keyterms account for most of the accuracy on noisy calls.
The Real 2026 Cost Math: Cloud API vs Self-Hosted
At low volume, cloud APIs always win. At high volume, self-hosted Whisper on your own GPUs comes out ahead. The crossover lands somewhere between roughly 1 and 10 million minutes per month, and the exact point depends on how busy your GPUs stay.
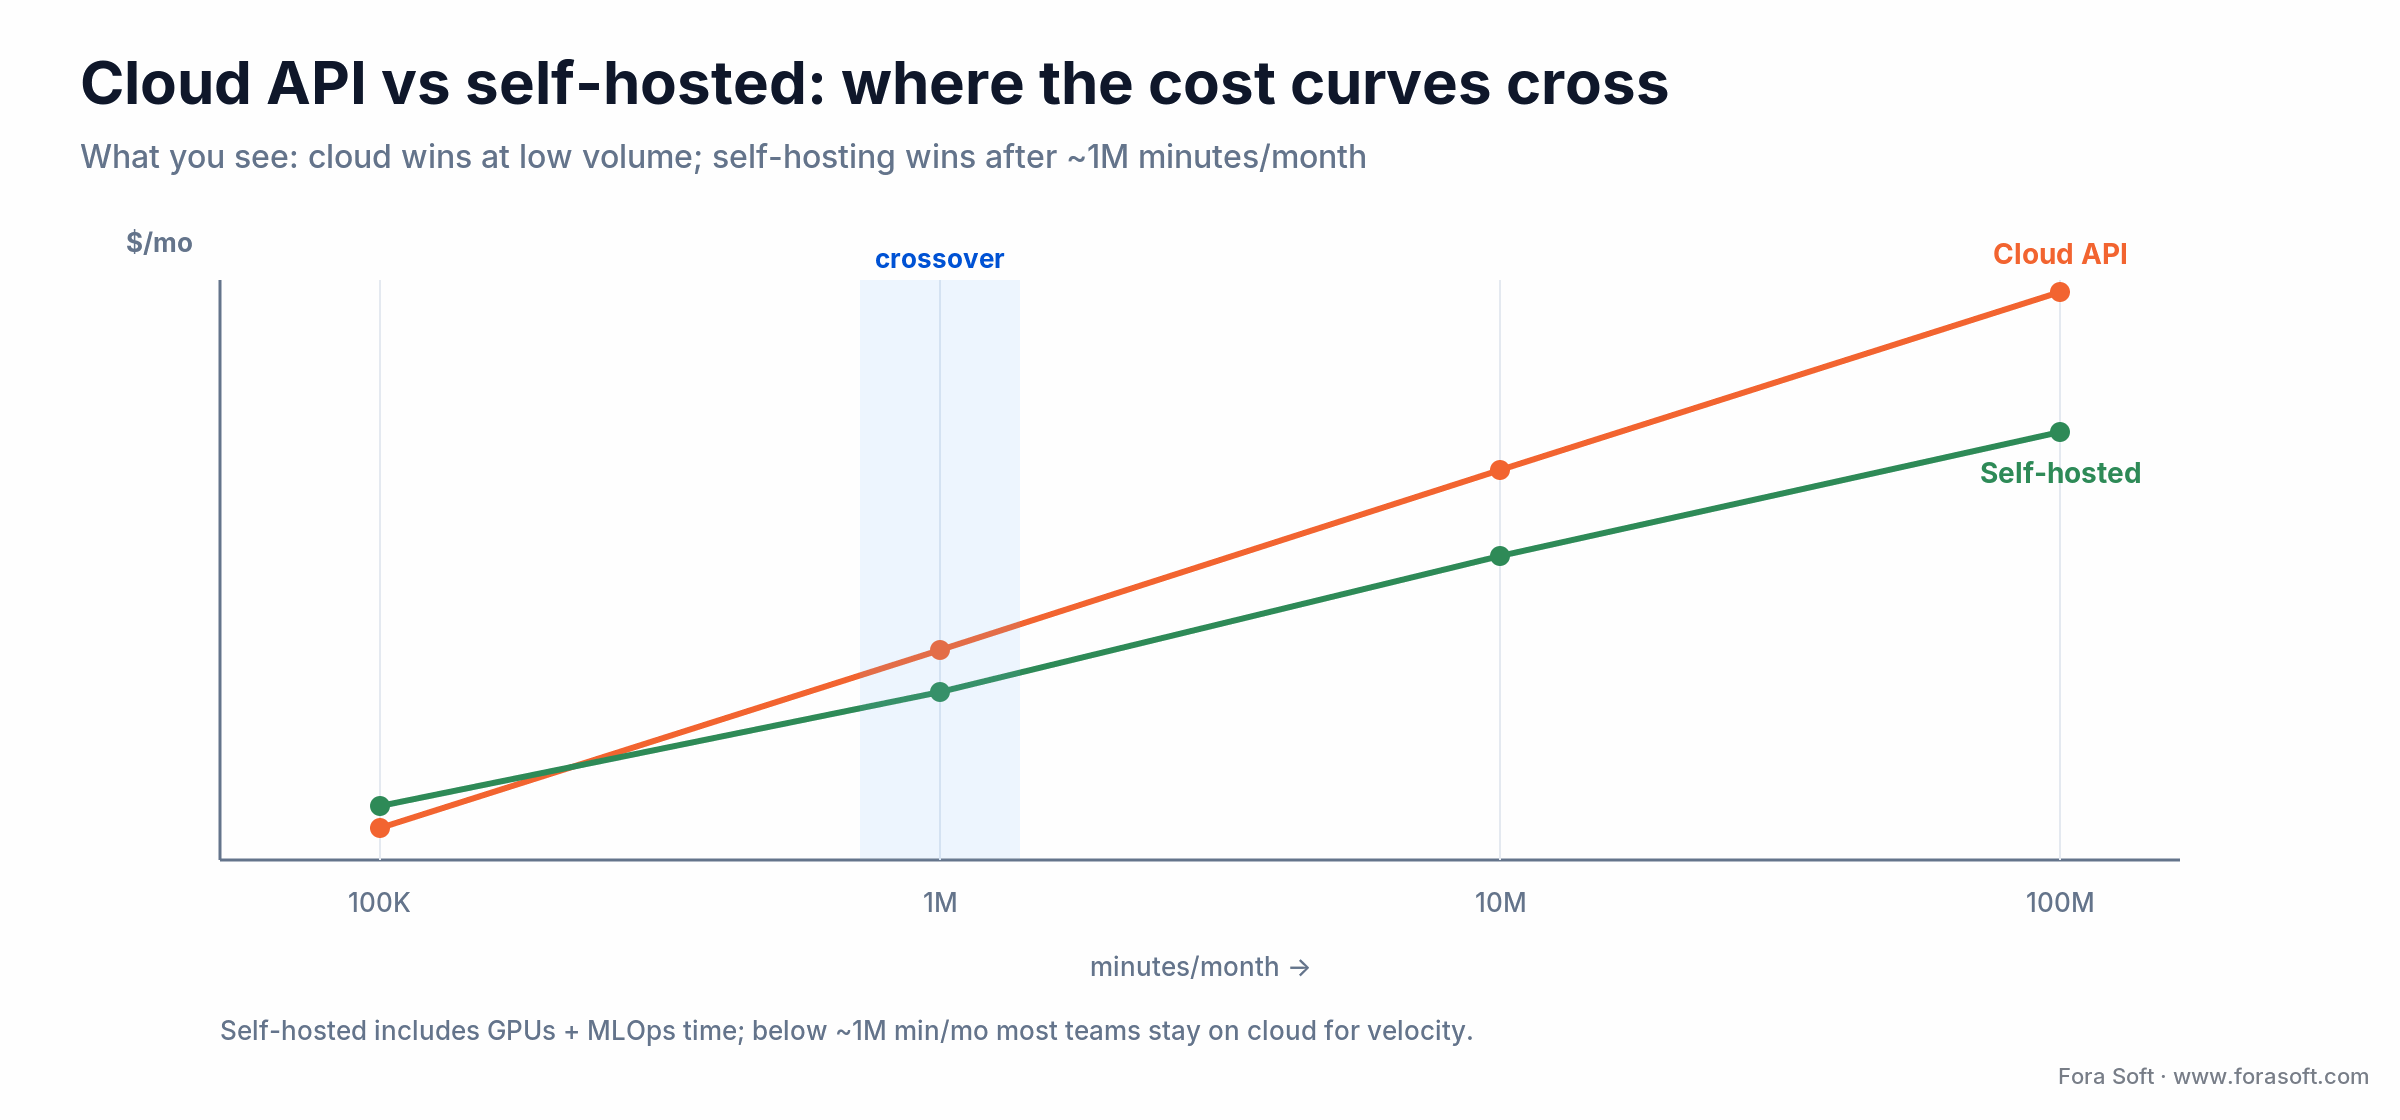
Figure 4. Cloud wins at low volume; self-hosting pulls ahead once GPUs stay busy.
| Volume (minutes/month) | Cloud API (Nova-3 streaming, ~$0.006/min blended, Oct 2026) | Self-hosted Whisper (L4/A10 GPUs) | Winner |
|---|---|---|---|
| 100,000 (small) | ~$600 | ~$800 (one GPU, under-used) | Cloud |
| 1,000,000 (mid) | ~$6,000 | ~$3,500 (2–3 GPUs) | Self-hosted |
| 10,000,000 (enterprise) | ~$60,000 | ~$15,000–25,000 | Self-hosted |
| 100,000,000 (hyperscale) | ~$600,000 | ~$80,000–120,000 | Self-hosted |
Worked example: 1,000,000 minutes/month on Nova-3 at $0.006/min is 1,000,000 × $0.006 = $6,000. Two L4 GPUs (roughly $1,000–1,400/mo on-demand) plus a slice of one MLOps engineer comes to about $3,500, but only if those GPUs stay busy. The self-hosted figures include GPU, MLOps time (spread) and observability. They leave out the opportunity cost of engineers not building something else. That is why most teams under 10M minutes/month stay on cloud even when the math tips. So ask which option unblocks product velocity, not only which one is cheaper.
Not sure whether to stay on a cloud API or self-host?
We’ll model your volume, latency, and compliance constraints and tell you where the crossover really sits for your workload, no upsell.
Build vs. Buy: When to Train Your Own Acoustic Model
In 2026, training a speech model from scratch is almost never the right call. Fine-tuning a frontier open-source model (Whisper, Canary, Parakeet) on domain data usually is. A custom model is justified only in a few cases:
• You operate in a language or dialect frontier models don’t cover well.
• Your environment is so far from mainstream that public models degrade unrecoverably (extreme industrial noise, custom radio channels, ultra-low-bandwidth telephony).
• You have a large labeled dataset (>1,000 hours) and the scale to amortize the MLOps burden.
• Regulatory or contractual constraints require model provenance you can prove end-to-end.
Everyone else should start with a frontier model plus the three strategies, measure WER, and put money into training only after hitting a clear floor. We’ve built both paths for clients, and the fine-tuning path reaches product-ready WER 5–10× faster than from-scratch training.
Evaluation: Measuring WER in the Conditions You Ship To
Vendor WER numbers come from benchmark conditions, and your users don’t live in LibriSpeech. Build an internal evaluation set that mirrors your production distribution: speaker demographics, noise profiles, device mix, vocabulary and accent spread. For statistically meaningful comparisons between candidate pipelines, 100–300 hand-labelled utterances is enough.
Measure the metrics your product actually depends on:
• WER: the classic metric, but segment it into clean, medium-noise, heavy-noise and accented.
• Keyterm recall: did the model get your critical vocabulary right? A 15% WER pipeline that nails every drug name beats a 10% WER pipeline that mangles them.
• Latency percentiles: p50, p95, p99. Tail latency is what breaks voice agents.
• Endpointing accuracy: false starts, truncated utterances, over-long pauses.
• Semantic correctness: for voice-agent / LLM pipelines, measure end-task accuracy on top of transcription accuracy.
Automate it. Each model update, pipeline change and fine-tune iteration should produce a WER report against the same reference set. Otherwise you’re guessing.
Privacy, Compliance, and the EU AI Act
Most jurisdictions treat speech as personal data, so handle it that way:
GDPR & HIPAA. If you process EU user voice or protected health information, the ASR vendor counts as a sub-processor. You need a DPA, a commitment on processing location and the right to delete. Deepgram, AssemblyAI, and NVIDIA sign HIPAA BAAs. Whisper on-prem avoids the vendor question but moves the burden onto your own security posture.
EU AI Act, the Digital Omnibus moved the dates. The Digital Omnibus, which received final Council approval on 29 June 2026, pushed high-risk obligations back. Standalone Annex III systems (workplace, education, law-enforcement and similar uses) now apply from 2 December 2027, and AI embedded in regulated products under Annex I (medical devices, machinery, vehicles) from 2 August 2028. The Article 50 transparency duties (telling people they’re interacting with or being recorded by AI) applied from 2 August 2026 as originally planned. The Omnibus only shortened the grace period for marking AI-generated content, which now ends on 2 December 2026. Transcription-only ASR usually falls outside high-risk. Once your pipeline infers speaker identity, demographics or emotion, you’re in Annex III territory and need the conformity paperwork.
Call-recording laws. Two-party-consent jurisdictions (California, Illinois, Germany) require explicit consent before recording and transcribing, so build the consent flow in from day one.
Data retention. Keep transcription storage short-lived by default and make longer retention opt-in. Never use customer audio for vendor model training without explicit opt-in. None of this is legal advice; run your deployment past counsel.
Comparison Matrix: Build, Buy, Hybrid, or Open-Source
A quick decision grid for the four typical 2026 paths. Pick the row that fits your team size, regulatory surface and time-to-value target, even if another row sounds more ambitious.
| Approach | Best for | Build effort | Time-to-value | Main risk |
|---|---|---|---|---|
| Buy off-the-shelf SaaS | Teams < 10 engineers, generic use case | Low (1–2 weeks) | 1–2 weeks | Vendor lock-in, customization limits |
| Hybrid (SaaS + custom layer) | Mid-market, mixed use cases | Medium (1–2 months) | 1–3 months | Integration debt, two systems to maintain |
| Build in-house (modern stack) | Enterprise, unique data or compliance | High (3–6 months) | 6–12 months | Engineering velocity, talent retention |
| Open-source self-hosted | Cost-sensitive, technical team | High (2–4 months) | 3–6 months | Operational burden, security patching |
A Decision Framework in Five Questions
These five answers narrow the stack down fast.
1. Real-time or batch? Live captions and voice agents need streaming, so Nova-3 or Riva Parakeet. Recorded media can run on batch Whisper and save most of the cost.
2. How noisy, really? Measure signal-to-noise ratio on real recordings. Above ~20 dB SNR, a good model plus VAD is enough. Below 15 dB, you need the full three-layer stack.
3. How specialized is the vocabulary? If it overlaps >90% with general English, an off-the-shelf model with keyterm biasing wins. For dense clinical, legal or industrial jargon, budget for a LoRA fine-tune.
4. What’s your compliance surface? PHI, EU voice data or an on-prem-only requirement pushes you toward Whisper or Riva on your own infrastructure, with a signed BAA or full self-hosting.
5. What’s your monthly volume? Under ~1M minutes/month, stay on a cloud API for velocity. Above that, with steady load, self-hosting starts to pay off. If two of these answers point in opposite directions, that trade-off is what we work through on a scoping call.
Five Pitfalls That Wreck Noisy-Environment ASR
1. Benchmarking on the wrong audio. A team picks a model on LibriSpeech numbers and then finds production WER is double. Evaluate on your own recordings before you commit.
2. Skipping the front-end. Teams reach for a bigger, pricier model when a low-cost neural suppressor would have delivered most of the gain for a fraction of the effort.
3. Double-denoising. Running your own suppressor on top of aggressive Bluetooth or OS denoising strips phonemes twice and hurts WER. Test with native denoising both on and off.
4. Ignoring the tail. Teams optimize median WER while p99 latency quietly ruins the voice-agent experience for one user in a hundred. Watch percentiles, because averages hide the tail.
5. Fine-tuning before biasing. Teams spend GPU budget on a fine-tune when a 20-minute keyterm list would have fixed the errors that actually mattered. Try the free fix first.
The KPIs to Track Before and After Shipping
Base every noisy-ASR decision on outcome metrics and ignore vanity counters. We track three buckets.
Quality KPIs. Segmented WER (clean / noisy / accented), keyterm recall on your critical vocabulary, and endpointing accuracy. Take a hard WER ceiling for each scenario from the benchmark table and raise an alert when a release crosses it.
Business KPIs. Task-completion rate for voice agents, caption-complaint tickets per 1,000 sessions, and cost per transcribed minute. Attribute lift with a clean A/B test against a hold-out group. Most teams skip the hold-out and then can’t tell whether the gain is real.
Reliability KPIs. Latency at p95 and p99, streaming disconnect rate, and how often the fallback path fires when the primary model times out. If a voice product is accurate but sometimes 3 seconds late, users still experience it as broken.
When NOT to Build Noise-Hardened ASR
There are cases where this whole effort is the wrong call, and we’d rather name them than oversell.
If your users always sit in a quiet room (a dictation app for home offices, a podcast-editing tool), a single frontier model out of the box will clear 7–10% WER, and the front-end and fine-tune are wasted engineering. At a few thousand minutes a month, skip self-hosting entirely: the cloud API costs less than the meeting you’d hold to discuss GPUs. If your product only needs short command recognition (“play,” “next,” “call Mom”), on-device keyword spotting beats a full ASR pipeline on latency, cost, and privacy.
If accuracy is truly life-critical, as with safety commands or legal records of the exact words, no 2026 ASR is good enough to run unsupervised. Keep a human in the loop and use ASR to make that person faster.
Our Track Record Shipping Speech Recognition
Fora Soft has integrated ASR into real-time communication and AI products since the pre-WebRTC era. Since 2005 we’ve shipped 250+ products across video, audio, and AI, and many of them include speech recognition. Some examples:
• TransLinguist, the video interpretation platform we developed, with live closed captions on the speech-to-text layer we built.
• BlaBlaPlay, voice processing wired into real-time communication, handling accented speech in noisy user environments.
• Medical and clinical platforms, vocabulary-sensitive ASR with HIPAA-grade data handling and custom pronunciation lexicons.
• Education and e-learning systems including BrainCert, live captions for virtual classrooms across varied mic and bandwidth conditions.
• Live-streaming and broadcast tools, real-time caption overlays for events and sports, where noise and music are always part of the audio.
Our engineers have shipped on every major ASR platform: Deepgram, Whisper, Google Speech-to-Text, Azure Speech, AWS Transcribe, NVIDIA Riva and Vosk. We have opinions about which one fits which job. Every real-time team includes an AI/ML specialist, so the three-layer architecture in this guide is what we actually deploy.
FAQ
What WER is realistic for my product?
Map your deployment to the benchmark table. Clean and quiet: 5–10%. Office or meeting: 10–14%. Call center: 12–16%. In-vehicle or retail: 14–20%. Industrial or clinical: 16–24%. Results below those ranges usually mean you’ve stacked all three strategies; results above them mean at least one is missing.
Do I still need noise suppression with Whisper or Nova-3?
In most noisy settings, yes. Frontier models handle moderate noise, but in truly loud conditions a Krisp- or DeepFilterNet-class front-end still buys a 20–40% relative WER improvement. In 2026 it’s the single highest-impact addition you can make to an existing pipeline.
Should I pick Deepgram, Whisper, or Riva?
Deepgram Nova-3 for real-time streaming SaaS where latency and ease of integration matter. Whisper Large v3 Turbo for offline, batch, or privacy-sensitive workloads, or when you need an open-source backbone to fine-tune. NVIDIA Riva (Parakeet, Canary-Qwen) for on-prem, regulated, or leaderboard-WER-critical deployments that already run on NVIDIA hardware.
How much labeled data do I need to fine-tune?
For a LoRA adapter on Whisper or Canary, 20–100 hours of labeled domain audio typically recovers 3–8 WER points. Full fine-tuning needs 200–1,000 hours to pay off. Below 10 hours, keyterm biasing and prompt engineering usually beat training.
Can I run speech recognition fully on-device?
Yes, and in 2026 it’s an increasingly attractive option. Whisper.cpp int4, Vosk, and on-device Parakeet variants deliver 12–18% WER on mid-range phones. Core ML Speech and Android’s on-device STT work well for short commands. On-device wins on privacy and offline support, while cloud still leads on accuracy, language coverage, and diarization.
How do I handle accents and non-native speakers?
Pick multilingual-trained models (Whisper, Canary) whose training data covers your target accents, and add accent-specific fine-tuning where accuracy is critical. If your user base is global, avoid US-English-only models: they add 3–8 WER points on accented speech.
Is speaker ID or voice biometrics safe to build in 2026?
Biometric identification counts as high-risk under the EU AI Act and is increasingly regulated in the US. Build it only with explicit consent, a narrow stated purpose, and legal review. Speaker diarization (“speaker A” vs “speaker B” without naming anyone) carries lower risk and can be deployed widely.
Which speech recognition API has the lowest word error rate on noisy audio?
On the 13 November 2026 Open ASR Leaderboard, the lowest WER on noisy, reverberant speech (URGENT24) belongs to Zoom’s Scribe API Pro model at 6.63%, and the top hosted APIs score about 6% on real meeting audio (AMI). Among the open models in our table, NVIDIA Nemotron 3.5 Transcribe leads on AMI at 7.78%. Deepgram does not submit to that leaderboard, so test Nova-3 on your own recordings alongside them.
How do I ensure accurate transcription in a noisy environment?
Put the microphone close to the speaker, record 16 kHz mono, run a neural suppressor (Krisp, NVIDIA Maxine or DeepFilterNet) before the model, use a model trained on noisy speech, and pass your key vocabulary as keyterms. Then measure WER on 100–300 of your own noisy clips before and after every change.
How does Deepgram handle background noise and different accents?
Nova-3 copes with moderate noise and common accents. Deepgram reports 6.84% streaming median WER on its own multi-domain set (2025), and on noisy call-center audio we see 11–15%. For loud environments, add a suppressor and keyterms; when speakers switch languages mid-sentence, use Nova-3 Multilingual.
Which SDK works for speech enhancement in real-time communication?
Krisp’s SDK (Voice Isolation 2.5, CPU, 15 ms latency) is the most common commercial choice. NVIDIA Maxine Audio Effects suits GPU servers, and RNNoise and DeepFilterNet are free open-source options. In WebRTC apps, pair any of them with the built-in AEC3 echo canceller.
Can Deepgram filter out non-speech sounds like music or static?
Partly. Nova-3 returns words, with no sound labels, so in our tests steady static and instrumental music mostly drop out of the transcript. Sung lyrics, TV audio and nearby talkers can still get transcribed as speech. For music-heavy or crowded audio, put a suppressor or source separation (Krisp, DeepFilterNet, Demucs) in front and keep keyterms for the words that matter.
How do translation tools work in noisy environments?
Speech translation runs speech recognition first, so every word the ASR layer mishears in noise turns into a translation error. The same three layers apply: suppress noise before recognition, use a model trained on noisy speech, and pass names and terms as keyterms. We compare how the main platforms handle this in our comparison of meeting translation platforms.
How long does it take to ship a noise-hardened ASR feature?
For a team that has done it before, integrating a cloud API end-to-end with noise suppression, keyterm biasing, and an evaluation suite takes 4–8 weeks. A self-hosted pipeline with custom fine-tuning takes 3–6 months. For budget ranges, see our software estimating guide.
What to Read Next
Voice agents
Multimodal AI Agents with LiveKit
How ASR slots into a production voice-agent stack at sub-500 ms end-to-end latency.
iOS
iOS Speech Recognition in 2026
SpeechAnalyzer, WhisperKit, and the full on-device iOS playbook.
Live streaming
Speech-to-Text for Live Streaming
Captioning audio with music, crowd noise, and variable bandwidth.
Translation
Real-Time Meeting Translation Platforms
The ASR layer that feeds the top translation platforms, compared.
Vendors
Top AI Speech Recognition Software in 2026
The vendor landscape and a decision matrix for picking a provider.
Ready to Ship ASR That Works in the Real World?
Speech recognition accuracy in noise has no single knob. A better model can’t fix audio that was broken before it arrived, and a denoiser can’t teach the model your vocabulary. The three strategies (neural front-end, noise-hardened model, domain biasing) cover different failures, and together they close the gap between benchmark WER and production WER.
If you’re picking a stack for real-time voice, streaming captions, call-center analytics, or a voice agent, the default 2026 answer for cloud is Krisp + Deepgram Nova-3 + keyterm biasing. For self-hosted, it’s DeepFilterNet + Whisper Large v3 Turbo + a LoRA fine-tune. Start there, measure WER on your own audio, and iterate.
If you’d rather work with a partner who has shipped this stack dozens of times, talk to us. Fora Soft builds real-time, AI-integrated apps for clients who need ASR to hold up in the field as well as in the demo.
The book · Volume 6 of 7
AI for Video: A Complete Guide to Intelligence in Video Products: From Models and Inference to Computer Vision, Speech, Search, and Generative Video
A noise-hardened front end buys accuracy, but the model and the way you evaluate it decide what reaches users. This volume treats speech as part of a full AI product: ASR, TTS and diarization, the AI feature lifecycle from prototype to production, deployment topologies and the ML basics behind model choice, for teams turning a WER benchmark into a shipped feature. Written by Nikolay Sapunov, CEO at Fora Soft.
Read it on Amazon →Kindle & paperback · Fora Soft Video Engineering Handbook
Need a domain-tuned STT stack that clears your WER bar?
Our speech team scopes the front-end, the model choice, the biasing list, and the evaluation set — then builds it. Book a call and bring a sample of your worst audio.

