


AI quality assurance isn’t “AI test automation.” Test automation is one slice of it. The 2026 QA stack spans defect prediction, risk-based test selection, AI code review, performance and security testing, accessibility, synthetic test data, chaos engineering, and shift-right observability — nine layers that together decide whether your team ships at DORA-elite velocity or leaks defects to production. This is the buyer’s playbook we use at Fora Soft with engineering leaders assembling that stack.
Key takeaways
- AI QA is a nine-category stack, not just AI test automation. Skipping a layer is where production escapes come from.
- A 50-engineer org running the full stack spends roughly $244k–$498k/year — about $4.9k–$10k per engineer, at October 2026 list prices.
- Gartner renamed the category in 2026: its Magic Quadrant for Agentic Software Quality Assurance Platforms (6 October 2026) names Keysight, TestMu AI (formerly LambdaTest), Tricentis and UiPath as Leaders.
- EU AI Act QA duties live in Article 12 (logging) and Article 11 (documentation); high-risk Annex III obligations start 2 December 2027 under the Digital Omnibus, Regulation (EU) 2026/1744, in force since 27 July 2026.
- Benchmark against the DORA 2024 elite band (change failure rate around 5%, recovery under 1 hour). DORA’s 2025 report found about 90% of respondents use AI and that AI adoption is still associated with more delivery instability — the gap QA has to close.
Updated October 2026: Gartner’s new Agentic Software QA Magic Quadrant, EU AI Act Omnibus (Regulation 2026/1744) dates, DORA 2025 and METR 2026 findings, re-checked vendor prices.
Why Fora Soft wrote this playbook
We’ve shipped production software since 2005 — 250+ projects, a 50-person team, and platforms like VALT that run for 770+ organizations and 50,000+ active users. QA failure modes at that scale are specific: you don’t just need flaky-test reduction, you need defect prediction wired to your deploy graph, observability tied to your test history, and chaos engineering that probes the failure modes your synthetic tests never reach. If you want the deeper engineering context, our AI engineering track on /learn walks through how we build and validate production ML systems. Teams that want a baseline before buying tools can start with our code quality audit, which reports each issue with the exact file, line and fix.
Our companion piece on AI-driven testing covers the test-automation slice in depth (mabl, Testim, Diffblue, Applitools). This guide covers the other eight layers — the ones that decide whether test automation actually prevents production incidents or just burns CI minutes. For how our own testers work day to day, see how the Fora Soft QA team tests real-time products.
What is AI quality assurance?
AI quality assurance is the use of machine learning and LLM agents across the software QA lifecycle — predicting risky commits, choosing which tests to run, reviewing code, generating test data and watching production — so defects are caught before users find them. In 2026 it is a nine-layer stack rather than one tool, and each layer has its own vendor category; skipping any of them is where escape rates come from.
- Defect prediction — ML models correlate code metadata (churn, complexity, author history) with historical failures to flag risky commits before they ship.
- Risk-based test prioritization — run the subset of tests most likely to fail on this change first and defer the rest to nightly, so CI time stops growing with the suite.
- AI code review / static analysis — SonarQube, Snyk Code, and Checkmarx use pattern matching plus LLM assist to catch bugs and security issues human review misses.
- Performance testing — AI generates load profiles and detects regressions (k6, BlazeMeter, LoadRunner Cloud).
- Security testing — AI-driven SAST, DAST, and IaC scanning (Snyk, Checkmarx, GitHub Code Security with Copilot Autofix).
- Accessibility testing — computer vision and LLM tools (Evinced, axe DevTools) catch WCAG failures traditional scanners miss.
- Test data management — Tonic.ai, Gretel, and Mostly AI generate production-grade synthetic data without PII leakage.
- Observability-driven QA — Datadog Watchdog, New Relic AI, and Splunk AI detect anomalies in production before users do.
- Chaos engineering — Gremlin, Chaos Mesh, and LitmusChaos inject failures to validate resilience under real-world conditions.
Two other things travel under the same name. QA of AI systems means testing the model itself — evaluation sets, drift, bias and the logging the EU AI Act asks of high-risk systems; we cover that in the compliance section below. AI QA scoring in contact centers means software that scores every customer call against a checklist; vendors such as Convin describe manual programs that review only 2–5% of calls, which is why 100% automated scoring raises coverage. This guide is about the first meaning: AI that assures the quality of software you ship.
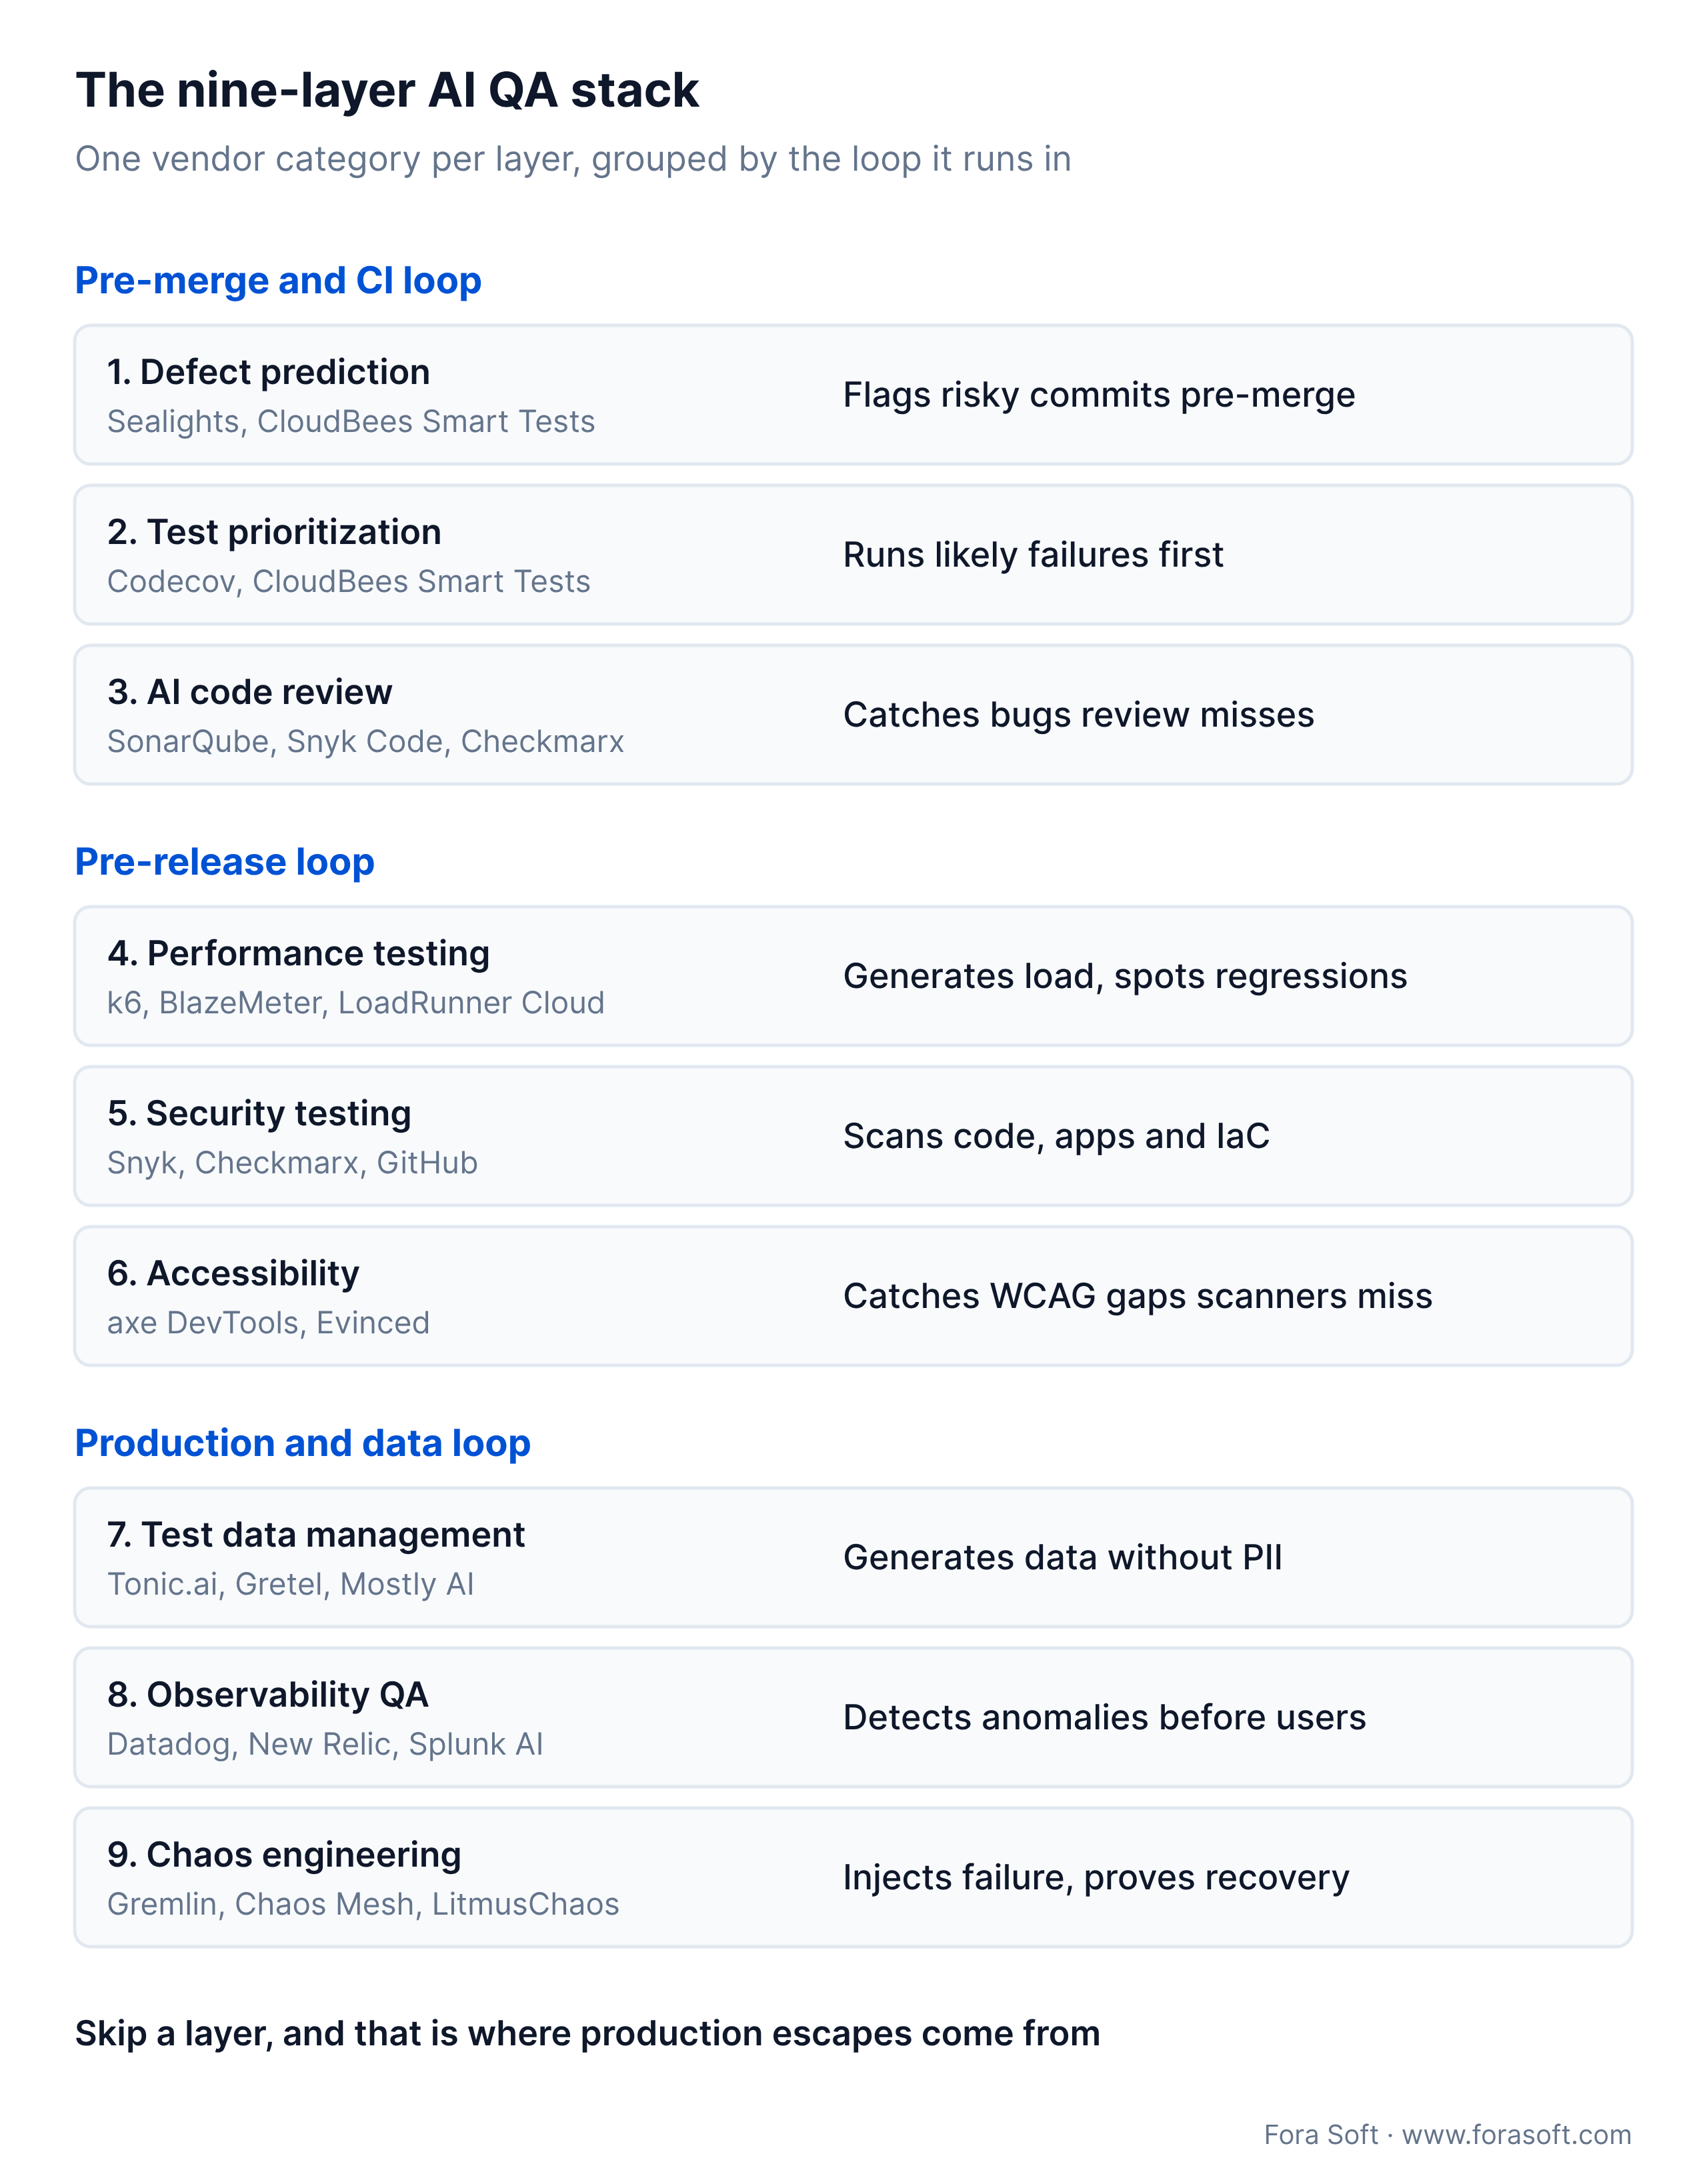
Figure 1. The nine vendor categories in a 2026 AI QA stack, grouped by where each runs: pre-merge and CI, pre-release, and production.
Reach for the full stack when a single production incident costs more than a year of tooling. If you’re pre-revenue or shipping less than one deploy a day, buy two layers (code review + security) and revisit. The stack earns its keep on scale and blast radius, not on headcount.
Market snapshot — size, growth, adoption
The Business Research Company (February 2026) sizes the AI-enabled testing market at $1.04 billion in 2026, up from $0.85 billion in 2025, and forecasts $2.04 billion by 2030 at an 18.4% CAGR (report summary). Treat any single figure as an estimate — the direction is what matters.
The category hit an inflection in late 2025, when Gartner published its first Magic Quadrant for AI-Augmented Software Testing Tools (6 October 2025), named Tricentis, Keysight, OpenText and UiPath as Leaders, and projected that 70% of enterprises would integrate AI-augmented testing by 2028, up from 20% in early 2025. One year later Gartner renamed the market. The 2026 Magic Quadrant for Agentic Software Quality Assurance Platforms (6 October 2026) evaluates 12 vendors and names Keysight, TestMu AI, Tricentis and UiPath as Leaders, with ACCELQ, Katalon, mabl, OpenText, Perforce, QyrusAI, Sauce Labs and SmartBear also placed (Automation Today, October 2026). Gartner’s framing: vendors have moved beyond AI-augmented tools to platforms with specialized agents. TestMu AI is LambdaTest, renamed in January 2026.
Why now? More code is being written by AI than review capacity can absorb. Google’s DORA 2025 report found about 90% of respondents use AI at work, up from roughly 75% in 2024, and that AI adoption now helps throughput but is still associated with higher delivery instability. More code at flat review capacity is exactly what a wider QA stack exists to absorb.
The nine AI QA vendor categories
Every mature QA stack in 2026 pulls from nine vendor categories. Here’s who leads each and what you pay.
Defect prediction. Sealights (Tricentis-owned) leads on code-level risk analysis with real-time predictive analytics. CloudBees Smart Tests (formerly Launchable, now owned by CloudBees) ranks tests by importance to code changes. Both quote-based; expect $40k–$80k/year for a 50-engineer org.
Risk-based test prioritization. Codecov (Sentry) is the volume option: the Team plan at $4–5 per user per month includes failed-test reporting, and flaky-test detection sits in Pro at $12 per user per month (Codecov pricing, October 2026). CloudBees Smart Tests predictive test selection and Sealights layer model-driven test selection on top.
AI code review. SonarQube prices self-hosted Server editions per instance per year by lines of code; the cloud Team plan starts at $34/month for teams under 50 developers, Enterprise is custom, and Sonar now sells Gitar AI Code Review at $20 per user per month alongside its remediation agents (Sonar pricing, October 2026). AI Code Assurance flags AI-generated code paths for stricter gates. Snyk Team starts at $25/month for up to 10 developers; larger orgs buy Enterprise credits, metered per active contributor per day. Checkmarx is quote-based and bundles SAST/SCA/DAST/IaC.
Performance testing. k6 / Grafana Cloud k6 starts at $0.15 per virtual-user hour on the Pro plan, with 500 VUh free per month and a $25k/year Enterprise minimum (Grafana pricing, October 2026) — the cloud-native default. BlazeMeter starts near $149/month. LoadRunner Cloud runs $50k+/year for enterprise deployments.
Security testing. Snyk and Checkmarx dominate. GitHub unbundled Advanced Security on 1 April 2025: GitHub Code Security (code scanning with Copilot Autofix) costs $30 and Secret Protection $19 per active committer per month (GitHub changelog) — hard to beat on integration cost if you already live in GitHub.
Accessibility testing. axe DevTools (free extension plus a paid tier with Intelligent Guided Tests). Evinced uses computer vision to catch what axe misses — proprietary pricing, CI/CD integrated.
Test data management. Tonic.ai prices by GB of source data; Tonic Textual by words processed. Gretel (acquired by NVIDIA in March 2025) and Mostly AI are direct competitors on privacy-first synthetic data.
Observability-driven QA. Datadog ties testing to observability through Watchdog anomaly detection and APM/RUM/log correlation. New Relic AI and Splunk AI (Cisco-owned) complete the big three.
Chaos engineering. Gremlin is quote-based for teams. Steadybit and AWS Fault Injection Service are the managed commercial options; LitmusChaos and Chaos Mesh are the open-source defaults.
Stuck picking vendors across nine categories?
We run a 60-minute architecture review on your current stack, CI/CD topology, and compliance exposure and return a tier-by-tier vendor recommendation the same day.
Comparison matrix — what you pay, what you get
| Category | Top vendor | 2026 price | 50-eng org/yr |
|---|---|---|---|
| Defect prediction | Sealights / CloudBees Smart Tests | Quote-based | $40k–$80k |
| Test prioritization | Codecov (Pro) | $4–$12/user/mo | ~$7k |
| AI code review | SonarQube Server Enterprise | LOC-based, custom | $32k–$96k |
| Performance testing | k6 / Grafana | $0.15/VU-hr | $25k–$50k |
| Security testing | Snyk | Credits per contributor/day | $35k–$50k |
| Accessibility | axe + Evinced | Free + custom | $15k–$30k |
| Test data mgmt | Tonic.ai | Volume-based | $25k–$40k |
| Observability QA | Datadog | Per-host/container | $50k–$120k |
| Chaos engineering | Gremlin | Quote-based | $15k–$25k |
| TOTAL | Full stack | $244k–$498k |
Reference architecture — six QA loops
A production AI QA program is six feedback loops operating in parallel, not a linear pipeline. Each loop has its own latency budget and its own AI tool category.
- Commit loop (seconds). SonarQube, Snyk Code, and GitHub Code Security scan the diff at PR time; AI Code Assurance flags Copilot output for extra scrutiny.
- CI loop (minutes). CloudBees Smart Tests and Sealights prioritize tests; Codecov tracks flakes; k6 runs smoke-performance tests on every merge.
- Staging loop (hours). Full regression, chaos experiments (Gremlin), accessibility audits (axe + Evinced), security DAST (Checkmarx/Snyk).
- Release loop (canary). Feature flags plus Datadog Watchdog correlate deploy metadata with user metrics; auto-rollback on anomaly.
- Production loop (continuous). Watchdog, New Relic AI, and Splunk AI detect anomalies in real user traffic; RUM ties back to test coverage gaps.
- Compliance loop (audit). EU AI Act Article 12 logging: every model version, test result, and deploy captured and retained for the system’s lifetime.

Figure 2. A production AI QA program is six parallel feedback loops — production signal feeds back into test selection and defect-prediction models.
Cost model — what a 50-engineer org actually spends
Mid-market reality: most orgs don’t buy all nine categories at once. They buy three, prove value, then expand. Typical sequencing:
Year 1 — foundation ($75k–$155k). SonarQube + Snyk + Codecov. Covers code review, security, and flaky-test tracking. Immediate cycle-time wins.
Year 2 — observability ($65k–$145k). Add Datadog + Gremlin. Now test results correlate with production incidents and chaos experiments validate recovery.
Year 3 — predictive + data ($105k–$200k). Add Sealights or CloudBees Smart Tests for defect prediction plus Tonic.ai for synthetic data. Accessibility (Evinced) and performance (k6) round out the stack.
Three-year all-in lands at $244k–$498k/year for a 50-engineer org — roughly $4.9k–$10k per engineer per year. Set that against one release that takes down production (the CrowdStrike case below) and the math answers itself.

Figure 3. A phased three-year budget for a 50-engineer org: buy three layers, prove value, then expand to the full stack.
Mini case — when automated QA fails: the CrowdStrike outage
On 19 July 2024 a CrowdStrike Falcon content update — a new version of Channel File 291 — crashed more than 8.5 million Windows machines worldwide, grounding flights and taking hospitals and banks offline. CrowdStrike’s root-cause analysis found that the new template type defined 21 input fields while the sensor code supplied only 20; no test covered that mismatch, and the update went to every sensor at once (Help Net Security summary of the RCA).
Root causes were textbook QA gaps, not exotic ones: tests that never exercised the new template against the field count the sensor actually supplied, a missing bounds check in the code that read it, and no staged rollout between the test artifact and production. CrowdStrike’s fixes map one-to-one onto layers of the stack in this guide — extra test cases for template inputs, bounds checks, staged deployment with canaries, and customer control over when content lands.
The lesson for AI-generated tests is direct: a pipeline can pass its own tests and still ship a crash. Once EU AI Act high-risk obligations apply, a provider that can’t produce Article 12 logs or Article 11 documentation for such an incident also faces a provider-obligation breach — up to €15M or 3% of global turnover. If you want a second set of eyes on where your own pipeline could do this, book a 30-minute review.
Reach for output validation when any test is machine-authored. AI amplifies errors at scale, so validation on AI-generated tests matters as much as input validation on production code. Feature flags and canary deploys aren’t optional for AI-driven changes — they’re the cheap insurance that turns a global outage into a rolled-back canary.
Compliance — EU AI Act, ISO 25010, IEC 62304, SOC 2
EU AI Act. The Act phases in by obligation. Prohibited-practice bans (Article 5) have applied since 2 February 2025. The high-risk obligations that hit most production AI were originally set for 2 August 2026, but the Digital Omnibus on AI — Regulation (EU) 2026/1744, published in the Official Journal on 24 July 2026 and in force since 27 July 2026 — pushed stand-alone Annex III systems to 2 December 2027 and AI embedded in regulated products (Annex I) to 2 August 2028. Article 50 transparency duties have applied since 2 August 2026. Two articles drive QA work: Article 12 requires high-risk systems to automatically log events across their lifetime, and Article 11 (with Annex IV) requires technical documentation you can hand an auditor. If you test high-risk systems on live traffic, Article 60 governs real-world testing outside sandboxes. Penalties top out at €35M or 7% of global turnover for prohibited practices, and €15M or 3% for other provider obligations.
ISO 25010. The foundational software-quality model — functionality, reliability, usability, performance, security, maintainability. Auditors now map AI QA controls (Sealights coverage, Snyk scans, Datadog observability) directly to these characteristics.
IEC 62304. Mandatory for FDA-regulated medical-device software. It requires documented architectural design, software validation, and unit/integration/system/acceptance testing. On healthtech builds like CirrusMED, IEC 62304 turns QA into a documentation discipline as much as a testing one — and ISO/IEC 5259 closes the AI/ML gap on training-data provenance.
SOC 2 Type II. 2026 auditors now scrutinize AI/ML-specific controls: data security on training sets, access logs on model retraining, change management on promoted models. AI-generated test data must meet the same confidentiality and integrity bar if it ever touches PII — which means your Tonic or Gretel vendor must itself be SOC 2 Type II certified.
Reach for compliance tooling first when you’re EU-facing or FDA-regulated. Article 12 logging and Article 11 documentation aren’t a reporting afterthought — they shape which vendors you can even use, because the log and the audit trail have to exist before the deadline, not after the first audit.
A decision framework — pick the stack in five questions
- Regulatory exposure. EU-facing or high-risk under the Act? Start with audit-trail tooling (Datadog + SonarQube + Checkmarx) before anything else.
- Current delivery performance. Near the DORA 2024 elite band (deploy daily, change failure rate around 5%)? You need predictive test selection to keep cycle time flat. Low performers start with defect prediction plus flaky-test analytics.
- AI-generated code share. Over 40% Copilot output? Non-negotiable: AI-code-path detection in SonarQube, tighter Snyk policies, and output-validation gates. If a large share of the codebase was generated in Cursor, Lovable or Bolt before any of this existed, our AI code cleanup team refactors it into something these gates can pass.
- Production observability maturity. No Datadog, New Relic, or Splunk today? Start there — without production signal, test results don’t correlate with anything meaningful.
- Team size. Under 20 engineers, buy. 20–150, buy plus adapt on top of platforms. 150+, build the differentiating AI tooling in-house on bought platforms.

Figure 4. Route by your biggest constraint first — regulatory exposure, observability, AI-code share, or DORA tier.
Reach for a two-layer pilot when you can’t get budget for the full stack yet. Pick the one loop where escapes hurt most — usually code review plus security — prove a cycle-time or escape-rate number in one quarter, then use that number to fund the next two layers. Nobody approves nine line items on faith.
Five pitfalls that kill AI QA rollouts
- Overreliance without governance. Teams wire up AI test generators without output validation — hallucinated tests pass and poison coverage metrics. Fix: mandatory human review, output-validation frameworks, and feature-flag gating on all AI-authored tests.
- Data-quality blind spot. Defect-prediction models trained on stale code miss novel failure modes. Fix: continuous data audits, synthetic-data validation, and model retraining on a 90-day cadence.
- Production validation failure. Coverage improves 40% in staging; production incident rate stays flat. Fix: shift-right observability, RUM plus test correlation, and chaos engineering on every major release.
- Velocity explosion without oversight. AI code generation pushes more PRs through faster and escape rate balloons if review can’t keep up. The catch: the volume goes up, but the speedup isn’t guaranteed — METR’s 2025 randomized trial found experienced developers were about 19% slower with AI on codebases they knew well; METR’s February 2026 update saw point estimates swing to a 4–18% speedup in late 2025, but METR itself calls that very weak evidence. Assume more code, not proven faster delivery. Fix: enforce defect-escape-rate SLOs (under 5%) and a change failure rate near the DORA 2024 elite band (around 5%).
- No security on AI-written tests. AI-generated tests often skip injection, auth-bypass, and API fuzzing. Fix: mandatory SAST on test code, chaos injections, and accessibility gates in CI.
KPIs — what to measure on day one
- Defect escape rate — target under 5% (defects reaching prod divided by total defects found).
- Mean time to detect (MTTD) — under 4 hours in dev, under 1 day in prod.
- Test coverage efficiency — over 85% of requirements covered, not just lines.
- Production incident rate — under 0.1 per 10k transactions.
- MTTR (mean time to recovery) — under 1 hour (DORA 2024 elite), under 4 hours (good).
- Change failure rate (DORA) — around 5% at the DORA 2024 elite band; low performers sat near 40%. DORA 2025 dropped the four tiers for seven team archetypes, so treat these as benchmarks, not a current ranking.
- Code review cycle time — under 24 hours from PR to merge.
- Test flakiness — under 2% of tests showing intermittent failures.
- AI-generated code defect ratio — under 1.5× the human-written defect rate.
- Compliance gap coverage — 100% of Article 12 logging and Article 11 documentation checks automated.
Industries shipping real value in 2026
Fintech. Fraud detection, transaction risk scoring, compliance monitoring. Common stack: Snyk + Sealights + Datadog. Most fintech orgs now test AI scoring models before production.
Healthtech. Diagnostic AI validation, FDA software testing, IEC 62304 regression. Common stack: SonarQube + Checkmarx + Tonic.ai. Regulatory pressure is driving adoption ahead of tightening FDA expectations.
Automotive / ADAS. Autonomous-vehicle testing, sensor-fusion validation, ISO 26262 safety-critical regression. Common stack: LoadRunner + Gremlin + axe for in-vehicle HMI accessibility.
E-commerce. Recommendation-engine testing, UX optimization, fraud prevention. Common stack: Evinced + BlazeMeter + Datadog. Accessibility exposure (per-violation fines) drives axe/Evinced adoption. Our companion guide on AI content recommendation systems covers how those engines get tested.
SaaS. Multi-tenant performance, feature-flag validation, API reliability. Common stack: k6 + Launchable + Codecov.
Build vs buy vs adapt
2026 reframed “build vs buy” as “own vs orchestrate.” Three patterns emerge:
Buy systems-of-record: defect tracking, compliance workflows, SAST, APM. 3–6 month ROI; vendor lock-in is acceptable in exchange for time-to-value.
Build the differentiating layer: AI copilots tailored to your domain (WebRTC quality heuristics, model-drift detection), agentic test generation, internal workflow automation. 18–36 month runway; real hiring risk. This domain layer is what our AI integration team builds for clients who would rather not hire for it.
Adapt (platform). Buy core platforms, customize the experience layer — Snyk for SAST plus internal Slack integration plus custom policy rules on top. 6–12 month ROI; dual maintenance is the main cost.
A cautionary data point: S&P Global’s 2025 enterprise-AI survey found the share of companies abandoning most of their AI initiatives jumped from 17% to 42%, with about 46% of proofs-of-concept scrapped before production. Success depends on picking the right pattern per initiative, not org-wide.
When not to adopt AI QA (yet)
- No CI/CD. AI QA tools assume a pipeline to wire into. Fix the pipeline first.
- Team under 10 engineers. Cost of ownership exceeds benefit until you’re shipping more than one deploy a day.
- No production observability. Without Datadog, New Relic, or Splunk signal, test results have no real-world validation.
- No compliance pressure and no scale. Not EU-facing and not processing PII? You can delay the Act-specific tooling.
A 12-week deployment playbook
Weeks 1–3 — foundation. Audit the existing test suite; baseline defect escape rate, coverage, and cycle time. Pick 2–3 pilot tools (typically Codecov + Sealights or k6 + Datadog). Integrate with CI/CD, configure alerting, train two engineers per tool. Deliverable: live DORA dashboards.
Weeks 4–8 — pilot. Deploy risk-based test prioritization on one service; measure cycle-time reduction. Add defect prediction; correlate predicted risks with actual escapes. Retro at week 8; target 20%+ cycle-time reduction and under 5% escape rate.
Weeks 9–12 — expansion. Add security (Snyk) and accessibility (axe); scan the whole codebase. Integrate observability (Datadog) with test results. Run a chaos mini-pilot on staging (Gremlin). Exit: escape rate under 5%, change failure rate at the elite band, coverage efficiency over 85%, MTTR under 1 hour, and a working Article 12 logging trail.
Need a 12-week plan customized to your stack?
We deliver a fixed-scope QA rollout: vendor picks, integration sequencing, KPI targets, and weekly checkpoints, tuned to your team size and compliance exposure.
Key takeaways
- AI QA is a nine-category stack, not just AI test automation.
- Budget $244k–$498k/year for a 50-engineer org running the full stack.
- EU AI Act QA duties are Article 12 (logging) and Article 11 (documentation); high-risk Annex III obligations start 2 December 2027 under Regulation (EU) 2026/1744.
- Gartner’s 2026 Magic Quadrant renamed the market to Agentic Software Quality Assurance Platforms; Keysight, TestMu AI, Tricentis and UiPath are Leaders.
- Benchmark against DORA 2024 elite: change failure rate around 5%, recovery under 1 hour, deploy on demand; keep defect escape rate under 5%.
- Buy systems-of-record, build the differentiating layer, adapt on top of purchased platforms.
- 42% of enterprises abandoned most AI initiatives in 2025 (S&P Global) — pattern selection matters more than tool selection.
FAQ
What is AI quality assurance?
AI quality assurance is the use of machine learning and LLM agents across software QA — defect prediction, test selection, code review, security and performance testing, test data, production observability and chaos engineering — so defects are caught before release. It is a nine-layer stack, not a single tool.
How is AI in QA different from AI test automation?
AI test automation (mabl, Testim, Applitools) is one of nine QA categories. AI quality assurance also covers defect prediction, risk-based prioritization, AI code review, performance, security, accessibility, test data, observability, and chaos engineering. Our AI-driven testing guide covers the automation slice; this guide covers the other eight layers.
What does the EU AI Act require from QA teams?
Article 12 requires high-risk systems to automatically log events across their lifetime, and Article 11 (with Annex IV) requires technical documentation. High-risk Annex III obligations start 2 December 2027 under the Digital Omnibus, Regulation (EU) 2026/1744 (Annex I products, 2 August 2028). Non-compliance runs to €15M or 3% of turnover; prohibited practices, €35M or 7%.
Where should a 50-engineer org start?
SonarQube + Snyk + Codecov for year one ($75k–$155k). Add Datadog + Gremlin in year two. Defer predictive and test-data tooling to year three unless compliance forces it sooner.
Do AI tools really reduce escape rate?
Yes, when governance holds, but measure it yourself: vendor case studies report escape-rate drops, and the numbers are vendor-reported. Baseline your escape rate before the pilot and compare after one quarter. Without output validation and staged rollouts, automation can raise risk — see the CrowdStrike case above.
What’s the DORA elite benchmark in 2026?
The last published elite band is from DORA 2024: deploy on demand, lead time under 1 day, recovery under 1 hour, change failure rate around 5%. The 2025 DORA report replaced tiers with seven team archetypes, so use the 2024 numbers as targets and track your own trend.
Can we skip chaos engineering?
Only if your SLO commitments don’t require validated recovery time. With five-nines commitments or ISO 26262 exposure, Gremlin or an equivalent is mandatory, not optional.
How do we validate AI-generated tests?
Three gates: human review on all AI-authored tests merged to trunk; an output-validation framework that rejects tests asserting implausible invariants; and feature-flag gating so any AI-authored test path can be toggled off in under 30 seconds.
Is Codecov cheaper than Checkmarx?
Almost always: Codecov publishes $4–$12 per user per month in 2026, while Checkmarx sells quote-based enterprise contracts for its SAST/SCA/DAST suite. They do different jobs — Codecov tracks coverage and flaky tests, Checkmarx finds security flaws — so most teams need both kinds of tool, not one instead of the other.
When is AI QA a good fit for large or critical software projects?
When one bad release costs more than a year of tooling: regulated products, multi-team codebases deploying daily, and systems with a high share of AI-generated code. On small, low-risk projects, start with AI code review and security scanning and add layers once incidents justify them.
What should you prioritize when evaluating AI-driven QA services?
Prioritize governance over test count: human review of AI-written tests, output validation, staged rollouts, and audit-ready logs. Then check that the vendor or team measures defect escape rate and change failure rate before and after, and integrates with your CI/CD instead of running beside it.
Is a quarterly AI scan enough for maintenance?
No. Code review, security and dependency scans should run on every pull request; a quarterly scan finds issues months after they shipped. Quarterly is fine for a deeper review such as a full code audit or architecture review on top of per-PR gates.
How does Fora Soft price a QA program build?
A fixed-scope 12-week engagement, priced after a 30-minute scoping call because vendor count and compliance exposure drive the effort. Vendor license fees are pass-through. Book a scoping call.
Read next
AI TESTING
AI-Driven Testing: 2026 Buyer’s Guide
mabl, Testim, Diffblue, and Applitools compared with cost math and the EU AI Act compliance envelope.
AI RECOMMENDERS
AI Content Recommendation Systems in 2026
Two-tower models, vector DBs, and the cost math behind personalized feeds.
AI VIDEO
AI Video for E-Learning in 2026
Synthesia, HeyGen, ElevenLabs, and a 12-week rollout that cuts video cost 60–92%.
SERVICES
AI Development Services
How Fora Soft builds production ML systems end-to-end.
To sum up
AI quality assurance in 2026 is a cost center that pays back by preventing the one release that takes production down, not by replacing QA engineers. The nine-layer stack — defect prediction, test prioritization, AI code review, performance, security, accessibility, test data, observability, chaos — costs $244k–$498k/year at mid-market scale and collapses defect escape rate under 5% when governance holds.
We build these programs for media, video, and ML platforms where production failure is expensive and visible. If you’re deciding where to start, which vendors match your compliance posture, or how to wire test results to production observability without burning a year on integration, book a 30-minute review and we’ll leave you with a sequenced plan the same day.

The handbook · 7 volumes
Fora Soft Video Engineering Handbook
For video and real-time products, QA also has to measure what users see and hear, not only whether tests pass. We wrote a seven-volume handbook on the video stack, from encoding to delivery, audio and AI. Start with Volume 3 on QoE monitoring and player recovery, then Volume 1 for VMAF-style quality metrics and Volume 5 for PESQ, POLQA and ViSQOL. Written by Nikolay Sapunov, CEO at Fora Soft.
Browse the handbook on Amazon →7 volumes · 9,000+ pages · Kindle & paperback
Ready to take your QA program to DORA elite?
Book a 30-minute AI QA architecture review. We’ll audit your current stack, compliance exposure, and DORA metrics, and leave you with a vendor-by-vendor recommendation the same day.

