


Key takeaways
• Script maintenance eats 40–70% of automation effort. Self-healing AI locators knock that to under 15% and free your QA team to write new coverage instead of repairing old scripts.
• Five pain points absorb almost all of the pain. Flaky tests, manual regression across devices, drifting requirements, bad bug reports, and test-data management — AI compresses every one of them, but with different tools.
• Budgets are real. A small team can stand up an AI QA pipeline for $20K–$50K; mid-market lands at $100K–$250K; regulated enterprise at $500K+. Typical ROI breakeven is 6–12 months.
• AI does not replace human testers. It automates regression, synthetic data, bug triage, and visual diffing. Exploratory, UX, ethics, and bias checks remain human-owned.
• Measure defect-escape rate, not test count. Passing tests prove nothing if bugs still reach production. Track DER, MTTD, MTTR, flaky-test rate, and script-maintenance hours from day one.
Updated October 2026: Gartner’s new Magic Quadrant for Agentic Software QA Platforms, Playwright test agents, Diffblue Testing Agent, TestMu AI (ex-LambdaTest) and re-verified 2026 tool pricing.
The five biggest test automation pain points in 2026 are flaky and fragile tests, slow manual regression across browsers and devices, test cases that drift away from changing requirements, noisy or duplicate bug reports, and unsafe test data. This guide explains how AI in software testing compresses each one in 2026, which tools have earned their place on a mid-market roadmap, and where AI still fails. It is written for heads of QA, engineering directors, founders, and CTOs weighing an AI QA rollout against a brittle automation stack and burned-out manual testers.
The short version: AI-enabled testing is roughly a $1 billion market in 2025, forecast to reach $3.8 billion by 2032 (Fortune Business Insights). 89% of organisations pilot or deploy generative-AI QA workflows, but only 15% have scaled them enterprise-wide (Capgemini World Quality Report, November 2025). Gartner expects 70% of enterprises to use AI-augmented testing tools by 2028, up from 20% in 2025. Mature self-healing platforms cut script maintenance by up to 85% (vendor-reported). But 42% of companies abandoned most of their AI initiatives in 2025 (S&P Global), usually because they bought tools before defining metrics. This article shows how to avoid that trap.
Why Fora Soft wrote this playbook
Fora Soft has shipped tested, production-grade software for 20 years and 250+ projects. Our QA team runs AI-assisted pipelines on real client codebases daily — from the BrainCert virtual-classroom LMS used by 100K+ customers to a Mindbox video-surveillance system hitting 99.5% facial-recognition accuracy across 50+ deployments.
We work in Agent Engineering mode — senior QA engineers pair with AI agents that generate test cases, repair locators, and triage bug reports. On a recent project our team shipped 312 AI-generated test cases from 25 user stories in two hours, and the AI flagged seven logical contradictions in the spec before a line of code shipped. Market numbers in this article carry their source and year; vendor claims are marked as vendor-reported; numbers from our own projects are marked as ours. When the codebase under test is the real problem, our code audit covers security, quality and architecture, and names the exact file, line and fix for every issue.
Stuck with a flaky test suite and a burned-out QA team?
Book a 30-minute QA audit and we will come back with a tool shortlist, a rollout plan, and a dollar-accurate estimate — no sales pitch.
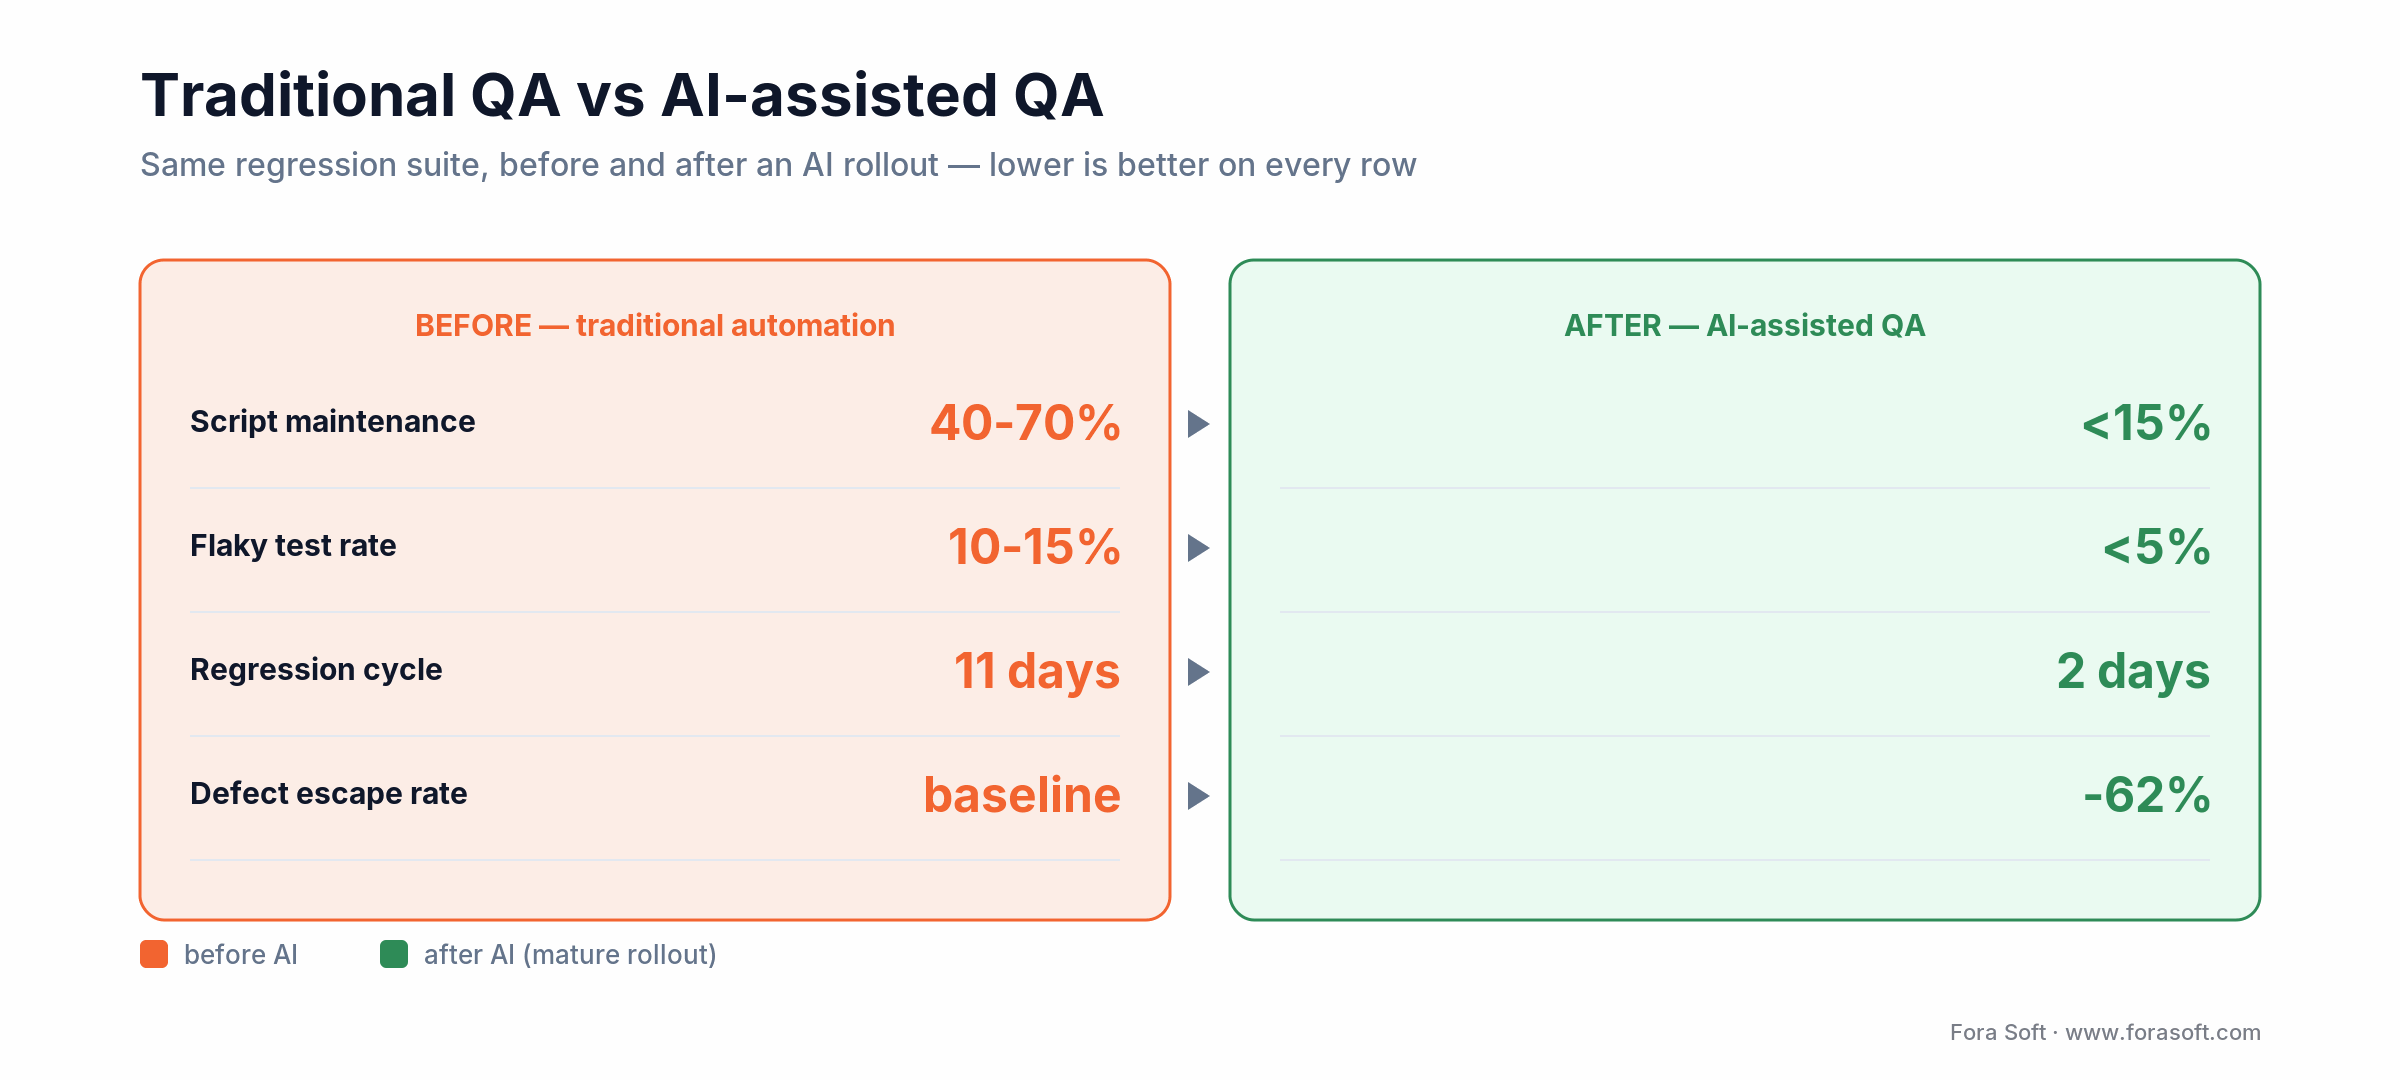
Figure 1. The payoff of a mature AI QA rollout on the same regression suite.
The 2026 QA numbers that should inform every budget decision
Six signals frame the conversation with your CFO.
| Signal | 2025–2026 number | Why it matters |
|---|---|---|
| AI-enabled testing market | $1B (2025) → $3.8B (2032, Fortune Business Insights forecast) | Vendor consolidation is imminent — choose tools with ecosystem staying power. |
| Cost of poor software quality (US) | $2.41 trillion, 2022 (CISQ) | The ROI argument for QA investment is not subtle. |
| Cost multiplier per stage | $100 (req.) → $1,500 (QA) → $10,000+ (prod) | IBM’s shift-left curve: every $1 in QA saves $5–10 later. |
| Script maintenance burden (traditional) | 40–70% of QA effort | Without AI, automation spends itself on self-repair. |
| AI self-healing impact | Up to 85% maintenance reduction (vendor-reported) | The single highest-ROI AI QA capability. |
| Gen-AI QA adoption | 89% piloting or deploying, 37% in production, 15% enterprise-wide (Capgemini WQR, Nov 2025) | Most teams are stuck between pilot and scale — the rollout plan matters more than the tool. |
| AI-augmented testing tools | 20% of enterprises (2025) → 70% by 2028 (Gartner, October 2025) | Late-movers will trail the median within two budget cycles. |
One more sobering stat: 42% of companies abandoned most of their AI initiatives in 2025, up from 17% in 2024 (S&P Global), because teams bought the tool before defining the metric. If you do not have a vulnerability-density baseline, an MTTR number, or a defect-escape-rate figure today, stop. Measure first, buy second.
What are the biggest test automation pain points in 2026?
The biggest test automation pain points are flaky tests, manual regression across devices, requirement drift, poor bug reports and test-data risk. Every QA team we audit shows the same five, and AI compresses each one with a different capability.
Pain 1 — Flaky and fragile automation
A button moves or a CSS class renames, and dozens of E2E tests go red. Even at Google, about 1.5% of all test runs report a flaky result and almost 16% of tests show some flakiness (Google Testing Blog, 2016). Target a flaky rate under 5% and a fix-or-quarantine policy with a two-week deadline.
Reach for AI self-healing when: your test suite has ≥ 200 E2E tests and the UI changes weekly — vendors such as Mabl, Testim and Functionize market 80–85% fewer flaky failures at that scale. The open-source option since Playwright 1.56 (October 2025) is the Playwright Healer agent, which reruns failing tests and repairs them until they pass or a guardrail stops it.
Pain 2 — Manual regression across devices and browsers
Thousands of browser, OS and device combinations are in active use; no team can cover them manually, and manual regression cycles routinely eat weeks per release. AI visual-regression tools (Applitools Eyes, Percy) filter rendering noise so testers review real changes instead of anti-aliasing diffs.
Reach for AI visual regression when: the product’s value depends on visual polish (e-commerce, media, design tools) or when you need to cover more than five browser/device combos.
Pain 3 — Drifting requirements and ballooning test-case management
When the spec mutates weekly, manual test cases decay faster than testers can update them. LLMs now ingest Jira stories, user stories in Gherkin, or requirement docs and emit structured cases in minutes — a shift documented across a growing body of peer-reviewed research on AI in software testing. Playwright’s Planner and Generator agents (2025) do the same against a running app: explore it, write a Markdown test plan, then turn it into Playwright tests. Human review is still needed on every generated case, but it beats writing from scratch — see the 312-case example above.
Reach for AI test-case generation when: the team rewrites more than 20% of cases per sprint, or when new features routinely ship with no cases at all.
Pain 4 — Poor bug reports and duplicate submissions
In busy trackers a large share of tickets are duplicates, and even the non-duplicates frequently lack reproduction steps, environment data, or screenshots, so developers request more info and fixes stall. Retrieval-based deduplication (BM25F similarity, now often embeddings) surfaces likely duplicates at filing time, and AI classifiers auto-route the rest to the correct squad. When the backlog itself is the problem rather than the tests, our software troubleshooting and optimization team reproduces, profiles and fixes the defects that keep escaping.
Reach for AI bug triage when: your Jira backlog grows by more than 50 tickets a week or you have more than one product squad fielding issues from the same channel.
Pain 5 — Test-data management and privacy risk
Using production data in test environments breaches GDPR, HIPAA, and PCI-DSS. Manually crafted test data is thin and skips edge cases. Gartner predicted that by 2026 75% of businesses would use generative AI to create synthetic customer data, up from under 5% in 2023. Tools: Tonic.ai, K2view, Gretel (acquired by NVIDIA in March 2025), MOSTLY AI, YData, and Hazy (part of SAS since November 2024).
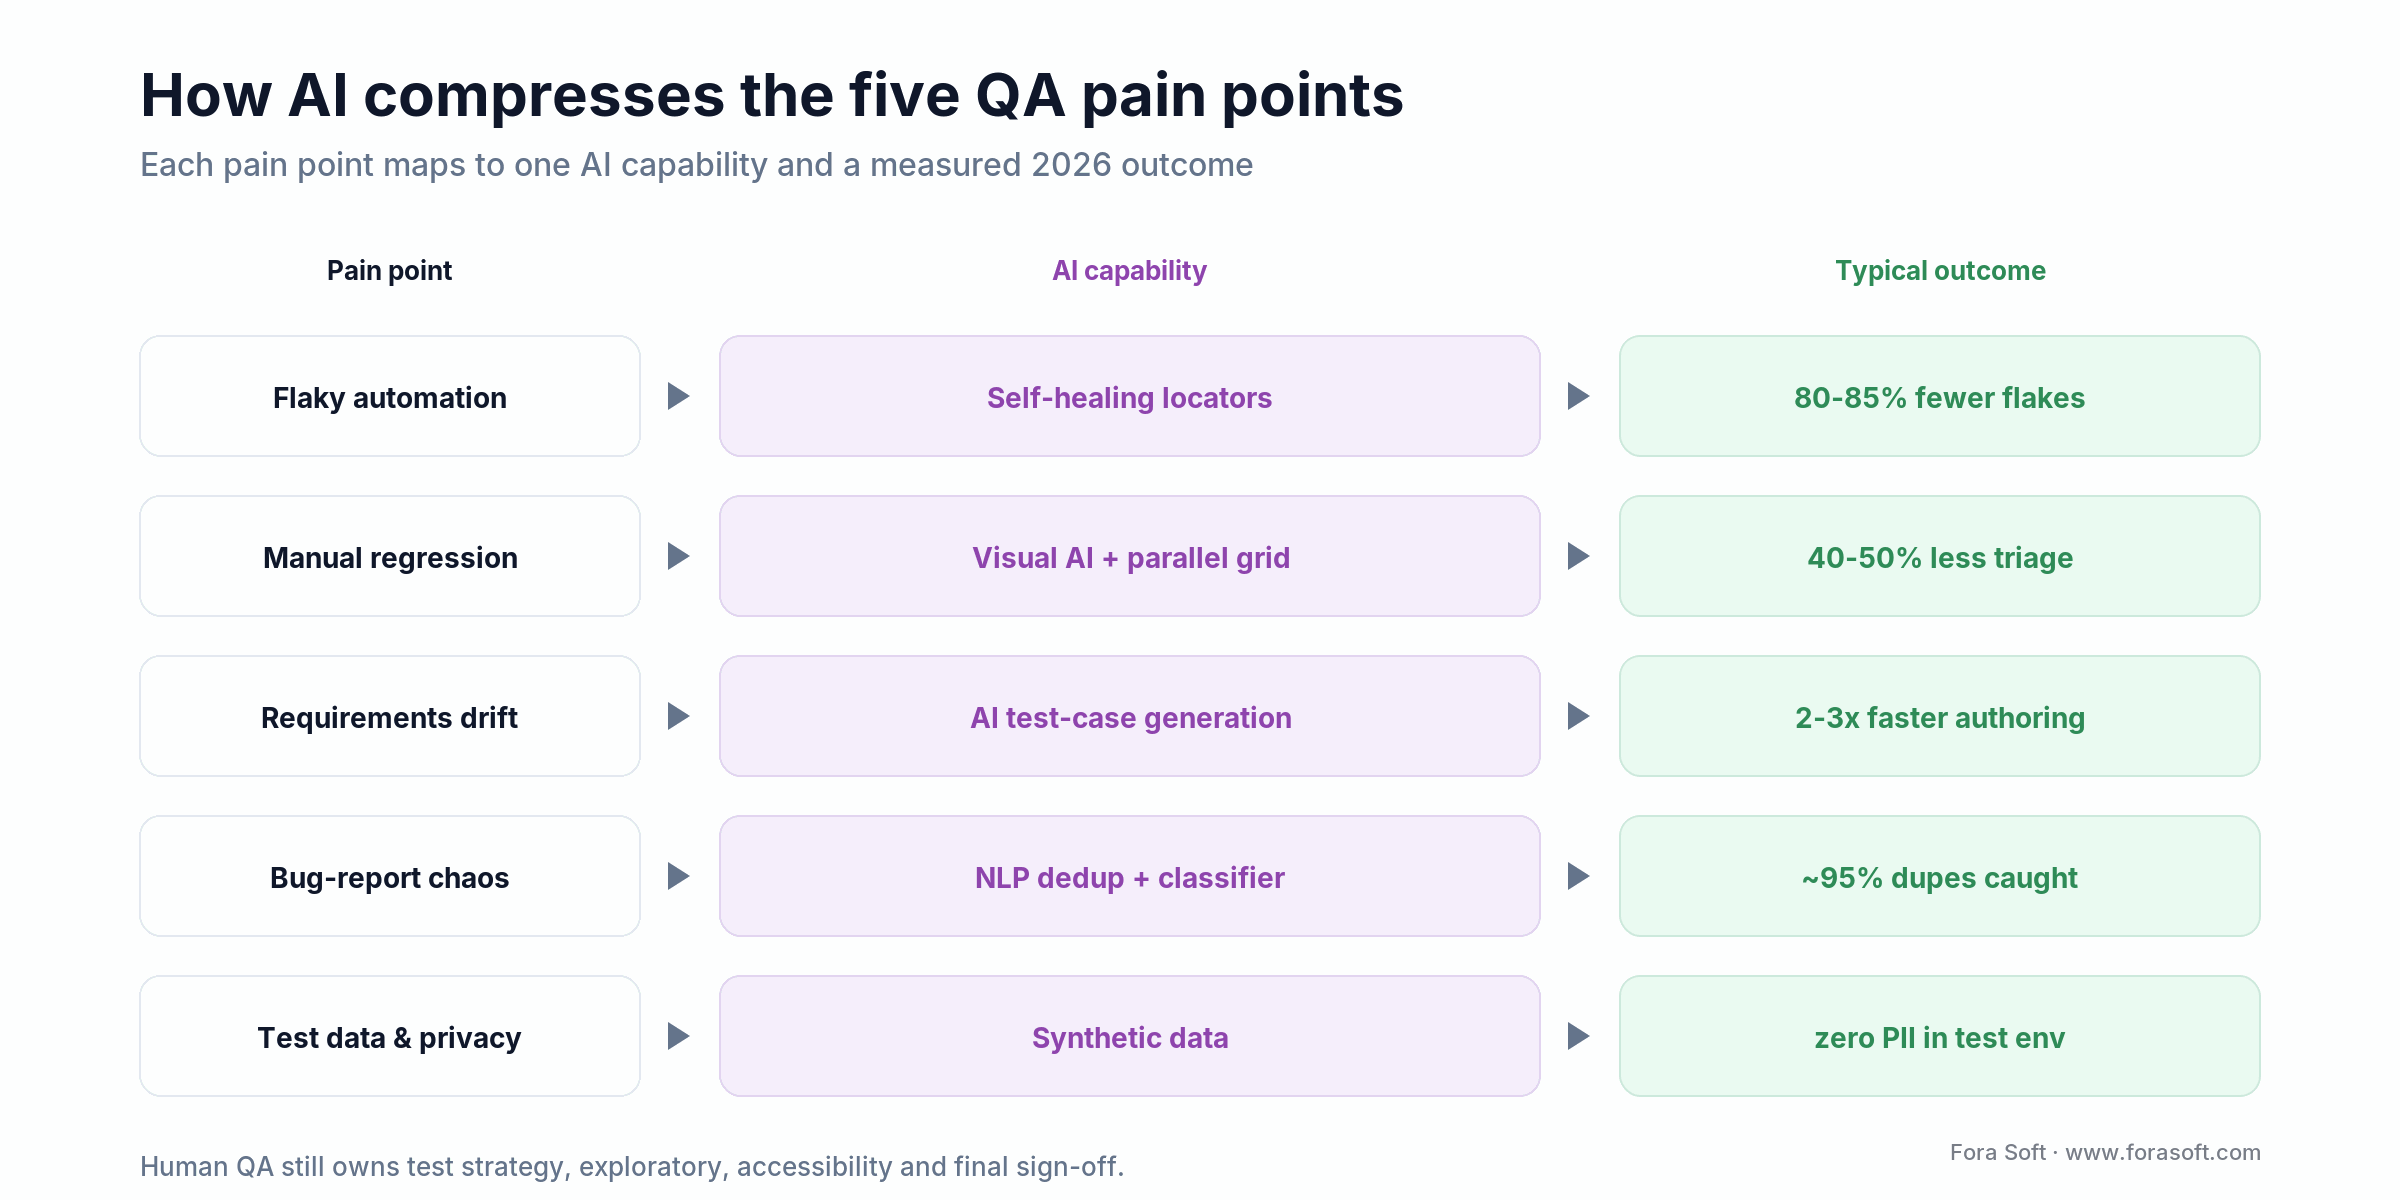
Figure 2. Each pain point maps to one AI capability and a measured outcome.
How AI actually compresses each pain point
AI in software testing is not one capability but five. One table, five outcomes, no guesswork.
| Pain | AI capability | Mechanism | Typical outcome (vendor-reported) |
|---|---|---|---|
| Flaky tests | Self-healing locators | Semantic intent, visual fingerprints, ML relocation | 80–85% fewer flaky failures |
| Manual regression | Visual AI + parallel grid | Pixel / structure diff with noise filtering | 40–50% triage cut, full regression < 24 h |
| Requirements drift | AI test-case generation | LLM reads user stories, emits steps / expected results | 2–3× faster authoring |
| Bug report chaos | NLP dedup + classifier | BM25F similarity, severity/component ML | Duplicates caught at filing, faster routing |
| Test data | Synthetic data | Statistical twinning of production schema | No production PII in test environments |
The 2026 AI QA tool matrix
Twelve tools that actually ship. In Gartner’s October 2025 Magic Quadrant for AI-Augmented Software Testing Tools, Tricentis, UiPath, Keysight and OpenText were named Leaders. In October 2026 Gartner followed it with a Magic Quadrant for Agentic Software Quality Assurance Platforms, where Tricentis is again a Leader (Tricentis, October 2026). Prices below were re-checked in October 2026; most vendors now quote rather than publish list prices.
| Tool | Strength | Weakness | Price shape | Best fit |
|---|---|---|---|---|
| Mabl | Auto-healing E2E, built-in quality metrics | Smaller enterprise governance | Quote-based (no public list price, 2026) | Agile mid-market SaaS |
| Testim (Tricentis) | ML locators, cloud-native, Gartner Leader | Learning curve; pricing opacity | Custom enterprise | Web/mobile enterprise |
| Functionize | NLP authoring, autonomous repair | No-code can oversimplify | Quote-based | SaaS-first orgs |
| Katalon Studio | Balanced UI/API/mobile, co-pilot | Higher maintenance without AI | Free tier + paid seats | Mid-market, mixed skills |
| Applitools | Visual AI + Ultrafast Grid | Expensive at scale | Starter $667/mo billed annually; higher tiers quoted (Oct 2026) | Visual-heavy apps |
| BrowserStack Percy | AI Review Agent, real devices | Pixel-based diffs | $199/mo billed annually for 10K screenshots → enterprise (Oct 2026) | Cross-browser / device |
| Tricentis Tosca | Vision AI, risk-based, 160+ tech | Expensive, learning curve | Enterprise quote | Regulated enterprise |
| ACCELQ | NL automation, codeless | Smaller community | Quote-based | Requirement-driven teams |
| Qodo / Codium | AI unit-test generation | Unit / integration only | Free – SaaS tiers | Coverage-starved dev teams |
| Playwright test agents + MCP | Open source; Planner, Generator and Healer agents since v1.56 (Oct 2025); works with Copilot, Claude Code, Codex | No vendor support layer | Free + your AI coding agent | Dev-heavy teams |
| Diffblue Cover / Testing Agent | Autonomous regression-test generation: 81% average line coverage vs 32% for a developer with an AI coding agent (Diffblue benchmark, March 2026) | Java and Python only | Enterprise licence | Java enterprises |
| TestMu AI KaneAI (ex-LambdaTest) | Real devices + AI insights | Newer self-healing engine | Per-minute + bundles | Cross-browser CI/CD |
Most mid-market teams land on a pair: Mabl or Testim for E2E self-healing, plus Applitools or Percy for visual regression, plus Tonic.ai for synthetic data. Anything beyond three AI QA tools usually signals tool sprawl rather than coverage.
Reference QA pipeline — where AI plugs in at each stage
Seven stations, each with a specific AI contribution. If your current pipeline is missing two or more, you are paying the maintenance tax.
1. Dev / unit. Diffblue Cover or Qodo generates unit tests on save; Copilot suggests them inline. Target: 80%+ line coverage without human authoring.
2. Integration. AI test-case generation from API specs (OpenAPI, GraphQL); contract tests via Pact with AI-assisted schema diffing.
3. UI automation. Self-healing locators (Mabl, Testim, Functionize). Target: < 15% flaky-test rate, < 30% QA time on maintenance.
4. Visual regression. Applitools or Percy across a matrix of device/browser combos. AI noise filtering is essential; untuned visual diffs produce 1,000+ false positives per run.
5. Load and performance. AI-driven test-data generation (Tonic.ai, K2view). AI anomaly detection on load metrics.
6. Exploratory. Human-led. AI can suggest edge-case scenarios from telemetry, but the testers own the session.
7. Production observability. AI root-cause analysis on logs and traces (Datadog Watchdog, Dynatrace Davis, New Relic AI). Feeds back into test-case generation for regression.
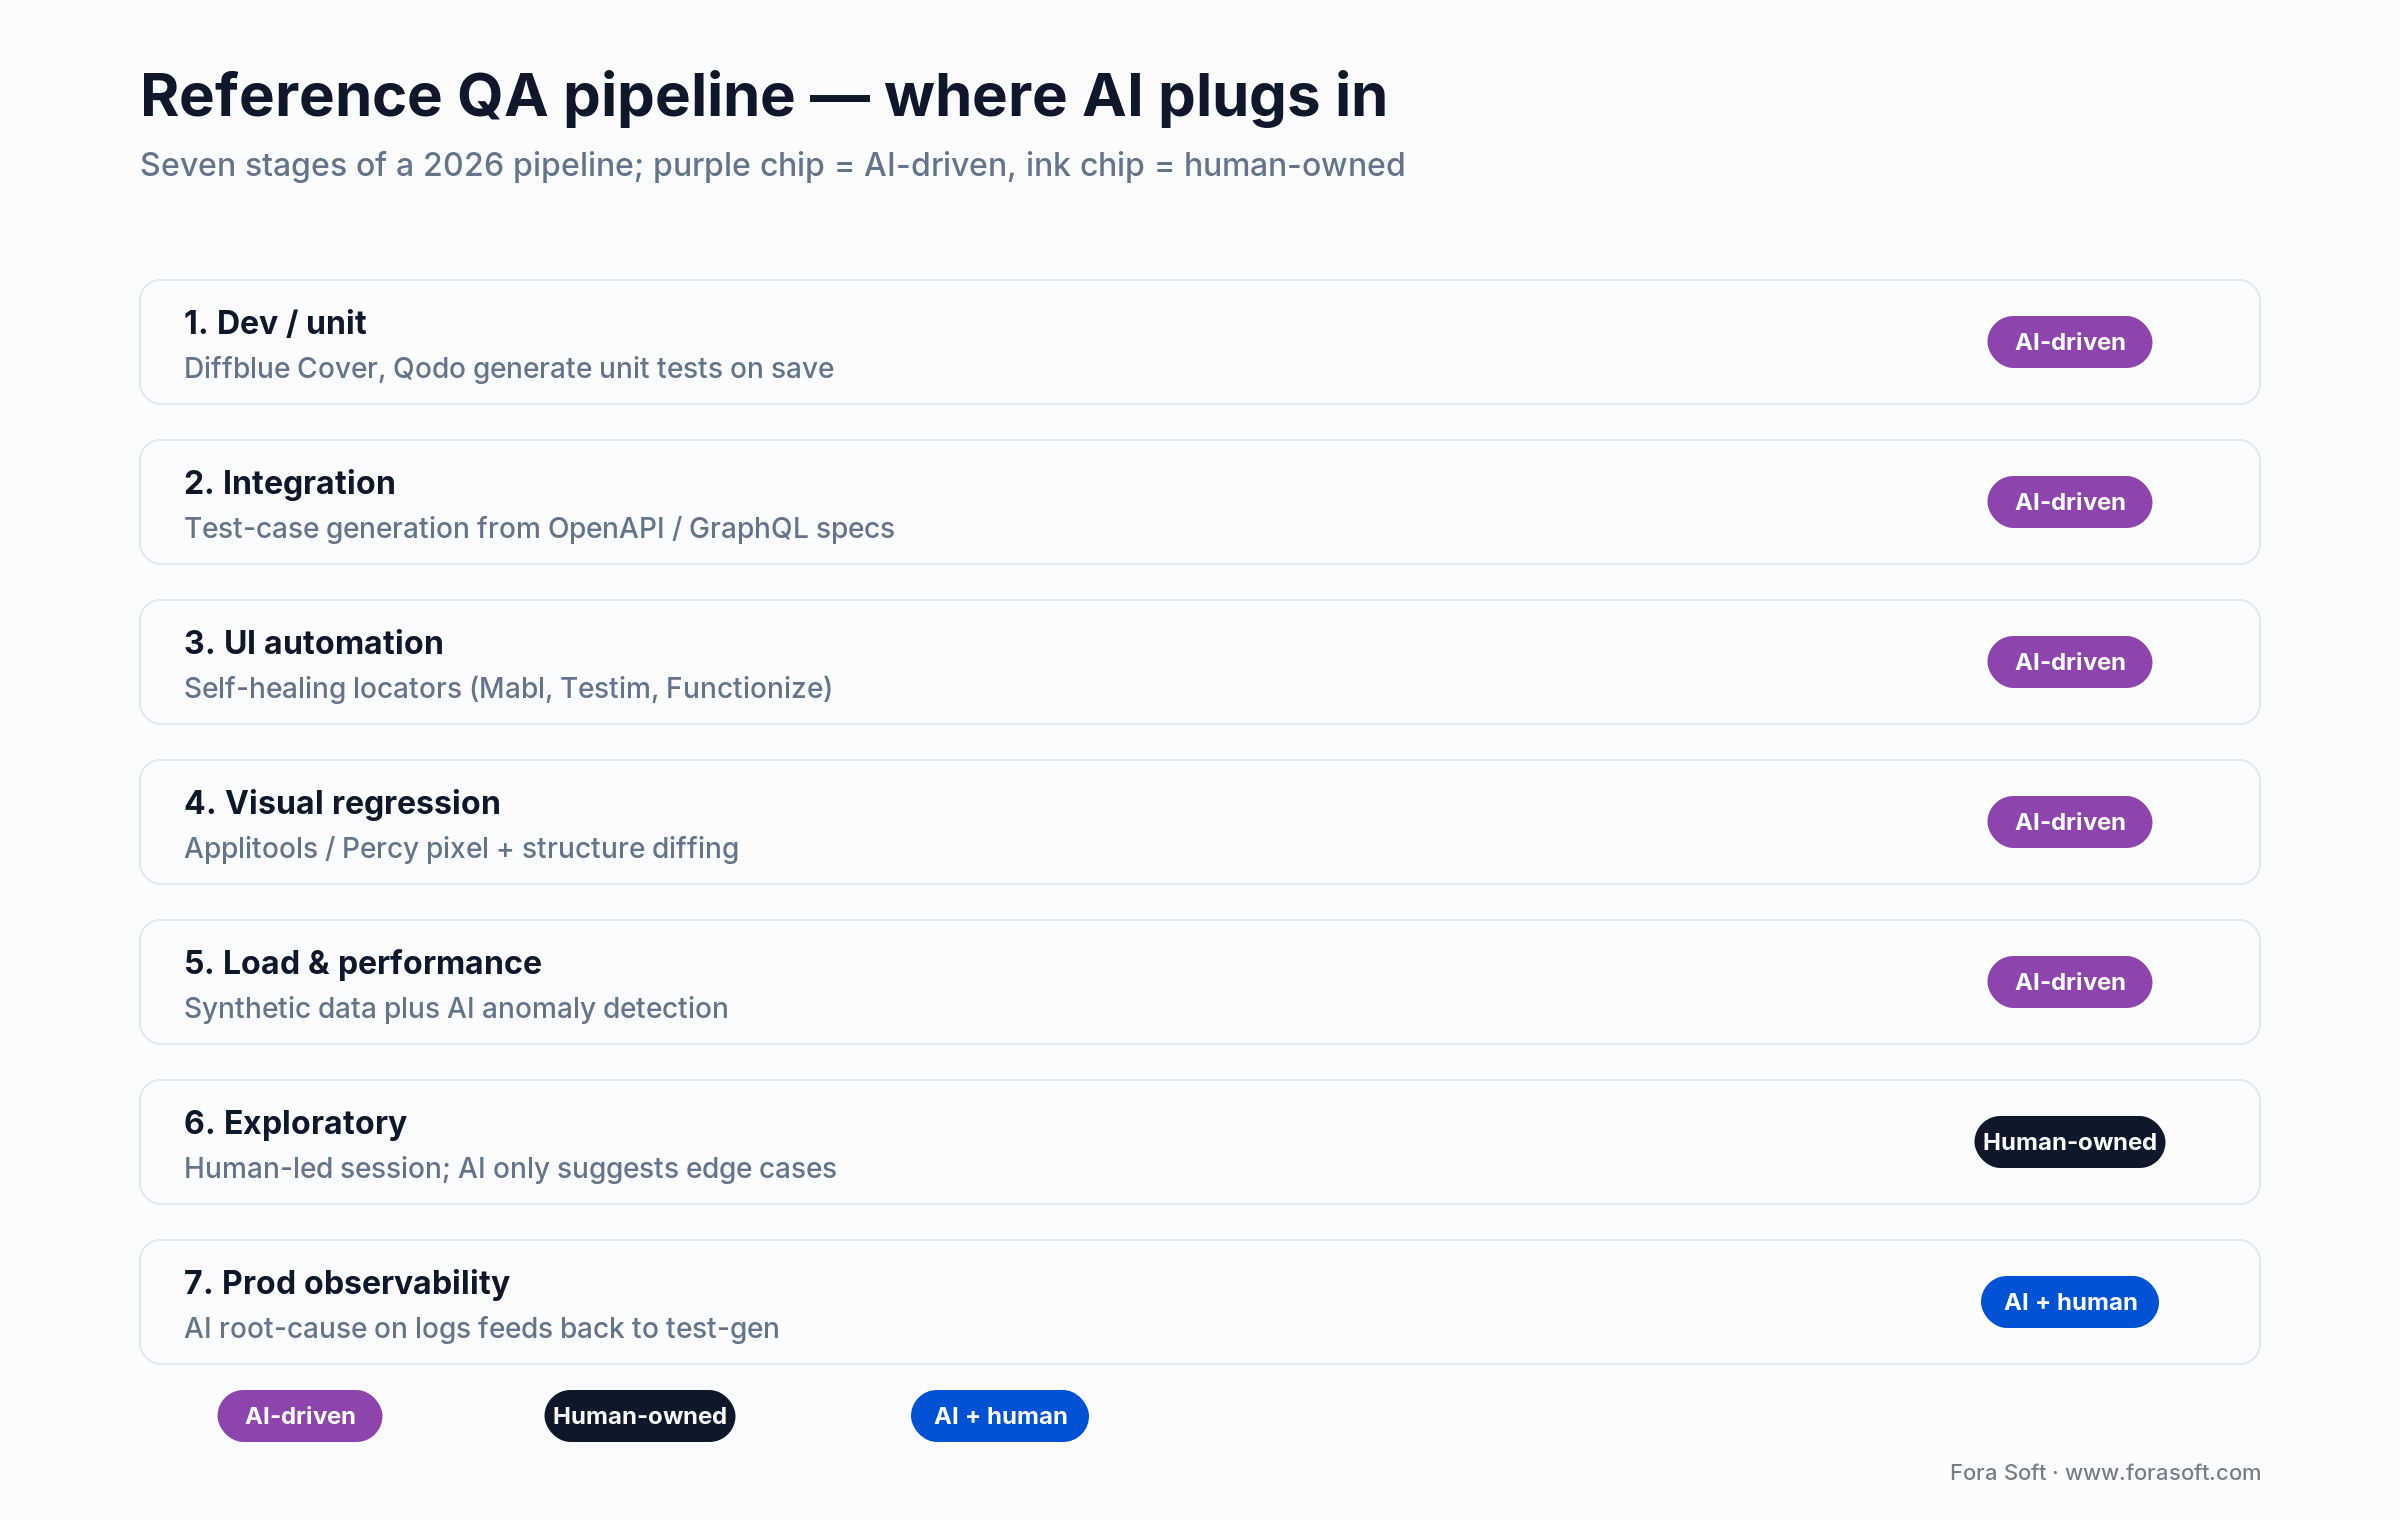
Figure 3. Where AI plugs into a 2026 QA pipeline, and where humans stay in charge.
Want a 2-week AI QA pilot on your real codebase?
We run a fixed-fee pilot: tool selection, baseline metrics, 20 self-healing tests, and a go/no-go report with next-step budget.
Cost and timeline — three realistic rollout tiers
| Tier | Team size | Upfront | Annual | Timeline |
|---|---|---|---|---|
| SMB | 10–50 testers | $20K–$50K | $40K–$80K | 4–8 weeks |
| Mid-market | 50–200 testers | $100K–$250K | $150K–$400K | 8–12 weeks pilot, 4–6 months full |
| Enterprise | 200+ testers | $500K–$2M | $500K–$1.5M | 6–12 months pilot, 12–18 months full |
Hidden costs bite hardest at the enterprise tier. Data prep adds 10–20%, legacy-system integration 15–25%, training 10–15%, ongoing maintenance another 10–15%. Budget overruns are the norm — 85% of organisations misestimate AI costs by more than 10% and nearly a quarter are off by 50% or more, almost always on the low side (Benchmarkit and Mavvrik, 2025 State of AI Cost Management). Get a fixed-fee pilot before committing to an enterprise rollout.
Worked example — cutting regression from 11 days to 2 on a HIPAA-style suite
Here is how the pieces combine on a typical regulated suite. The figures are an illustrative model built from the ranges above, not one client’s audited results: a 180-test Selenium suite that takes 11 days per regression cycle, keeps 38% of tests in a permanent “flaky” state, and blocks weekly deploys.
The 10-week plan: migrate the suite to Mabl for self-healing UI tests, layer Applitools for cross-browser visual regression, introduce Tonic.ai for HIPAA-compliant synthetic test data, and add a CodeRabbit-style AI PR reviewer on every merge. Backlogged user stories go through our Fora Soft spec-driven Agent Engineering workflow to generate the missing cases.
Target outcome: regression from 11 days to about 2, flaky rate from 38% to under 6%, and a defect escape rate that falls quarter over quarter — the same exit criteria we write into real engagements. Deploys move from once every three weeks to weekly or faster. Want a similar audit for your suite?
How to roll out AI QA in four phases
Phase 1 — Baseline (week 1–2)
Measure existing defect escape rate, flaky-test rate, script-maintenance hours, regression cycle time, and MTTR on Critical bugs. Without these numbers you cannot prove ROI, and the CFO will notice.
Phase 2 — Pilot (week 3–8)
Pick one product surface (checkout, onboarding, a single micro-service). Migrate 20–50 tests to the chosen AI tool. Target: self-healing success > 80% and flaky rate < 10%. Exit criterion: a metrics dashboard showing the improvement.
Phase 3 — Scale (week 9–20)
Extend to the whole suite. Add visual regression and synthetic data. Introduce an AI bug-triage workflow. Require all new tests to be authored on the AI platform; phase out the legacy framework on a 90-day timeline.
Phase 4 — Mature (ongoing)
Quarterly retros on defect escape rate. Retune self-healing thresholds. Review AI test-generation quality; retrain templates. Audit synthetic-data drift. Train new QA hires on AI-first workflows from day one.
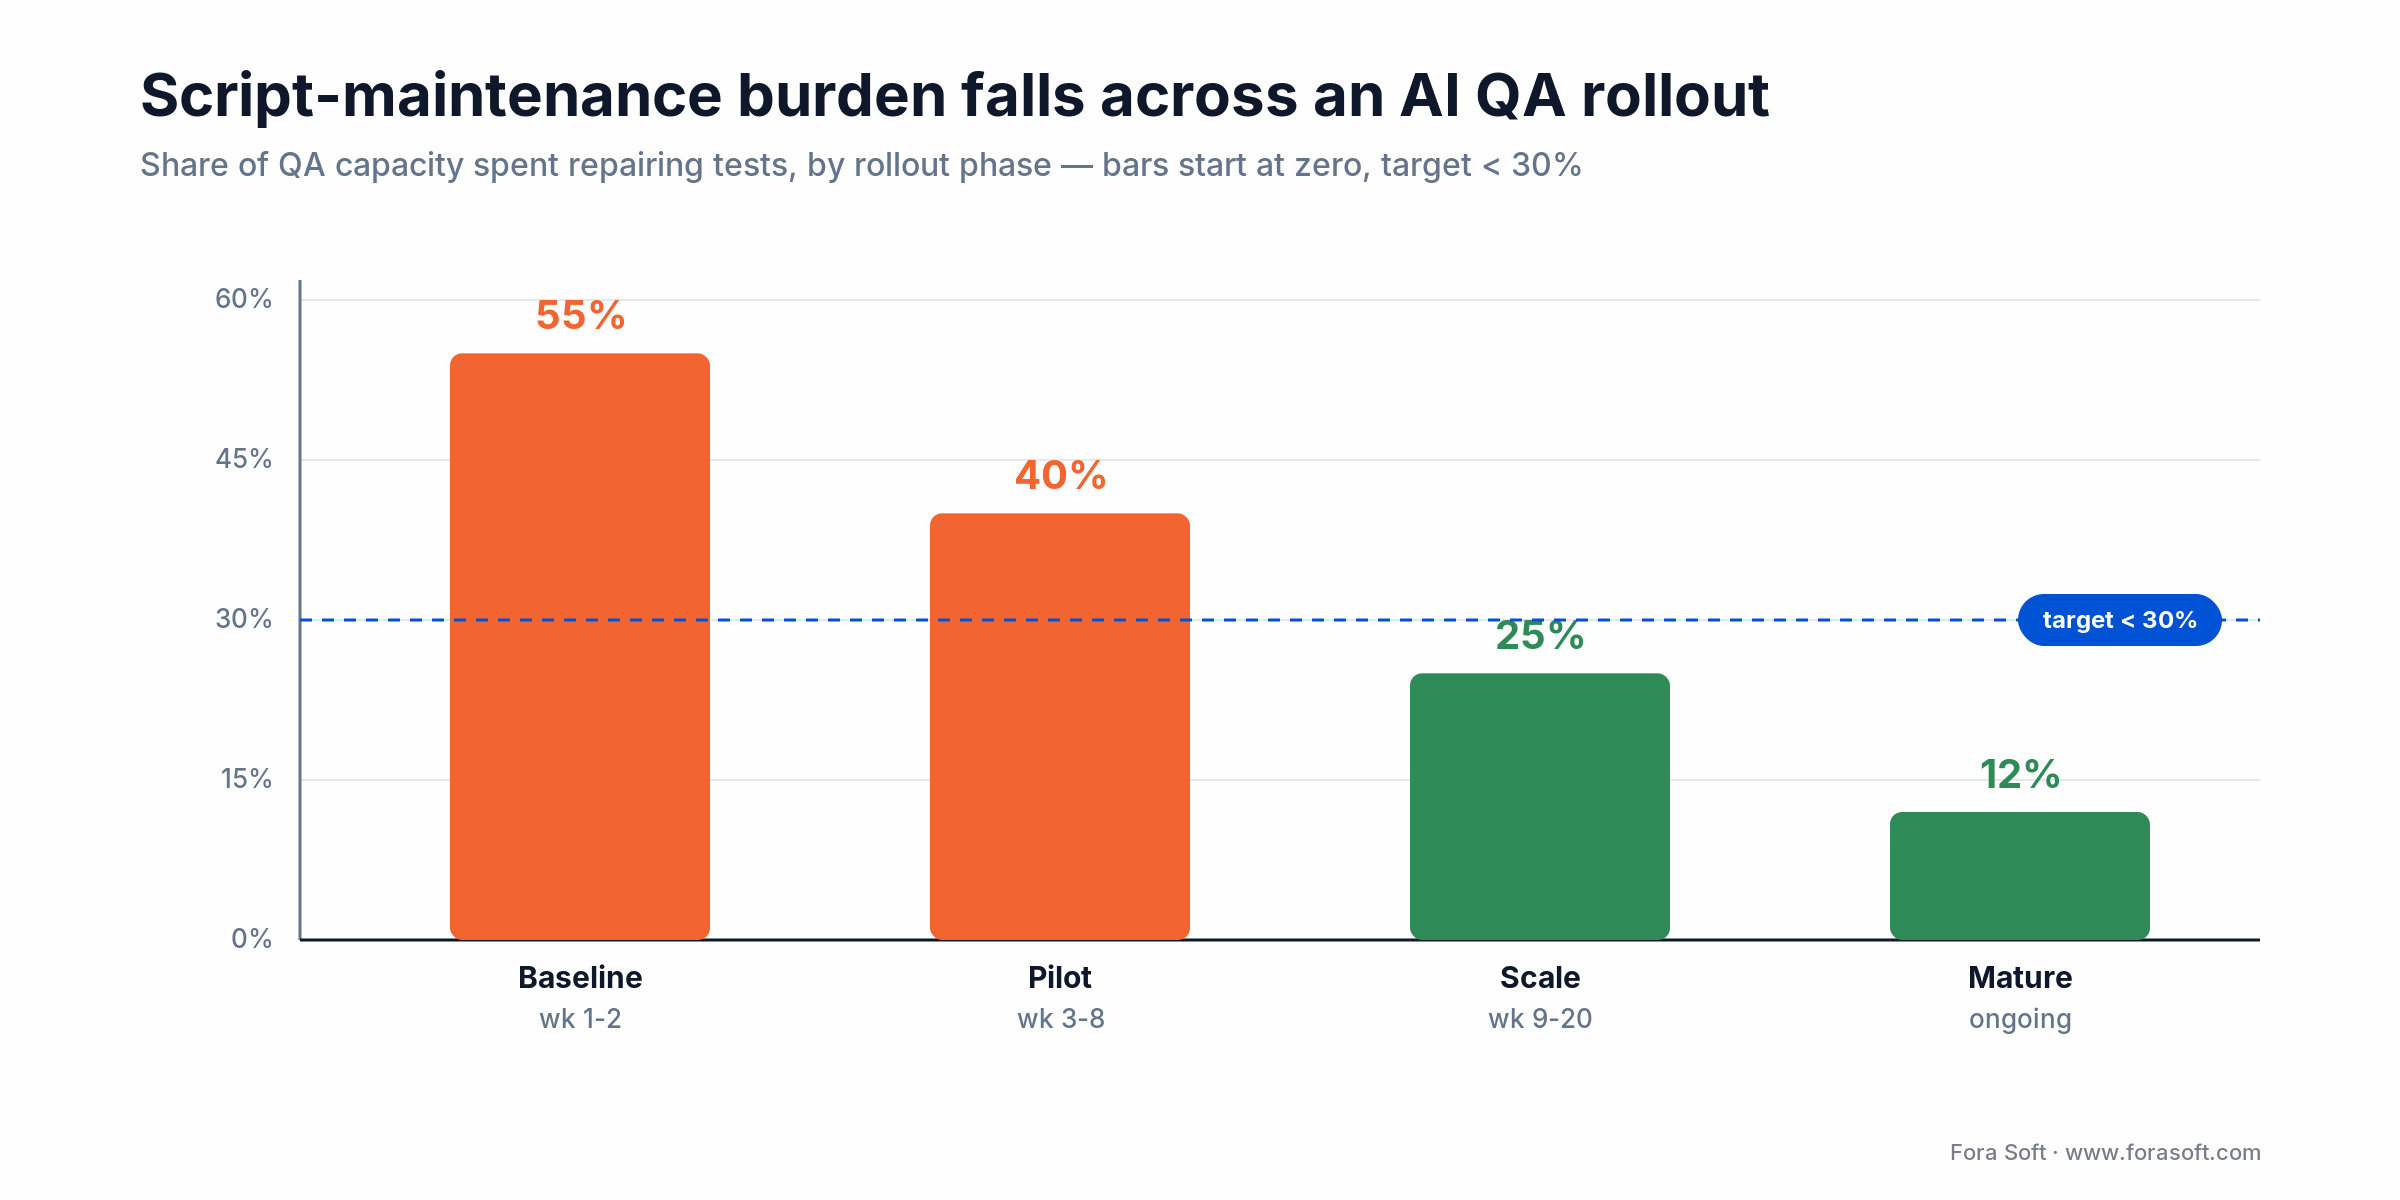
Figure 4. Script-maintenance burden falls phase by phase. This is the metric that proves the rollout pays.
KPIs — what the CFO and CISO will ask for
Quality KPIs. Defect escape rate (target < 1.5%), risk-weighted test coverage (target > 85%), flaky-test rate (target < 5%). These three numbers are the scoreboard.
Business KPIs. Release cadence / lead time (target < 7 days), cost per escaped defect (target < $10K), script-maintenance hours as a fraction of QA capacity (target < 30%). Business signals the CFO will read.
Reliability KPIs. MTTD (mean time to detect a defect, target < 4 h), MTTR (mean time to resolve Sev-1, target < 8 h), automation pipeline uptime (target ≥ 99.5%). Reliability signals the CISO will read.
Five pitfalls that sink AI QA rollouts
1. Over-relying on AI-generated tests. LLMs miss domain context and happily skip edge cases. Keep human QA leads in charge of test strategy; review 100% of AI-generated cases before they enter the suite.
2. Tool sprawl. Teams adopt Mabl plus Playwright plus Applitools plus Tonic.ai plus Qodo without integration and end up with five data silos. Start with one platform covering 80% of your needs; expand deliberately.
3. Missing AI / ML expertise. Capgemini’s World Quality Report 2025 finds 50% of organisations still lack AI/ML expertise (unchanged from 2024), the skills needed to run these tools well. Upskill the team or partner with a delivery organisation that does this every week; do not let a junior QA engineer own the whole stack.
4. Privacy risk in synthetic data. Poorly configured generators leak production patterns (and sometimes actual records). Use enterprise-grade tools with GDPR / HIPAA / PCI-DSS audit trails — Tonic.ai, K2view, Hazy — and sign DPAs with every vendor touching PII.
5. False confidence from green dashboards. A passing suite is not a safe suite. Track defect escape rate monthly; run mutation testing quarterly; keep exploratory sessions on the calendar. If the dashboard is green but production keeps breaking, the test-set is the bug.
When not to use AI in QA
Ethics, bias, and accessibility. AI will not catch that your hiring app discriminates or that your media player fails for screen readers. Human review is mandatory.
Chatbot and NLP validation. AI graders miss sarcasm, cultural nuance, and regional dialects. Use diverse human annotators.
Exploratory testing. The value of an exploratory session is the human noticing what they did not expect. AI suggests leads; humans own the verdict.
Test strategy and risk ranking. An LLM writes a plausible-sounding test plan that misses the real risk. Keep senior QA leads on strategy.
Low-volume, one-off checks. Setting up an AI pipeline for a single-shot test costs more than running it manually. Use judgement.
What stays human-owned on a Fora Soft project
Our default position, informed by shipping regulated products for 20 years and our AI engineering practice: AI automates the structured, repetitive 70%. Humans own the 30% where judgement matters. Specifically:
- Security and privacy testing — threat modelling, key exchange, HIPAA / GDPR paths.
- Accessibility audits — manual screen-reader, voice-control, keyboard-only, colour-blind review.
- UX and usability testing with real users in the target demographic.
- Exploratory sessions on the highest-risk surfaces (payment, auth, medical input).
- Final test strategy sign-off before a release — AI proposes, the human disposes.
See our full position on AI in QA and technical debt.
A decision framework — pick your AI QA stack in five questions
1. What is your baseline pain? Flaky tests → self-healing (Mabl, Testim). Manual regression → visual AI + parallel grid (Applitools, Percy). Spec drift → AI test-case generation (Functionize, Qodo).
2. What is your tech stack? Web SaaS → Mabl / Testim. Mobile heavy → BrowserStack Percy + TestMu AI KaneAI (LambdaTest renamed itself TestMu AI in January 2026). Java enterprise → Diffblue + Tricentis Tosca. Dev-driven open-source → Playwright test agents + MCP.
3. What regulations apply? HIPAA / PCI-DSS / GDPR → synthetic data is mandatory (Tonic.ai, K2view). FedRAMP → Tricentis / OpenText. SOC 2 → any of the major vendors will pass, ask for SOC 2 Type II reports.
4. What is your budget cap? Under $80K/year: one self-healing E2E platform (Mabl or Katalon) or Playwright test agents, plus Percy and an entry synthetic-data tier. $80K–$400K: add Testim or Functionize for larger suites. Above $400K: Tricentis, OpenText, or UiPath with dedicated vendor support.
5. Who will own the tool? If no one on the team is excited about AI QA, the tool will be shelfware in six months. Pick a champion first, tool second.
Pre-launch checklist — ten items that keep the rollout on track
- Baseline metrics captured (DER, flaky rate, MTTR, maintenance hours, regression time).
- A single product champion owns the AI tool rollout.
- Pilot scope is bounded — one team, one surface, 20–50 tests.
- Exit criteria for the pilot are written down before it starts.
- Data privacy / vendor DPAs are signed before test data leaves the company.
- Self-healing success threshold is set (≥ 80%).
- Human review gate for 100% of AI-generated test cases.
- Tool integrations with Jira / Linear / GitHub / GitLab are tested end-to-end.
- Rollback plan exists if the pilot fails to hit exit criteria.
- 30 / 60 / 90-day retrospectives are on the calendar.
Common mistakes we keep seeing
Buying the tool before defining the metric. 42% abandonment rate traces almost entirely to this mistake.
Treating AI QA as pure automation. The real value is redirection of human attention, not replacement. Plan for testers to spend the saved hours on exploratory and UX work, not be reduced in headcount.
Using production data in test environments. Fines reach €20M or 4% of global revenue under GDPR. Always synthetic.
Running AI self-healing without a confidence threshold. Heal at 60% confidence and you will get silent, wrong passes. Set the threshold at 85% and log every self-healed locator for human review.
Scaling the pilot to 100% of tests on day one. The phased rollout exists for a reason — AI tools need tuning. Give yourself 90 days.
The QA metrics dashboard that earns executive trust
Executives rarely want the Mabl or Applitools console. They want a one-page dashboard with last-quarter deltas. Build it once; share it in every board meeting.
Top-left — Defect escape rate. Percentage of bugs that reached production this quarter. Target < 1.5%. Trend line vs the previous four quarters.
Top-right — Regression cycle time. Days from code freeze to release-ready signal. Target < 7. AI rollouts usually halve this within two quarters.
Bottom-left — Script-maintenance hours per sprint. Percentage of QA capacity spent on repair, not new coverage. Target < 30%. The single metric that proves an AI QA rollout pays.
Bottom-right — Flaky test rate and MTTR. Twin reliability signals. Flaky < 5%, MTTR for Sev-1 < 8 hours. Use red-amber-green thresholds and trend arrows; the board will read those before they read the numbers.
FAQ
Will AI replace QA testers?
No. AI takes over repetitive, structured work — regression, data generation, deduplication — so testers can spend more time on exploratory testing, UX, and risk analysis. Capgemini’s World Quality Report 2025 puts the average Gen-AI productivity gain in quality engineering at 19%, with a third of organisations seeing minimal gains — augmentation, not replacement. In our experience, teams that cut QA headcount on AI promises regret it within two quarters.
How long until AI QA pays for itself?
Typically 6–12 months for SMB and mid-market teams; 12–18 months at enterprise scale. Break-even accelerates if your baseline script-maintenance burden is above 50%, because that is exactly the cost AI compresses fastest.
Which AI QA tool should a mid-market SaaS choose?
For most mid-market SaaS teams, Mabl (self-healing E2E) plus Applitools or Percy (visual regression) plus Tonic.ai (synthetic data) covers 80% of needs for under $120K/year. Add Qodo or Diffblue if unit-test coverage is below 60%.
Can AI handle our legacy desktop app?
Partially. Self-healing locators work well on most web and mobile apps. Deeply custom desktop UIs or legacy Windows applications usually need vision-based AI (Tricentis Tosca, UiPath Test Suite) and a careful selector strategy. Visual regression excels here because it bypasses the selector problem.
How do we avoid vendor lock-in?
Prefer tools that support open standards — Playwright, WebDriver, OpenAPI. Avoid proprietary scripting languages. If you must use a closed platform, negotiate data-export rights for your tests and historical run data upfront. Playwright with its built-in test agents and MCP is the most open stack in 2026.
What about synthetic test data and GDPR / HIPAA?
Enterprise-grade tools (Tonic.ai, K2view, Hazy, Gretel) generate compliant synthetic data with audit trails. Never use real production data in test environments — the fines reach €20M or 4% of global revenue under GDPR and can top $1.5M per incident under HIPAA. Validate synthetic data does not leak statistical patterns.
What is the realistic ROI on an AI QA investment?
Treat published ROI figures with caution: most are vendor-funded. The biggest single lever is the script-maintenance time you recover, so track cost per escaped defect and maintenance hours from week one; teams spending more than half of QA capacity on maintenance usually reach breakeven inside 12 months.
How do we handle AI-generated tests that look good but miss the real risk?
Pair every AI-generation pass with a human risk-mapping review, run mutation testing quarterly, and track defect escape rate as the single scoreboard metric. If AI tests are passing but production still breaks, your coverage is wrong — fix the generation templates, not the dashboard.
What are the most common test automation pain points?
The five most common test automation pain points are flaky and fragile tests, slow manual regression across browsers and devices, test cases that drift from changing requirements, noisy or duplicate bug reports, and unsafe test data. Self-healing locators, visual AI, AI test-case generation, AI bug triage and synthetic data address them one-to-one.
Our UI changes weekly and test maintenance eats QA time — what reduces it?
Self-healing locators reduce it most: a commercial platform such as Mabl or Testim, or the open-source Playwright Healer agent, repairs broken selectors instead of a tester. Add stable test IDs to the UI, heal only above an 85% confidence threshold, and log every healed locator for human review.
What is AI regression testing?
AI regression testing uses machine learning to keep a regression suite running as the product changes: it heals broken locators, generates missing cases from user stories, filters visual-diff noise and picks the tests most likely to catch a given change. Humans still decide what the suite must cover.
How does AI bug detection work in QA?
AI bug detection combines anomaly detection on test runs, logs and traces with visual diffs and AI code review on every pull request, so a likely defect is flagged before a tester files it. Duplicate detection and auto-routing then send each confirmed bug to the right squad.
What to read next
AI testing
AI-Driven Testing: The Buyer’s Guide
The full 2026 tool-by-tool comparison with pricing and rollout playbook.
Case study
AI Software Development: A Case Study
A real Fora Soft engagement: shipping production software with AI in the loop.
Security
AI Code Security & Shift-Left Playbook
How AI-powered SAST, DAST, SCA, and AI PR review fit alongside QA.
Agent engineering
Spec-Driven Agentic Engineering
The Fora Soft methodology behind our faster-than-agency rollouts.
Process
AI in the Software Development Process
How AI fits into the full SDLC without taking over critical decisions.
Ready to fix your QA pain with AI?
The playbook is simple. Measure baseline defect-escape rate, flaky rate, and script-maintenance hours. Pick one tuned tool per pain point — self-healing E2E, visual regression, synthetic data, unit generation, bug triage. Run a 2–6-week pilot with hard exit criteria. Scale only when the numbers prove the tool. Retain human ownership of test strategy, accessibility, security, and exploratory work.
Do not let your team become one of the 42% that abandoned an AI project in 2025. Define the metric before you pick the tool, give the pilot a 90-day window, and insist on fixed-fee entry points.
Fora Soft has rolled out AI QA pipelines across regulated healthcare, SaaS, and AI-heavy video platforms through our AI development services. If you want a second pair of eyes on your QA roadmap — or a team to run it with you — a 30-minute scoping call is the shortest path.

The handbook · 7 volumes
Fora Soft Video Engineering Handbook
AI can generate test cases, but someone still has to know what a broken video product looks like. Our seven volumes cover the video stack from encoding and delivery to audio and AI. QA teams testing video features can start with Volume 3 on players, stall recovery and QoE monitoring, then Volume 1 on quality metrics and Volume 5 on diagnosing audio incidents by symptom. Written by Nikolay Sapunov, CEO at Fora Soft.
Browse the handbook on Amazon →7 volumes · 9,000+ pages · Kindle & paperback
Let’s rebuild your QA pipeline
Tell us your team size, stack, and current pain — we will come back with a tool shortlist, a phased plan, and a dollar-accurate estimate.

