
Intelligent tutoring systems have left the research lab. In 2026 they ship to millions of learners at Khan Academy, Carnegie Learning and Duolingo, and inside corporate reskilling platforms, with learning gains that land in the d = 0.6–0.8 range when they are built right. This playbook is how Fora Soft engineers actually build them: the five-layer reference stack, the 2026 model and knowledge-tracing choices, the RAG grounding pattern that stops hallucinations, the compliance calendar that shifted under everyone in July, and the 10–14-week path to production.
Key takeaways
• An ITS is five layers, not a prompt. Learner model, curriculum graph, pedagogy model, multimodal I/O and an evaluation loop. Ship only the LLM layer and you get engagement without durable learning.
• The evidence is real but conditional: d = 0.71–0.79. VanLehn’s meta-analysis puts step-based tutoring at d = 0.76, near a human tutor’s 0.79. Some K-12 math studies find far smaller gains, so guardrails and measurement decide which camp you land in.
• Knowledge tracing is the spine. BKT stays the interpretable baseline; SAKT and SAINT reach AUC 0.82–0.85 on EdNet. Pick one off the shelf unless you have more than 10M interactions.
• 2026 models: Claude Sonnet 5 for Socratic reasoning, GPT-5 for math and code, Gemini 2.5 Flash for cheap high-volume dialogue, Llama 4 or Mistral Large 3 on-prem for privacy. Hybrid routing cuts token cost 70–85%.
• The EU compliance clock just moved. The Digital Omnibus deferred the heavy Annex III high-risk duties for education to December 2, 2027; from August 2, 2026 only transparency, GPAI rules and penalties apply. Breathing room, not a reprieve.
• Cost is not the constraint. All-in cost runs $1.12–$3.60 per student per month. The learner model, the curriculum graph and compliance are where the real work and money sit.
Why Fora Soft wrote this playbook
Fora Soft is a software development company, and we have shipped AI-powered learning products since 2005. Our e-learning practice and AI integration line work together on every tutoring engagement: LMS integration, live-class video, speech-to-text, vector stores, learner-model inference, and the unglamorous compliance scaffolding that makes an audit pass. Across 250+ projects since 2005 we have shipped EdTech at scale, from BrainCert (an LMS handling 500M+ classroom minutes) to ALDA, an AI course generator whose institutions serve 500K+ students a year, and Scholarly, which runs live classes for up to 2,000 concurrent students.
Over the past year we have watched the same three mistakes sink tutoring projects: teams bolt a raw GPT-5 prompt onto a curriculum page and call it a tutor, ship a learner model that tracks nothing, or skip curriculum grounding and let the model invent derivative rules. All three are avoidable. This article is what has actually worked for us, with the trade-offs left in. It is a companion to our broader AI tutor and adaptive-learning build guide, which covers the consumer AI-tutor angle in more depth.
Scoping an intelligent tutoring system?
We’ll map your curriculum, learner model and compliance footprint in a single 30-minute call. You leave with a stack recommendation and a realistic budget.
What an intelligent tutoring system actually means in 2026
An intelligent tutoring system is software that teaches one learner at a time the way a good human tutor would: it models what the student knows, decides what to do next, and adapts in real time, without a teacher driving every step. Classically, as the canonical ITS model describes, it has four parts: a domain model, a student model, a pedagogical model and a user interface. In 2026 that grows to five working layers: (1) a learner model that tracks which skills a student has actually mastered, (2) a curriculum graph that defines what is teachable and in what order, (3) a pedagogical model that chooses hint, ask, scaffold or advance, (4) a multimodal interface that accepts voice, handwriting, code and diagrams, and (5) an evaluation layer that measures learning gain and feeds experiments.
The reference point everyone quotes is Bloom’s 1984 “2 sigma” result: one-to-one mastery tutoring moved average students about two standard deviations above a normal class. No software has matched that, but a well-built ITS is the most credible attempt to approach it at scale.
The LLM is one component, not the system. A tutor that is only an LLM wrapped in a pedagogy prompt is fragile. A 2024 Wharton field experiment (Bastani and colleagues, “Generative AI Can Harm Learning”) found that students who practiced with an unguarded GPT-4 scored measurably worse on a later closed-book exam than peers who never used it, because the model did the thinking for them. A guardrailed “tutor mode” version, which withheld answers and asked leading questions, erased that penalty. The difference was not the model. It was the four other layers.
Market: the numbers driving the 2026 category
Every EdTech board we brief opens with the same question: is this still a growth market, or is it peaking? The 2025–2026 data says growth, with the usual caveat that market-sizing estimates vary widely by analyst.
| Metric | 2025–2026 | Source |
|---|---|---|
| AI-in-education market (2026) | ~$10.6B, projected to $42B+ by 2030 | Grand View Research, 2026 |
| AI-tutors sub-segment | ~$2.75B in 2026, ~$17.7B by 2033 | Grand View Research, AI Tutors, 2026 |
| Sub-segment CAGR 2026–2033 | ~30% | Grand View Research, 2026 |
| K-12 students using AI weekly | 26% and climbing (Dec 2024 baseline) | EdWeek Research Center, 2025 |
| Enterprise L&D prioritizing AI upskilling | 47% of leaders, top 18-month priority | LinkedIn Workplace Learning, 2026 |
| Carnegie Learning MATHia | 600K+ students, 2,400+ US schools | Carnegie Learning impact report, 2025 |
| Duolingo Max subscribers | 500K+ paying (early 2026) | Duolingo investor update, Q4 2025 |
Translation for product leaders: the market funds you, the evidence base survives skeptical procurement, and reference deployments at Khan, Carnegie, Duolingo and Squirrel AI give you defensible benchmarks. What kills projects is execution, not market conditions.
The five-layer reference stack
Every production ITS we have shipped maps to the same five layers. When one is weak or missing, that is where audits, teacher complaints or flat learning-gain curves show up first.
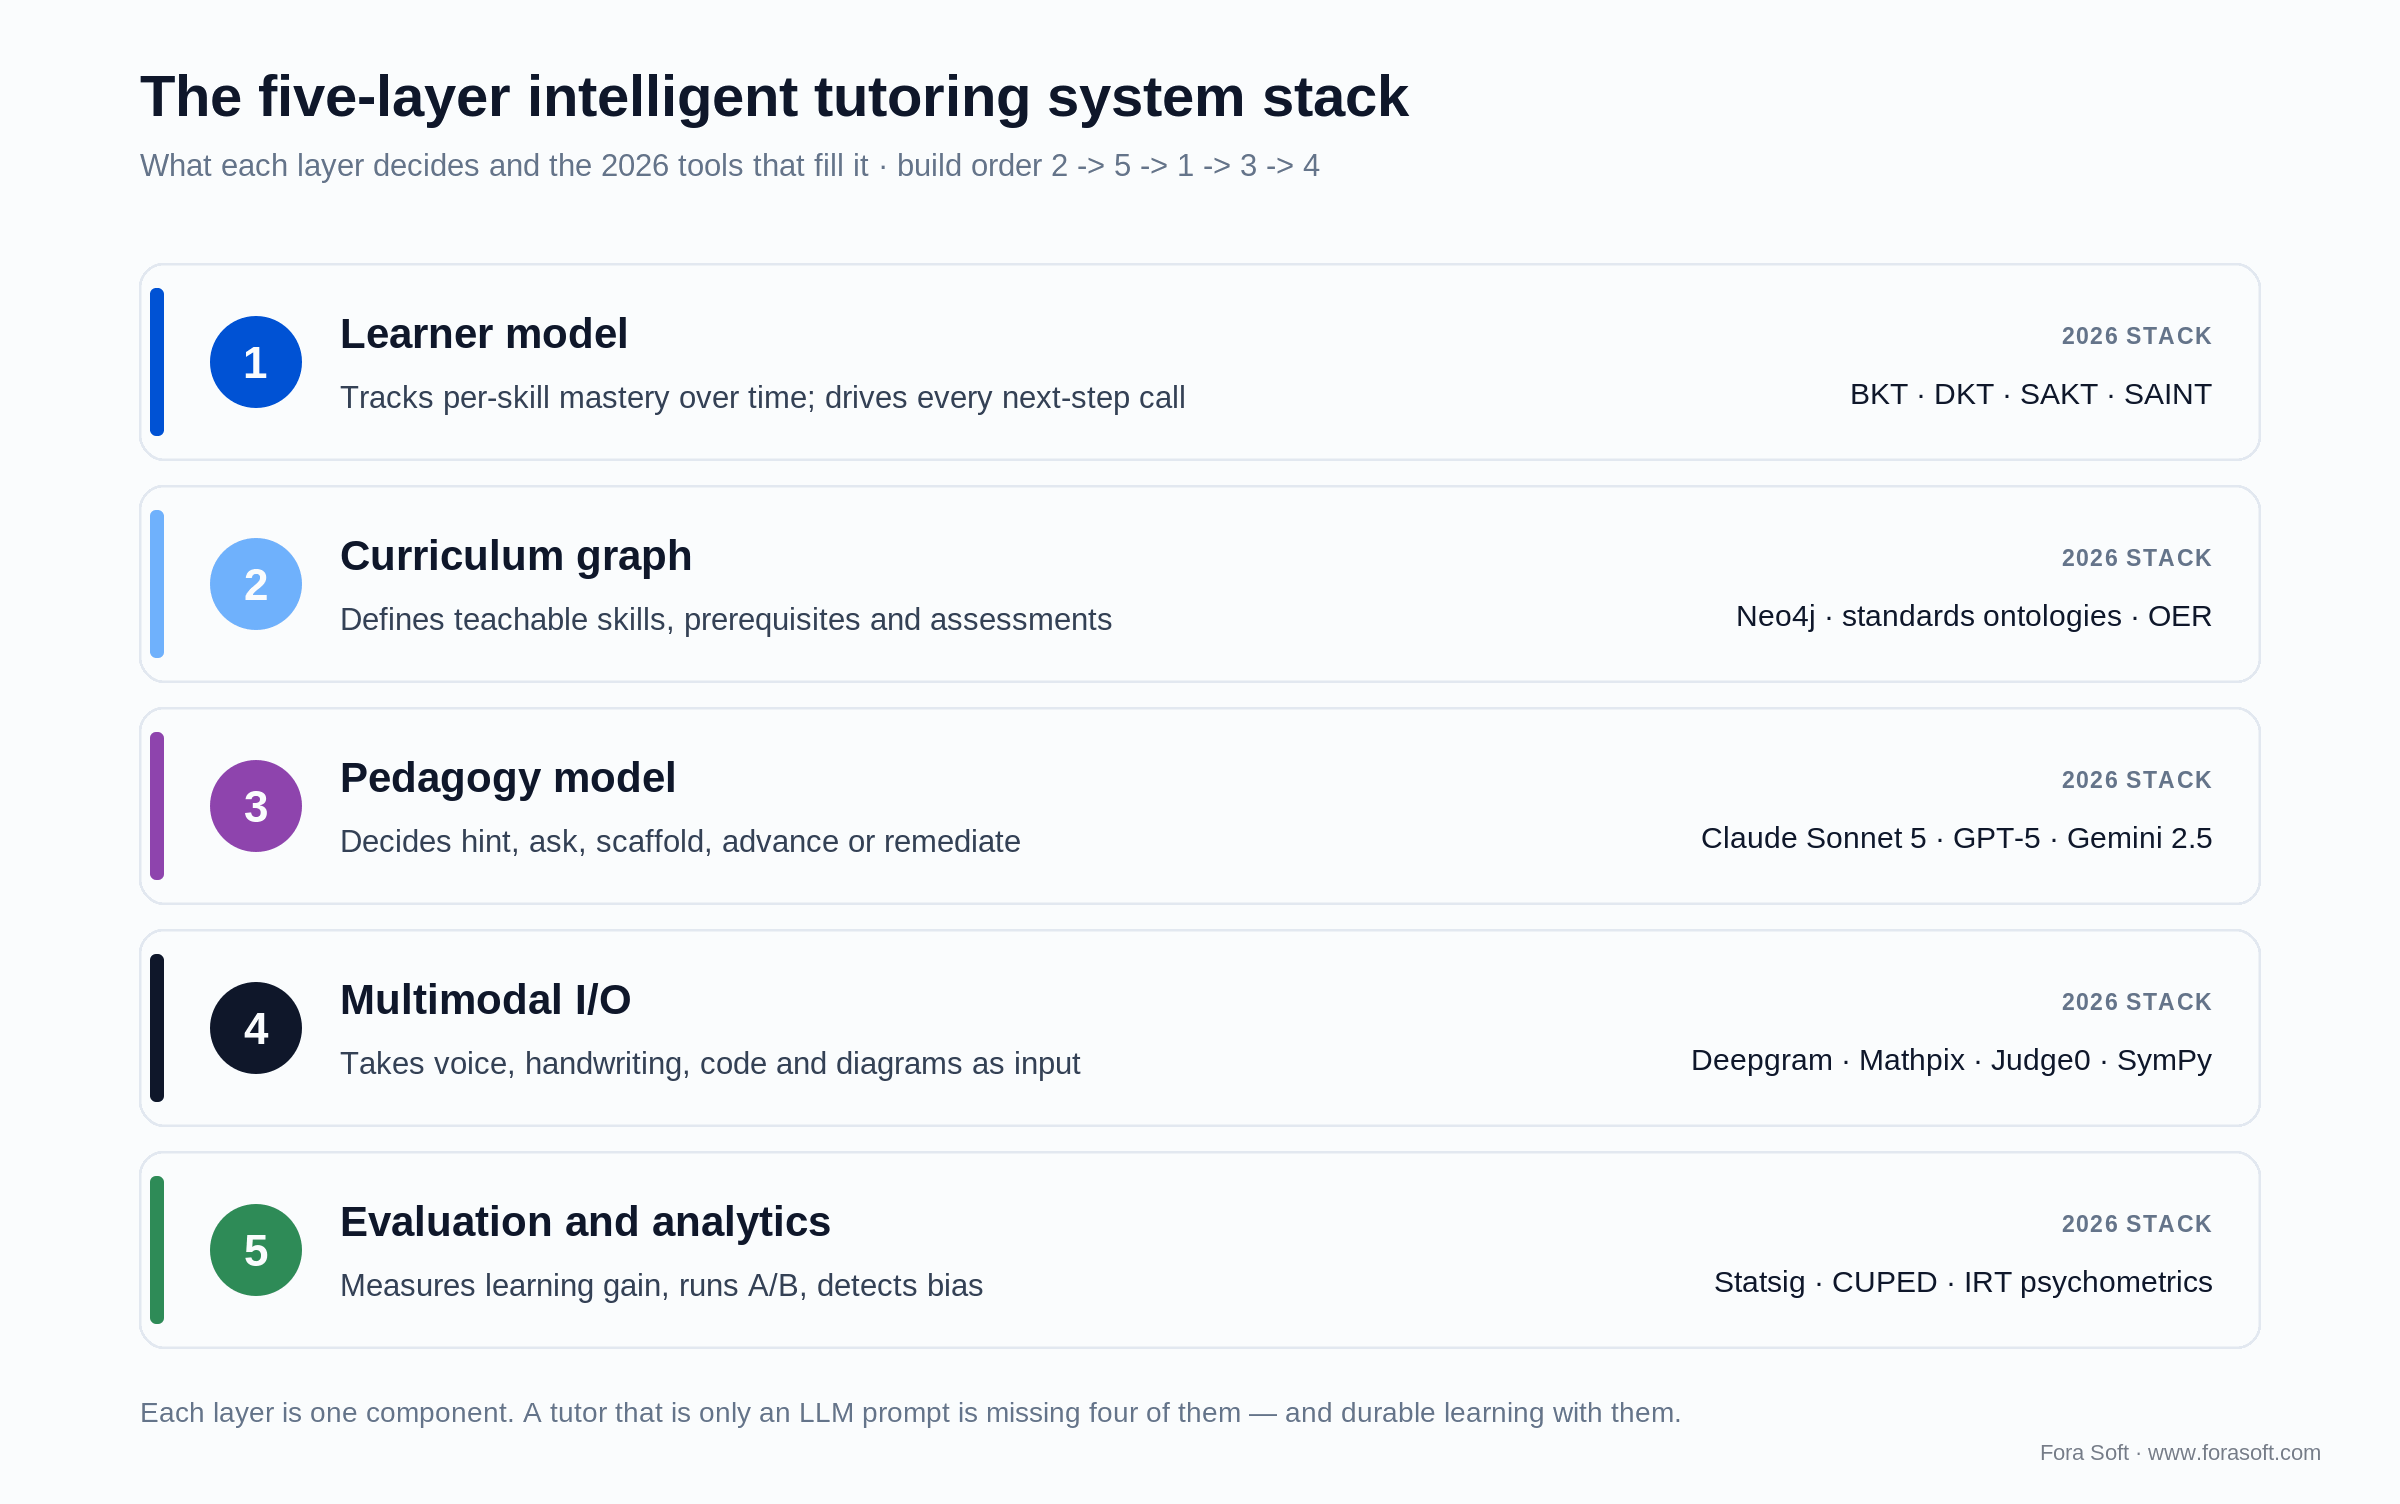
Figure 1. The five layers of a 2026 ITS, the job each one owns, and the tools that fill it.
| Layer | What it does | 2026 tech choices |
|---|---|---|
| 1. Learner model | Track per-skill mastery over time | BKT, DKT, SAKT, SAINT, AKT |
| 2. Curriculum graph | Define teachable skills, prerequisites, assessments | Neo4j, curriculum ontologies, OER Commons metadata |
| 3. Pedagogical model | Decide hint, ask, scaffold, advance, remediate | Claude Sonnet 5, GPT-5, Gemini 2.5 Pro with RAG + learner state |
| 4. Multimodal interface | Voice, handwriting, code, diagrams, math ink | Deepgram Nova-3, Mathpix, Judge0 / Piston, SymPy, Lean 4 |
| 5. Evaluation + analytics | Measure learning gain, run A/B, detect bias | Statsig, GrowthBook, CUPED, IRT psychometrics, Metabase |
The layer teams underestimate most is layer 5. Without it you cannot tell whether a prompt change helped or hurt, so every deploy is a guess. We will not ship an ITS without a CUPED-instrumented experiment pipeline on day one.
Build order we’ve earned the hard way: curriculum graph first (you cannot ground anything without it), then the evaluation pipeline (measure before you learn), then the learner model (the highest-payoff long-term asset), then the pedagogy prompts, and last the multimodal I/O. Teams that start with the prompt usually rebuild the learner model within 90 days.
Knowledge tracing: the quiet center of gravity
Every decision the tutor makes, which problem to serve next, when to hint, when to declare mastery, depends on the learner model. Get this layer wrong and no amount of LLM cleverness saves you. Get it right and even a small model can drive d = 0.6+ gains.
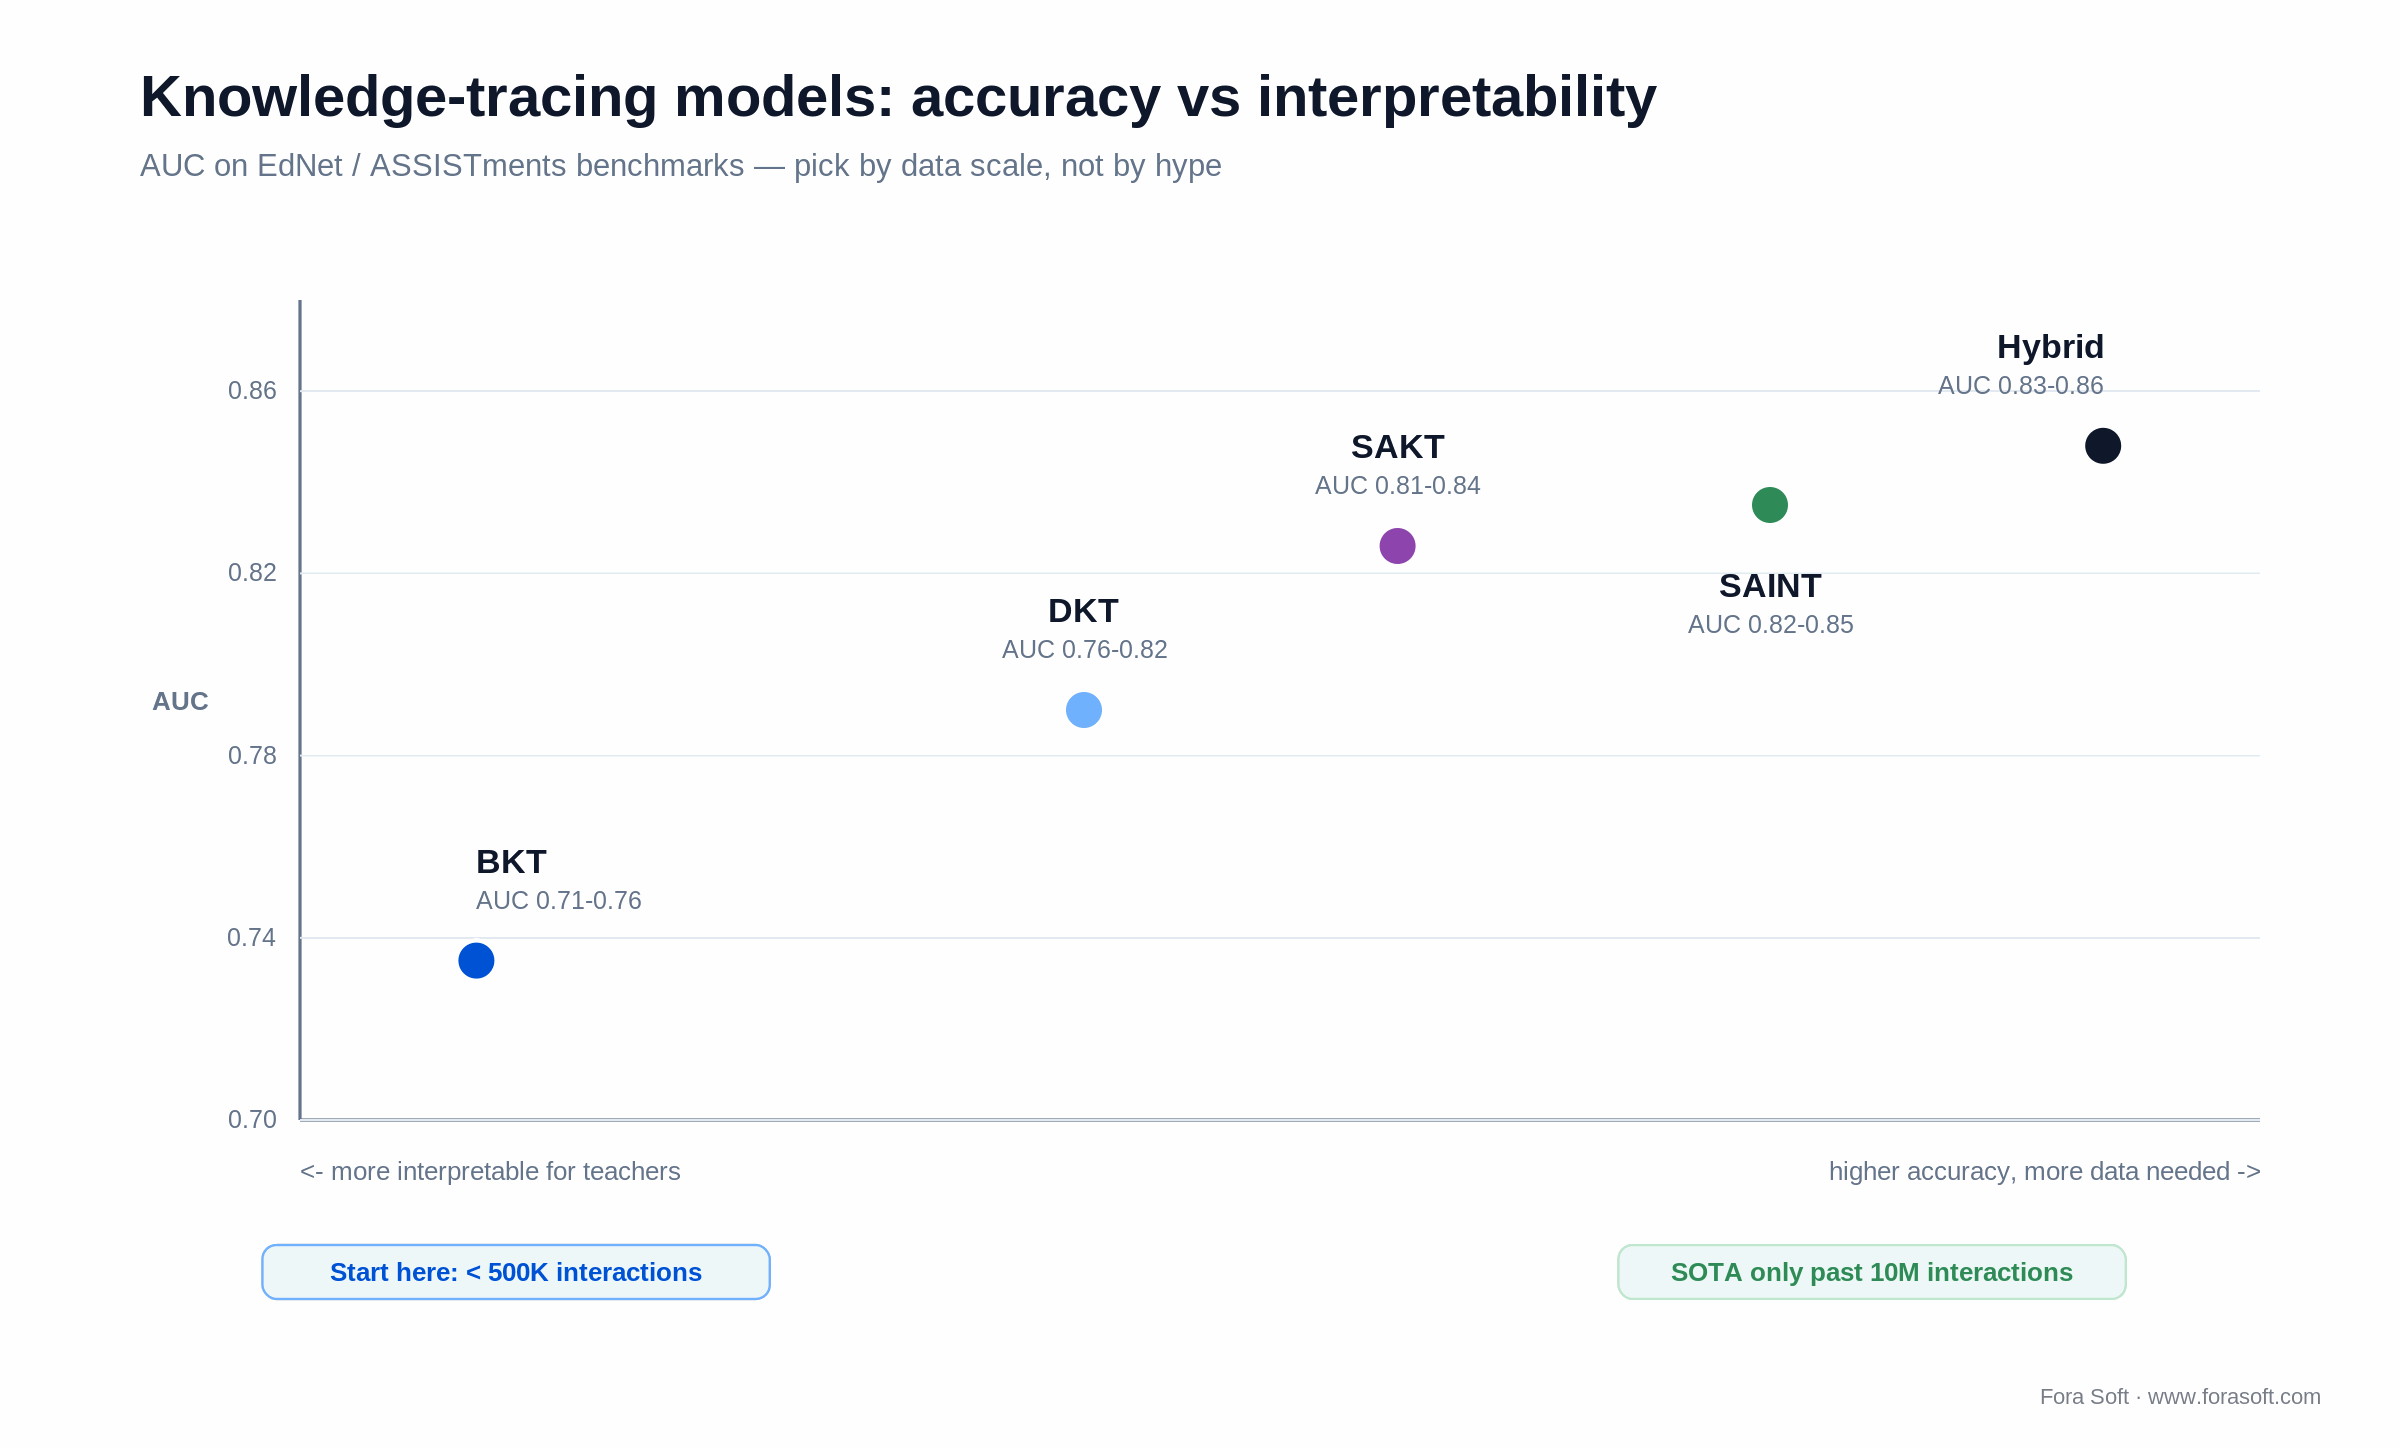
Figure 2. Where each knowledge-tracing model sits on the accuracy-versus-interpretability trade-off.
| Model | Architecture | AUC (EdNet / ASSISTments) | Best for |
|---|---|---|---|
| BKT | 2-state hidden Markov per skill | 0.71–0.76 | Interpretable teacher dashboards, small datasets |
| DKT | LSTM / GRU over interaction history | 0.76–0.82 | Cross-skill transfer, forgetting curves |
| SAKT | Transformer with self-attention | 0.81–0.84 | Explainable attention weights, mid-size datasets |
| SAINT | Transformer, separated Q/A encoders | 0.82–0.85 | Current SOTA at EdNet scale (>10M interactions) |
| AKT | Attention + IRT difficulty estimation | 0.80–0.83 | Adaptive assessment where difficulty matters |
| Transformer×Bayesian hybrid | SAINT backbone, Bayesian last layer | 0.83–0.86 | Accuracy plus calibrated uncertainty (emerging 2025) |
Our default: start with BKT under 500K interactions, graduate to SAKT around 1–5M, and reach for SAINT or a hybrid only past 10M interactions with a dedicated ML engineer watching for drift. Do not invent a custom architecture. Recent work like simpleKT shows a well-tuned standard baseline matches most bespoke designs, and the benchmark gap is almost always smaller than the cost of maintaining something custom. The original Deep Knowledge Tracing paper (Stanford, 2015) is still the reference point for the deep-learning approach.
Which 2026 model fits which tutoring job
There is no single tutor model. Every deployment we run uses two to four models behind a router, chosen by task and by cost. Here is the matrix we brief clients with, priced as of August 2026 (list prices move; treat them as ratios, not contracts).
| Model | Input $/M tokens | Output $/M tokens | Best tutoring job |
|---|---|---|---|
| Claude Sonnet 5 | $2 (through Aug 31, then $3) | $10 (through Aug 31, then $15) | Socratic dialogue, misconception diagnosis, feedback quality |
| Claude Haiku 4.5 | $1 | $5 | Hint generation, summarization, high-volume dialogue |
| GPT-5 | ~$1.25–2.50 | ~$10–14 | Multi-step math, code tutoring, tool use |
| Gemini 2.5 Pro | $2.50 | $15 | Multimodal input (images, diagrams, handwritten work) |
| Gemini 2.5 Flash | cents per M | cents per M | Cheap high-volume dialogue, quick feedback |
| Llama 4 (on-prem) | capex (H200 / B200) | capex | Privacy-sensitive EU, healthcare, government |
| Mistral Large 3 | ~$2 | ~$6 | EU sovereign-cloud, on-prem quantized FP8 |
A typical routing policy: Gemini 2.5 Flash handles ~70% of simple turns (recall, confirmation, short feedback), Claude Sonnet 5 handles ~20% of Socratic dialogue, GPT-5 takes ~8% of heavy math and code, and Gemini 2.5 Pro covers ~2% of multimodal work. That mix lands per-session LLM cost in the $0.005–0.02 range and cuts token spend 70–85% versus routing everything to a frontier model.
Our opinion: start every project with Claude Sonnet 5 as the reasoning layer and Gemini 2.5 Flash as the default dialogue layer, even if you plan to migrate later. Sonnet 5 is the most reliable Socratic tutor we have deployed. It asks the leading question instead of rushing to the answer, and that is the whole game when the goal is durable learning rather than engagement metrics.
RAG and curriculum grounding: the hallucination firewall
An ungrounded tutor will, under pressure, invent plausible but wrong math rules, misattribute historical events, and wander outside the student’s curriculum. Retrieval-augmented generation over a structured curriculum knowledge base is the firewall. It is not optional. The pattern we ship has five steps.
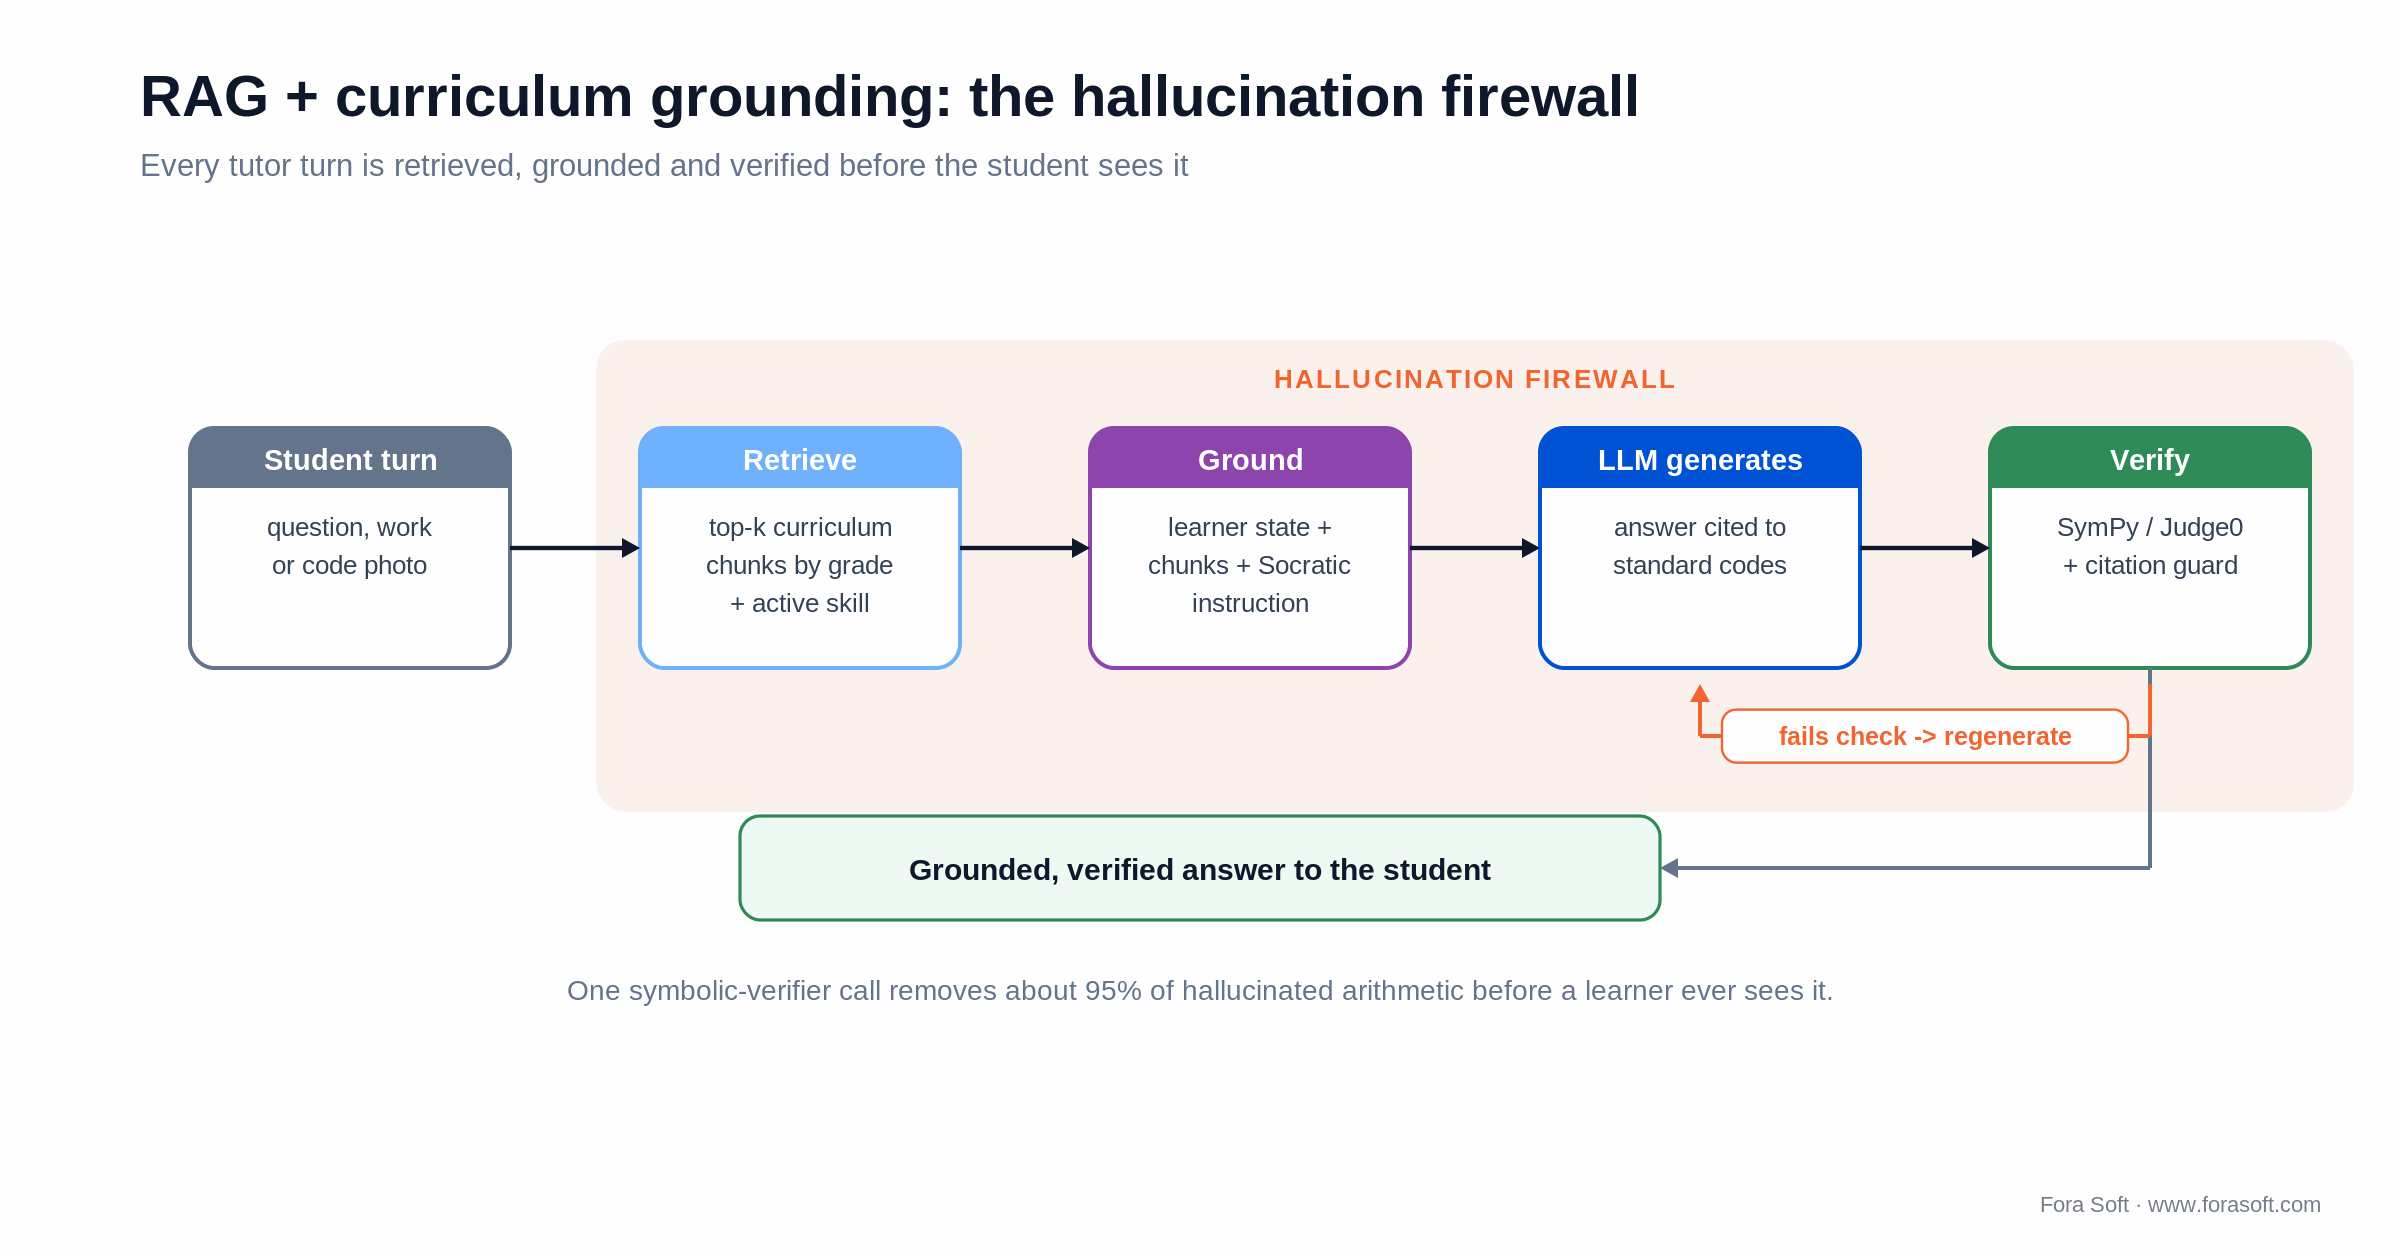
Figure 3. The grounding-and-verification loop that sits between the model and the learner.
1. Curriculum ingestion. Parse adopted standards (Common Core, NGSS, AP syllabi, EU learning-outcome frameworks, internal competency maps) into structured chunks. Tag each with grade band, prerequisite skills, Bloom’s level and worked examples.
2. Embedding. OpenAI text-embedding-3-large for English-heavy curricula, Gemini Embedding for multilingual, Cohere Embed for cost-sensitive builds. Store in Pinecone, Weaviate or Qdrant with metadata filters (grade, subject, standard code).
3. Retrieval. On every turn, pull the top 5–8 most relevant curriculum chunks, filtered to the student’s grade band and the active skill node from the learner model.
4. Grounded generation. Prompt the model with the retrieved chunks, the learner state (mastered versus developing skills) and the pedagogy instruction (“ask a Socratic question, do not solve”). Require citations to standard codes and reject responses that fail the citation guard.
5. Verification. For math and science, route the proposed step through a symbolic verifier (SymPy, Wolfram Alpha, or Lean 4 for proofs). For code, run it in a Judge0 or Piston sandbox before the student sees it. This one pattern removes roughly 95% of hallucinated math.
Multi-modal I/O: the 2026 baseline
Students do not type equations, they write them. They do not type code neatly, they paste messy work in progress. Accessibility rules increasingly require that every task be doable through at least two modalities. A 2026 tutor has to natively consume the inputs below. The speech side connects to the wider AI-for-video-engineering work we publish on real-time audio and ASR.
Voice input. Deepgram Nova-3 for streaming speech-to-text (12–15% word error on real student audio, diarization, 40+ languages) or Whisper v3 for private on-prem. Voice opens K-3 tutoring, dyslexia support and hands-free use. We go deeper on the trade-offs in our podcast accessibility playbook.
Handwriting and math ink. Mathpix converts math to LaTeX at 95%+ on printed equations and about 85% on handwriting. It is the only production-grade option we trust for calculus and matrix work.
Code execution. Judge0 (SaaS, 70+ languages) for most builds, Piston (open source) when on-prem is required. Every submission runs in a sandbox before the tutor comments, which turns “your code has a syntax error” from a guess into a fact.
Multimodal model input. GPT-5, Gemini 2.5 Pro and Claude Sonnet 5 all accept images at production quality, so a student can photograph a whiteboard or paste a diagram and the tutor responds to what it actually sees. For the interaction patterns around this, see our AI accessibility UX guide.
Adaptive assessment: IRT, CAT, and Elo
Item response theory is the quiet workhorse of serious tutoring. Two-parameter IRT (difficulty plus discrimination) is the floor; three-parameter adds a guessing term for multiple choice; multidimensional IRT models several latent skills at once. Computerized adaptive testing uses these models to pick the next item at the point of maximum information, delivering roughly 50% fewer items at the same measurement precision.
For smaller platforms (under ~100K items administered), Elo-style difficulty estimation is simpler to run and lands within about 5% of full IRT on most real tasks. Duolingo, DreamBox and Quizlet all use Elo variants. Start there and move to IRT once you cross ~5M item responses and have an assessment specialist on staff.
Compliance: what actually binds in 2026
Tutoring sits in the regulatory bullseye: education, automated decisions and minors all stack requirements. The headline shifted in July 2026, so read this section carefully if you brief a board on EU timelines.
Under the EU AI Act, an ITS that scores placement, evaluates learning outcomes or runs proctoring is high-risk (Annex III). The heavy obligations for that tier, a risk-management system, a technical file, documented human oversight and post-market monitoring, were originally set for August 2, 2026. The Digital Omnibus package adopted in late July 2026 pushed the Annex III high-risk compliance date to December 2, 2027. From August 2, 2026 the transparency duty (Article 50), general-purpose-AI governance and the penalty regime still apply.
| Regulation | Scope | 2026–2027 date | What it requires |
|---|---|---|---|
| EU AI Act Annex III (high-risk) | ITS used for placement, assessment or proctoring | Dec 2, 2027 (deferred from Aug 2, 2026) | Risk management, technical file, human oversight, post-market monitoring |
| EU AI Act Article 50 (transparency) | AI systems that interact with people | Aug 2, 2026 | Disclose that the learner is interacting with AI |
| GDPR Article 22 | EU users, solely automated significant decisions | In force | Human review of high-stakes decisions (placement, intervention flags) |
| COPPA (amended rule) | US children under 13 | 2026 compliance window | Verifiable parental consent before third-party sharing; no behavioral ads |
| FERPA | US K-12 and higher ed on federal funds | In force | Education-records protection; vendor data-processing agreements |
| ADA Title II + WCAG 2.2 AA | US state/local government, incl. public schools | Apr 24, 2026 (pop >50K) | All digital tools WCAG 2.2 AA; enforced via DOJ complaints |
| California CAADCA + SOPIPA | California users | In force 2026 | Data-protection impact assessments; no data sale |
So the practical read is: the disclosure and penalty pieces are live now, and the documentation-heavy high-risk pieces have slipped by about 16 months. That is breathing room, not a reprieve. The date has already moved once, procurement teams still ask for the technical file, and retrofitting an audit trail is the expensive way to build one.
Compliance shortcut we use: bake the technical file into the engineering workflow from week one. Every learner-model change, prompt revision and dataset update writes to an append-only compliance log, so the client ends up with a complete audit trail instead of a panicked documentation sprint before whichever deadline holds.
Cost and latency economics
LLM tokens are rarely the binding constraint on tutoring unit economics in 2026. Infrastructure, human review and content authoring dwarf them. Here is the breakdown we run for a K-12 math tutor serving 20 sessions per student per month.
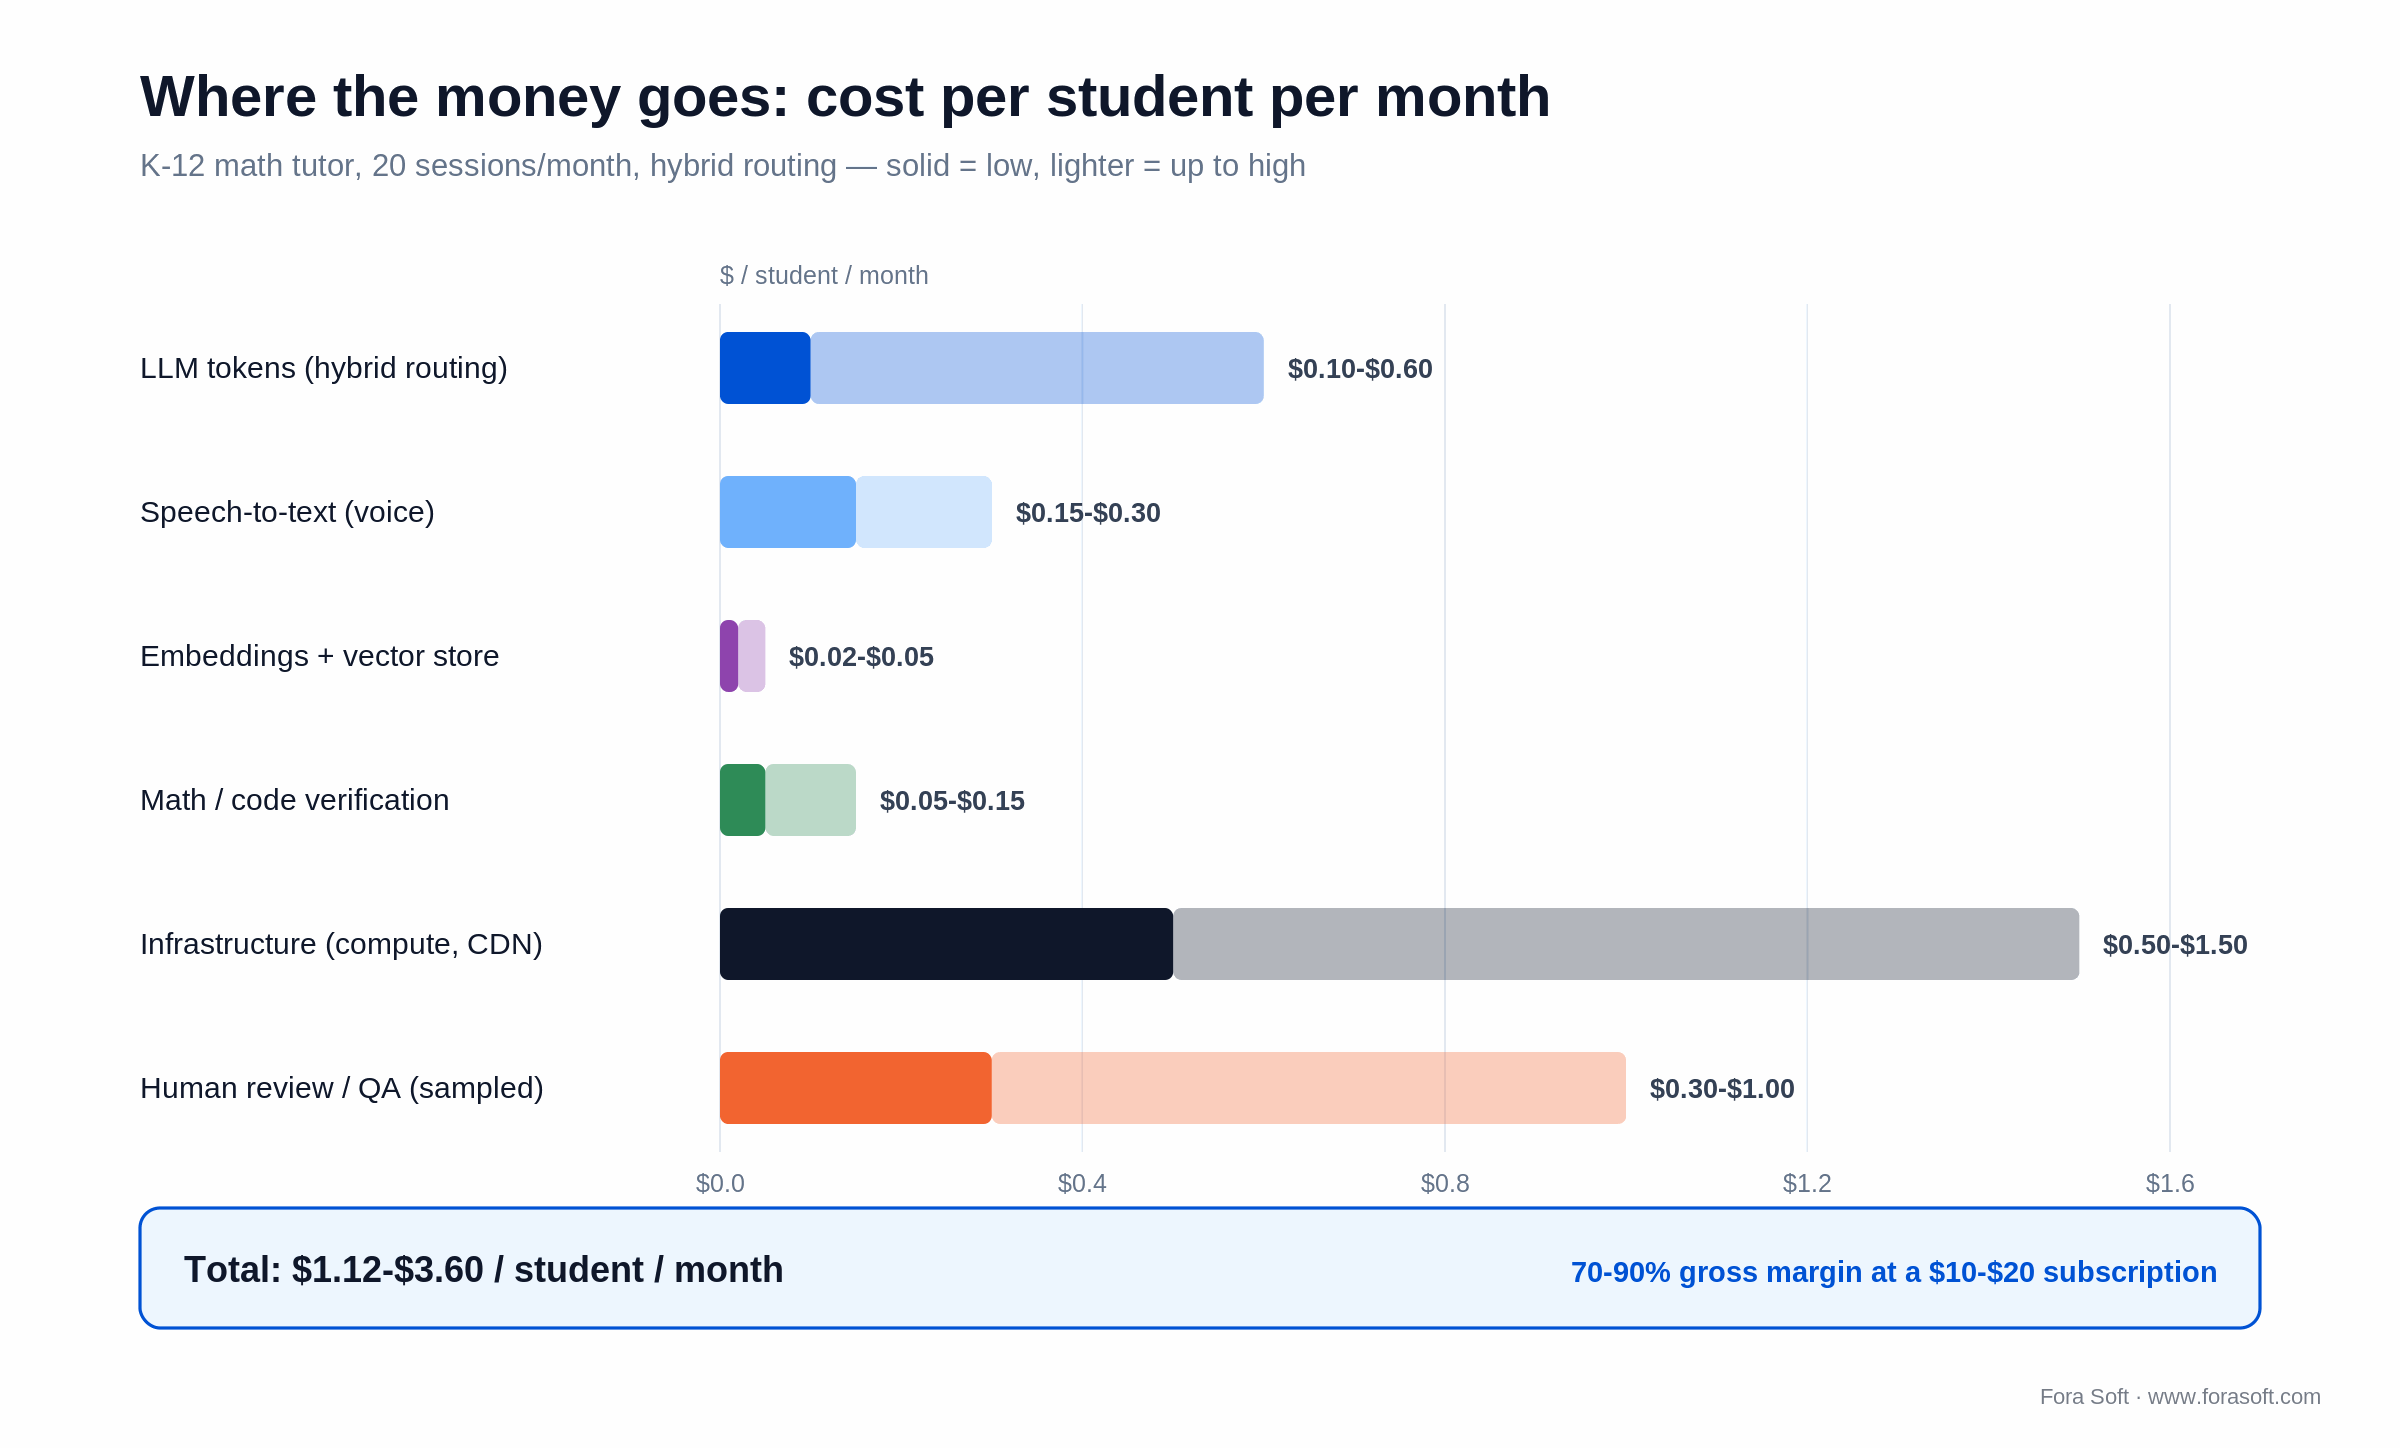
Figure 4. Where the money actually goes, per student per month, low to high estimate.
| Component | Cost per student / month |
|---|---|
| LLM tokens (hybrid routing, 20 sessions) | $0.10–$0.60 |
| Speech-to-text (voice, ~30 min / month) | $0.15–$0.30 |
| Embeddings + vector storage | $0.02–$0.05 |
| Math / code verification APIs | $0.05–$0.15 |
| Infrastructure (compute, storage, CDN) | $0.50–$1.50 |
| Human review / QA (sampled) | $0.30–$1.00 |
| Total per student / month | $1.12–$3.60 |
In plain terms: a production K-12 ITS costs $1.12–$3.60 per student per month all-in, which is a 70–90% gross margin at a $10–20 subscription. At a $50–150 per-year district seat the math is similar. The economics work. The real strategy question is ARPU versus volume, not cost of goods.
Mini case: a European reskilling platform ships an ITS in 12 weeks
A Fora Soft client in European insurance needed to reskill ~5,000 claims handlers on Python data literacy inside their own 2026 AI-readiness program. Classroom training had cost €1.2M in 2025 and moved completion from 34% to 41%. They asked for a tutor that scaled without adding classroom hours.
What we shipped in 12 weeks:
- Learner model: SAKT over the client’s Python competency map (48 skills, 380 items, ~2,000 training interactions from an earlier pilot).
- Curriculum graph: Python.org reference plus internal data-handling standards, embedded with text-embedding-3-large into Weaviate.
- Pedagogy: Claude Sonnet 5 with a Socratic prompt, grounded by top-6 retrievals and the student’s mastery vector; Gemini 2.5 Flash for recall and quick feedback.
- Multimodal: Jupyter-style cells executed in Piston (on-prem for privacy); voice Q&A via Deepgram Nova-3.
- Evaluation: Statsig-powered CUPED tests on prompt variants; pre/post assessment with IRT-scored difficulty.
- Compliance: EU AI Act technical file drafted from day one, GDPR Article 22 human-review step on any at-risk-learner flag, WCAG 2.2 AA audit passed.
Results after four months: completion rose from 41% to 63% (+22 points), time-to-mastery fell 31%, and cost per completion dropped from €350 (classroom) to €58 (tutor plus sampled human review). The client’s data-protection officer signed off the technical file in week 11, well ahead of any EU deadline. Want a similar assessment? Book a 30-minute call and we’ll walk your numbers.
Five pitfalls that kill intelligent-tutoring projects
1. “We’ll just prompt GPT.” This is the unguarded-AI outcome from the Wharton study: short-term engagement, then a learning penalty when the crutch is removed. Without a learner model, grounding and Socratic scaffolding, an LLM is a homework-completion service, not a tutor.
2. Skipping the symbolic verifier. Models are confident and often wrong on arithmetic, algebra and calculus. A SymPy or Wolfram Alpha call before the answer reaches the student is cheap insurance. Skip it and you will teach a cohort that 2/3 + 1/4 = 3/7, confidently.
3. No teacher override. Teachers need to see the learner state, disagree with it, and move a student forward or back by hand. Tutors that hide this become teacher-hostile, and adoption dies in the staff room.
4. Ignoring accessibility until launch. ADA Title II with WCAG 2.2 AA is the new floor for US public schools. Retrofitting accessibility costs three to five times what designing it in costs, and the April 24, 2026 deadline is a hard line, not a target.
5. Flying blind on learning gain. If you cannot tell whether prompt v18 tutors better than v17, you are guessing. CUPED-instrumented A/B testing on learning gain, not just engagement, is not optional.
Budget heuristic we use: for a mid-sized engagement (single subject, 10–50 skills, 5K–50K learners) plan €180K–€400K over 10–14 weeks, split roughly 40% engineering, 25% curriculum and content, 20% compliance and accessibility, 15% evaluation. Anyone quoting far less is usually skipping the learner model or compliance, and you pay for both later at 3× the cost.
KPIs: what to measure
Learning gain (normalized, or Cohen’s d) is the only metric that matters in the long run. Engagement can move without learning improving, and the reverse. A production tutor usually reports:
- Normalized learning gain. (posttest% − pretest%) / (100 − pretest%); target above 0.40.
- Cohen’s d versus control. Target above 0.5 versus traditional instruction; the literature ceiling is about 0.8.
- Completion rate. Share of enrolled learners reaching mastery on the target skill set.
- Time-to-mastery. Median minutes per skill; expect a 15–30% drop versus a non-adaptive baseline.
- Hint-use calibration. Share of learners at 2–4 hints per problem (the healthy band); above 5 signals over-scaffolding.
- Hallucination rate. Share of tutor responses flagged wrong by the verifier or a human; target under 1% for K-12 math.
- Accessibility conformance. WCAG 2.2 AA automated and manual pass rate; target 100%.
- Teacher override usage. Share of cohorts where teachers touch the learner model; a healthy 10–25%.
When not to build an ITS in-house
Do not build if any of these hold: you have fewer than 1,000 learners and no clear path to 10K; your curriculum changes more than twice a year; your team has no ML engineer and no plan to hire one; your subject has no symbolic verifier and you can tolerate 5–15% hallucination; or your procurement cannot absorb the eventual EU high-risk documentation. In those cases, license Khanmigo, MATHia, Century Tech or a domain vendor and spend your engineering on integration. The figure below is the version of this call we walk clients through.
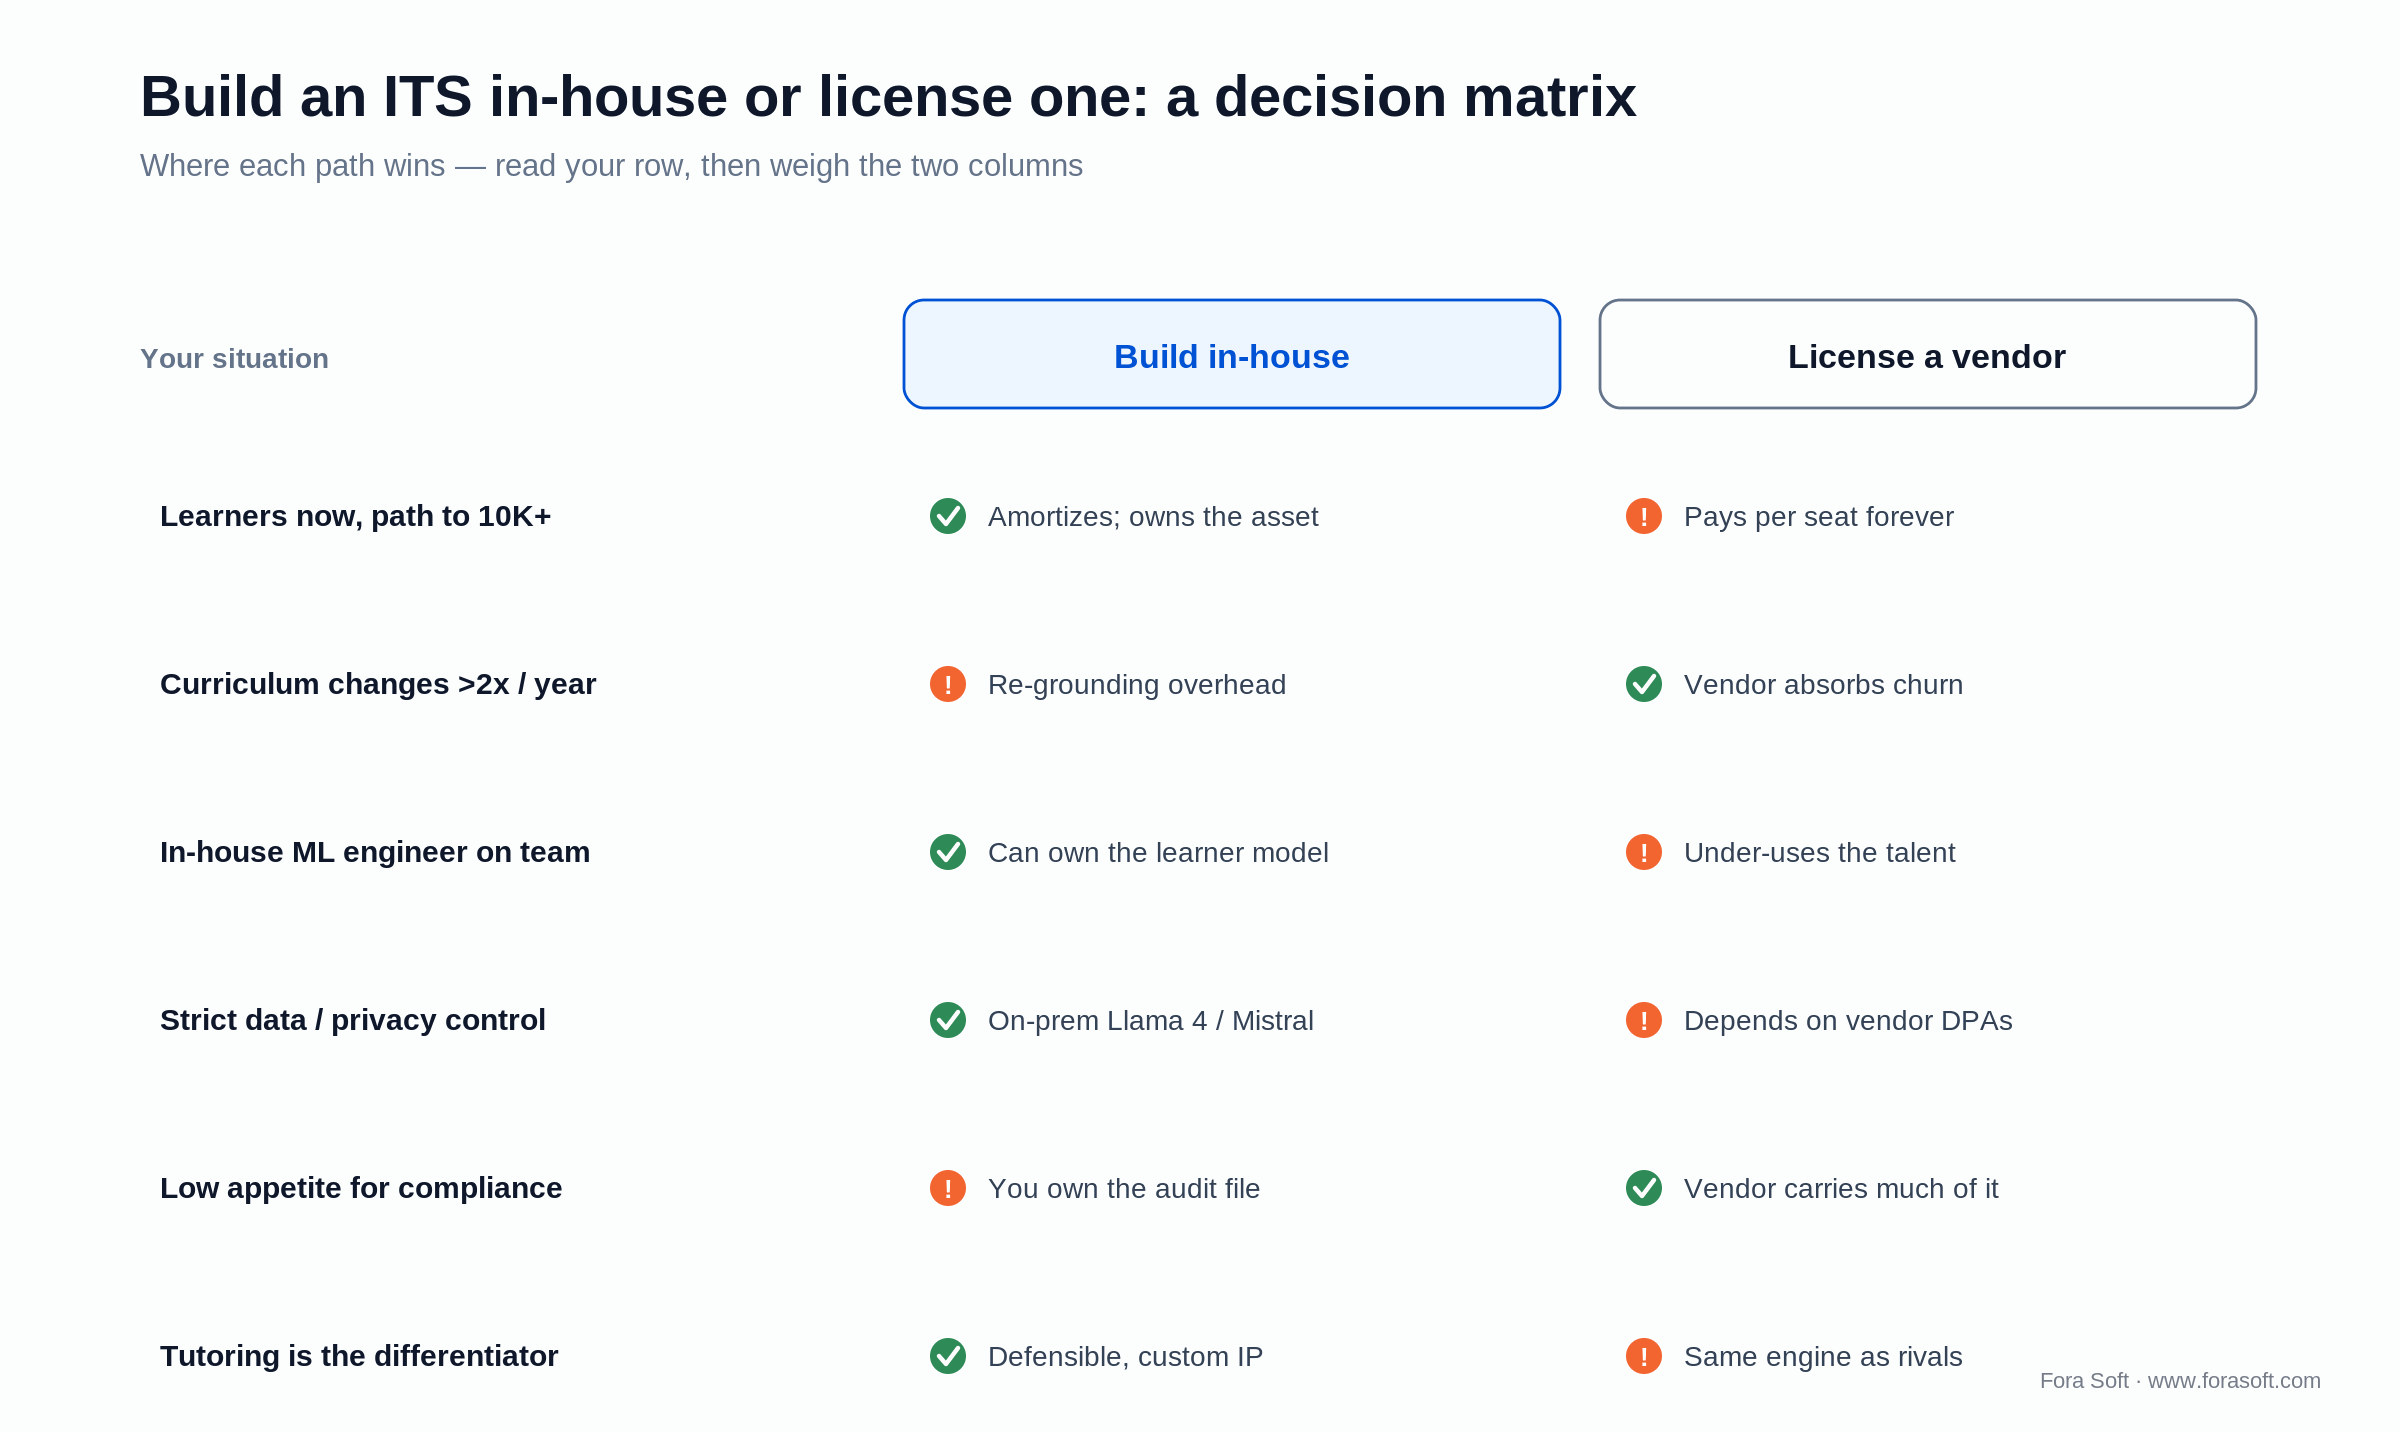
Figure 5. Read your row, then weigh building in-house against licensing a vendor.
A decision framework: pick your stack in six questions
Answer these before writing a line of code:
- 1. What subject and grade band? Math and STEM need a symbolic verifier; humanities need RAG plus rubric scoring; language learning needs pronunciation and dialogue; coding needs sandboxed execution.
- 2. How much interaction data do you have? Under 500K goes to BKT; 1–10M to SAKT; over 10M to SAINT or a hybrid.
- 3. What is the jurisdiction? EU means budget the Annex III technical file even with the 2027 date; US K-12 means COPPA, FERPA and ADA; California adds CAADCA.
- 4. What is the privacy profile? Enterprise, government or healthcare points to on-prem Llama 4 or Mistral Large 3; consumer EdTech can use API models with data-processing agreements.
- 5. Which modalities are required? Voice plus handwriting plus code raises engineering effort by roughly 30% over text-only.
- 6. What is the success metric? Engagement, completion or learning gain? Only the third justifies the full stack; the first two can often be served by a lighter adaptive-content system, and we’ll tell you honestly which one you need.
Want us to run this framework with you?
Thirty minutes, live walkthrough, no pitch. You leave with a stack recommendation and a realistic budget.
Integration playbook: the 10–14-week path
Every engagement we run follows the same phased path. The duration flexes for scope, not for structure.
| Week | Phase | Deliverables |
|---|---|---|
| 1–2 | Discovery + compliance scoping | Curriculum graph v0, compliance matrix, LMS integration plan |
| 3–4 | RAG + embeddings | Vector DB populated, retrieval evaluation, citation guards |
| 5–6 | Learner model | BKT or SAKT trained, AUC baseline, mastery threshold tuning |
| 7–8 | Pedagogy + multimodal | LLM router, Socratic prompts, STT / math ink / code exec wired |
| 9–10 | Evaluation + A/B | Statsig or GrowthBook, CUPED, learning-gain instrumentation |
| 11–12 | Compliance + accessibility | Technical file, WCAG 2.2 AA audit, FERPA / COPPA sign-off |
| 13–14 | Rollout + teacher enablement | Teacher dashboards, training, monitoring, SLA handover |
Where ITS is heading in 2026–2027
Agentic tutors. The next step is not a better single prompt but a planner-executor loop: the tutor sets a session goal, picks tools (retrieval, verifier, code sandbox, math renderer) and checks its own progress. Claude Sonnet 5 and GPT-5 are already good enough for this in production.
Long-term learner memory. Instead of re-grounding every session, the tutor keeps a per-student memory that spans months, which improves recall of prior misconceptions and cross-skill transfer, and raises the bar for deletion workflows (GDPR erasure, COPPA parental access).
Open-weight parity for narrow tutoring. Llama 4 and Mistral Large 3 are within about 10% of frontier models on curriculum-grounded tasks, and the gap keeps closing. Expect sovereign-cloud and on-prem deployments to gain share through 2027.
Predictive learner trajectories. Pairing knowledge tracing with the predictive-UX patterns we covered for SaaS lets a tutor anticipate disengagement, step in early, and schedule reviews against forgetting curves.
FAQ
Does an intelligent tutoring system replace teachers?
No. Every production ITS we deploy is built around teacher control: dashboards, overrides, intervention flags. VanLehn’s 2011 meta-analysis put step-based tutoring at d = 0.76 and human tutors at 0.79. The win is not replacement, it is scaling individual practice to every student in a class.
Can we just use ChatGPT with a custom prompt?
You can ship something that looks like a tutor, but it will not produce durable learning. The 2024 Wharton study found students using an unguarded GPT-4 did worse on a later closed-book exam; a guardrailed tutor-mode version removed the penalty. The engineering difference is the learner model, RAG, symbolic verification and an evaluation loop.
What is an intelligent tutoring system, in one sentence?
It is software that models what a learner knows, decides what to teach next, and adapts in real time across five layers, a learner model, a curriculum graph, a pedagogy model, a multimodal interface and an evaluation loop, without a teacher driving every step.
BKT or deep knowledge tracing, which do we start with?
BKT if you have under 500K interactions or need interpretable teacher dashboards. SAKT once you cross ~1M interactions and have an ML engineer. SAINT only at EdNet scale (over 10M). The accuracy gains from more complex models are real but marginal next to better grounding and pedagogy.
How do we stop the tutor hallucinating math?
Route every candidate answer through a symbolic verifier before the student sees it. SymPy is free and covers K-12 through undergraduate algebra and calculus; Wolfram Alpha adds coverage; Lean 4 handles proofs. This one pattern removes about 95% of hallucinated arithmetic.
Is my ITS high-risk under the EU AI Act, and when does that bind?
If it makes placement, admission or assessment-scoring decisions, or proctors exams, yes, Annex III lists it as high-risk. After the Digital Omnibus, the heavy obligations bind December 2, 2027 rather than August 2, 2026; the Article 50 transparency duty applies from August 2, 2026. Pure practice-feedback tutors without automated decisions are usually limited-risk.
What is a realistic Cohen’s d for an ITS we build?
0.5–0.7 is a well-engineered production outcome. 0.7–0.8 is the literature ceiling, reached by systems with years of tuning like MATHia and ASSISTments. Any claim above d = 1.0 without a decade of evidence is almost certainly measurement error or selection bias.
Can an ITS work for corporate L&D, not just K-12?
Yes, and it is often easier: cleaner objectives, measurable business KPIs, and fewer minors to protect. The stack transplants cleanly; what changes is the curriculum (competency frameworks instead of Common Core) and the assessment (job-task simulation instead of standardized tests). The mini case above is exactly this pattern.
What to read next
If this playbook helped, these Fora Soft deep-dives fit naturally next to it.
EdTech
AI tutor and adaptive learning: 2026 build guide
The consumer AI-tutor angle, adaptive learning, and where it meets an ITS.
EdTech
AI study-guide maker
How the content-generation layer pairs with an ITS learner model.
EdTech
AI lesson-plan generator
Turning a curriculum graph into teacher-ready lesson plans.
Analytics
AI video analytics for online learning
Engagement measurement and attention tracking for video-based courses.
Summing up
Intelligent tutoring in 2026 is a five-layer infrastructure problem: a learner model that tracks mastery, a curriculum graph that scopes the subject, a pedagogy model grounded by RAG and checked by symbolic tools, a multimodal interface that takes voice, handwriting and code, and an evaluation layer that measures learning gain. Teams that ship all five reliably reach Cohen’s d = 0.5–0.7 and keep cost under $3.60 per student per month. Teams that ship only the LLM layer produce engagement without durable learning, and sometimes worse.
The good news: the reference stack is settled, the evidence base is strong, and the 10–14-week path is well understood. The EU high-risk deadline just moved to December 2, 2027, which buys documentation time but not a reason to wait. Build the learner model and the audit trail now.
Ready to scope your intelligent tutoring system?
Thirty minutes on your learner model, curriculum graph, compliance footprint and a realistic budget. No slide deck.

