

Updated October 2026: Opus 1.6 neural bandwidth extension and a 3× smaller DRED model, LRAC 2025–2026 low-resource codec results, Mimi 80 ms streaming latency, and the 2026 speech tokenizers (Qwen3-TTS 12.5 Hz, NeuCodec 0.8 kbps).
Why this matters
Short answer: a neural audio codec is a codec whose encoder and decoder are trained neural networks. The encoder turns sound into a short stream of discrete tokens, usually through residual vector quantization, and the decoder rebuilds audio from those tokens. The reference systems are Google's SoundStream (2021) and Lyra v2 (2022), Meta's EnCodec (2022), Descript's DAC (2023) and Kyutai's Mimi (2024). At equal listening quality they need about three to four times fewer bits than Opus, but every frame costs far more processor time. As of October 2026 their main job is tokenizing speech for voice AI, while Opus, which added small neural modules of its own in versions 1.5 (2024) and 1.6 (December 2025), still carries most real-time calls. For a one-line definition, see our neural codec glossary entry.
If you build anything that carries voice or sound — a conferencing app, a streaming service, a telemedicine platform, a voice assistant — you will keep hearing that "neural codecs" are about to change everything, and you need to know whether that is true for your product or just a conference-talk headline. The honest answer in 2026 has two halves. For raw real-time calling, the 2012-standardised Opus codec is still the right default, and a neural codec is a research line item, not a shipping decision. But for anything that touches voice AI — a model that listens and talks back, automatic dubbing, on-device speech generation — neural codecs are already the foundation, because they are how sound gets into and out of a language model. This article is for the product manager, founder, or engineer who has to tell the difference: what these systems do, what they cost, where they actually ship today, and what the next three years hold. It is the deep-dive companion to our survey of AI in audio for video, which sketched neural codecs as one of four families; here we open the box.
What a codec is, and what makes a neural one different
Start with the ordinary kind. A codec — short for coder-decoder — is the software that compresses sound into fewer bits to send or store, then unpacks it again at the other end. Every voice call and every streamed song uses one. For about forty years, codecs were designed by hand: engineers studied how human hearing works, noticed that we cannot hear a quiet tone right after a loud one, and wrote algorithms that throw away the sounds the ear will not notice. That is the family that gave us MP3, AAC, and Opus, and we explain the machinery in how audio compression works. It is brilliant engineering, and it is hand-built, brick by brick, by people.
A neural audio codec replaces the human designers with a learning process. Instead of an engineer deciding which parts of the sound to keep, you take a neural network — a mathematical model with millions of adjustable numbers — and show it enormous quantities of audio until it discovers, on its own, how to represent sound compactly and rebuild it. Nobody writes the rules; the model learns them from data. The result is a codec that can hit bitrates the hand-built ones cannot touch at the same quality, because the network finds patterns in real sound that no human thought to encode by hand.
The analogy worth keeping: a traditional codec is like a translator who learned grammar from a rulebook, and a neural codec is like one who grew up bilingual. The rulebook translator is fast, predictable, and cheap. The bilingual one is more fluent, catches nuances the rules miss — and is far more expensive to train and to run. That cost difference, as we will see, is the whole story of why neural codecs have not yet taken over.
The one idea that made it work: residual vector quantization
Almost every neural codec you will read about — SoundStream, Lyra, EnCodec, the newest research systems — is built on the same three-part shape, and one of the three parts is the clever bit that made the whole field practical. Walk through it slowly, because once you have it, every codec in this article is a variation on it.
First, an encoder: a neural network that takes the raw sound wave and squeezes it down into a compact stream of numbers, called a latent representation. Think of it as the network's private shorthand for "what this sound is." Last, a decoder: a mirror-image network that takes the shorthand and reconstructs the sound wave you can actually play. Encoder and decoder are trained together, end to end, so the shorthand the encoder writes is exactly the shorthand the decoder knows how to read.
The middle part is where the difficulty — and the cleverness — lives. The encoder's shorthand is made of continuous numbers, like 0.3719 or −1.882, and you cannot send numbers of infinite precision over a network. You have to round them to a fixed menu of allowed values, a process called quantization. The catch is brutal: to represent rich, high-quality sound, you would need a menu of millions of possible values, and a menu that big is too expensive in memory and computation to use.
The breakthrough, introduced for audio in SoundStream in 2021, is called residual vector quantization, or RVQ, and it works like making change with coins. Suppose you owe \$8.37 and your first "coin jar" only holds dollar coins. You pay \$8, and you are left with a residual of \$0.37 that you could not represent. So you go to a second jar that holds dimes, pay three (\$0.30), and your residual shrinks to \$0.07. A third jar of pennies clears the rest. Each jar is small and cheap, but stacked in layers they represent any amount precisely. RVQ does exactly this with sound: the first quantizer captures the rough shape, the second captures the error the first one left behind, the third captures the error after that, and so on through a stack of layers. A handful of small menus, stacked, do the work of one impossibly large one.
 Figure 1. The shared shape of every neural codec: a learned encoder, a stack of residual quantizers that refine the signal layer by layer, and a learned decoder. Using fewer quantizer layers lowers the bitrate on the spot.
RVQ has a second gift that turns out to matter enormously in practice. Because the layers refine the sound progressively, you can simply stop early. Use all the layers and you get the highest quality at the highest bitrate; drop the bottom few layers and you get lower quality at a lower bitrate — from the same model, decided on the fly. This is why a single neural codec can offer several bitrates without shipping several models. SoundStream's authors trained one model that runs anywhere from 3 to 18 kbps with almost no penalty versus models trained for each rate separately. Hold onto that property; it is the reason these codecs adapt so gracefully to bad networks.
One more piece, because it explains why the rebuilt sound is convincing rather than muffled. Early attempts to reconstruct audio from a tiny representation came out dull and blurry. The neural codecs fixed this by borrowing a technique from image generation called adversarial training: alongside the decoder, you train a second network — a discriminator — whose only job is to tell real recordings apart from the decoder's reconstructions. The decoder is then pushed to fool the discriminator. The two networks chase each other, and the decoder learns to produce sound crisp enough to pass as real. That adversarial push is what separates a 2021-and-later neural codec from the muddy autoencoders that came before.
The three codecs that built the field
SoundStream — the one that started it
SoundStream, published by Google researchers in 2021, is the foundation everything else stands on. It was the first end-to-end neural codec to combine all three ideas above — a learned convolutional encoder-decoder, residual vector quantization, and adversarial training — into one system that clearly beat the hand-built codecs. The headline result is the number you will see quoted everywhere: in listening tests on 24 kHz audio, SoundStream at 3 kbps outperformed Opus at 12 kbps, and approached the quality of the EVS speech codec at 9.6 kbps, using three to four times fewer bits for the same perceived quality. It also ran in real time on a smartphone processor and could fold noise suppression into the same pass, cleaning the audio for free while it compressed.
SoundStream did not ship as a consumer product under that name. Its importance is as the blueprint: RVQ-for-audio was its contribution, and every codec below inherits it.
Lyra v2 — the one that actually ships
Lyra v2 is Google's production speech codec, and it is SoundStream made practical. Released in September 2022, it is built directly on the SoundStream architecture, with the residual quantizer sitting on each side of the transmission link. It offers three bitrates — 3.2, 6, and 9.2 kbps — and you can switch between them mid-call simply by changing how many quantizer layers you use, the RVQ property from the section above doing real work in a real product.
The quality numbers are specific and worth stating plainly. In Google's listening tests, Lyra v2 at 3.2, 6, and 9.2 kbps matched the quality of Opus at 10, 13, and 14 kbps respectively. Put differently, Lyra delivers Opus-grade speech using roughly half to sixty percent of the bandwidth. Against the telephony codecs it is meant to replace, it outperforms EVS and AMR-WB while using a fraction of their bits.
But the number that explains why Lyra matters is not about bitrate at all — it is about speed. On a Pixel 6 Pro phone, Lyra v2 encodes and decodes a 20-millisecond frame of audio in 0.57 milliseconds, which is about 35 times faster than real time, and its algorithmic delay is 20 milliseconds, comparable to Opus. Google built Lyra specifically so a neural codec could run on an ordinary phone without draining the battery or adding lag. That engineering — not the research quality — is what let it ship: Google Meet uses Lyra to carry speech when bandwidth is limited. The open-source Lyra codec library, however, has had no release since version 1.3.2 in December 2022, so treat it as a stable reference implementation rather than an actively developed project (status checked October 2026). Lyra is the existence proof that a neural codec can be a product. It is also, tellingly, still the exception rather than the rule.
EnCodec — the one that handles music
EnCodec (EnCodec in our glossary), from Meta in October 2022, took the SoundStream shape and pushed the quality ceiling up, especially for music. Where SoundStream and Lyra target speech, EnCodec was built to handle the full range: 24 kHz mono speech at the low end and 48 kHz stereo music at the high end, at bitrates from 1.5 up to 24 kbps. In MUSHRA listening tests — the standard method for subjective audio quality testing — EnCodec scored higher than SoundStream at matched bitrates, and at 3 kbps it beat both Lyra v2 at 6 kbps and Opus at 12 kbps.
EnCodec added two refinements worth knowing. It used a single multi-scale spectrogram discriminator to make training simpler and faster, and a "loss balancer" that kept the training stable. And it showed that you could bolt a small Transformer model onto the codec's output to squeeze the bitstream a further 25 to 40 percent — turning a 3 kbps stream into roughly 1.9 kbps — while still running faster than real time. That last trick is a preview of where the field went next: treating the codec's output not as a final bitstream but as a language that another model can compress and predict.
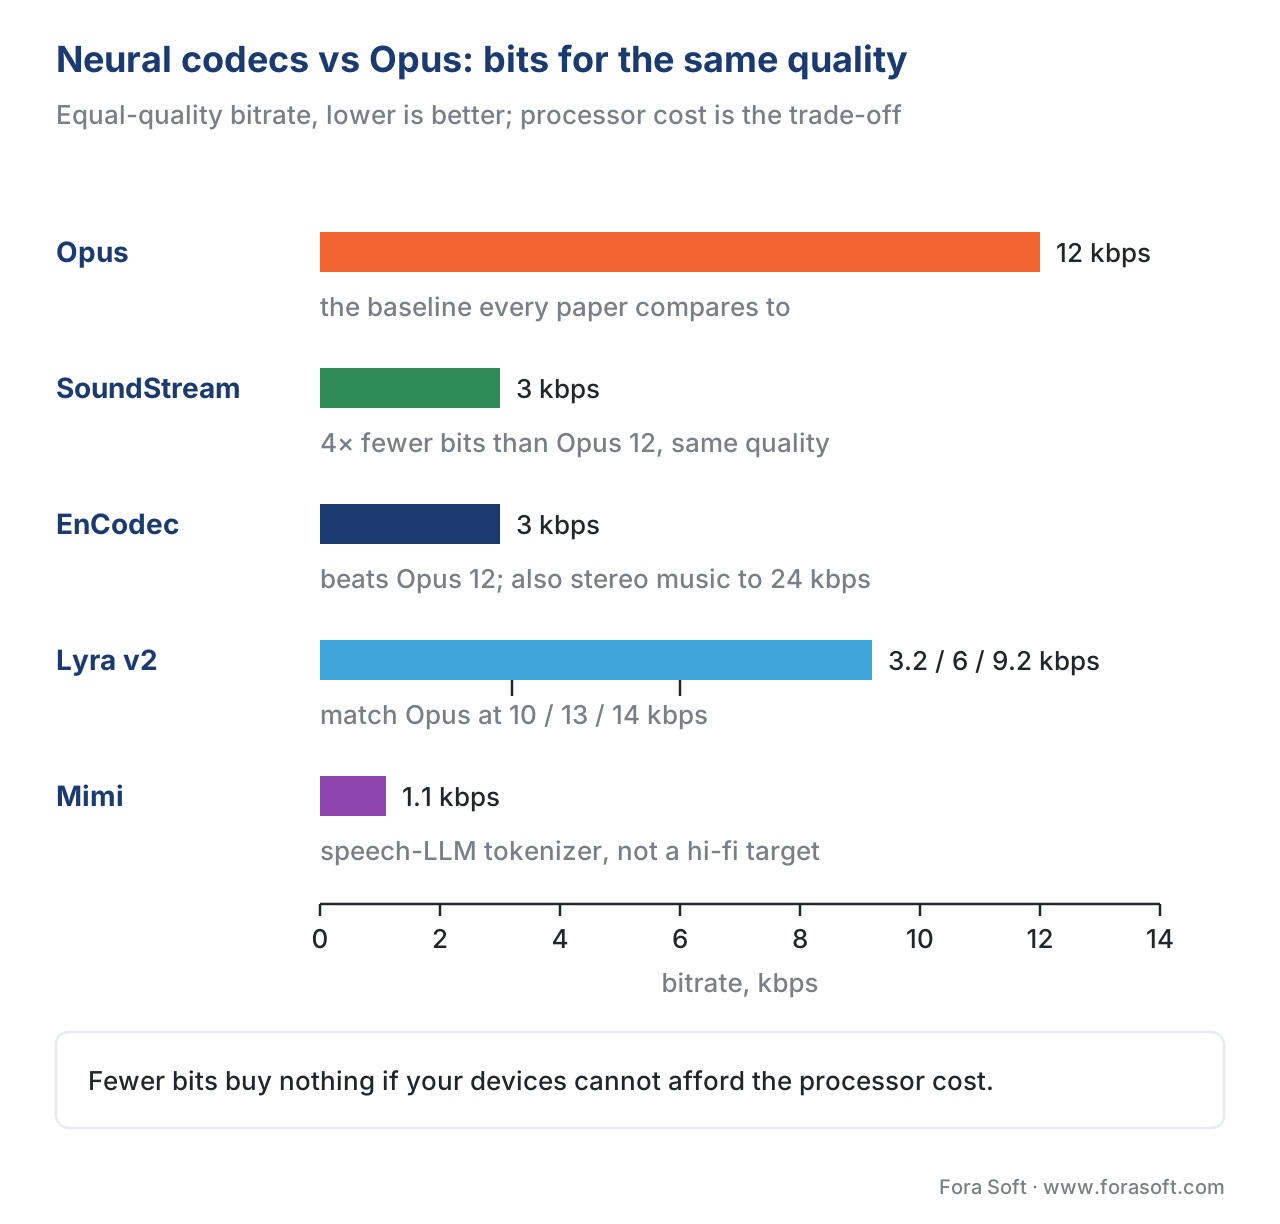 Figure 2. Where each codec lands on the bitrate-for-equal-quality axis. The neural codecs win on bits; the rest of the article is about what that win costs.
The numbers that decide it: bitrate, quality, and the processor bill
The temptation with neural codecs is to read the bitrate savings and conclude they are obviously better. The discipline is to put all three costs on the table at once, because the bandwidth saving is real but it is paid for on a different axis.
Here is the comparison that matters for a real product decision, with the figures stated at the quality each codec is designed for.
| Codec | Year | Bitrate range | Equal-quality benchmark | Audio type | Processor cost | Ships in production? |
|---|---|---|---|---|---|---|
| Opus | 2012 | 6–510 kbps | the baseline everyone compares to | speech + music | very low (microseconds); optional neural add-ons in 1.5–1.6 cost about 1% of a laptop core or less | yes — mandatory in WebRTC |
| SoundStream | 2021 | 3–18 kbps | 3 kbps ≈ Opus 12 kbps | speech + general | moderate (phone-capable) | no — research blueprint |
| Lyra v2 | 2022 | 3.2 / 6 / 9.2 kbps | 9.2 kbps ≈ Opus 14 kbps | speech | low–moderate (0.57 ms/frame on a phone) | yes — Google calling |
| EnCodec | 2022 | 1.5–24 kbps | 3 kbps > Opus 12 kbps | speech + music | high | no — research / model fuel |
| Mimi | 2024 | ~1.1 kbps (12.5 Hz frames, 24 kHz, 80 ms latency) | speech-LLM tokenizer, not a hi-fi target | speech | high | yes — inside voice-AI models (Moshi) |
| DAC (Descript) | 2023 | ~8 kbps at 44.1 kHz | ~90× compression of 44.1 kHz audio | speech + music + general | high | open weights — audio-LM tokenizer |
| NeuCodec (Neuphonic) | 2025 | 0.8 kbps (50 Hz, one FSQ codebook) | speech tokenizer for TTS, 24 kHz output | speech | high | open weights (Apache 2.0) |
| Qwen3-TTS-Tokenizer-12Hz | 2026 | 12.5 Hz × 16 codebooks (≈2.2 kbps, our calculation) | 1 semantic + 15 acoustic RVQ layers | speech | 4 ms tokenizer decode per packet | yes — inside Qwen3-TTS (Apache 2.0) |
| MLow (Meta, not neural) | 2024 | 6 kbps wideband and up | POLQA MOS 3.9 vs Opus 1.89 at 6 kbps | speech | 10% below Opus | yes — Instagram and Messenger calls, WhatsApp rollout |
Read that table twice, and notice the last row. MLow, which Meta launched in June 2024 for calls on poor networks, is a classical CELP codec, not a neural one: Meta reported twice Opus's POLQA score at 6 kbps with 10% less computation, and explicitly rejected EnCodec-style models as too expensive for billions of phones. The left columns are a triumph: neural codecs reach the same quality as Opus at a third to a quarter of the bits, and the newest speech-LLM codecs run near 1 kbps. The right columns are the catch. Opus decodes in microseconds on any device made this century; neural codecs need a neural network to run for every frame, which costs orders of magnitude more processor time, more battery, and — for the heavier ones — a capable phone or a GPU. Lyra is the only one engineered hard enough to escape this on a commodity phone, and even Lyra is a speech-only codec, not a general one.
Do the arithmetic on the saving so it is concrete. Suppose a 50-person all-hands streams audio and each speaker uses Opus at 12 kbps:
50 speakers × 12 kbps = 600 kbps of audio
Swap in a neural codec at equal quality and 3 kbps per speaker:
50 speakers × 3 kbps = 150 kbps of audio
That is a 4× cut in the audio bandwidth, and it lands exactly where bandwidth is scarce — a patient on rural mobile data in a telemedicine call, a student on a congested campus network. The saving is genuine. The reason you still cannot deploy it everywhere is the column on the far right: running the network on every client, every frame, costs more than the bandwidth it saves, unless your devices and your battery budget can absorb it.
Pitfall — "beats Opus" almost never means "replace Opus." Nearly every neural-codec paper reports beating Opus at low bitrate, and it is true under the paper's conditions. It is also nearly irrelevant to a real-time product, because Opus's advantage is not its bitrate — it is that it decodes for free on every device, has zero licensing cost, and is built into the WebRTC standard. Before you take a "3 kbps beats Opus 12 kbps" result as a reason to switch, ask the three questions the paper did not: what does it cost to run on my worst client device, what does it do to battery, and what is the latency? For most live calling in 2026, those answers still favour Opus. Reach for a neural codec where the network is the hard constraint and the compute is available — not as a default.
Is Opus becoming a neural codec? DRED, NoLACE and BWE in Opus 1.5–1.6
Partly, and this is the most practical neural-audio news for anyone shipping calls. Instead of replacing Opus, its developers have been adding small neural modules around the classic bitstream, each one optional and each one backward-compatible with ordinary Opus decoders.
- Opus 1.5 (March 2024) added Deep PLC, neural packet loss concealment that uses about 1% of a laptop CPU core; DRED (Deep REDundancy), which packs up to 1 second of neural-coded redundant speech into each packet for about 12–32 kb/s of overhead; and LACE and NoLACE, decoder-side enhancers of roughly 100 and 400 MFLOPS that clean up low-bitrate speech.
- Opus 1.6 (15 December 2025) added an experimental neural bandwidth extension that regenerates the 8–20 kHz band from wideband speech with no side information; with NoLACE at 9 kb/s it reaches about the quality of Opus 1.4 fullband at 18 kb/s. The DRED model shrank about 3×, to 600 kB from 1,800 kB, was retrained on noisy and reverberant speech, and its data is not usable by 1.5 decoders. The release also brought experimental 96 kHz "Opus HD" at up to 2 Mb/s and a 24-bit API.
- Standardisation: DRED is going through the IETF mlcodec working group as draft-ietf-mlcodec-opus-dred-06. At IETF 126 in 2026 the draft was described as complete, with the model unchanged since IETF 124 and the authors asking about working group last call.
The lesson for a product team: in 2026 the realistic route for neural audio into live calling is "Opus plus learned helpers" — concealment, redundancy, enhancement, bandwidth extension — not a wholesale switch to SoundStream-style transport. If your stack already runs Opus, upgrading libopus and enabling these features at the right decoder complexity is often the cheapest quality win available. Our Opus codec explainer covers the base codec these modules sit on.
Where neural codecs really ship in 2026: as the mouth and ears of voice AI
Here is the turn that surprised the field, and it is the most important thing to understand about why neural codecs matter even though Opus still wins live calling.
A large language model predicts the next token in a sequence. For text that is easy — a tokenizer chops writing into a few thousand possible word-pieces, and the model predicts one at a time. Sound is far harder, because raw audio is tens of thousands of numbers per second; a model trying to predict it sample by sample drowns. What neural codecs gave the AI world, almost as a side effect, is a way to turn a second of sound into a short sequence of discrete tokens — the quantizer indices from the RVQ stack — that a language model can predict exactly the way it predicts words. The codec became the tokenizer for audio. The encoder is the model's ears; the decoder is its mouth.
This reframes everything. EnCodec was adopted as the audio tokenizer inside Meta's MusicGen. Descript's open Descript Audio Codec (2023), which compresses 44.1 kHz audio at a roughly 90× ratio, became a drop-in fuel for audio language models. And the clearest example of the new design is Mimi, the codec built by Kyutai for its Moshi speech model in 2024. Mimi runs at about 1.1 kbps and just 12.5 frames per second on 24 kHz audio; each frame is 80 milliseconds, so its streaming latency is 80 ms, the frame size, and it does something the earlier codecs did not: it splits its tokens into two kinds. The first token stream is semantic — distilled from a speech-understanding model, it carries what is being said, the way text does, stripped of voice. The remaining streams are acoustic — they carry how it sounds: the speaker's timbre, pitch, and emotion. By separating meaning from voice, Mimi lets a language model reason about content and delivery as two different things, which is exactly what a system needs to listen and speak naturally. Moshi, built on it, can listen and talk at the same time with a theoretical latency of 160 milliseconds and about 200 milliseconds in practice.
This is also what "speech-to-speech" and "neural codec language model" mean. Microsoft's VALL-E (January 2023) was the first widely cited example: trained on about 60,000 hours of English speech, it predicts EnCodec tokens instead of waveforms and clones an unseen voice from a 3-second recording. Speech-to-speech systems such as Moshi go further and both hear and answer in codec tokens. The 2026 generation keeps the same recipe with fewer tokens per second: the Qwen3-TTS report (January 2026) uses a 12.5 Hz tokenizer with one semantic and 15 acoustic codebooks and reaches a first audio packet in about 97 ms, and Neuphonic's NeuCodec (2025) gets speech down to 0.8 kbps with a single finite-scalar-quantized codebook at 50 tokens per second.
So the production answer in 2026 is split cleanly. For moving a known voice across a network in real time, Opus is the default and a neural codec is rarely worth its compute. For generating or understanding voice with a model — voice assistants, AI dubbing, on-device text-to-speech, real-time translation — the neural codec is not optional; it is the thing that makes the model able to hear and speak at all. The same RVQ stack that compresses a call is what tokenizes sound for an LLM. One idea, two futures.
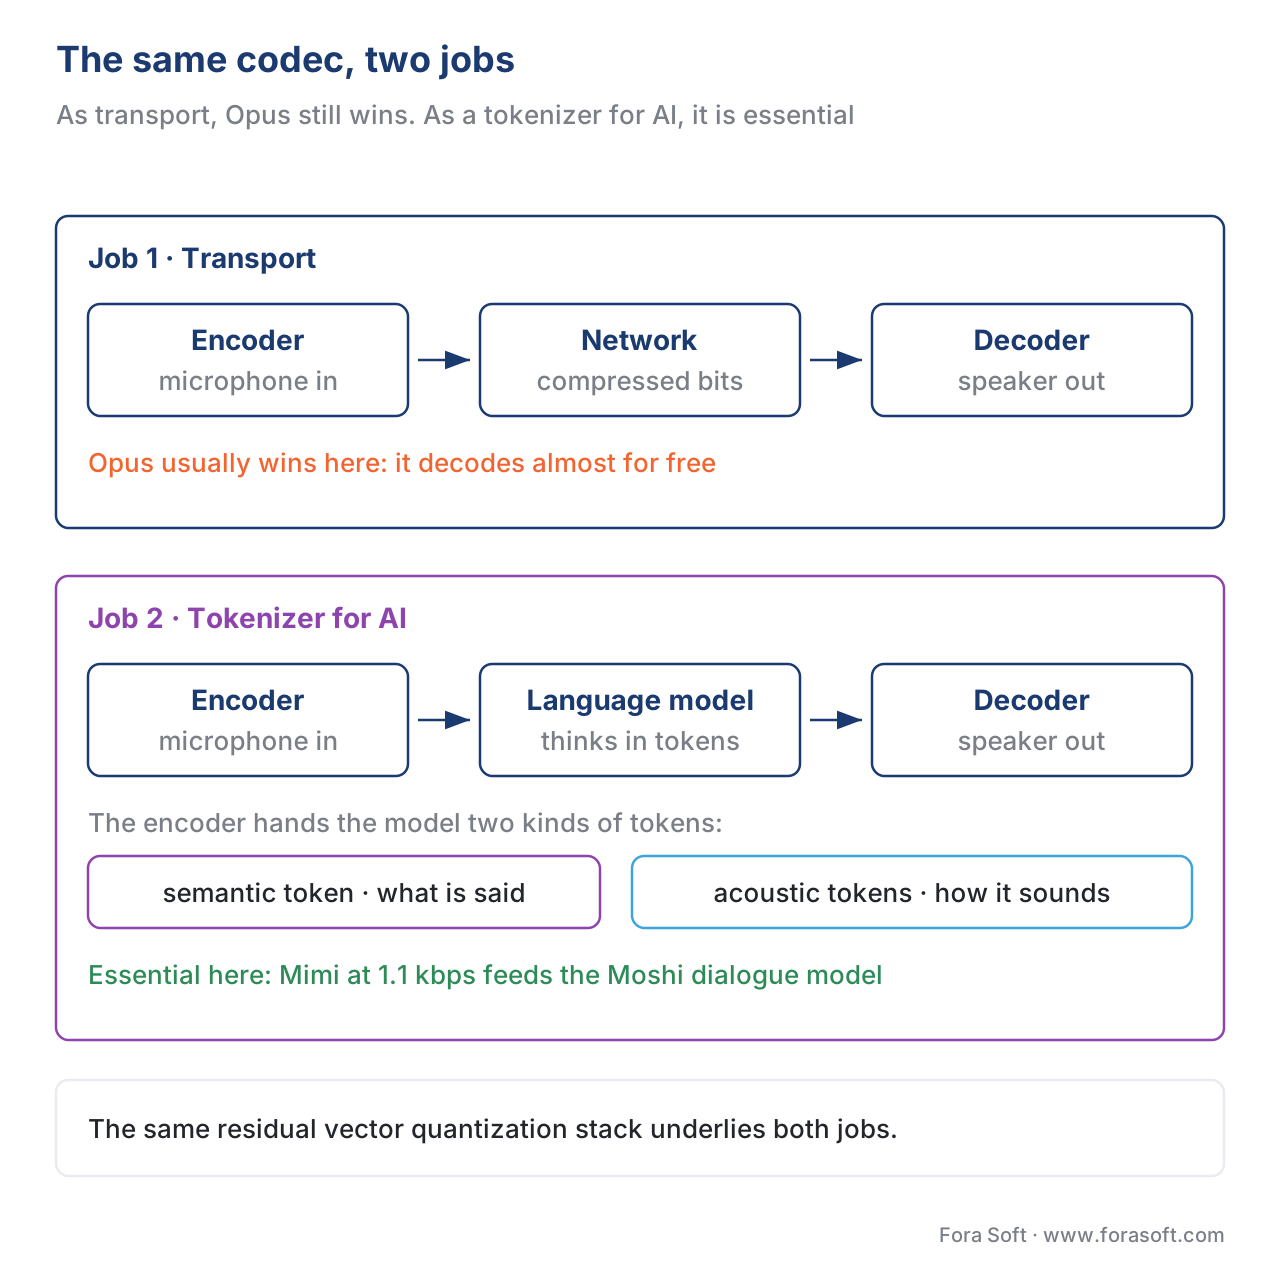 Figure 3. The same codec, two jobs. As transport (left), Opus still wins on cost. As a tokenizer for a language model (right), the neural codec is already the foundation — and the semantic/acoustic token split is why voice AI can separate what is said from how it sounds.
What comes next
Three lines of work define the next few years, and none of them is "neural codecs finally beat Opus on a phone for plain calling." That race is mostly over: Opus stays the default for ordinary transport, and a fork called the AOMedia Open Audio Codec (OAC) — made public in February 2026 as liboac, a fork of libopus, and described by its own README as very early-stage — is the industry's bet on the next traditional codec, aiming to beat Opus on its own terms rather than replace it with a neural one.
The first real frontier is making neural codecs cheap enough to deploy at the edge. The whole field now treats processor cost, not quality, as the hard problem. The Low-Resource Audio Codec (LRAC) Challenge 2025 asked for 24 kHz mono speech codecs at 6 kbps and 1 kbps under joint compute and latency caps. ByteDance's IRIS Codec won the transparency track and Nanjing University's PR-Vocodec won the joint enhancement-and-coding track, and every entry used the same end-to-end VQ-GAN design. At the first LRAC workshop (ICASSP 2026, Barcelona, May 2026) the closing panel asked whether neural codecs are ready for low-resource reality; the consensus was promising, but small models still struggle with noisy, reverberant real-world input — the gap between a benchmark winner and something you can ship. Lyra showed it is possible for speech on a good phone; the work now is to make it true for more devices, more audio types, and lower power.
The second frontier is the codec-as-tokenizer line maturing into infrastructure. As voice-native AI models move from the lab into products — assistants that hear tone, real-time dubbing that preserves a performance, translation that keeps your voice — the neural codec underneath becomes a piece of plumbing as standard as a video codec is today. The open questions there are about token design: how to split semantic from acoustic information cleanly, how many tokens per second a model needs, and whether the next systems even keep discrete tokens at all — some 2025 research generates audio from continuous representations and skips quantization entirely.
The third is the one to watch for your own roadmap: the line between "codec" and "generator" dissolving. A neural codec that can rebuild a voice from 1.1 kbps of tokens is, mechanically, very close to a model that can generate that voice from scratch. The same machinery that conceals a dropped packet by predicting the missing audio (covered in packet loss concealment) is the machinery that clones a voice. As we noted in the AI-in-audio survey, that convergence is where the consent, likeness, and disclosure law lives — and it is arriving through the codec layer, not just the dubbing tools. When your compression and your synthesis are the same network, "is this audio real" stops being a question the codec can answer for you.
Free download: Neural Audio Codec Cheat SheetOne page: what SoundStream, Lyra v2, EnCodec, and Mimi each do, the 2026 bitrate-vs-quality and processor-cost numbers, residual vector quantization in one diagram, and when Opus still wins.Where Fora Soft fits in
We build conferencing, telemedicine, e-learning, OTT streaming, and surveillance products, and our advice on neural codecs is deliberately unfashionable: for live, real-time audio in 2026, we still reach for Opus first, because its near-zero decode cost, zero licensing, and WebRTC-mandatory status beat a bitrate saving that most clients do not need and most devices cannot afford to run. Where we watch neural codecs closely is the AI layer — when a product needs a model to understand or generate voice, the codec is no longer a compression choice but a foundation choice, and getting the WebRTC audio pipeline right around it (latency budget, per-client compute, fallback to Opus) is the engineering that decides whether the feature is usable. The right framing for a client is rarely "should we switch to a neural codec" and almost always "where in our pipeline does a learned model earn its processor cost" — and the answer is moving, year by year, from nowhere toward the AI features at the edges. Our audio and video processing development team benchmarks Opus, including its DRED and bandwidth-extension modes, against Lyra, EnCodec and Mimi on your own recordings. When the codec is really a tokenizer for voice AI, our text-to-speech and voice cloning development team chooses the codec-and-model pair, and our LiveKit voice agent development work keeps Opus on the wire while the model listens and speaks through its own tokens.
The book
Audio for Video: A Complete Guide to Sound in Video Products: From Jitter Buffers and Lip Sync to Atmos, Quality Metrics, and Neural Codecs
Volume 5 of the handbook takes neural codecs from the paper to the call: residual vector quantization, what SoundStream, Lyra and EnCodec change, and where a learned codec earns its processor cost next to Opus. It sets them beside the network half of real-time audio (jitter buffers, packet loss concealment, FEC) and the listening tests (MUSHRA, POLQA, ViSQOL) you need before you trust any "beats Opus" claim. Written by Nikolay Sapunov, CEO at Fora Soft.
Weighing a neural codec against Opus for your product?
Tell us your weakest client device, your network conditions and whether voice AI is on the roadmap, and we will map the work: where Opus stays, where a learned codec pays for its compute, the latency budget and the fallback path, and how to prove quality with MUSHRA or POLQA before launch. 250+ video products shipped since 2005.
See our case studies
Case study
Volo (Blaze Streaming Media)
We developed the software for Blaze Streaming Media's Volo: real-time AI subtitles and voiceover for live events. Blaze runs Volo at conferences such as Black Hat USA, GDC and HIMSS.
Case study
TransLinguist
Interpretation platform with 75+ languages, AI speech-to-speech translation in 16+ and captions in 22, on the UK NHS national framework — voice AI running beside a WebRTC call that still ships its audio as ordinary codec packets.
Case study
Tyxit
Remote jamming for musicians under 30 ms end to end, with a proprietary codec at zero algorithmic latency — the transport job, where every millisecond of codec delay and every CPU cycle on the client counts.
What to read next
Codecs
Opus: the open codec that ate WebRTC
The baseline every neural codec is measured against, and why it still wins live calls.
Fundamentals
How audio compression works
The four ideas behind every codec, learned or hand-built.
AI audio
AI in audio: cloning, dubbing, restoration, generative music
The voice AI features that neural codec tokens make possible.
Quality
Objective audio quality metrics: PESQ, POLQA, ViSQOL
How to check a "same quality at a quarter of the bits" claim yourself.
References
- N. Zeghidour, A. Luebs, A. Omran, J. Skoglund, M. Tagliasacchi, SoundStream: An End-to-End Neural Audio Codec, arXiv:2107.03312, July 2021 (published in IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2021). https://arxiv.org/abs/2107.03312 (Primary source from the codec's authors, read directly: convolutional encoder-decoder + residual vector quantization + adversarial training; one model spans 3–18 kbps via structured quantizer dropout; at 3 kbps outperforms Opus at 12 kbps and approaches EVS at 9.6 kbps on 24 kHz audio; real-time on a smartphone CPU.)
- A. Défossez, J. Copet, G. Synnaeve, Y. Adi, High Fidelity Neural Audio Compression (EnCodec), arXiv:2210.13438, Meta AI, October 2022. https://arxiv.org/abs/2210.13438 (Primary source, read directly: streaming encoder-decoder with quantized latent; single multi-scale spectrogram discriminator + loss balancer; 24 kHz mono to 48 kHz stereo, 1.5–24 kbps; higher MUSHRA than SoundStream at equal bitrate; a lightweight Transformer compresses the bitstream a further 25–40%, e.g. 3 kbps → 1.9 kbps.)
- Google Open Source Blog, Lyra V2 — a better, faster, and more versatile speech codec, 30 September 2022. https://opensource.googleblog.com/2022/09/lyra-v2-a-better-faster-and-more-versatile-speech-codec.html (Primary vendor source, read directly: built on SoundStream; bitrates 3.2 / 6 / 9.2 kbps switchable via RVQ layer count; in MUSHRA, those rates match Opus at 10 / 13 / 14 kbps; 20 ms delay; 0.57 ms to encode+decode a 20 ms frame on a Pixel 6 Pro, ~35× real time; outperforms EVS and AMR-WB at 50–60% of their bandwidth.)
- IETF RFC 6716, Definition of the Opus Audio Codec, J.-M. Valin, K. Vos, T. Terriberry, September 2012. https://www.rfc-editor.org/rfc/rfc6716 (Standards primary source: the controlling specification for Opus — the codec every neural codec benchmarks against and the one mandatory in WebRTC; 6–510 kbps operating range, speech + music, microsecond-class decode.)
- R. Kumar, P. Seetharaman, A. Luebs, I. Kumar, K. Kumar, High-Fidelity Audio Compression with Improved RVQGAN (Descript Audio Codec), arXiv:2306.06546, June 2023. https://arxiv.org/abs/2306.06546 (Primary source: open universal neural codec; 44.1 kHz audio at ~90× compression / 8 kbps; explicitly positioned as a drop-in replacement for EnCodec in audio language models such as AudioLM, MusicLM, MusicGen.)
- A. Défossez, L. Mazaré, M. Orsini, A. Royer, P. Pérez, H. Jégou, E. Grave, N. Zeghidour, Moshi: a speech-text foundation model for real-time dialogue, arXiv:2410.00037, Kyutai, September 2024. https://arxiv.org/abs/2410.00037 (Primary source for the Mimi codec: ~1.1 kbps, 12.5 Hz frame rate; splits tokens into a WavLM-distilled semantic stream and acoustic streams; powers the Moshi full-duplex speech model at ~200 ms latency.)
- V. Volhejn (Kyutai), Neural audio codecs: how to get audio into LLMs, October 2025. https://kyutai.org/codec-explainer (First-party explainer from the Mimi/Moshi lab, read directly: walks through VQ-VAE, the straight-through estimator, residual vector quantization, the multi-level token problem, and the semantic-vs-acoustic token split; source for the "codec as LLM tokenizer" framing and the RVQ coin-change intuition.)
- Low-Resource Audio Codec Challenge (LRAC) 2025, Challenge Description, arXiv:2510.23312, 2025. https://arxiv.org/abs/2510.23312 (Current research source: frames the 2026 frontier as neural codecs that meet strict compute, latency, and bitrate limits under everyday noise and reverberation — i.e. edge deployability, not raw quality, is now the hard problem.)
- A. Biswas et al., A Streamable Neural Audio Codec with Residual Scalar-Vector Quantization for Real-Time Communication, arXiv:2504.06561, 2025. https://arxiv.org/abs/2504.06561 (Current research source on streamable low-complexity neural codecs aimed specifically at real-time communication — evidence of the push to make neural codecs deployable in WebRTC-grade pipelines.)
- BlogGeek.me (T. Levent-Levi), OAC: AOMedia Open Audio Codec, WebRTC Glossary, 2026. https://bloggeek.me/webrtcglossary/oac/ (Industry source: OAC began in early 2026 on the Opus source base, aiming to surpass Opus in efficiency as the next traditional codec — context for why the post-Opus default is not assumed to be neural. Secondary source; flagged for a primary AOMedia citation at review once the working group publishes.)
- N. Zeghidour et al., SoundStream IEEE/ACM TASLP version (DOI 10.1109/TASLP.2021.3129994), 2021. https://ieeexplore.ieee.org/document/9625818 (Peer-reviewed journal version of reference 1, cited for the formal RVQ definition and the subjective-test methodology.)
- Xiph.Org, libopus 1.6 released, 15 December 2025. https://opus-codec.org/release/stable/2025/12/15/libopus-1_6.html (Primary vendor source, read October 2026: wideband-to-fullband BWE, 96 kHz Opus HD, improved DRED, 24-bit API.)
- J.-M. Valin et al., Opus 1.6 demo, Xiph.Org, 2025. https://opus-codec.org/demo/opus-1.6 (Primary source: BWE generates 8–20 kHz from wideband; NoLACE 9 kb/s + BWE ≈ Opus 1.4 fullband at 18 kb/s; DRED model 600 kB vs 1,800 kB; Opus HD up to 2 Mb/s.)
- J.-M. Valin et al., Opus 1.5 demo, Xiph.Org, 4 March 2024. https://opus-codec.org/demo/opus-1.5 (Primary source: Deep PLC (~1% of a laptop core), DRED up to 1 s at ~12–32 kb/s overhead, LACE ~100 MFLOPS, NoLACE ~400 MFLOPS.)
- IETF mlcodec WG, Opus DRED status, IETF 126 slides (draft-ietf-mlcodec-opus-dred-06), 2026. https://datatracker.ietf.org/meeting/126/materials/slides-126-mlcodec-dred-00 (Standards-track status of DRED: description complete, model unchanged since IETF 124.)
- Cisco and partners, LRAC Challenge 2025 results and Challenge overview slides, LRAC Workshop 2026. https://crowdsourcing.cisco.com/lrac-challenge/2025/results (Primary source: 6 kbps and 1 kbps tracks at 24 kHz mono; IRIS Codec (ByteDance) and PR-Vocodec (Nanjing University) won Tracks 1 and 2.)
- N. Pia, Highlights from the 2026 LRAC Workshop, Fraunhofer IIS, July 2026. https://www.dsai.iis.fraunhofer.com/?p=2059 (Workshop at ICASSP 2026, Barcelona; all entries end-to-end VQ-GAN; panel on readiness for low-resource reality.)
- Kyutai, moshi package documentation (Mimi), PyPI. https://pypi.org/project/moshi/ (Primary source: Mimi handles 24 kHz audio at 12.5 Hz and 1.1 kbps with 80 ms streaming latency, the frame size.)
- C. Wang et al., Neural Codec Language Models are Zero-Shot Text to Speech Synthesizers (VALL-E), arXiv:2301.02111, January 2023. https://arxiv.org/abs/2301.02111 (Primary source: ~60,000 hours of training speech; voice cloning from a 3-second enrolled recording using neural codec tokens.)
- Qwen Team, Qwen3-TTS Technical Report, arXiv:2601.15621, January 2026. https://arxiv.org/abs/2601.15621 (Primary source: 12.5 Hz tokenizer, 16 codebooks (1 semantic + 15 RVQ), 97 ms first-packet latency (0.6B), Apache 2.0.)
- Neuphonic, NeuCodec model card, 2025. https://huggingface.co/neuphonic/neucodec (Primary source: 50 tokens/s, 16 bits per token, 0.8 kbps, single FSQ codebook, 24 kHz output, Apache 2.0.)
- Meta Engineering, MLow: Meta's low bitrate audio codec, 13 June 2024. https://engineering.fb.com/2024/06/13/web/mlow-metas-low-bitrate-audio-codec/ (Primary vendor source: CELP-based; POLQA MOS 3.9 vs Opus 1.89 at 6 kbps WB; 10% lower complexity than Opus; live in Instagram and Messenger, rolling out on WhatsApp.)
- M. Larabel, AOMedia Open Audio Codec "OAC" aims to be the successor to Opus, Phoronix, 22 February 2026. https://www.phoronix.com/news/AOMedia-OAC-Open-Audio-Codec (Industry report on the first public liboac commit, based on libopus; project in very early stages.)
- Wikipedia, Lyra (codec), checked October 2026. https://en.wikipedia.org/wiki/Lyra_(codec) (Latest release 1.3.2, 20 December 2022; used by Google Meet on limited bandwidth; Apache-2.0.)
Living note: the neural-codec field moves fast. SoundStream (2021), Lyra v2 (2022), EnCodec (2022), DAC (2023), and Mimi (2024) are stable primary references; the 2025–2026 frontier (Opus 1.6 neural modules and the DRED draft, LRAC results, OAC, Qwen3-TTS and NeuCodec tokenizers) was re-verified in October 2026 and should be checked again on the next refresh. Bitrate-equal-quality claims are stated at each codec's own test conditions and sampling rate; they are not a single apples-to-apples benchmark.
