

Updated October 2026: added a short answer on echo-cancelling speakerphones and a buyer’s checklist, HFP 1.9 super-wideband (LC3-SWB) calls, the new echoCancellation modes in the W3C spec, Apple voice processing in Swift, AirPods Pro 3 and iOS 26 call audio, and a FAQ.
What is an echo-cancelling speakerphone? The short answer
An echo-cancelling speakerphone is a hands-free speaker and microphone unit with built-in acoustic echo cancellation (AEC): it subtracts the sound of its own loudspeaker from what its microphones pick up, so the people on the far end do not hear themselves repeated back. A good one stays full-duplex — both sides can talk at once — which is how ITU-T Recommendation P.340 classifies hands-free terminals; a weak one goes half-duplex and clips whoever is quieter.
Bluetooth headsets and speakers are the hardest case for echo cancellation because the Bluetooth link makes the speaker-to-microphone delay long and constantly moving, and opening the microphone on classic Bluetooth drops audio from stereo A2DP to mono HFP call quality. Sealed in-ear AirPods rarely produce real echo at all; when an AirPods call sounds bad, the usual cause is that profile switch, not echo.
Why this matters
If you build a video conferencing tool, a telemedicine platform, an online classroom, or a contact centre, your users will not behave. They will join from a phone on a desk, from AirPods on a train, from a conference-room speakerphone with six people, and from a Bluetooth speaker in a kitchen with tile floors. Each of those is a different echo problem, and the same echo canceller that sounds flawless on your headset can clip words or leak echo on theirs. This article is for the product manager, founder, or operations lead who needs to understand why one device echoes and another does not, so you can read a support ticket, ask your engineer the right question, and set honest expectations with a customer. A senior engineer will also find every claim traced to the relevant Bluetooth, ITU-T, Apple, or Android source. By the end you will know exactly why Bluetooth is the hardest case in real-time audio, and what to do about it.
Start here: what echo cancellation needs to succeed
Before we get to the hard devices, hold one idea in your head, because everything else follows from it. Echo cancellation, abbreviated AEC (for acoustic echo cancellation), removes the sound of your own speaker after it leaks back into your microphone. To do that, it needs the one thing the device already knows: the audio it is about to play, called the reference signal. The canceller predicts how that reference will come back as echo, and subtracts the prediction from the microphone. If the prediction is good, only your voice survives. The full mechanism — the adaptive filter, the double-talk detector, the residual suppressor — is covered in Acoustic Echo Cancellation (AEC): How It Really Works. Here we only need one part of it.
That one part is delay alignment. The canceller cannot subtract the echo unless it knows how late the echo arrives compared to when the reference was played. Picture two copies of the same song, one playing a fraction of a second behind the other; to cancel one against the other, you first have to slide them until they match. The gap the canceller has to measure is the round trip from "audio handed to the speaker" to "echo captured at the microphone." It includes the playback buffer, the digital-to-analog converter, the air path across the room, the analog-to-digital converter, and the capture buffer.
On a normal phone or laptop, that round-trip delay is typically tens of milliseconds and can reach a couple of hundred, and it can drift during a call. WebRTC's echo canceller, AEC3, estimates this delay continuously by sliding the reference against the captured signal to find the lag where they best line up. Here is the rule that decides every device's fate: if the delay estimate falls outside the short window the adaptive filter covers (tens of milliseconds in AEC3), the filter is comparing the echo to the wrong slice of reference, and nothing cancels. Keep that sentence in mind. It is the whole story of why Bluetooth is hard.
The easy end of the spectrum: wired headsets
The reason a wired headset sounds clean is almost boring. The speaker is sealed against or inside your ear, so the sound it plays has almost no path back to the microphone. There is barely any echo to cancel in the first place. The delay is small and fixed, because a wire does not buffer audio or change its timing. The canceller converges in a fraction of a second and then has almost nothing to do.
This is why every honest piece of advice about call audio starts the same way: use a wired headset. It removes the echo by physics, not by software, and it removes the timing problem because a wire is instant. Everything that follows in this article is about what happens when the user does not do that.
Why Bluetooth is the hardest case in real-time audio
Bluetooth fails the delay-alignment test on every axis at once. To see why, you have to understand a quirk of how classic Bluetooth carries audio, because it is the root of most Bluetooth call complaints.
The profile switch: why your headphones get worse the instant you speak
Classic Bluetooth does not have one way to send audio. It has two, and they are built for opposite jobs.
The first is the Advanced Audio Distribution Profile, abbreviated A2DP. This is the high-quality, stereo, one-direction path. It is what plays music to your headphones. It sounds good — stereo, full bandwidth, a real codec like AAC or aptX. But it has no return channel. There is no microphone in A2DP at all, because music does not need one.
The second is the Hands-Free Profile, abbreviated HFP. This is the two-direction path built for phone calls. It carries audio out to the speaker and voice back from the microphone. But classic Bluetooth’s profiles were never designed to carry a full-quality stereo stream and an uplink microphone at the same time. So HFP collapses the audio to a single low-bandwidth mono voice channel in both directions.
Here is the consequence that surprises almost everyone. The instant your app opens the microphone — the instant a call starts — the headphones must leave A2DP and switch to HFP. The music-grade stereo path is gone, and both directions drop to mono voice quality. This is why your expensive wireless earbuds sound rich while you listen to a podcast and suddenly sound like a 1990s mobile phone the moment you answer a call. Nothing broke. The profile switched.
How far does the quality drop? HFP's voice runs over a synchronous link with a fixed budget of 64 thousand bits per second. The mandatory codec, called CVSD, samples at 8 kHz, which captures only about the bottom 4 kHz of the audible range — telephone quality. A newer optional codec, mSBC, introduced in HFP version 1.6, samples at 16 kHz for roughly 7 kHz of usable bandwidth, marketed as "HD Voice" or wideband speech. Compare that to A2DP's AAC at 44.1 or 48 kHz in stereo, and you can hear the cliff.
The cliff is getting a little lower on newer hardware. HFP 1.9, the current adopted version of the Hands-Free Profile, adds super-wideband speech using the LC3 codec (often written LC3-SWB), which stretches call audio to roughly 50 Hz–14 kHz instead of mSBC’s 7 kHz. It only helps when the phone and the headset both support it, so in 2026 you still have to plan for CVSD and mSBC on most of your users’ devices.
 Figure 1. The Bluetooth profile switch. Listening uses A2DP — stereo, full bandwidth, no mic. Opening the mic forces HFP — mono, narrow or wideband, in both directions. The drop in quality the moment a call starts is the profile switch, not a fault.
The moving target: why the canceller cannot lock on
The profile switch is the quality problem. The delay is the echo problem, and it is worse.
A Bluetooth link adds a large amount of round-trip delay, because audio is packetized, buffered, transmitted over radio, and re-buffered at the other end. The radio link adds tens of milliseconds in each direction on top of the device’s own buffers, so the full playback-to-capture loop on a Bluetooth setup sits at the high, painful end of the range a canceller has to search. Worse than the size is the variability. Radio conditions change, buffers adjust, the link renegotiates, and the delay shifts mid-call.
Now recall the rule from earlier: the canceller must know the delay to within a few milliseconds, or it cancels nothing. A delay that is both large and constantly moving is exactly the input the delay estimator is worst at. It locks on, the delay shifts, the lock breaks, echo leaks while it re-locks, and the cycle repeats. This is the core reason classic Bluetooth is the hardest case in real-time audio: it attacks the one measurement the canceller depends on most.
WebRTC's earlier echo canceller openly struggled with variable-latency devices and Bluetooth routing changes. AEC3, the current generation introduced around 2017 to 2018, added a continuously adapting delay estimator and faster detection of echo-path changes specifically to cope with this kind of moving target. It is better. It is not magic. On a bad Bluetooth link it is still fighting physics.
The double-processing trap
There is a second, quieter Bluetooth problem that produces some of the strangest bug reports. Many Bluetooth and USB headsets run their own echo cancellation and noise suppression inside the headset's own chip, before they ever send the microphone signal to the phone. Your application's software canceller then receives a signal that has already been processed once. Two cancellers, each assuming it is the only one, can fight each other — pumping the volume, chopping the start of words, or producing a hollow, warbling voice that neither canceller would create alone.
The fix is not "add more cancellation." It is the opposite: on mobile, let one canceller own the job — usually the platform or hardware one — and do not stack a second software canceller on top of an already-cleaned signal. Knowing this turns an unexplainable "the voice sounds underwater on this one headset" ticket into a one-line answer.
AirPods: a different problem wearing the same costume
AirPods get blamed for echo constantly, and they are usually innocent of it. Walk through the physics and you can see why.
An AirPod sits sealed in or against your ear canal. The speaker fires into your ear, not into the room. So the path from the AirPod's speaker back to the AirPod's microphone is tiny — there is almost no acoustic echo to cancel. On the echo axis, sealed earbuds behave like a wired headset: the problem mostly is not there.
What is there is everything from the Bluetooth section above. AirPods are Bluetooth devices, so the moment you take a call they switch from the rich A2DP music path to the mono HFP voice path, and your voice quality drops. AirPods also add real on-device processing to fight back: the H2 chip in AirPods 4, AirPods Pro 2 and AirPods Pro 3 runs beamforming microphones and computational audio to clean up your voice (with iOS 26, announced in June 2025, Apple applies that call-quality processing to iPhone calls, FaceTime and CallKit apps such as Zoom on AirPods 4 and AirPods Pro 2), and Apple's Voice Isolation feature uses machine learning to strip background noise from calls — available for FaceTime since iOS 15, for regular phone calls since iOS 16.4, and extended to recent AirPods with the heavy lifting running on the H2 chip. So when an AirPods call sounds bad, the cause is almost always codec degradation from the profile switch or a switching artifact, not echo.
The exception is worth stating, because it catches teams off guard. The "no echo" reasoning depends on the AirPod being in the ear. The instant a user pulls the earbuds out and sets them on a desk while staying on the call, the speaker now fires into open air, the microphone is no longer sealed, and you are back to a full open-room echo problem — over a Bluetooth link with all its delay troubles. Same hardware, completely different acoustic situation.
The pitfall, stated plainly. When a ticket says "echo on AirPods," it is rarely the AirPods echoing. Check three things in order: was the audio routed through HFP and degraded (sounds muffled, not echoey)? Did the user take them out of their ears mid-call? Is your app stacking a software canceller on top of Apple's voice processing? Real acoustic echo from sealed, in-ear AirPods is the least likely cause. The seal matters more each generation: AirPods Pro 3 (September 2025) ship with foam-infused ear tips in five sizes for better passive isolation, which also means even less speaker sound reaches the outer microphones.
Speakerphone: the open room turns every weakness up to maximum
The conference-room speakerphone and the laptop-on-a-table are the opposite of a sealed earbud, and they are hard for reasons that have nothing to do with Bluetooth — though Bluetooth often makes them worse.
The first problem is the echo path is long and reverberant. In an open room, the speaker's sound bounces off walls, the table, a glass window, and arrives back at the microphone as a smear of reflections that can stretch 100 to 300 milliseconds. The canceller's adaptive filter has to model that entire tail, which means a longer, heavier filter that converges more slowly and re-converges every time someone moves.
The second problem is loudspeaker distortion. Turn a speakerphone up and the speaker itself stops behaving like a clean, predictable device — it adds distortion the adaptive filter cannot model, because the filter can only predict echo that is a delayed, scaled copy of the reference, and distortion is neither. Whatever the filter cannot subtract is mopped up by a second stage, the residual suppressor, which attenuates rather than subtracts. Push it too hard and you get the third problem.
The third problem is double-talk, the situation where both people speak at once, and it is the one your users will complain about. When the canceller is unsure whether the microphone holds echo or the near person's voice, it can clamp down to be safe and chop the near voice. The audible result is half-duplex behaviour: the device acts like a walkie-talkie, where whoever is louder wins and the other person gets cut off. The international standard for hands-free terminals, ITU-T Recommendation P.340, formally classifies these devices by exactly this property — full-duplex, where both directions stay open, versus half-duplex, where one direction is suppressed. A cheap speakerphone that goes half-duplex under pressure is not broken; it is making the only trade it can.
 Figure 2. The open room turns up every echo weakness. A long reverberant tail, speaker distortion at volume, and double-talk all hit at once. The failure you hear is half-duplex clipping — the device cutting one direction to stay echo-free.
What to look for in an echo-cancelling speakerphone
If you are choosing speakerphones for a clinic, a classroom or a meeting room, or recommending one to your users, five properties decide whether calls stay clean. The spec sheet rarely uses these words, so here is what each one means and how to check it.
| Property | Why it matters for echo | How to check |
|---|---|---|
| Full-duplex under double-talk | Both people can talk at once without clipping; this is the P.340 distinction between full- and half-duplex | Talk over the far end on a test call; listen for cut-off syllables |
| USB (cable or dongle) for calls | USB audio skips the Bluetooth A2DP-to-HFP switch and the moving radio delay | Prefer models that connect over USB or ship a USB dongle for the laptop |
| Microphone array with beamforming | Picks voices over room reflections, so less echo reaches the canceller | Spec sheet lists several mics and a pickup range in metres |
| Platform certification (Microsoft Teams, Zoom) | Certified devices are tested for echo, double-talk and loudness on that platform | Look for the certification badge for the platform your users run |
| On-device AEC you can rely on | The speakerphone already cancels echo; your app must not stack a second canceller on top | Test with the app’s own AEC on and off; keep whichever owner sounds clean |
The short version for a buyer: a USB-connected, full-duplex, platform-certified speakerphone with a microphone array removes most of the problems in this section before your software ever sees them.
Who owns the echo canceller on each platform
When your product runs in a browser or a mobile app, you are not the only party with an echo canceller. The operating system has one too, and on mobile it is often the better choice. Knowing who owns the job per platform is half of fixing echo bugs.
On the web, the relevant control is the echoCancellation constraint in the browser's getUserMedia API, defined by the W3C Media Capture and Streams specification. Setting it asks the browser to remove crosstalk between the output and input devices. On a desktop browser this usually runs WebRTC's own AEC3 in software. On a phone, the browser frequently satisfies the same request by routing through the platform's hardware canceller instead. Since the October 2025 Candidate Recommendation Draft, the constraint is no longer just on or off: it can also take a mode string — "all" to cancel every sound the device plays, or "remote-only" to cancel only audio from the remote peers, so a music teacher’s backing track stays in the microphone. Browser support for the modes is still partial in 2026, so feature-detect with getCapabilities() before relying on them.
// Ask the browser to engage echo cancellation on the mic stream.
// On desktop this is usually AEC3; on mobile it often means the
// platform/hardware canceller does the work instead.
const stream = await navigator.mediaDevices.getUserMedia({
  audio: { echoCancellation: true, noiseSuppression: true, autoGainControl: true },
});
On Apple platforms, the system canceller lives in the Voice-Processing I/O audio unit, which adds echo cancellation, noise suppression, and gain control built for voice calls. You engage it by setting the audio session to a voice mode such as .voiceChat. On iOS and macOS this is the canceller that handles the hardware and the routing for you, including the Bluetooth path, and it is usually better than fighting that path yourself.
In Swift, the two common routes to that canceller are AVAudioEngine and Audio Toolbox. With AVAudioEngine you turn on voice processing on the input node; with Audio Toolbox (Core Audio) you create the I/O unit with the subtype kAudioUnitSubType_VoiceProcessingIO instead of kAudioUnitSubType_RemoteIO. Either way, Apple’s canceller gets the playback reference and the Bluetooth route from the system, which your own code cannot see as precisely.
// Swift echo cancellation on iOS: let Apple's Voice-Processing I/O own it.
let session = AVAudioSession.sharedInstance()
try session.setCategory(.playAndRecord, mode: .voiceChat,
                        options: [.allowBluetooth, .defaultToSpeaker])
try session.setActive(true)

// .defaultToSpeaker suits video calls; omit it for receiver-style voice calls.
let engine = AVAudioEngine()
// Enable before connecting nodes and before engine.start().
try engine.inputNode.setVoiceProcessingEnabled(true)   // AEC + noise suppression + AGC
// Audio Toolbox equivalent: AudioComponentDescription with
// componentSubType = kAudioUnitSubType_VoiceProcessingIO
try engine.start()
Since WWDC 2023 (iOS 17 and macOS 14), the same voice-processing unit also lets you control how much it ducks other audio during a call (voiceProcessingOtherAudioDuckingConfiguration) and tells you when a muted user starts talking. Do not run a second software canceller on the buffers it hands you.
On Android, the system exposes AcousticEchoCanceler, an audio pre-processor that removes the far-end signal from the captured microphone audio. It is engaged through the capture path — typically by choosing the VOICE_COMMUNICATION audio source — and which effects actually run is decided per device by the manufacturer's configuration. That last point is the catch: Android AEC quality is wildly inconsistent across OEMs, which is exactly why many serious Android voice apps bypass the platform and run AEC3 themselves, accepting the delay-estimation challenge in exchange for predictable behaviour.
| Platform | Who owns AEC | How you engage it | Practical note |
|---|---|---|---|
| Desktop browser | WebRTC AEC3 (software) | echoCancellation: true in getUserMedia |
Predictable; the reference deep dive applies directly |
| Mobile browser | Usually platform / hardware | echoCancellation: true |
Same constraint, different engine underneath |
| iOS / macOS native | Apple Voice-Processing I/O | Audio session .voiceChat mode |
Let it own routing, including Bluetooth |
| Android native | AcousticEchoCanceler or AEC3 |
VOICE_COMMUNICATION source, or run AEC3 |
OEM quality varies; many apps run AEC3 instead |
The single most expensive mistake here is double-processing: engaging the platform canceller and a software canceller on the same already-cleaned signal. Pick one owner per platform. That decision prevents more echo bugs than any amount of tuning.
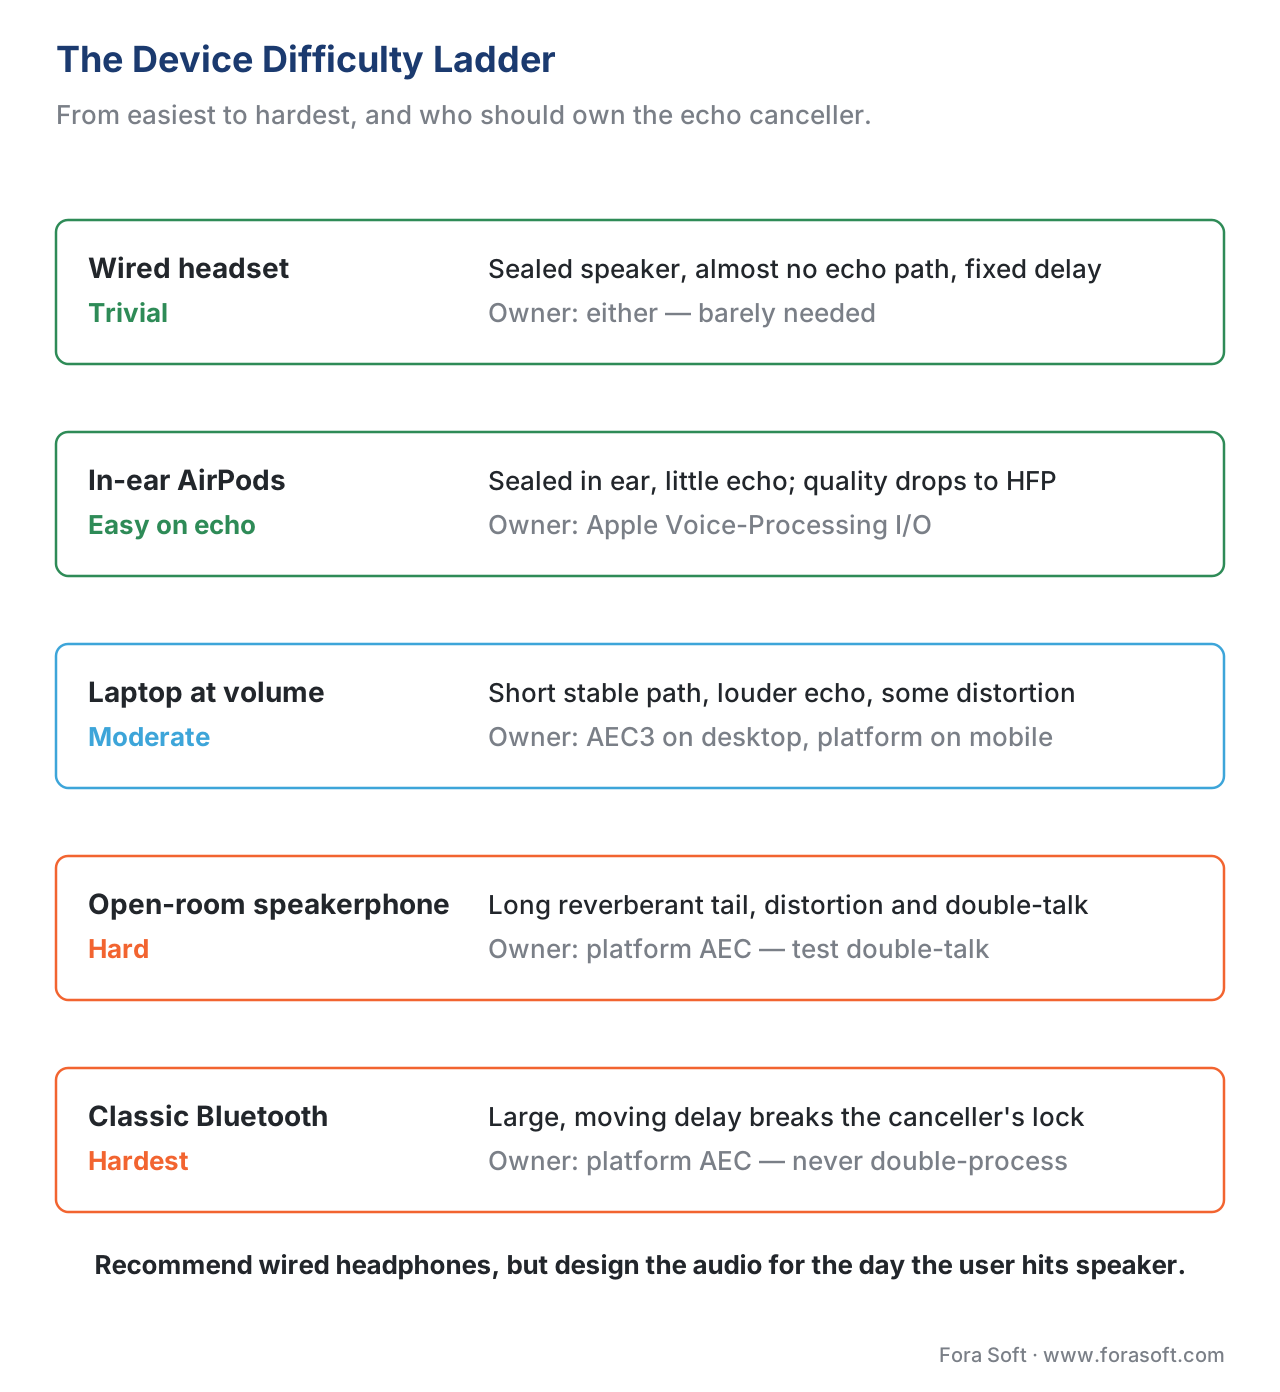 Figure 3. The same devices in difficulty order, with the canceller owner for each. The pattern is short: the more open the acoustic path and the more variable the delay, the more you want the platform to own the job — and the more it costs you to run a second canceller on top of it.
The horizon: Bluetooth LE Audio and LC3
The profile-switch problem is a limitation of classic Bluetooth, and it has a real fix arriving. Bluetooth LE Audio, introduced with Bluetooth Core Specification 5.2, replaces the old A2DP-or-HFP either-or with a new architecture built on a royalty-free codec called LC3 (Low Complexity Communication Codec). LC3 carries high-quality audio at less than half the bitrate of the old music codec, and LE Audio's connected isochronous streams can run high-quality audio in both directions at once. In plain terms: a future call over LE Audio keeps good quality and a microphone simultaneously — the drop becomes much smaller.
The honest status as of 2026 is "arriving, not arrived." LE Audio and its broadcast feature, Auracast, are shipping across new phones, earbuds, and hearing aids, with the Bluetooth Core specification reaching version 6.3 in May 2026, but it is not yet the default that every device on a call will speak. For the next few years you must assume a meaningful share of your users are on classic Bluetooth, living with the profile switch and the variable delay. In 2025 Android added Auracast broadcast audio and LE Audio hearing-aid support (Android 16 on Pixel 9, One UI 7 on Samsung Galaxy), which speeds adoption on the Android side. Design for the floor, not the ceiling.
Frequently asked questions
What is an echo-cancelling speakerphone?
It is a hands-free speaker-and-microphone unit with built-in acoustic echo cancellation, which removes its own loudspeaker sound from the microphone signal so the far end does not hear an echo. Good models stay full-duplex, so both sides can talk at the same time without words being clipped.
Why do my Bluetooth headphones have echo?
If you hear your own voice back, the echo usually comes from the other person’s device, not yours. If they hear themselves, it is usually because the Bluetooth link makes the speaker-to-microphone delay long and variable, and the echo canceller loses its lock each time the delay shifts. Open-back or on-desk use makes it worse; a second canceller stacked on the headset’s own processing can also cause echo-like artefacts.
Why do AirPods echo on calls?
Sealed in-ear AirPods almost never create acoustic echo; what users call echo is usually the muffled HFP call mode after the profile switch. Real echo appears when someone takes the AirPods out mid-call or an app runs its own canceller on top of Apple’s voice processing.
How do I stop echo on a speakerphone?
Lower the speaker volume, move the unit away from walls and glass, connect it over USB instead of Bluetooth, and make sure only one echo canceller is active — either the speakerphone’s or the app’s, not both.
How do I do echo cancellation in Swift?
Use Apple’s Voice-Processing I/O: set the audio session to .playAndRecord with the .voiceChat mode and call setVoiceProcessingEnabled(true) on the AVAudioEngine input node, or create a kAudioUnitSubType_VoiceProcessingIO unit in Audio Toolbox. It gives you echo cancellation, noise suppression and gain control for the Bluetooth and speaker routes.
Is a USB speakerphone better than Bluetooth for calls?
For calls, yes in most cases: USB audio avoids the classic Bluetooth switch from stereo A2DP to mono HFP and the moving radio delay, so the canceller has an easier job and voice stays wideband. Bluetooth is fine for portability, especially with HFP 1.9 super-wideband or LE Audio on both ends.
Does Bluetooth LE Audio fix call quality?
It removes the root cause: LE Audio with the LC3 codec carries good-quality audio in both directions at once, so the drop in quality when the microphone opens becomes much smaller. It only applies when the phone, the earbuds and the operating system all support it, which in 2026 is still a minority of calls.
Free download: Echo by device — field guideOne page with every device class your users join from, why each one echoes or does not, who should own the canceller on it, the A2DP against HFP profile switch with the codec numbers (CVSD at 8 kHz, mSBC at 16 kHz), and the fix to apply per class.Where Fora Soft fits in
We have built real-time audio into video conferencing, telemedicine, e-learning, and live-shopping products since 2005, and the device a user actually joins from is where most audio tickets are born. In telemedicine, a clinician on a clinic speakerphone with a patient on AirPods is the exact combination — long open-room path on one side, Bluetooth profile switch on the other — that defeats a naive setup, and getting it usable is the difference between a finished consultation and a frustrated callback. Most of our work here is choosing the right canceller owner per platform, configuring the WebRTC Audio Processing Module sensibly per device class, and testing deliberately under Bluetooth, speakerphone, and double-talk conditions rather than only on the headset the developer happens to wear. We do not rewrite AEC3; we make the right canceller win on the messy devices your users actually own. That device-matrix work is part of every telemedicine software development project we take on, and our video conferencing app development team runs the same Bluetooth and double-talk test plan before each release. If the product already exists and echo tickets keep coming, our WebRTC consulting review starts with exactly this device matrix: which canceller runs where, and why one headset clips.
The book
Audio for Video: A Complete Guide to Sound in Video Products: From PCM and Codecs to Loudness, Accessibility, and Real-Time Voice Processing
This article stops at which device breaks the canceller and who should own it; volume 4 takes the canceller apart — the adaptive filter, the delay estimator, the double-talk detector, the residual suppressor — and then puts the rest of the capture chain around it, AGC, noise suppression and VAD, in the order a real pipeline runs them. It also covers the codecs on both sides of the Bluetooth cliff, from CVSD and mSBC up to Opus and AAC, so you can tell a profile-switch complaint from an echo complaint before anyone opens a debugger. 1,229 pages for the team that owns the call audio. Written by Nikolay Sapunov, CEO at Fora Soft.
Does your call still work on the device your user actually joined from?
Tell us which devices show up in your tickets — clinic speakerphones, AirPods on a train, a Bluetooth speaker in a kitchen — and we will find out which canceller is running on each platform, stop the double-processing that makes voices sound underwater, set the capture path per device class, and test the result under Bluetooth, speakerphone and double-talk instead of on a developer's headset. 250+ video products shipped since 2005.
See our case studies
Case study
CirrusMed
A direct-primary-care telemedicine platform licensed in 48+ U.S. states, $39/mo for unlimited visits — patients join from home laptops, phones and whatever earbuds they own, which is exactly the device mix this article is about.
Case study
ProVideoMeeting
A WebRTC and FreeSWITCH conferencing SaaS where participants dial in from cell phones and landlines over SIP alongside browser users — one call spanning full-bandwidth browsers and narrowband telephony legs at the same time.
Case study
TransLinguist
Simultaneous interpretation on mediasoup across 75+ languages with 30,000+ certified interpreters, carrying the NHS national framework across the UK — interpreters on wired headsets, everyone else on whatever the room or the pocket provides.
What to read next
Real time
Acoustic echo cancellation (AEC): how it really works
The adaptive filter, the delay estimator and the double-talk detector in full.
Real time
The WebRTC audio pipeline end-to-end
Where the canceller sits between the microphone and the encoder.
Codecs
LC3 and LC3plus: the new Bluetooth audio standard
What replaces the A2DP-or-HFP either-or once LE Audio is the default.
Operations
Diagnosing audio problems in production: a runbook
Turning "it echoes on her headset" into a reproducible test.
References
- Bluetooth SIG, Hands-Free Profile (HFP) 1.6 Specification (approved 2011-05-10). Defines the HFP voice link over (e)SCO, the mandatory CVSD codec (8 kHz), and the optional wideband mSBC codec (16 kHz) added in v1.6. Standards primary source. https://www.bluetooth.org/docman/handlers/downloaddoc.ashx?doc_id=238193
- Bluetooth SIG, A technical overview of LC3 (M. Afaneh; published 2020-11-02, updated 2026-01-27). Source for A2DP being a one-way stereo profile, the history of BR/EDR voice-only profiles, LC3 parameters (7.5/10 ms frames; 8–48 kHz), and LE Audio's bidirectional high-quality streams. First-party. https://www.bluetooth.com/blog/a-technical-overview-of-lc3/
- Bluetooth SIG, Bluetooth LE Audio specifications (current 2026). LE Audio architecture, LC3, connected isochronous streams for simultaneous bidirectional audio; LE Audio introduced with Core Specification 5.2. Standards primary source. https://www.bluetooth.com/specifications/le-audio/
- ITU-T Recommendation P.340, Transmission characteristics and speech quality parameters of hands-free terminals (05/2000). Classifies hands-free terminals by duplex capability (full-duplex vs half-duplex), the formal basis for the "walkie-talkie" clipping symptom. Standards primary source. https://www.itu.int/rec/T-REC-P.340-200005-I
- ITU-T Recommendation G.131, Talker echo and its control (11/2003). Relates tolerable echo to one-way delay — the reason a long Bluetooth or network delay turns faint echo objectionable. Standards primary source. https://www.itu.int/rec/T-REC-G.131
- ITU-T Recommendation G.168, Digital network echo cancellers (06/2002). The performance and test framework for echo cancellers; mandates a nonlinear (residual) processing stage. Standards primary source. https://www.itu.int/rec/T-REC-G.168
- W3C, Media Capture and Streams (Candidate Recommendation Draft, 2025-10-09). Defines the
echoCancellationconstraint ongetUserMedia, now a boolean or a mode string ("all","remote-only"). Standards primary source. https://www.w3.org/TR/mediacapture-streams/ - Apple Developer, kAudioUnitSubType_VoiceProcessingIO and Using voice processing. The Voice-Processing I/O audio unit adds AEC, noise suppression, and AGC; engaged via the
.voiceChataudio session mode. Vendor primary. https://developer.apple.com/documentation/audiotoolbox/kaudiounitsubtype_voiceprocessingio - Android Developers, AcousticEchoCanceler API reference, and AOSP, Configure preprocessing effects. The Android platform echo canceller and how per-source default effects (e.g.,
VOICE_COMMUNICATION) are configured per device. Vendor primary. https://developer.android.com/reference/android/media/audiofx/AcousticEchoCanceler - Apple Support 101993, Use Voice Isolation, Wide Spectrum, or Automatic Mic Mode, and Apple Newsroom (2024-06-24), AirPods introduce convenient ways to communicate. Voice Isolation availability (FaceTime iOS 15+, phone calls iOS 16.4+) and AirPods H2 beamforming / computational audio for calls. Vendor primary. https://support.apple.com/en-us/101993
- Bluetooth SIG, Hands-Free Profile 1.9 (adopted; current version 2026). Adds super-wideband speech over HFP using the LC3 codec (LC3-SWB), succeeding mSBC wideband. Standards primary source. https://www.bluetooth.com/specifications/specs/hands-free-profile/
- Bluetooth SIG, Just released: Bluetooth Core 6.3 (2026-05-06). Current Core specification version. First-party. https://www.bluetooth.com/blog/just-released-bluetooth-core-6-3/
- Apple Developer, AVAudioIONode: setVoiceProcessingEnabled and WWDC23 session 10235 What’s new in voice processing (2023). Voice processing on AVAudioEngine, ducking configuration and muted-talker detection. Vendor primary. https://developer.apple.com/documentation/avfaudio/avaudioionode
- Apple Newsroom, AirPods now more versatile with studio-quality audio recording and camera remote (2025-06-09), and Introducing AirPods Pro 3 (2025-09-09); Apple Support 125135, AirPods Pro 3 tech specs. H2 call-quality processing for iPhone, FaceTime and CallKit apps on AirPods 4 and AirPods Pro 2; AirPods Pro 3 H2 chip, beamforming mics, foam-infused tips. Vendor primary. https://www.apple.com/newsroom/2025/06/airpods-now-more-versatile-with-studio-quality-audio-recording-and-camera-remote/
- Google, Auracast support for hearing aids and earbuds on Android (2025-03-13). Auracast and LE Audio hearing-aid support on Pixel 9 (Android 16) and Samsung Galaxy (One UI 7). Vendor primary. https://blog.google/feed/auracast-hearing-aids-earbuds/
- WebRTC source,
modules/audio_processing/aec3/. The canonical AEC3 implementation: continuously adapting delay/render controller, frequency-domain block filter, residual suppressor. Accessed 2026-06-06. https://webrtc.googlesource.com/src/+/refs/heads/main/modules/audio_processing/aec3/
