

Updated October 2026: browser support for every getStats() signal the checks read (the sender-side audioLevel is Chrome-only), microphone drop-outs traced through track events and Bluetooth profile switching, and the Chrome playout stats that separate network loss from device glitches.
Why this matters
Audio failures are the support tickets that make users abandon a product, because a video glitch is annoying but a call you cannot hear is unusable. If you build or operate a video conferencing tool, a telemedicine platform, an e-learning classroom, or a live-shopping app, your on-call engineer needs a calm, ordered procedure to run when the audio breaks at 2 a.m. — not a guess. This runbook is written for the engineer holding the pager and the product manager who needs to understand what that engineer is doing. It turns a vague "no sound" report into a five-step diagnosis with a named cause and a known fix, so the incident ends in minutes instead of an afternoon of trial and error.
In short: to troubleshoot WebRTC audio, first classify the report — one-way or two-way, and silence, distortion, or echo. Then run five checks in order: device and permissions, the network path, echo cancellation, sample rate, and finally a packet capture. At each check you read one number from getStats() or the capture track and either fix the cause or move on.
How to use this runbook
A production audio failure feels chaotic because the symptom — "I can't hear them" — is the same for a dozen different root causes. The cure for chaos is a fixed order. This runbook lists five checks, and the order is deliberate: the earliest checks catch the most common and cheapest-to-fix problems, so most incidents resolve before you reach step three. Run the checks top to bottom. At each one, read a specific number or flag, compare it to the expected value, and either fix the problem or move to the next check. Do not skip ahead, and do not start with packet captures — that is step five for a reason.
Before anything else, capture two facts from the reporting user, because they cut the search space in half:
First, is the failure one-way or both-way? "I can hear them but they can't hear me" is a completely different problem from "neither of us hears anything." A one-way failure points at one specific endpoint's capture or the path in one direction; a two-way failure points at a shared cause like a server or a codec mismatch.
Second, is it total silence, distorted audio, or echo? Total silence means no signal is arriving or being rendered. Distortion (robotic, choppy, underwater) means the signal arrives but is damaged in transit — a network problem. Echo means the signal arrives fine but a processing stage failed. These three symptoms route to different steps, as the decision tree below shows.
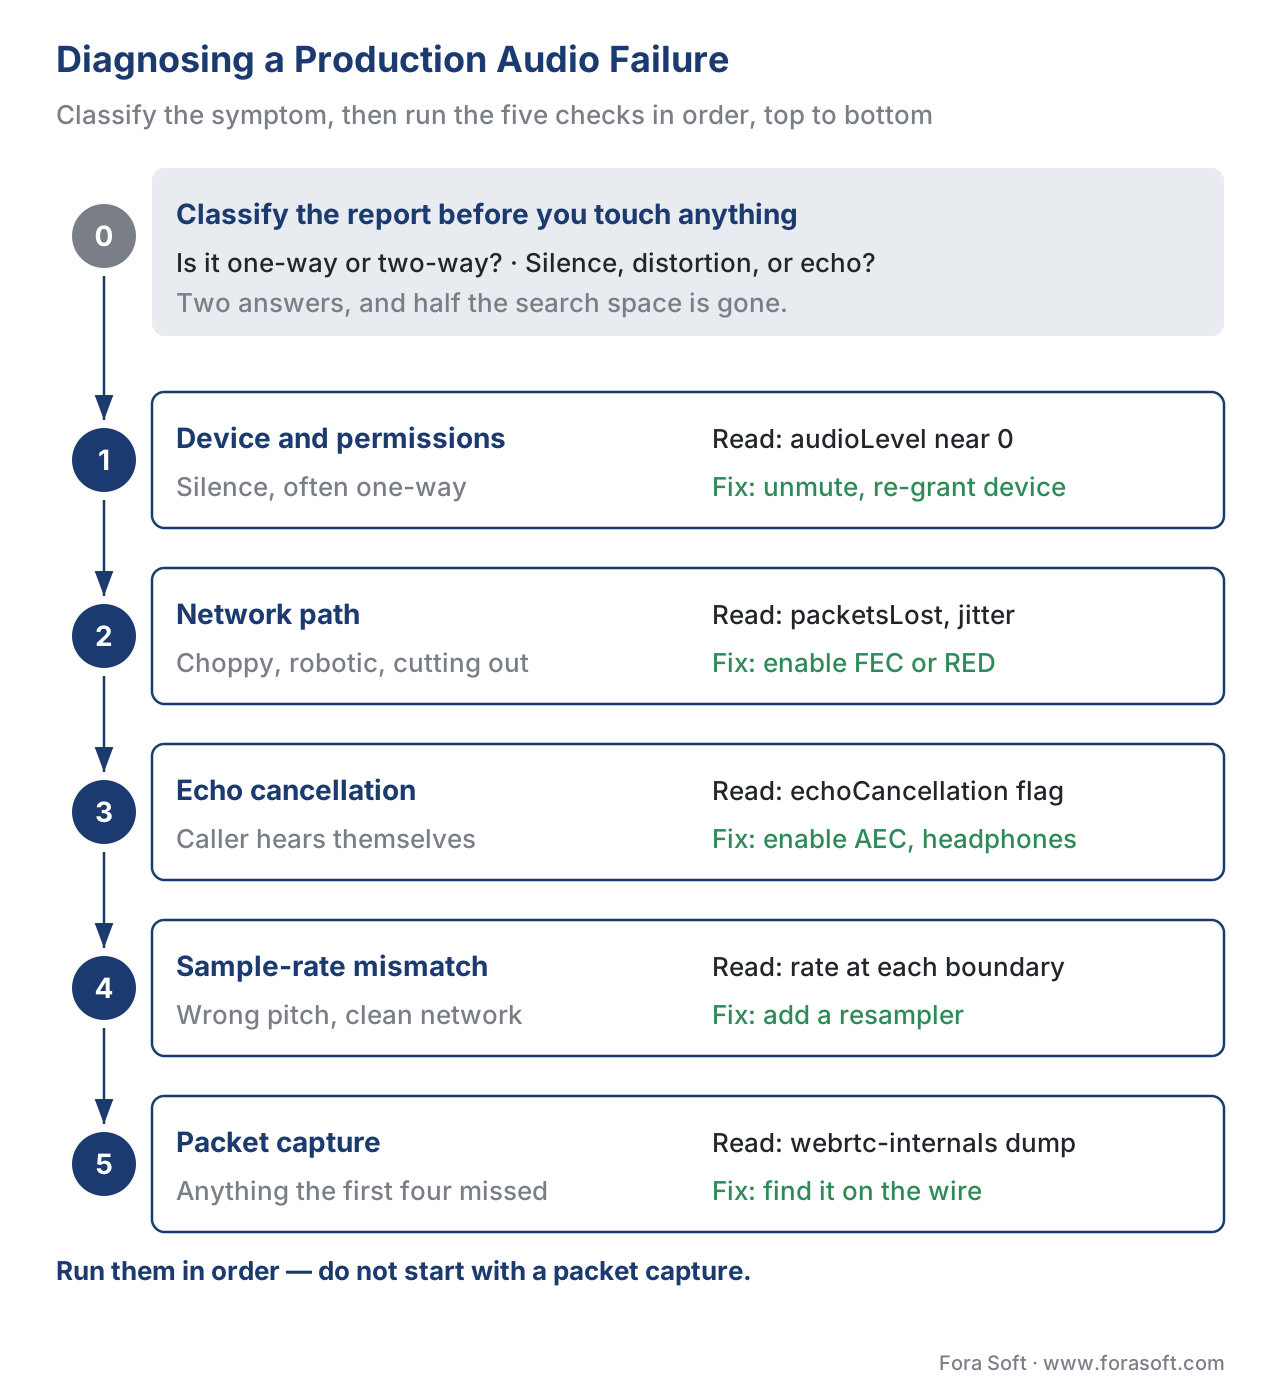 Figure 1. The runbook as a decision tree. Classify the symptom first, then run the five checks in order. The symptom tells you which check is most likely to fire, but you still run them in sequence from the top.
The rest of this article is those five checks, each with the symptom it explains, the number to read, the tool that reads it, and the fix.
The browser already knows: a one-minute primer on getStats
Four of the five checks read a number from the same place, so it is worth understanding that place before we use it. Every live WebRTC connection — the technology browsers use to carry real-time audio and video — keeps a running scorecard of itself. You read that scorecard by calling a function named getStats() on the connection, which is defined in the W3C "Identifiers for WebRTC's Statistics API" specification. It returns a report containing dozens of named numbers, and a handful of them tell you everything about whether audio is flowing.
Think of getStats() as the dashboard of a car. You do not need to open the engine; the dashboard already shows you the fuel level, the speed, and the warning lights. The audio failure is almost always visible on the dashboard if you know which three gauges to read.
Here is the minimal code that reads the dashboard for the audio that is arriving at a receiver. It works in any modern browser's developer console while a call is connected.
// Read the inbound audio stats for a live RTCPeerConnection named `pc`.
const report = await pc.getStats();
report.forEach((stat) => {
  if (stat.type === "inbound-rtp" && stat.kind === "audio") {
    console.log("packets received:", stat.packetsReceived);
    console.log("packets lost:", stat.packetsLost);
    console.log("jitter (s):", stat.jitter);
    console.log("jitter buffer delay (s):", stat.jitterBufferDelay);
    console.log("concealed samples:", stat.concealedSamples);
  }
});
The five numbers this prints map almost one-to-one to the failure classes in this runbook. packetsReceived climbing means audio is arriving at all; packetsLost and jitter rising mean a network problem; concealedSamples rising fast means the receiver is inventing audio to cover gaps, which is what distortion sounds like. The W3C specification (Candidate Recommendation Draft of 25 September 2025) defines a concealed sample as "a sample that was replaced with synthesized samples generated locally before being played out" — in practice, audio from packets that were lost or arrived too late to play. We will use each of these numbers in the checks below. The companion article The WebRTC Audio Pipeline End-to-End explains the full chain these numbers describe.
A note on reading accumulators. Most
getStats()numbers are totals counted since the call began —concealedSamples,packetsLost,totalAudioEnergy. A single reading tells you little; the rate of change between two readings a second apart tells you everything. Always sample twice and subtract. ApacketsLostof 4,000 sounds alarming until you learn it accumulated over a two-hour call with no audible effect; the same 4,000 in ten seconds is a dead call.
How often to call getStats(), and what it costs
Once per second is the right cadence for production monitoring. Each call makes the browser collect numbers from the network stack, the codec, and the audio device, so polling several times a second spends CPU without giving you new information. Tsahi Levent-Levi's webrtc-internals guide (updated June 2026) recommends one call a second and warns that intervals longer than about 10 seconds miss short incidents. Keep the previous reading and compute rates from the difference, as above.
Not every number exists in every browser. MDN's browser compatibility data (checked October 2026) shows the receiver-side fields in all three engines, but the sender-side audioLevel only in Chromium browsers and the playout statistics only in Chrome 111 and later. The table shows which signal each check can rely on, by browser version.
| Signal | Used in | Chrome / Edge | Firefox | Safari |
|---|---|---|---|---|
audioLevel on the sender's media-source report |
Check 1 | 80+ | no | no |
permissions.query({name: "microphone"}) |
Check 1 | 64+ | 132+ | 16+ |
packetsLost, jitterBufferDelay, concealedSamples (inbound) |
Check 2 | 86+ | 104+ | 14.1+ |
jitterBufferTargetDelay (inbound) |
Check 2 | 105+ | 142+ | no |
synthesizedSamplesDuration (media-playout) |
Check 2 | 111+ | no | no |
Check 1 — Device, permissions, and routing (the most common cause)
Symptom it explains: total silence, usually one-way, often "it worked yesterday."
The number to read: audioLevel on the sender's media source, and the microphone permission state.
The tool: navigator.permissions, getUserMedia constraints, getStats() media-source report.
More audio tickets are caused by the operating system, the browser, and the hardware than by your code. The microphone is muted in the OS, the browser permission was denied, the user picked the wrong input device, or audio is routing to a Bluetooth headset that is connected but not selected. None of these are bugs in your application, and all of them masquerade as "your app is broken."
Start at the source: is the microphone actually producing signal? The sender's own statistics answer this. The W3C statistics API exposes an audioLevel on the audio media source — "a number between 0 and 1 (linear), where 1.0 represents 0 dBov, 0 represents silence." If the user is speaking and audioLevel sits at or near 0, no sound is entering the pipeline, and nothing downstream can fix that. You are looking at a muted or wrong-device problem, not a transport problem.
// Is the microphone producing any signal? Read the sender-side media source.
const report = await pc.getStats();
report.forEach((stat) => {
  if (stat.type === "media-source" && stat.kind === "audio") {
    console.log("audio level (0-1):", stat.audioLevel);
    console.log("total audio energy:", stat.totalAudioEnergy);
  }
});
If audioLevel is flat at zero, walk the source chain outward in this order, because each is more common than the next: the microphone is muted at the operating system level (the user's physical mute switch or the OS sound settings); the browser tab is muted or the site's microphone permission was revoked; the wrong input device is selected (the laptop's built-in mic instead of the headset); or the selected device was unplugged mid-call and the browser did not fail over. The permission state is one line to read:
// Check whether the page is actually allowed to use the microphone.
const status = await navigator.permissions.query({ name: "microphone" });
console.log("microphone permission:", status.state); // "granted" | "denied" | "prompt"
The fixes are operational, not code: prompt the user to check the OS mute, re-grant permission, or pick the right device from your in-app device selector. The lasting fix is product design — every serious call app shows a live input-level meter in its pre-call screen, driven by exactly the audioLevel number above, so the user sees a dead microphone before the call instead of during it. The constraints that request the microphone, and the echoCancellation, autoGainControl, and noiseSuppression flags, are defined in the W3C "Media Capture and Streams" specification; getting the device and its constraints right at getUserMedia() time prevents most of these tickets.
On Firefox and Safari, the sender's media-source report has no audioLevel, so measure the microphone directly with the Web Audio API. An AnalyserNode on the capture stream answers the same question — is any sound coming in? — in every browser. The permission query, by contrast, now works everywhere that matters: Chrome since version 64, Safari since 16, and Firefox since 132 (October 2024). Android WebView does not support it, so a hybrid app has to ask the native layer instead.
// Cross-browser microphone level: RMS of the live capture stream (0 = silence).
const ctx = new AudioContext();
await ctx.resume(); // contexts start suspended until a user gesture
const analyser = ctx.createAnalyser();
ctx.createMediaStreamSource(localStream).connect(analyser);
const buf = new Float32Array(analyser.fftSize);
analyser.getFloatTimeDomainData(buf);
const rms = Math.sqrt(buf.reduce((sum, x) => sum + x * x, 0) / buf.length);
console.log("mic RMS (0-1):", rms.toFixed(3)); // read on a timer: the first read can be 0
Why does the microphone keep cutting out mid-call?
A microphone that works and then drops out during a call is rarely your code crashing. Usually the capture device went away or something else took it. The W3C Media Capture and Streams specification gives you three events that tell these cases apart. mute fires when the source is "temporarily unable to provide data" — another app or a phone call grabbed the device, or the operating system paused capture. ended fires when the source will not provide data again, because the permission was revoked or the device was unplugged. devicechange on navigator.mediaDevices fires when a headset is connected or removed.
// Log every reason the microphone can drop out, with a timestamp.
const [track] = localStream.getAudioTracks();
track.addEventListener("mute", () => console.log("mic paused by the system", Date.now()));
track.addEventListener("unmute", () => console.log("mic back", Date.now()));
track.addEventListener("ended", () => console.log("mic gone: unplugged or permission revoked", Date.now()));
navigator.mediaDevices.addEventListener("devicechange", () => console.log("device list changed", Date.now()));
Ship these events to your session log and a "the mic keeps crashing" ticket becomes one line with a timestamp. To recover from ended, call getUserMedia() again and swap the new track in with RTCRtpSender.replaceTrack(), which changes the audio without renegotiating the call.
Bluetooth headsets produce a quieter version of the same complaint. On classic Bluetooth, opening the microphone switches the headset from its music profile (A2DP) to the Hands-Free Profile (HFP), which plays back in mono at 8 kHz in its original form or 16 kHz with "wideband" voice. In August 2025 Microsoft added LE Audio "super wideband stereo" to Windows 11 24H2, which keeps calls in stereo at a 32 kHz sample rate — but only with LE Audio hardware and an updated driver (Microsoft Windows OS Platform blog, August 2025). When a user says their wireless earbuds sound terrible on calls, that profile switch is the first suspect; the codec behind LE Audio is covered in LC3 and LC3plus: the new Bluetooth audio default.
Common mistake: blaming the network for a muted mic. The instinct on a "no audio" report is to check the connection. But if the sender's
audioLevelis zero, the network is irrelevant — there is nothing to send. Reading the source level first saves you from a fruitless packet capture. This is why device is Check 1 and capture is Check 5.
Check 2 — The network path: loss, jitter, and the buffer
Symptom it explains: choppy, robotic, "underwater," or intermittent audio — the signal is there but damaged.
The number to read: packetsLost rate, jitter, jitterBufferDelay, and concealedSamples rate.
The tool: getStats() inbound-rtp report, sampled twice.
If audio is arriving but sounds wrong, the network is the prime suspect, and the receiver's inbound statistics name the problem precisely. Three numbers work together here, and reading them as a group is the whole skill.
Packet loss is the fraction of audio packets that never arrived. Read packetsLost and packetsReceived twice, a few seconds apart, and compute the loss rate over that window:
loss rate = (packetsLost_now - packetsLost_before)
          / (packetsReceived_now - packetsReceived_before
             + packetsLost_now - packetsLost_before)
Plug in real numbers. Suppose between two readings ten seconds apart you see 120 newly lost packets and 4,880 newly received: loss rate = 120 / (4,880 + 120) = 120 / 5,000 = 0.024, or 2.4%. For voice, anything under about 1% is inaudible thanks to packet loss concealment; 2–5% is noticeable as occasional clicks; above 5% the call degrades sharply unless redundancy is in play. The repair tools for loss live in two companion articles: Packet Loss Concealment (PLC) hides the missing frames after the fact, and Forward Error Correction (FEC) and RED Redundancy prevents the gap by sending the audio twice.
Jitter is the variation in packet arrival timing — packets that should arrive evenly every 20 milliseconds instead bunch up and straggle. The jitter field reports this, and its calculation is defined in IETF RFC 3550, Appendix A.8, as a running average of the difference in transit time between consecutive packets. One subtlety trips up everyone: jitter is reported in seconds in getStats(), but RTP measures time internally in clock-rate units, and for Opus — the codec nearly every WebRTC call uses — that clock runs at 48,000 ticks per second, fixed by IETF RFC 7587. A jitter of 0.03 in the stats means 30 milliseconds of timing spread, which the jitter buffer must absorb.
The jitter buffer is the receiver's shock absorber. It holds arriving packets briefly so it can play them out on a smooth schedule despite their uneven arrival — like an airport waiting area that holds passengers who arrive on irregular flights so the bus can leave on a fixed timetable. The jitterBufferDelay field, divided by jitterBufferEmittedCount, gives the average time audio spent waiting. A larger buffer hides more jitter but adds delay; the buffer trades latency for smoothness automatically. When loss or jitter overwhelm it, the buffer gives up and the receiver synthesizes replacement audio, which it counts in concealedSamples. A concealedSamples count climbing fast — more than a percent or two of totalSamplesReceived over a window — is the numeric signature of audible distortion. The full machinery is the subject of Jitter Buffer: NetEQ, the Brain of WebRTC Audio.
The fix depends on which number is high. High loss with low jitter is a lossy link — enable FEC or RED. High jitter is an unstable link — the buffer will grow to compensate, at the cost of latency, and there is little the application can do beyond ensuring the buffer is allowed to adapt. Both high at once is a saturated or congested path, which points at the bitrate-control story in Bitrate and Bandwidth Control in Real-Time Audio.
Two newer fields make this check sharper. jitterBufferTargetDelay on the inbound report (Chrome 105+, Firefox 142+) shows the delay the buffer is aiming for; a target that keeps rising tells you the network is getting worse before the user hears it. In Chrome 111 and later, the media-playout report (RTCAudioPlayoutStats) adds synthesizedSamplesDuration: seconds of audio the playout device needed but did not get on time. If that number rises while inbound loss and jitter stay flat, the gap is between the browser and the speaker — an overloaded CPU or a struggling audio driver — not the network.
On native apps where you ship your own Opus build, there is one more repair tool. libopus 1.6 (December 2025) improved Deep Redundancy (DRED), the machine-learning redundancy introduced in Opus 1.5, which lets a receiver rebuild audio after longer bursts of loss than classic FEC covers. Browsers decide for themselves which Opus features they enable, so in a web client the levers remain FEC, RED, and the jitter buffer. The codec itself is explained in Opus: the open codec that ate WebRTC.
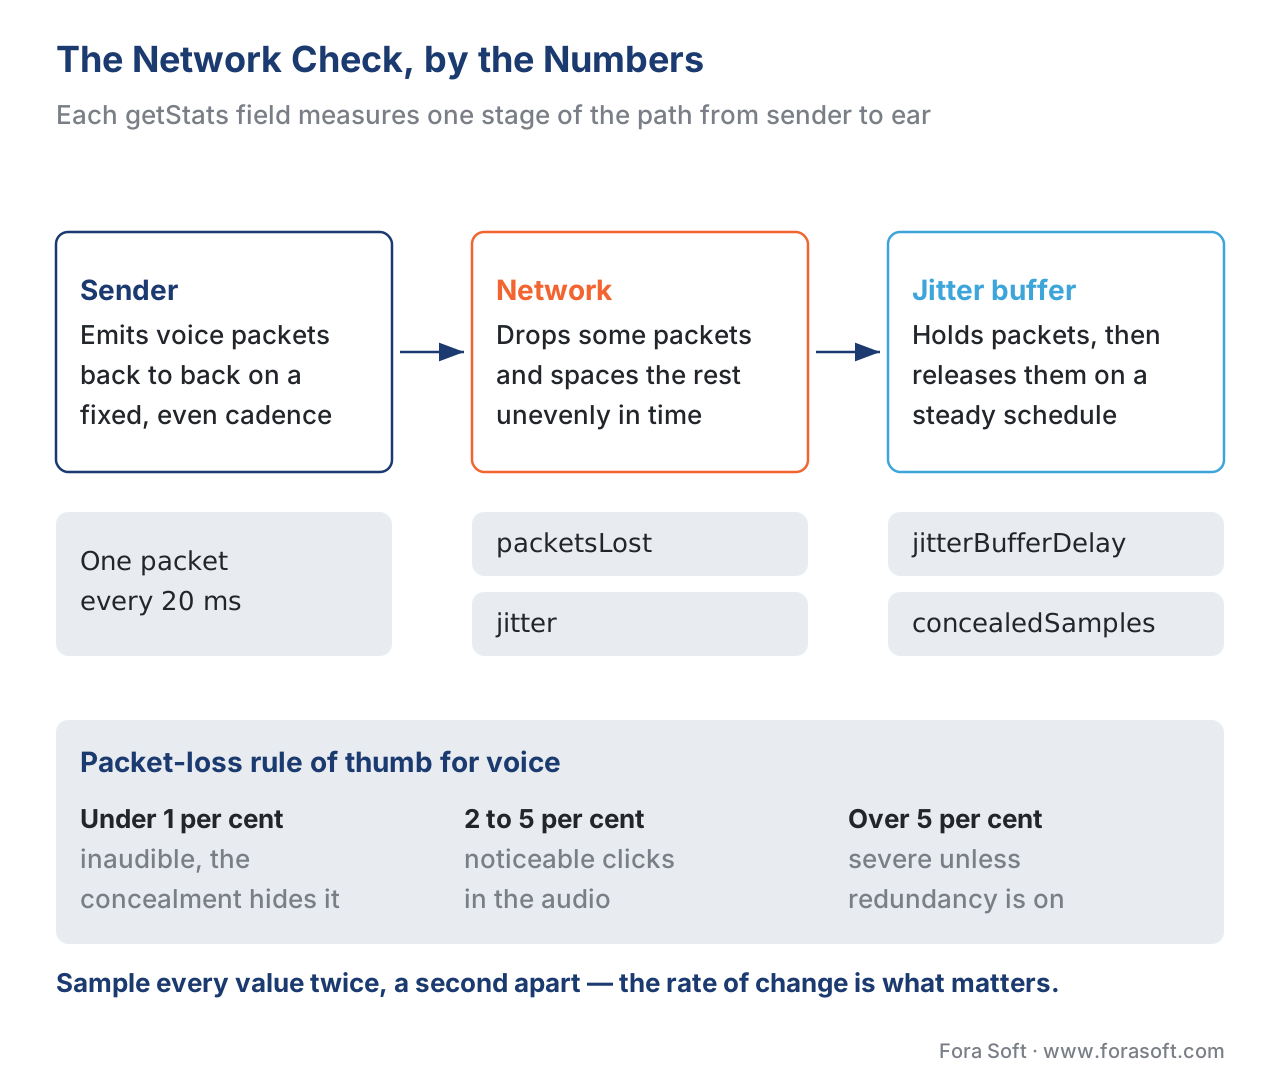 Figure 2. The network check, by the numbers. Loss happens in the cloud; jitter is uneven arrival; the buffer absorbs jitter at the cost of delay; concealed samples are the receiver inventing audio when the buffer runs dry. Each is a named getStats field.
Check 3 — Echo cancellation convergence
Symptom it explains: echo — one party hears their own voice come back a moment later.
The number to read: the echoCancellation setting on the capture track; whether headphones are in use.
The tool: MediaStreamTrack.getSettings(), plus a quick environment question.
Echo is not a network problem and not a device-silence problem; it is a processing problem, and it sits in its own check because its symptom is unmistakable. Echo happens when one participant's speaker plays the other participant's voice, that sound travels back into the first participant's microphone, and it gets sent back — so the second participant hears themselves a beat late. The job of acoustic echo cancellation, AEC, is to recognize the speaker output inside the microphone input and subtract it. The modern WebRTC implementation, AEC3, does this well, but it has a failure mode worth knowing.
First, confirm AEC is even switched on. The capture track carries its current settings, and the W3C Media Capture and Streams specification defines echoCancellation as a boolean you can read back:
// Confirm echo cancellation is actually enabled on the live capture track.
const [track] = localStream.getAudioTracks();
const settings = track.getSettings();
console.log("echoCancellation:", settings.echoCancellation); // expect true
If it reads false, something in your capture code requested raw audio — a common mistake when a developer copies a getUserMedia snippet meant for music recording, where echo cancellation is deliberately off. Re-request the track with echoCancellation: true.
If AEC is on and echo persists, the cause is usually one of three convergence problems, and the full mechanics are covered in Acoustic Echo Cancellation (AEC): How It Really Works. The canceller needs a moment at the start of a call to "converge" — to learn the acoustic delay between speaker and microphone — and during those first seconds echo can leak through. A long or variable delay defeats it: a Bluetooth speakerphone adds a hundred-plus milliseconds of unpredictable delay between the reference signal and the echo, which is exactly the case classical AEC assumptions break on. And "double-talk" — both people speaking at once — is the hardest moment for any canceller to hold its estimate. The deep version of the Bluetooth and speakerphone problem is Echo Cancellation on Speakerphones, Bluetooth, and AirPods.
The reliable operational fix is the oldest one: headphones eliminate echo at the source, because the speaker output never reaches the microphone. Design for the user who refuses to wear them — keep AEC on, prefer wired or low-latency audio paths — but when an echo ticket arrives, "are you on speakerphone or Bluetooth?" resolves it more often than any code change.
Check 4 — Sample-rate mismatch
Symptom it explains: persistent distortion or pitch shift that the network check could not explain — audio that sounds slightly fast, slow, or "chipmunk."
The number to read: the sample rate at capture, at the codec, and at the audio context.
The tool: AudioContext.sampleRate, track settings, and your server's codec configuration.
This is the subtle one, and it is Check 4 because it is rarer than the first three but invisible to them. Digital audio is a stream of samples taken at a fixed rate — for video and WebRTC, the standard is 48,000 samples per second, 48 kHz. Trouble appears when one stage of the pipeline assumes a different rate than another. If audio is captured at 44.1 kHz but a downstream stage treats it as 48 kHz, every second of sound is replayed in less than a second, and the pitch rises — the "chipmunk" effect. The reverse drops the pitch. A subtler version produces periodic clicks or slow drift as the two clocks slip against each other.
WebRTC standardizes on 48 kHz precisely to avoid this — Opus operates internally at 48 kHz and its RTP payload clock is fixed at 48,000 Hz by RFC 7587 — so in a pure WebRTC call the mismatch is usually introduced at the edges: a Web Audio graph running at the hardware's native rate, a recording branch written at the wrong rate, or a gateway bridging to a PSTN leg that runs at 8 kHz. The check is to read the rate at each boundary and confirm they agree or that an explicit resampler sits between them:
// What sample rate is the Web Audio graph actually running at?
const ctx = new AudioContext();
console.log("AudioContext sample rate:", ctx.sampleRate); // commonly 48000, sometimes 44100
One new boundary is worth knowing. libopus 1.6 (December 2025) added a 96 kHz "Opus HD" mode. The RTP clock for Opus in WebRTC is still 48,000 Hz under RFC 7587, so a server or native pipeline that starts handling 96 kHz audio — for recording or music features — adds one more place where the rate must be converted explicitly.
The fix is never to "force" a rate and hope; it is to insert a proper resampler at the boundary where the rate legitimately changes, so 44.1 kHz capture is resampled to 48 kHz before it reaches the 48 kHz codec. The background on why 48 kHz won video, and what resampling costs, is in Sample Rate: 44.1, 48, 96, 192 kHz. A recording or transcription branch is a frequent offender because it is bolted on after the call works; see Recording and Transcription Pipelines.
Common mistake: reading distortion as a network problem. Choppy audio with high
concealedSamplesis the network. Audio that is continuously the wrong pitch or speed, with clean network stats, is a sample-rate mismatch. The tell is that the network check in Step 2 comes back clean — low loss, low jitter — yet the audio is still wrong. When the numbers say the path is healthy but the ears say otherwise, suspect the clock.
Check 5 — Packet capture: the last resort
Symptom it explains: anything the first four checks could not, especially server-side and signalling problems.
The tool: chrome://webrtc-internals (or the browser equivalent), and Wireshark on a PCAP when you need the wire itself.
If a problem survives the first four checks, you have exhausted what the application can see and you need to watch the bytes. There are two depths.
The first, and the one to try before reaching for anything heavier, is the browser's own dump. Chrome exposes chrome://webrtc-internals, a live page that records every getStats() value as a graph for every active connection, and lets you export the whole session as a file. This is the same data the code above reads, but plotted over time and captured automatically — invaluable when a problem is intermittent and you cannot reproduce it on demand. Ask the user to open chrome://webrtc-internals in a second tab before the call, reproduce the failure, and send you the dump. The graph of concealedSamples or packetsLost over the exact second the audio broke usually names the cause without further work.
Getting the dump takes four steps. Open chrome://webrtc-internals in a new tab before the call starts, because it only records connections that are open while the page is open. Reproduce the problem. Click "Create a WebRTC-Internals dump" and download the file. Close the call only after the download finishes. Firefox has the equivalent page at about:webrtc. Safari has no comparable page, so for Safari users the only record is the one your own client collects — one more reason to sample getStats() once a second and send it to your backend.
The second depth is a true packet capture with Wireshark, the standard network protocol analyzer. You reach for it when the question is below the application — whether RTP packets are even leaving the machine, whether they carry the codec you expect, whether the negotiation (SDP) agreed on the payload format both sides assumed. Wireshark decodes RTP and RTCP, can show the per-stream loss and jitter it computes independently of the browser, and on a capture of audio it can even play the RTP stream back so you can hear what actually crossed the wire. This is how you catch the failures that never reach getStats() at all: a firewall dropping media while signalling succeeds (so the call "connects" but is silent), a codec mismatch from a broken SDP negotiation, or one-way media from an asymmetric NAT problem. The architecture that decides where these packets flow — and where to capture them — is covered in Audio in SFU vs MCU vs P2P.
Capture is Check 5 because it is the most expensive in time and skill, and because four times out of five one of the earlier checks has already found the answer. Reaching for Wireshark first is the classic rookie move — it is like dismantling the engine to find out the car was simply in neutral.
The five checks, side by side
The table is the runbook in one view. Print it, pin it next to the on-call dashboard, and work top to bottom.
| # | Check | Symptom | Number / signal to read | Typical fix |
|---|---|---|---|---|
| 1 | Device & permissions | Total silence, one-way | Sender audioLevel ≈ 0; permission denied |
Unmute OS, re-grant, pick right device |
| 2 | Network path | Choppy, robotic, intermittent | packetsLost rate, jitter, concealedSamples rate |
Enable FEC/RED; let buffer adapt |
| 3 | Echo cancellation | Caller hears themselves | echoCancellation = false; on speakerphone? |
Enable AEC; use headphones |
| 4 | Sample-rate mismatch | Wrong pitch/speed, clean network | Rates at capture vs codec vs context | Insert a resampler at the boundary |
| 5 | Packet capture | Anything unexplained | webrtc-internals dump; Wireshark RTP |
Find dropped/mismatched media on the wire |
The order encodes field experience: in our own support work across these products, roughly seven in ten "broken audio" tickets end at Check 1 or Check 2 — an estimate from our incident history, not a measured industry share — because device confusion and bad networks are simply the most common things that go wrong. Each step down the list is rarer and costlier to investigate. Honoring the order is what turns a two-hour debugging session into a two-minute diagnosis.
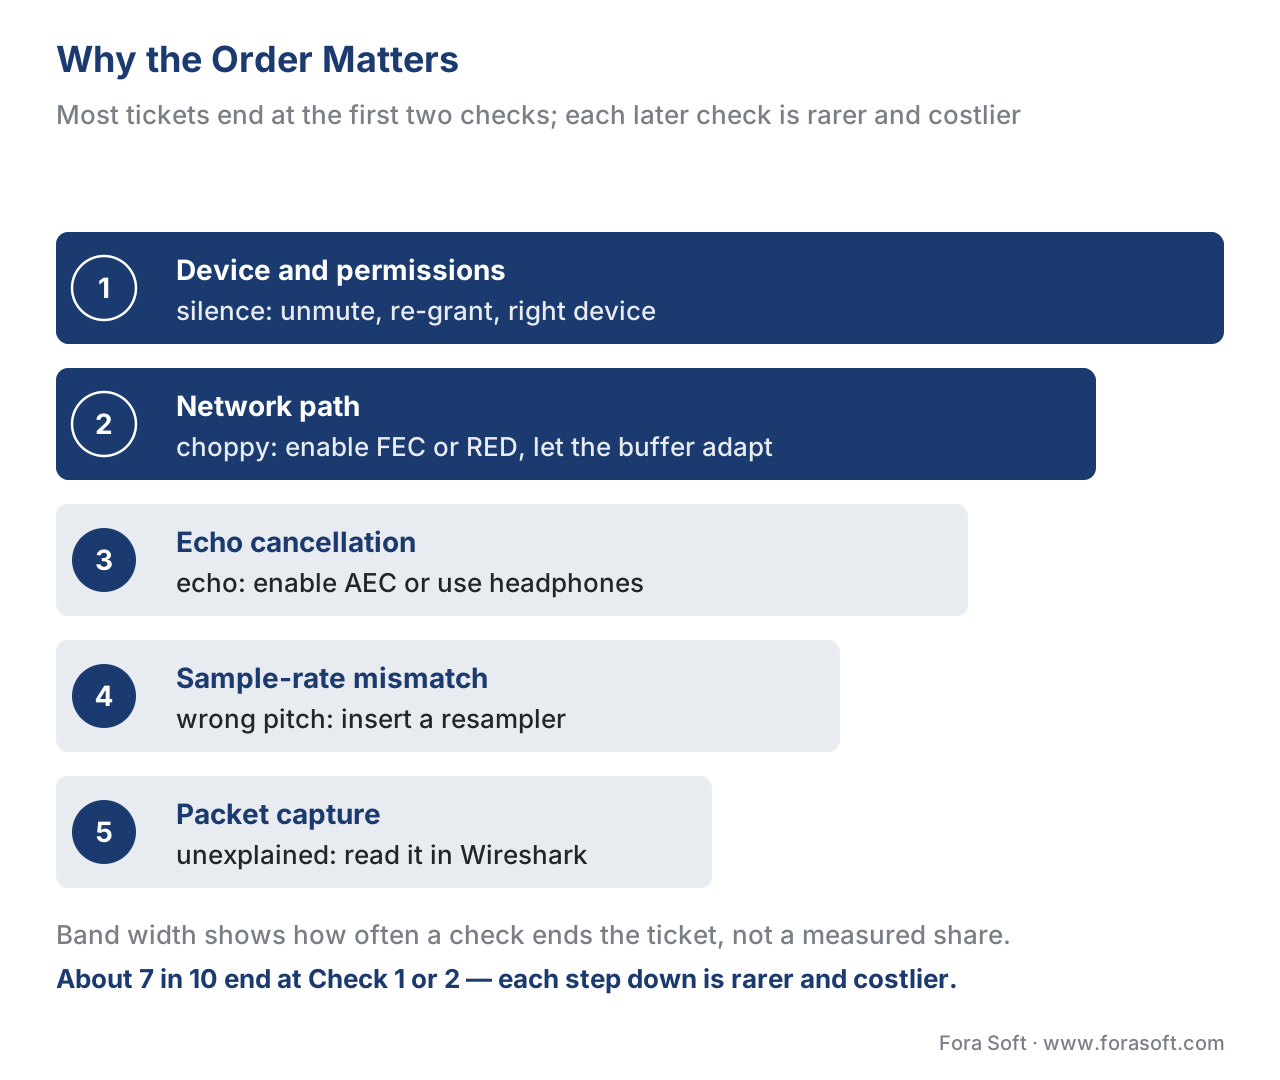 Figure 3. Why the order matters. Most incidents resolve at the first two checks; each later check is rarer and more expensive. Running them in order is the difference between a two-minute and a two-hour diagnosis.
A worked incident: "the patient can't hear the doctor"
Concrete beats abstract, so here is the runbook applied to a real shape of ticket from a telemedicine call. The report: the doctor can hear the patient, but the patient says the doctor is silent. That single fact — one-way, doctor-to-patient — already tells us the patient's receive path or the doctor's send path is at fault, and that the network in the other direction is fine.
Check 1, on the doctor's side: read the doctor's sender audioLevel while they speak. It reads 0.34 — a healthy level. The microphone is producing signal, so this is not a muted-mic problem on the doctor's end. Move on.
Check 2, on the patient's side: read the patient's inbound-rtp stats for the doctor's audio. packetsReceived is not climbing between two readings. No packets are arriving at all. This is not loss or jitter — those would show packets arriving and being damaged. Zero arrival with a connected call points past the application, to the path itself.
We skip to Check 5, because zero packets arriving despite a "connected" call is the classic signature of media being blocked while signalling succeeded. A webrtc-internals dump from the patient confirms the audio inbound stream exists but shows zero bytes received. A short Wireshark capture on the patient's network shows the doctor's RTP never arrives — a corporate firewall on the patient's hospital network is permitting the signalling channel but dropping the UDP media. The fix is operational (a TURN relay over TCP/443 to traverse the firewall), not a code change to the audio pipeline. Total time to a named cause: under ten minutes, because the one-way classification and the "packets not climbing" reading routed us straight to the right depth.
The lesson is the runbook's whole thesis: the symptom classification plus one or two getStats() readings almost always point at the right check, and the right check names the cause.
Frequently asked questions
How do I troubleshoot WebRTC audio?
Classify the report first: one-way or two-way, and silence, distortion, or echo. Then run five checks in order — device and permissions, network path, echo cancellation, sample rate, packet capture — reading one getStats() number or track setting at each.
Why does my microphone keep cutting out during a call?
Usually the device was taken or removed, not a crash: the track fires mute when the system pauses capture, ended when the device is unplugged or permission is revoked, and devicechange when a headset connects. On classic Bluetooth, opening the mic also drops the headset into its mono hands-free profile (HFP).
How often should I call getStats(), and is it expensive?
Once per second. Each call gathers data from the network, codec, and audio device, so faster polling costs CPU without adding information, while intervals over about 10 seconds miss short incidents.
How much packet loss is acceptable for WebRTC voice?
As a rule of thumb, under about 1% is inaudible thanks to packet loss concealment, 2–5% causes noticeable clicks, and above 5% the call degrades sharply unless FEC or RED is on.
Why does the audio pitch change or drift out of sync?
A pitch shift or slow drift on a clean network is a sample-rate mismatch: one stage treats 44.1 kHz audio as 48 kHz, or the reverse. Insert an explicit resampler at the boundary where the rate changes.
Why does a WebRTC call connect but have no audio?
Signalling got through but the media did not, most often because a firewall blocks UDP. packetsReceived stays flat on the receiver; a TURN relay over TCP or TLS on port 443 usually fixes it.
How do I tell a network problem from a device problem?
Network problems show rising packetsLost, jitter, and concealedSamples. A dead microphone shows a sender level near zero, and playout trouble shows rising synthesizedSamplesDuration in Chrome while loss and jitter stay flat.
Free download: WebRTC Audio Troubleshooting — Field RunbookOne page for the on-call engineer: the five checks in order — device, network, echo, sample rate, capture — with the exact
getStats() number to read at each one, the value to expect, and the fix that follows.
Where Fora Soft fits in
We have operated real-time audio in telemedicine, video conferencing, e-learning, and live-event products since 2005, which means we have run this runbook in anger more times than we can count. The pattern holds across verticals: the overwhelming majority of "audio is broken" reports are device, permission, or network problems that the user's environment created, not defects in the media code — and the teams that struggle are the ones without a fixed order to check them in. In the products we ship, the pre-call screen always shows a live microphone meter so a dead device is caught before the call, and the in-call client samples getStats() continuously so support can read the loss and concealment numbers from a session that already ended. Building the observability in from the start is the difference between diagnosing from data and guessing from a screenshot. When a live product already has audio complaints, our real-time software troubleshooting and optimization work starts from exactly these five checks, and new products get the same instrumentation built in by our WebRTC development team. If a stack keeps producing audio tickets and you want an outside read first, our WebRTC consulting review covers the media server, the signalling, and the client-side stats you would need to diagnose the next incident.
The book
Audio for Video: A Complete Guide to Sound in Video Products: From Jitter Buffers and Lip Sync to Atmos, Quality Metrics, and Neural Codecs
This runbook reads four numbers and names a cause; volume 5 is the 1,288 pages behind those numbers. It takes apart the machinery each check touches — the jitter buffer and NetEQ that jitterBufferDelay and concealedSamples report on, the packet-loss concealment that makes 1 per cent loss inaudible, the FEC and RED redundancy you switch on when it is not — and closes with a chapter on diagnosing incidents by symptom, which is this article at book length. It is part of a seven-volume series that takes the whole video stack apart from pixel to production. Written by Nikolay Sapunov, CEO at Fora Soft.
When a user says the audio is broken, can your on-call engineer name the cause in ten minutes?
Tell us what your call stack looks like today — peer-to-peer, SFU, or a gateway to something older — and whether you keep getStats() from sessions that have already ended, and we will come back with the observability you are missing, where to put the pre-call microphone meter, and what it costs to build. 250+ video products shipped since 2005.
See our case studies
Case study
TransLinguist
A mediasoup and WebRTC interpretation platform for 75+ languages and 30,000+ certified interpreters, which won the NHS national framework for language services across the UK. When an interpreter cannot be heard, a hearing goes on hold — so Checks 1 and 3 run as product features, not as support scripts.
Case study
WorldCast Live
Concert streaming at 0.4–0.5 s latency for 10,000 simultaneous viewers, carrying five audio channels at 1.5 Gb/s on a custom WebRTC and Kurento build. That is Check 2 with no margin: performers in different cities play together, so the jitter buffer has milliseconds to absorb what the network does.
Case study
VocalViews
A market-research platform with 1M+ participants and 5K+ completed studies, recording video interviews and transcribing them in 30+ languages for Samsung, McDonald’s, and Netflix. The recording and transcription branch is exactly where Check 4 earns its place: a rate set once at the wrong boundary ruins every file after it.
What to read next
Pipeline
The WebRTC Audio Pipeline End-to-End
The full chain the five numbers describe, from microphone to speaker.
Jitter buffer
Jitter Buffer: NetEQ, the Brain of WebRTC Audio
What Check 2 is really reading when concealedSamples starts climbing.
Echo
Acoustic Echo Cancellation (AEC): How It Really Works
Why Check 3 fails on speakerphones even when the flag reads true.
Sample rate
Sample Rate: 44.1, 48, 96, 192 kHz and Why 48 kHz Won Video
The background to Check 4, and what resampling actually costs you.
References
- W3C — Identifiers for WebRTC's Statistics API (Candidate Recommendation Draft, 25 September 2025; checked 2026-10-23). Defines
getStats(),RTCInboundRtpStreamStats(packetsReceived,packetsLost,jitter,jitterBufferDelay,jitterBufferEmittedCount,concealedSamples,totalSamplesReceived) andRTCAudioSourceStats(audioLevel,totalAudioEnergy,totalSamplesDuration). The normative definition of every metric this runbook reads; the "concealed sample" definition is quoted from here. https://www.w3.org/TR/webrtc-stats/ - W3C — Media Capture and Streams (Candidate Recommendation Draft, 9 October 2025; checked 2026-10-23). Defines
getUserMedia()and theechoCancellation,autoGainControl, andnoiseSuppressionconstrainable properties read back viaMediaStreamTrack.getSettings(). Also defines themute,unmute,ended, anddevicechangeevents used to trace microphone drop-outs. Source for the device/constraint facts in Checks 1 and 3. https://www.w3.org/TR/mediacapture-streams/ - IETF RFC 3550 — RTP: A Transport Protocol for Real-Time Applications, H. Schulzrinne et al., STD 64, July 2003. Appendix A.8 defines the interarrival jitter calculation (
J(i) = J(i−1) + (|D(i−1,i)| − J(i−1))/16) that thejitterfield reports. Read from rfc-editor.org. https://www.rfc-editor.org/rfc/rfc3550.html - IETF RFC 7587 — RTP Payload Format for the Opus Speech and Audio Codec, J. Spittka, K. Vos, JM. Valin, June 2015. Fixes the Opus RTP timestamp clock at 48,000 Hz — the basis for Check 4's "48 kHz is the WebRTC standard rate" and for converting
jitterseconds to clock units. Read from rfc-editor.org. https://www.rfc-editor.org/rfc/rfc7587.html - IETF RFC 6716 — Definition of the Opus Audio Codec, JM. Valin, K. Vos, T. Terriberry, September 2012 (updated by RFC 8251). The codec carried by virtually every WebRTC call; its internal 48 kHz operation and built-in PLC underpin Checks 2 and 4. https://www.rfc-editor.org/rfc/rfc6716.html
- IETF RFC 8825 — Overview: Real-Time Protocols for Browser-Based Applications, H. Alvestrand, January 2021. The WebRTC architecture overview defining the connection whose statistics
getStats()reports. https://www.rfc-editor.org/rfc/rfc8825.html - MDN Web Docs — RTCInboundRtpStreamStats (
jitterBufferDelay,concealedSamples) and RTCAudioSourceStats (audioLevel,totalAudioEnergy), accessed 2026-06-06. Developer-facing companion to the W3C spec; source for theMath.sqrt(totalAudioEnergy/totalSamplesDuration)RMS formula used to detect a silent microphone. Where MDN and the spec differ, the spec (ref 1) governs. https://developer.mozilla.org/en-US/docs/Web/API/RTCInboundRtpStreamStats - The WebRTC Project / Google —
chrome://webrtc-internalsdocumentation and the libwebrtc AEC3 source. Source for the browser stats-dump workflow in Check 5 and the AEC3 convergence behaviour in Check 3. https://webrtc.org/ - Wireshark User's Guide — RTP analysis, RTP stream player, and RTCP statistics, accessed 2026-06-06. The packet-capture tooling of Check 5; the independent loss/jitter computation cited there. https://www.wireshark.org/docs/wsug_html_chunked/
- T. Levent-Levi (BlogGeek.me) — Making sense of getStats in WebRTC, accessed 2026-06-06. Practitioner guide to which
getStats()fields matter in production; treated as a tier-4 vendor/practitioner source, subordinate to the W3C spec (ref 1) where they differ. https://bloggeek.me/getstats/ - MDN — browser-compat-data — for
RTCStatsReporttypes (media-source, inbound-rtp, media-playout) andPermissions.query(), checked 2026-10-23. Source for the browser-version table in the getStats primer. https://github.com/mdn/browser-compat-data - Xiph.Org — Opus codec news: libopus 1.6 — released 15 December 2025 (1.6.1 on 14 January 2026). Source for the 96 kHz Opus HD mode and the Deep Redundancy (DRED) improvements in Checks 2 and 4. https://opus-codec.org/
- Microsoft Windows OS Platform blog — Cutting the wire without cutting the audio quality — August 2025. Source for HFP mono at 8 kHz (16 kHz wideband) and LE Audio super wideband stereo at 32 kHz on Windows 11 24H2 in Check 1. https://techcommunity.microsoft.com/blog/windowsosplatform/cutting-the-wire-without-cutting-the-audio-quality/4447942
- T. Levent-Levi (BlogGeek.me) — Everything you wanted to know about webrtc-internals and getStats, updated June 2026. Source for the once-per-second
getStats()cadence and the dump workflow; practitioner source, subordinate to the W3C spec. https://bloggeek.me/webrtc-internals/
